
Awesome and highly useful: FineWeb-Edu High quality LLM dataset filtering the original 15 trillion FineWeb tokens to 1.3 trillion of the highest (educational) quality, as judged by a Llama 3 70B. +A highly detailed paper. Turns out that LLMs learn a lot better and faster
MACHINE LEARNING
-

Language Translation Using LSTM for NLP Sequential Data
By
–
Language Translation Using LSTM: Introduction In natural language processing (NLP), it is important to understand and effectively process sequential data.… https://
analyticsvidhya.com/blog/2024/04/l
anguage-translation-using-lstm/?utm_source=dlvr.it&utm_medium=twitter
… #DataAnalytics #DataScience #DataDriven #BusinessIntelligence #IoT #CTO #ITDirector #Blockchain -
Python Machine Learning and AI Engineering Resources
By
–
If you interested in: – Python – Machine Learning – AI Engineering Find me →
@akshay_pachaar My Newsletter on AI Engineering → @ML_Spring Cheers! -
U-Net Semantic Segmentation Library Released
By
–
How it works Internally it uses a U-Net based foreground/background semantic segmentation and yields the post processed results. If you try it, library would download the trained model first. Fine the code here:
-
SimPO: Reference-Free Preference Optimization for Language Models
By
–
10/ SimPO – a simpler and more effective approach for preference optimization with a reference-free reward; uses the average log probability of a sequence as an implicit reward (i.e., no reference model required) which makes it more compute and memory efficient.
-
GNN-RAG: Combining LLMs with Graph Neural Networks
By
–
5/ GNN-RAG – combines the language understanding abilities of LLMs with the reasoning abilities of GNNs in a RAG style; the GNN extracts useful and relevant graph information while the LLM takes the information and leverages its capabilities to perform question answering over
-
Attention as RNN: Parallel Training with Constant Memory Inference
By
–
6/ Attention as an RNN – presents a new attention mechanism that can be trained in parallel (like Transformers) and be updated efficiently with new tokens requiring constant memory usage for inferences (like RNNs).
-
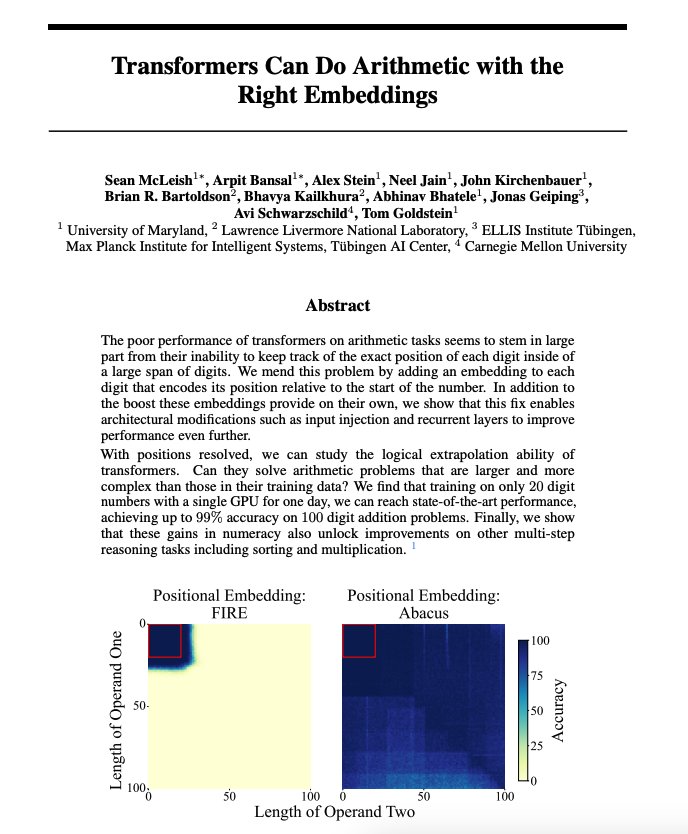
Abacus Embeddings Achieves 99% Accuracy on Addition Problems
By
–
3/ Abacus Embeddings – achieves 99% accuracy on 100-digit addition problems by training on only 20-digit numbers with a single GPU; the main challenge this work addresses is the inability of transformers to track the exact position of digits.
-
Vision-Language Modeling: Introduction and Effective Training Methods
By
–
4/ Introduction to Vision-Language Modeling – presents an introduction to vision-language models along with key details of how they work and how to effectively train these models.