LangChainGEPA shout out to @bryonkuchML for contributing a PR to the GEPA repo to make it work for LangChain! You can now optimize your LangChain chains Docs: https://
gepa-ai.github.io/gepa/tutorials
/langchain_adapter_pair_sum_product_walkthrough/
…
MACHINE LEARNING
-

Optimize LangChain chains with GEPA now
By
–
-

Nemotron-Labs-Diffusion: tri-mode model boosts accuracy and throughput
By
–
Can one model switch between three decoding modes to crush both accuracy and throughput? NVIDIA researchers (with Georgia Tech, HKU, and MIT) introduce Nemotron-Labs-Diffusion — a tri-mode language model that unifies autoregressive (AR), diffusion, and self-speculation decoding
-

Microsoft transforms SKILL.md into trainable object with SkillOpt
By
–
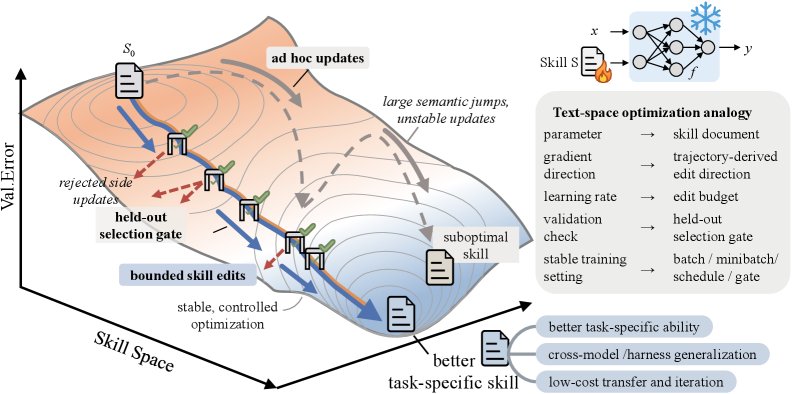
Microsoft just turned SKILL .md into a trainable object! SkillOpt is a text-space optimizer for agent skills. Instead of hand-writing or one-shot generating your SKILL .md, SkillOpt treats the skill document as the trainable external state of a frozen agent and optimizes it
-

Perplexity enhances Daily Digest with customizable sources and connectors
By
–
Perplexity keeps working on the Daily Digest feature, allowing users to precisely customise from where and which data needs to be pulled from. Memory, web sources, custom instructions and many connectors will be available.
-

Self-supervised learning cuts annotation costs, speeds up AI model deployment.
By
–
Self-supervised learning reduces annotation costs by generating labels from raw data, limiting manual effort. As models scale across business units, pretraining on unlabeled datasets shortens fine-tuning cycles and frees skilled teams for higher-value work. Microblog @antgrasso
-
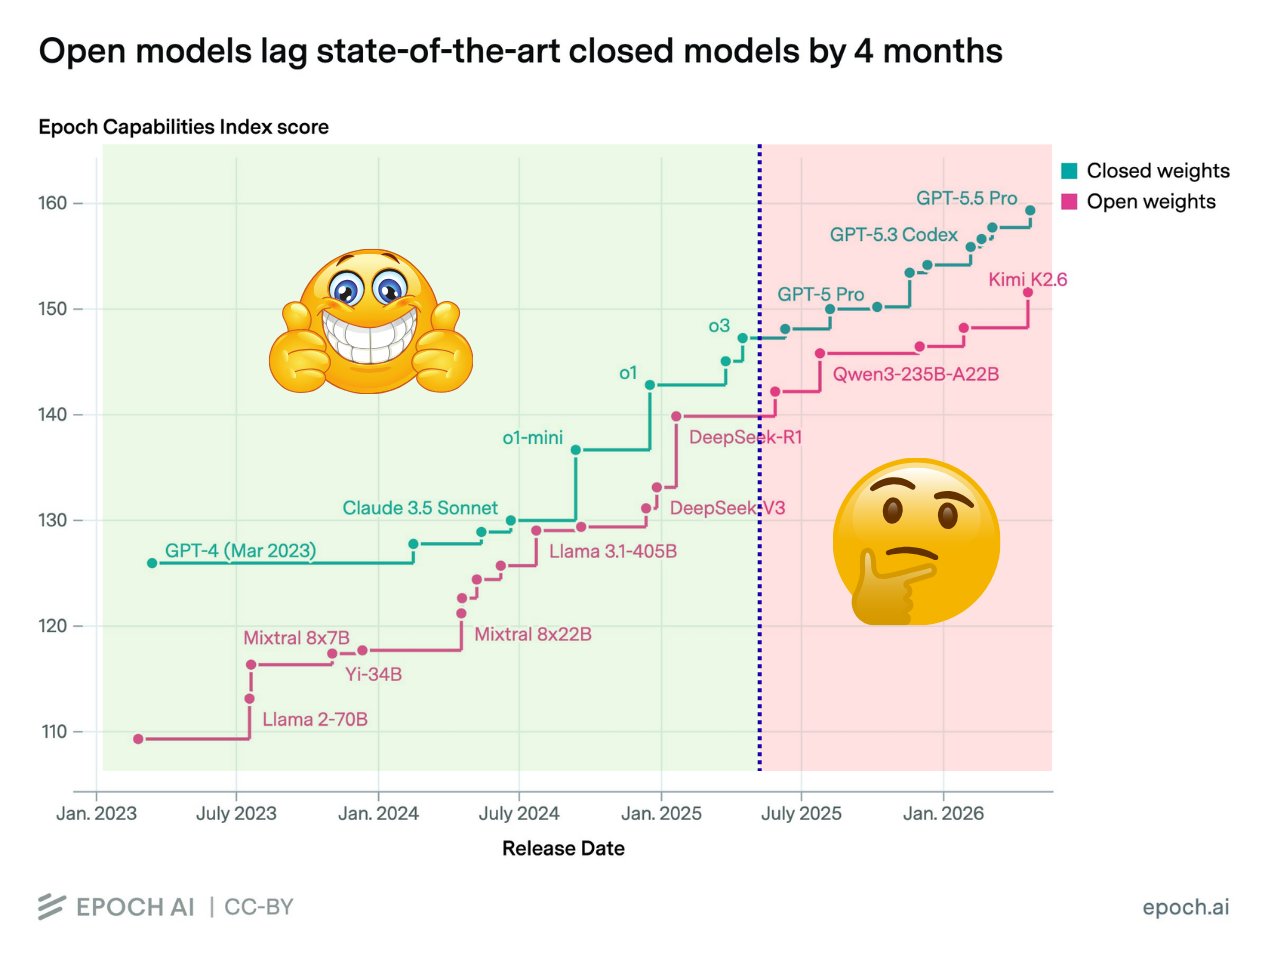
Opinion on DeepSeek R1, o1, and suspicious o3 benchmarks
By
–
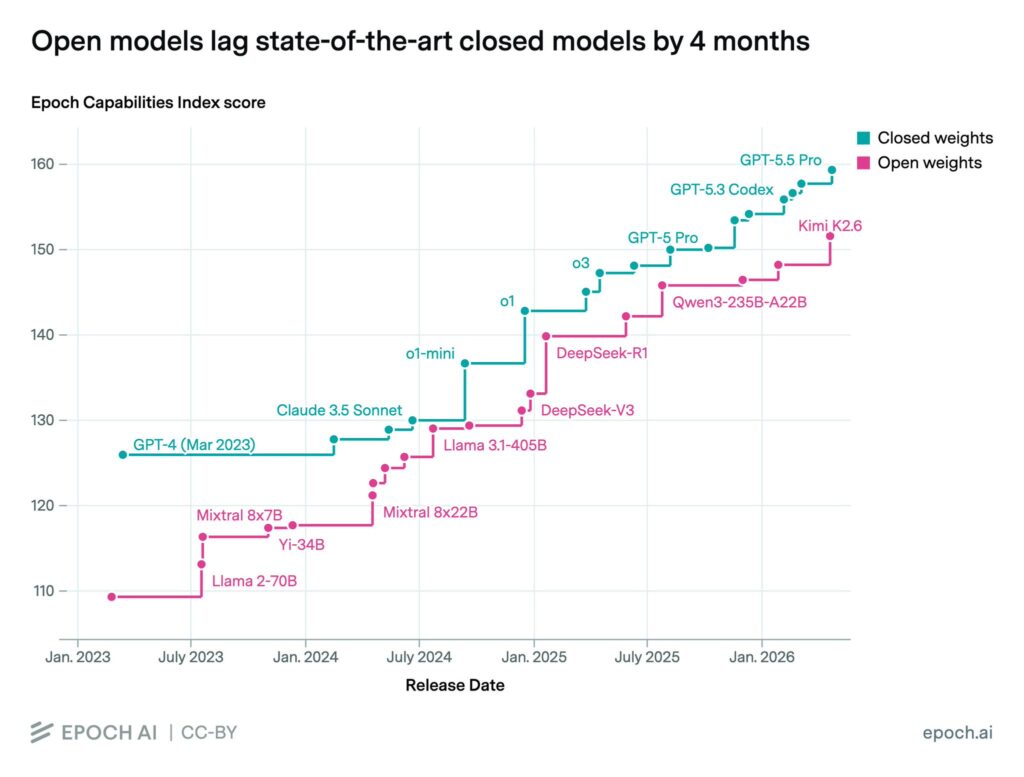
My personal vibes based opinion on this gap – at DeepSeek R1 level I believe this was real – o1 and r1 were not that far apart. From o3 onwards, I think there's something fishy going on with the benchmarks. Open models are not bad and certainly getting better, but the utility
-

The transformer inside an LLM: two blocks repeated
By
–
In our AI engineering workshops, one question comes up over and over. What's actually inside an LLM? The answer is one word. 𝗔 𝘁𝗿𝗮𝗻𝘀𝗳𝗼𝗿𝗺𝗲𝗿. And it's much simpler than the name makes it sound. A transformer is just two blocks, repeated many times. 𝗕𝗹𝗼𝗰𝗸 𝟭
-
Explain vs. Describe: Understanding the Nuance in AI Concepts
By
–
"Explain" vs. "Describe" These feel identical. They're not. "Explain RAG to me" gets you retrieval mechanics, why chunks are embedded, how context windows are populated, and where the architecture breaks. "Describe RAG to me" gets you a surface-level overview. What it looks
-

Too dangerous to release: Mythos sparks restricted AI era debate
By
–
Too dangerous to release: is Mythos the start of the restricted-#AI era?
by Chris Stokel-Walker @Nature Learn more: https://
bit.ly/3RN4zRM #GenerativeAI #ArtificialIntelligence #MachineLearning #ML -
GPT-5.6 improvement and token efficiency in agentic workflows
By
–
It’s reasonable to expect that the next iteration will be better. It would be surprising if GPT-5.6 wasnt an improvement over GPT-5.5. But the more interesting part is token efficiency. As models move into more complex, longer-running, agentic workflows, every wasted token