Diverse and Effective Red Teaming with Auto-generated Rewards and Multi-step Reinforcement Learning Alex Beutel, Kai Xiao, Johannes Heidecke, Lilian Weng @OpenAI https://
arxiv.org/pdf/2412.18693
v1
…
MACHINE LEARNING
-
Red Teaming AI Models with Reinforcement Learning Rewards
By
–
-
Adversarial Examples for Vision-Language Models via Diffusion
By
–
Efficient Generation of Targeted and Transferable Adversarial Examples for Vision-Language Models Via Diffusion Models https://
arxiv.org/abs/2404.10335 -
QiD Metric Measures LLM Training Levels and Token Requirements
By
–
the work proposes a novel perspective that we can use QiD to measure an LLM's training levels and determine the number of training tokens required for fully training LLMs of various sizes.
-
Low-Bit Quantization Favors Undertrained Large Language Models
By
–
Low-Bit Quantization Favors Undertrained LLMs: Scaling Laws for Quantized LLMs with 100T Training Tokens https://
arxiv.org/abs/2411.17691 -

Curating LLM Data: Best Practices and Strategies
By
–
Curating LLM data – Hamel’s Blog https://
bit.ly/3ZLa9Vm
#AI #MachineLearning #DeepLearning #LLMs #DataScience -
Essential AI Skills To Add To Your 2025 Resume
By
–
3 AI Skills To Include In Your Resume For 2025
#AI #AIio #BigData #ML #NLU #Futureofwork @ahier @guzmand
@DavidBrin @denisegarth @dez_blanchfield @diioannid @DioFavatas @gerald_bader -
Robot Manipulation Remains Harder Than Locomotion Despite Hype
By
–
“seemingly”: There has been recent progress in robot locomotion and driving but manipulation is much harder. After Elon and Jensen spot-lit humanoids this year, funding and PR accelerated rapidly, claiming “data will solve robotics”; but most roboticists are more cautious.
-
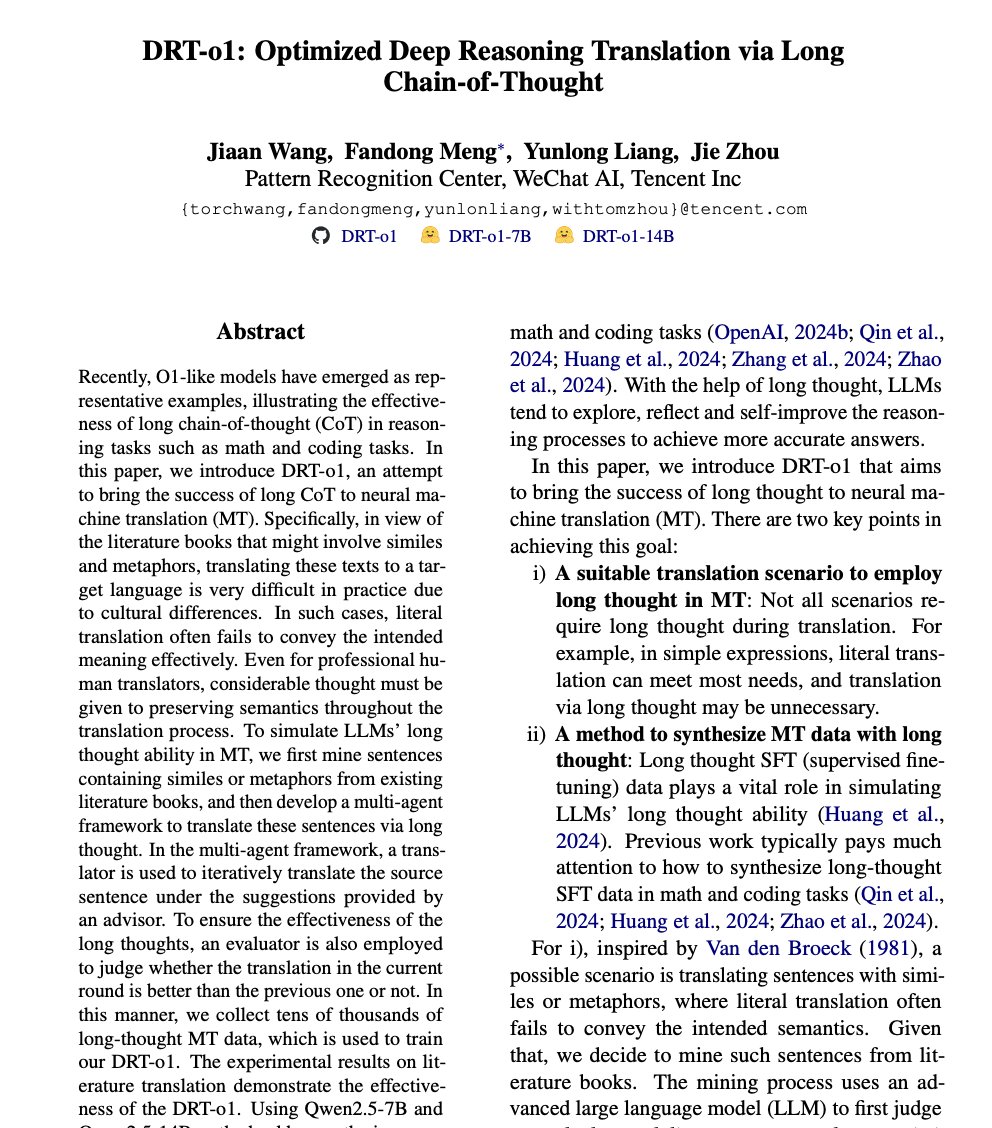
DRT-o1 Applies Long-Chain Reasoning to Machine Translation
By
–
10). DRT-o1 – applies long chain-of-thought reasoning to machine translation, particularly for handling metaphors and similes across different cultures.
-
CoMCTS: Enhancing Multimodal Models with Step-by-Step Reasoning
By
–
8). Empowering MLLM with o1-like Reasoning and Reflection – proposes a new learning-to-reason method called CoMCTS that enables multimodal language models to develop step-by-step reasoning capabilities by leveraging collective knowledge from multiple models.
-

Reinforcement Learning Overview: Comprehensive Guide
By
–
9). Reinforcement Learning Overview – presents a comprehensive overview of reinforcement learning.