
Seeing Isn't Knowing Do VLMs Know When Not to Answer Spatial Questions (and Why)?
MACHINE LEARNING
-
ElevenLabs previews on-device Text-to-Speech at Warsaw Summit
By
–
At the ElevenLabs Summit in Warsaw, we previewed on-device Text to Speech – a new model architecture that delivers human-level quality on limited hardware without an internet connection. pic.twitter.com/iZuztsIR9N
— ElevenLabs (@ElevenLabs) 2 juin 2026At the ElevenLabs Summit in Warsaw, we previewed on-device Text to Speech – a new model architecture that delivers human-level quality on limited hardware without an internet connection.
-

GPU Forecasters: Language Models as Selective Surrogates for Kernel Runtime Optimization
By
–
GPU Forecasters Language Models as Selective Surrogates for Kernel Runtime Optimization
-

Crafter: Multi-Agent Harness for Editable Scientific Figure Generation
By
–
Crafter A Multi-Agent Harness for Editable Scientific Figure Generation from Diverse Inputs
-
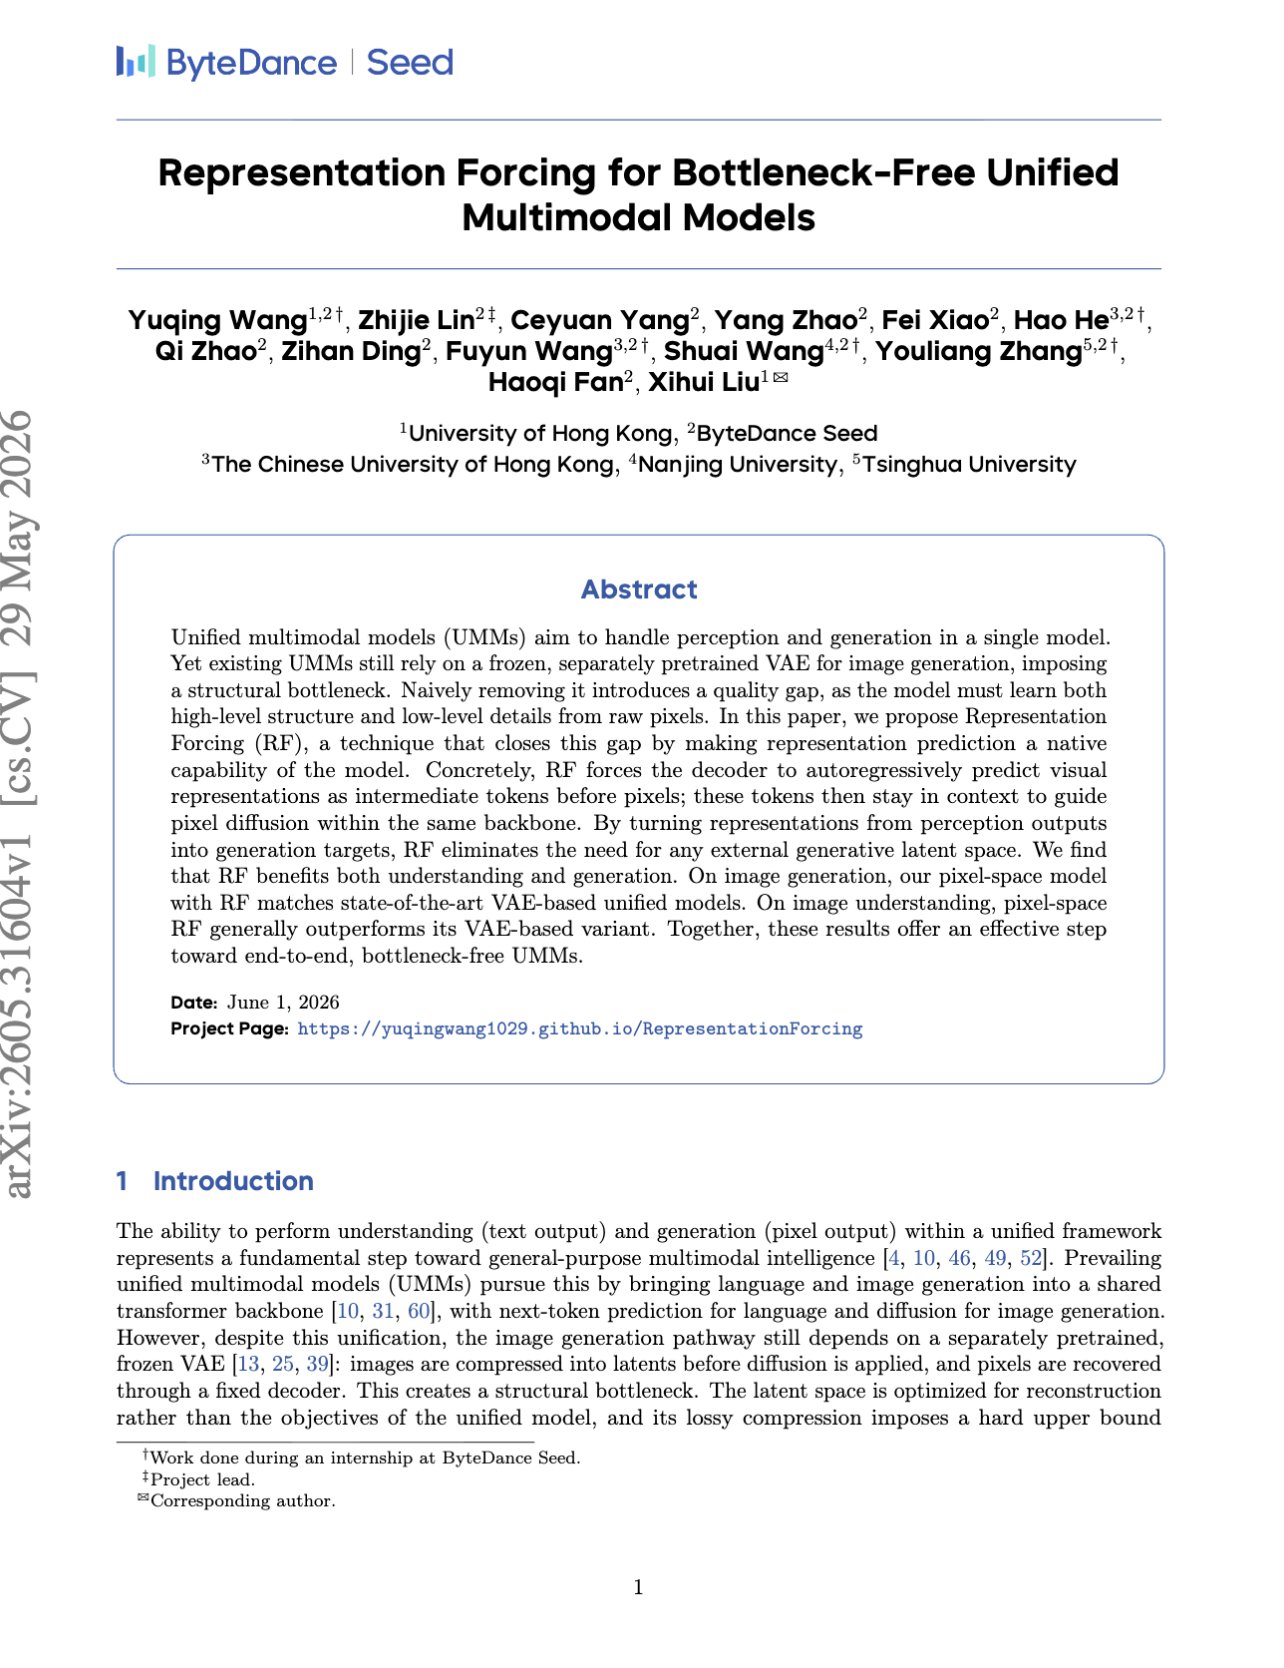
Representation Forcing for Bottleneck-Free Unified Multimodal Models
By
–
Most Unified Multimodal Models still generate images through a frozen VAE, which means perception and generation are not fully learned in one model. This paper fixes this by making the decoder first predict
-
Scobleizer tests a16z’s taste advice to improve AI news site design
By
–
In building https://
alignednews.com/ai one of my weaknesses has been design (it watches 30,000 posts every day and tells you what is important in AI). I will try this to see how its taste improves things. Thanks! Great to see you respond to @a16z
's "taste is what will matter in -
New paper reveals AI model scaling laws based on bytes, not tokens.
By
–
A new paper just exposed a setting that changes how AI models scale.
— AlphaSignal AI (@AlphaSignalAI) 2 juin 2026
Scaling laws tell labs how big a model should be for a given amount of data.
Until now, that math was always done in tokens.
A new paper rewrites the rule in bytes.
The team trained 988 models, from 50M… pic.twitter.com/G7j5tySh9VA new paper just exposed a setting that changes how AI models scale. Scaling laws tell labs how big a model should be for a given amount of data. Until now, that math was always done in tokens. A new paper rewrites the rule in bytes. The team trained 988 models, from 50M
-
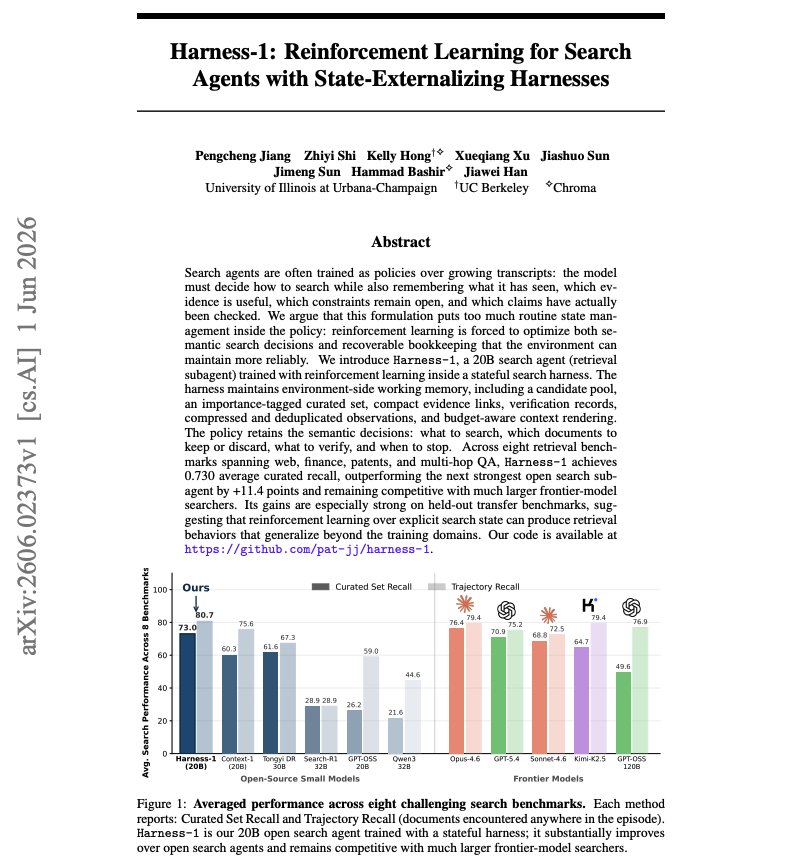
State-Externalizing Harnesses Shift Environment State from Policy to Harness
By
–
// State-Externalizing Harnesses // A new paradigm is emerging on how to effectively build agents and harnesses. If there is a state that the environment can maintain reliably, it probably doesn't belong inside the policy. Move it into the harness, and a 20B model trains
-
Seeking thoughts on Opus 4.8 after tepid reception
By
–
Almost a week later! What are your thoughts on Opus 4.8?
— Dan Shipper 📧 (@danshipper) 2 juin 2026
We were extremely bullish on it in testing—it seems the response was more tepid once y'all got your hands on it. If you disagreed with our take I'm curious why so we can tune our evaluations!
One theory I have is that by… https://t.co/nBUhzUbYRKAlmost a week later! What are your thoughts on Opus 4.8? We were extremely bullish on it in testing—it seems the response was more tepid once y'all got your hands on it. If you disagreed with our take I'm curious why so we can tune our evaluations! One theory I have is that by
