Search Arena revealed three factors strongly correlating with human preference: • Longer responses
• Higher citation counts
• Citations from community sources Sonar models had substantially higher search depth, citing 2-3x more sources than equivalent Gemini models.
MACHINE LEARNING
-
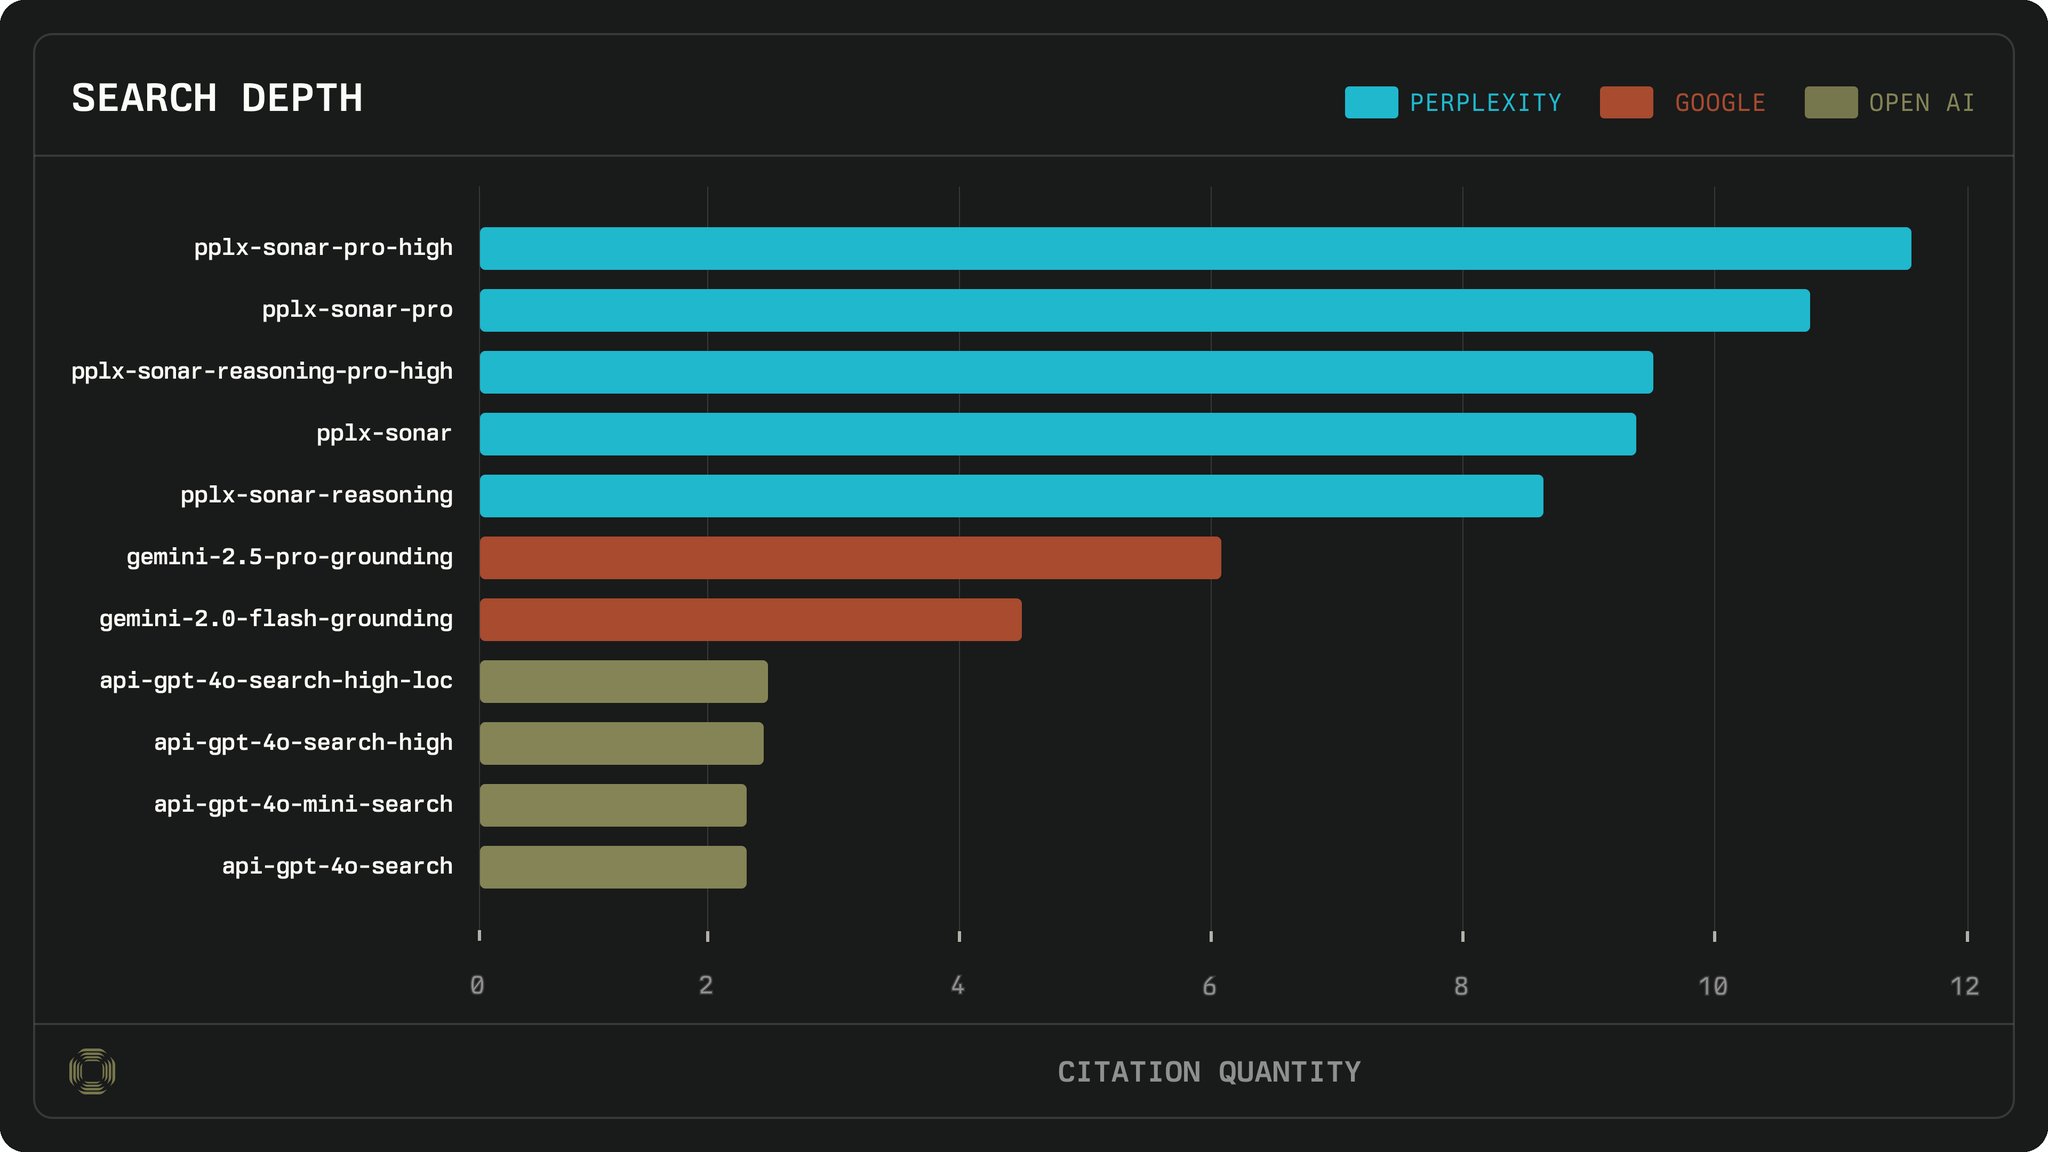
Search Arena reveals key factors in AI model preference rankings
By
–
-
Data vs Compute: The Real Bottleneck in AI Development
By
–
If you could afford a Cray, collecting 1.2 million digital images for ImageNet would not be a gating factor. DQN or AlphaGo didn’t need any data. The ChatGPT moment would have needed more data and compute, but the data would still be the lesser challenge.
-

Cray Vector Supercomputers Alternative Design for Deep Learning
By
–
There is an alternate reality where Cray took their vector supercomputers, ditched FP64 calculations, and went with one FP32 pipe and a BF16 tensor core pipe. The same instruction set, memory architecture, and vector registers would have made a sweet deep learning machine, in
-
Research Taste Training Difficulty in Robotics Scenarios
By
–
This scenario is interesting. No mention of robotics but I really like the notes about the difficulty of training for “research taste.”
-

GPT-4.1 Retrieves Multiple Similar Hidden Answers in Long Texts
By
–
GPT-4.1 peut trouver plusieurs réponses cachées dans un long texte, même si elles se ressemblent presque à l’identique.
-
Google Launches DolphinGemma LLM to Decode Dolphin Language
By
–
The CEO of Google announces to us a new AI capable of understanding dolphin language. Yes, you're not dreaming. Translation: Introducing DolphinGemma, a language model (LLM) fine-tuned from several years of dolphin sound data to advance scientific research. We collaborated
-

Major AI Updates from Google, OpenAI, Microsoft, Meta, and More
By
–
L’IA est totalement incontrôlable Des MÀJ MASSIVES dans le monde de l’intelligence artificielle cette semaine, venant de : Google
OpenAI
Microsoft
Canva
Meta
…et bien plus encore ! Voici le récapitulatif de tout ce que vous ne devez surtout pas manquer : -

Large Language Models May Be Rote Learners, Not Understanding
By
–
It challenges the assumption that memorization implies understanding.
Large Language Models Could Be Rote Learners
Link:
https://
arxiv.org/pdf/2504.08300 -

LLMs Show Lower Performance on Memorized Multiple-Choice Questions
By
–
Large language models exhibit lower performance on memorized multiple-choice questions compared to non-memorized ones.
This counterintuitive finding suggests the coexistence of two distinct learning mechanisms: rote memorization and genuine capability acquisition. -

OpenAI to launch o3, o4-mini, GPT-4.1 models this week
By
–


BREAKING : OpenAI is preparing to launch several new models this week: – Full o3, – o4-mini, – GPT-4.1, 4.1 nano, 4.1 mini As model cards have been updated recently on the website Image by @MeetPatelTech