
¡NUEVO VÍDEO en el LAB! El paper de la semana sin duda proviene de la compañía de la manzana, y es que su última investigación ha causado mucho ruido. ¿Las IAs NO razonan? ¿Es todo una ilusión? Hoy os explico de qué trata este paper y por qué a mi no me ha gustado
MACHINE LEARNING
-
AI Evolution: From Fixed Systems to Dynamic Personalization
By
–
Yesterday’s tech: fixed, uniform, one-size-fits-all. Today’s AI: dynamic, personal, emergent. One outcome on repeat vs. infinite possible paths.
-

Mistral’s New Reasoning Model Opens Innovation Opportunities
By
–
this new reasoning model from Mistral looks cool
— dr. jack morris (@jxmnop) 10 juin 2025
it's especially exciting that because no one knows the best way to do RL, there is a lot of room for smaller players to innovate. this wasn't really the case when we spent a few years just making models bigger. https://t.co/Qa5yd5PdZVthis new reasoning model from Mistral looks cool it's especially exciting that because no one knows the best way to do RL, there is a lot of room for smaller players to innovate. this wasn't really the case when we spent a few years just making models bigger.
-
Steps to build an AI model with Apob
By
–
Étape 2 : Construisez votre modèle IA avec Apob :
— Jouhatsu | AI Influence Operator (@Jouhatsu_ai) 10 juin 2025
1. Visitez : https://t.co/LSPCvAt7eO
2. Sélectionnez ou téléchargez une image.
3. Personnalisez-la à votre goût.
4. Choisissez un style ou rédigez un prompt spécifique.
5. Ajoutez les caractéristiques nécessaires.
Et voilà,… pic.twitter.com/VZEgDqHe4mStep 2: Build your AI model with Apob: 1. Visit:
https://
mega.apob.ai/Jouhatsu2 2. Select or upload an image.
3. Customize it to your liking.
4. Choose a style or write a specific prompt.
5. Add the necessary features. And there you have it, -
LLaVA-1.5: Building State-of-the-Art AI Visual Assistants
By
–
Ever wondered how a state-of-the-art AI visual assistant is actually built?
— Satya Mallick (@LearnOpenCV) 10 juin 2025
Our new technical deep dive breaks down the LLaVA-1.5 architecture, its groundbreaking Visual Instruction Tuning, and the open-source datasets that changed the game for multimodal AI.
A must-read for… pic.twitter.com/USfjcJ8fkeEver wondered how a state-of-the-art AI visual assistant is actually built?
Our new technical deep dive breaks down the LLaVA-1.5 architecture, its groundbreaking Visual Instruction Tuning, and the open-source datasets that changed the game for multimodal AI. A must-read for -

Multimodal Reasoning Emerges from Online RL Training
By
–
We also found that multimodal reasoning capabilities emerge naturally after online RL (even when RL is only done on math & code text data), as long as you start from an initial multimodal model.
-
Distilled Models Gain from Online RL Training Beyond Initial Distillation
By
–
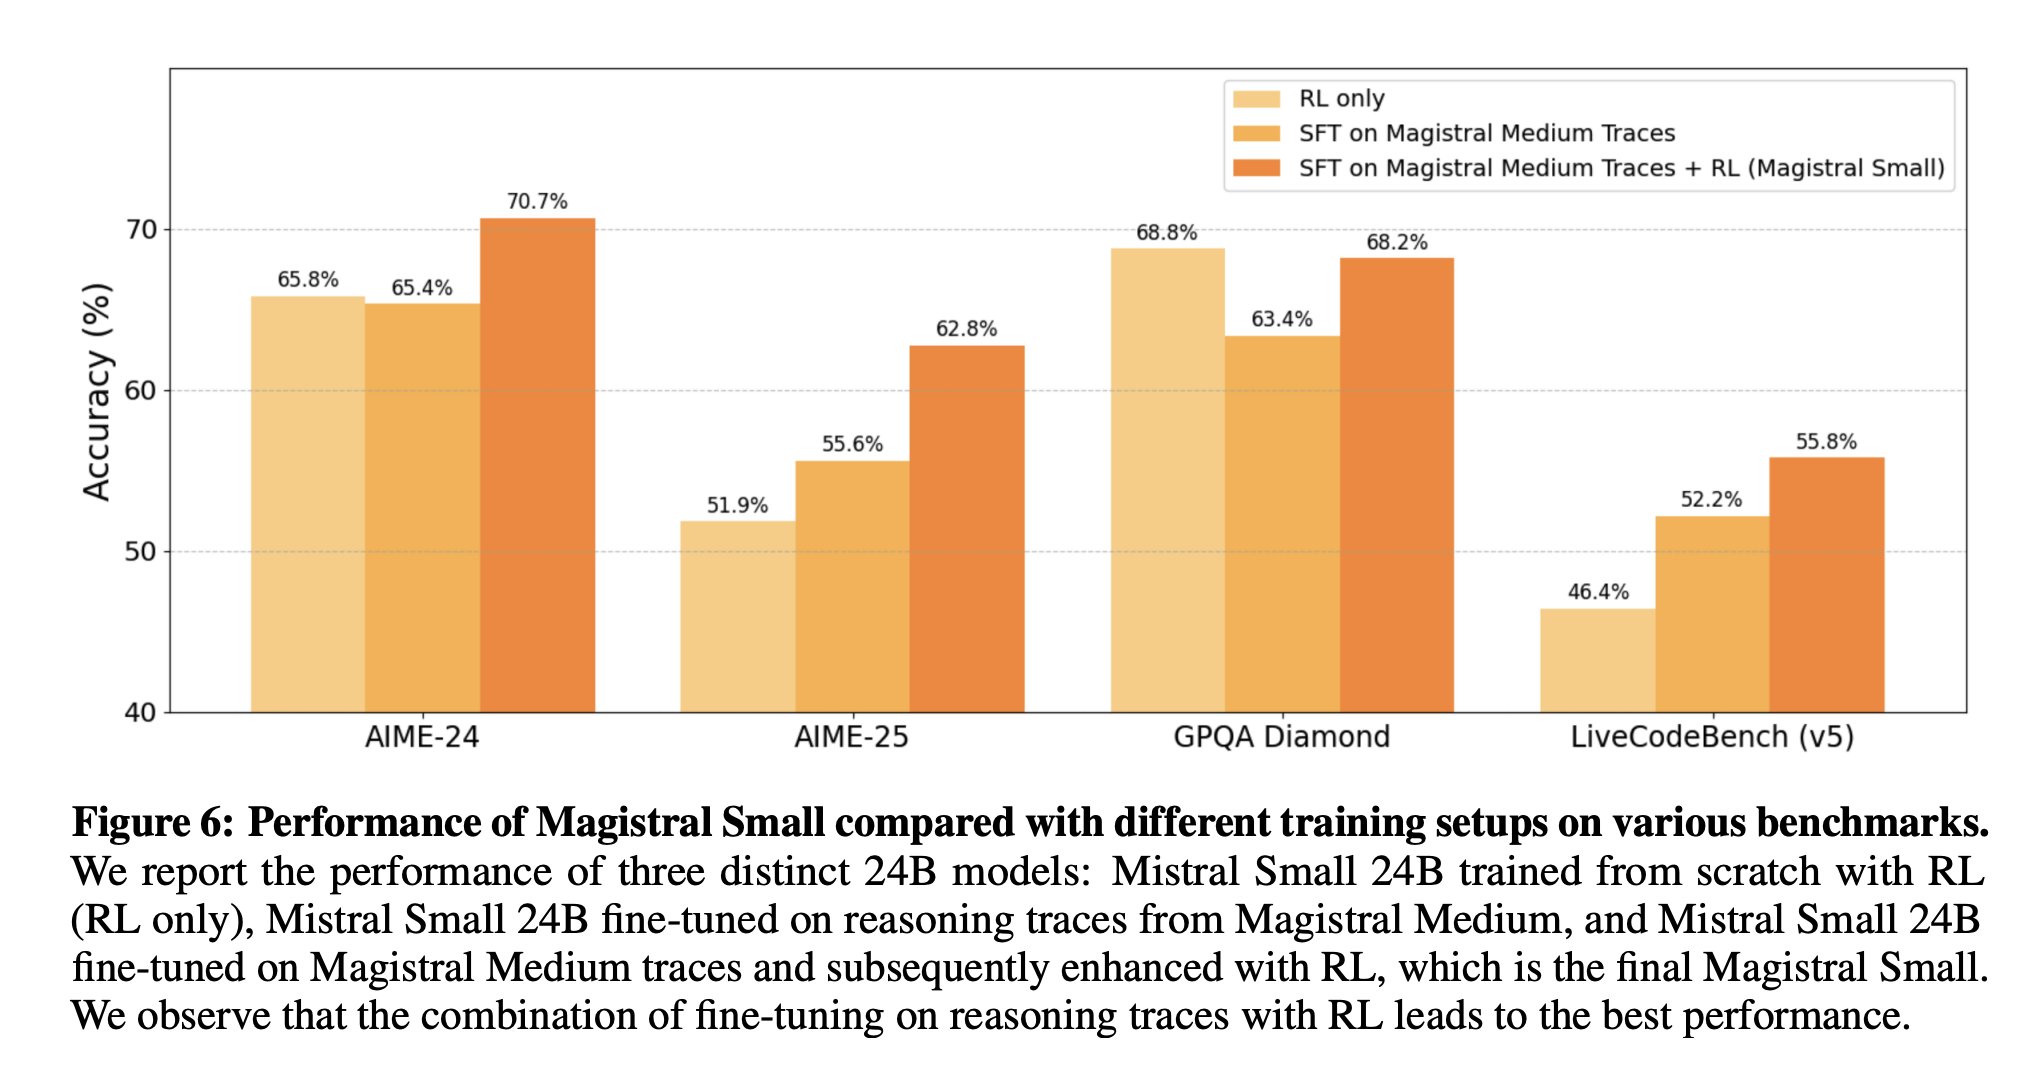
We found that a model distilled on reasoning traces from a larger model still benefits a lot from additional online RL training. In particular, we trained Magistral Small by distilling it from Magistral Medium and running additional RL.
-
Magistral: First Reasoning Model Release with Weights and Research Paper
By
–
Very excited to release our first reasoning model, Magistral. We released the weights of Magistral Small alongside a paper that presents our approach, online RL infrastructure, and findings. https://t.co/8hlqalBHjG pic.twitter.com/tNHxU5d1WI
— Guillaume Lample @ NeurIPS 2024 (@GuillaumeLample) 10 juin 2025Very excited to release our first reasoning model, Magistral. We released the weights of Magistral Small alongside a paper that presents our approach, online RL infrastructure, and findings.
-

Agents Hack next Sunday: 10k€ prizes with Hugging Face, AnthropicAI, Accel
By
–
Reminder: our Agents Hack is next Sunday ! It's shaping up to be the biggest ever hackathon on Agents in Paris, with over 10k€ in prizes, including large cash prizes for the top 3 teams. And now, @huggingface and @AnthropicAI are joined by @Accel : this will bring a bit of
-

Can LLMs Truly Introspect or Just Mimic Human Responses?
By
–
I think therefore I LLM Can AI actually introspect or is it just copying human responses? Turns out mostly copying, but LLMs can genuinely analyze some of their own internal settings. Temperature detection works. Other "self-awareness" claims are dubious.