The Data Flywheel Is the Next Competitive Advantage Leaders are building self-reinforcing AI loops to make their AI smarter: proprietary data → better models → more usage → better data. Why it matters: Owning the flywheel = differentiation + market leadership.
MACHINE LEARNING
-

PyTorch Training Resilience During Infrastructure Failures
By
–
the model keeps on training even when the underlying infra keeps failing….out-of-the-box PyTorch
-
WSDM 2009 Talk Slides on Google Search System Evolution
By
–
A set of slides from a talk I gave at WSDM 2009 describes some aspects of our search system evolution up to then: https://
static.googleusercontent.com/media/research
.google.com/en//people/jeff/WSDM09-keynote.pdf
… of talk: -
Machine Learning Summit 2025 Virtual Event with 40% Discount
By
–
Coming in July >> #MachineLearning Summit 2025 — The Hands-On Virtual Summit for Real-World ML Hosted by @PacktPublishing @PacktDataML Register now with my code KIRK40 — Get 40% OFF Registration: https://
eventbrite.com/e/machine-lear
ning-summit-2025-tickets-1332848338259?aff=kirk
… 25+ top AI, ML leaders will be speaking across 3 tracks -
Discrete Text Optimization Challenges in Language Models
By
–
you're right that it's the discreteness of text that makes this problem extremely hard but also the problem you're imagining requires optimizing over optimization processes, which is also very hard what you're describing sort of works for images, e.g. this
-
Jensen Huang Demos Greg Robot Trained in Simulation at VivaTech
By
–
🇫🇷 Jensen Huang a présenté Greg au vivatech paris.
— VISION IA (@vision_ia) 20 juin 2025
Un robot qui a appris à marcher, sauter, danser… dans un monde virtuel. 100 000 réalités simulées.
Puis, il a simplement été déployé dans la réalité. https://t.co/fCwc1FcAhb pic.twitter.com/SIlwmJz9zyJensen Huang introduced Greg at VivaTech Paris. A robot that learned to walk, jump, dance… in a virtual world. 100,000 simulated realities. Then, it was simply deployed into reality.
-
New Research Paper Published on ArXiv
By
–
finally check out our paper on arxiv, out yesterday! 🙂 http://
arxiv.org/abs/2506.15553 -
Extracting Hidden Information from Model Weights
By
–
im pretty convinced that there's significantly more information available in model weights, we just dont yet have tools to extract it in some sense that info is super "compressed" and we aren't sure how to build a proper decompressor our work is a tiny first step.
-
Embeddings Recovery with Minimal Data Requirements
By
–
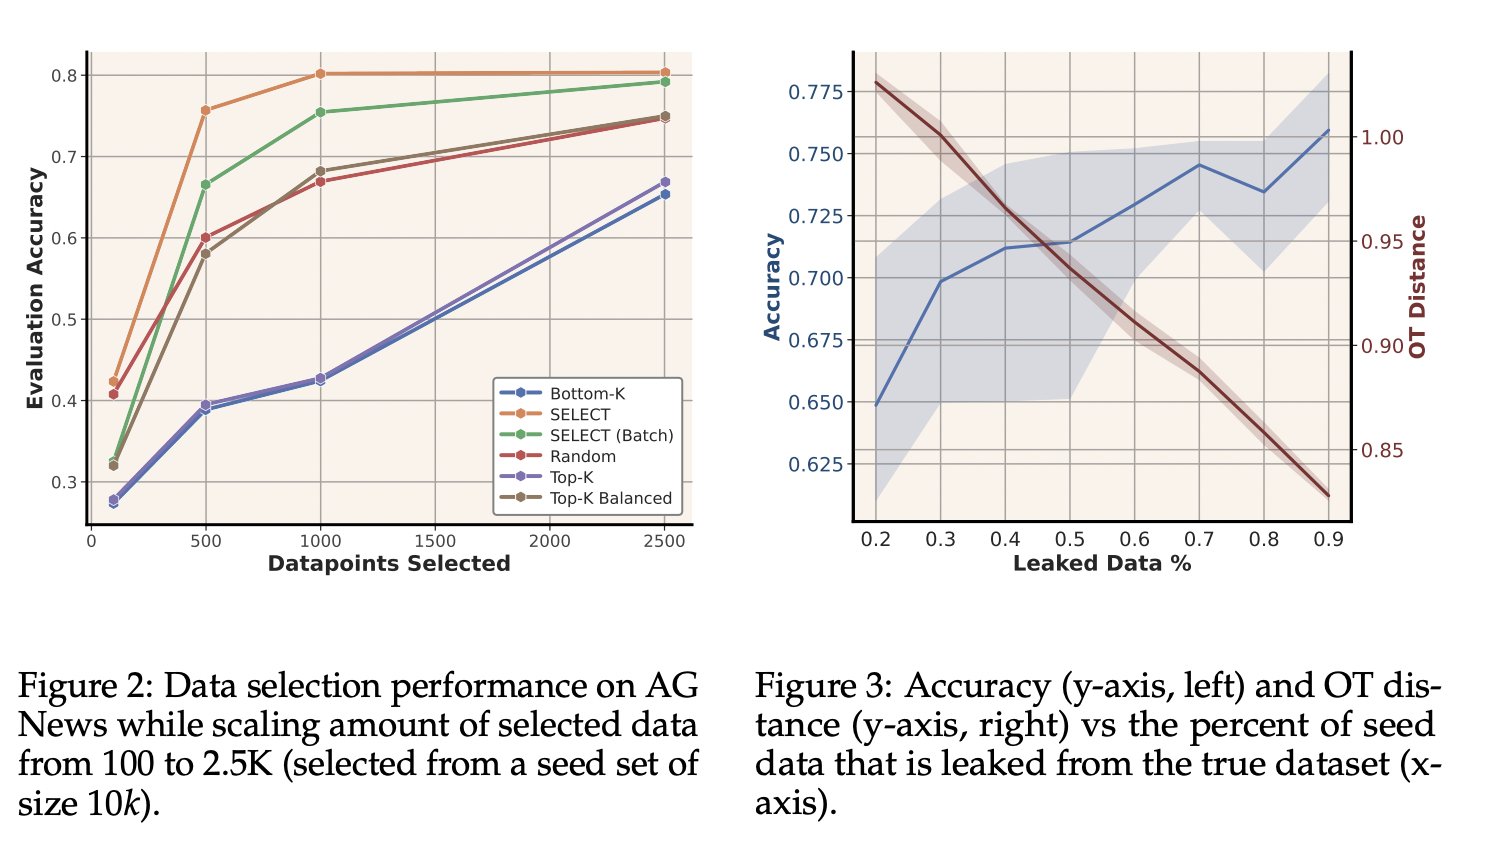
there are some other nice properties: – we can get good performance with very little data
– we recover embeddings that "look" like the original dataset
– when some percentage of the original data is available, we generally select that data first