
a random detail that I found cool is that AdamW seems to "obfuscate" weights a bit better than Adam or vanilla SGD guessing this is bc weight decay does something nonlinear during optimization, which decreases the amount of information available in weights
MACHINE LEARNING
-

SELECT: Training Models with Limited Data Access
By
–
…but it works we try a bunch of baselines like selecting data based on likelihood or even the top-k per-class our method (SELECT) can train a model to similar performance, with access only to model weights and some web data
-
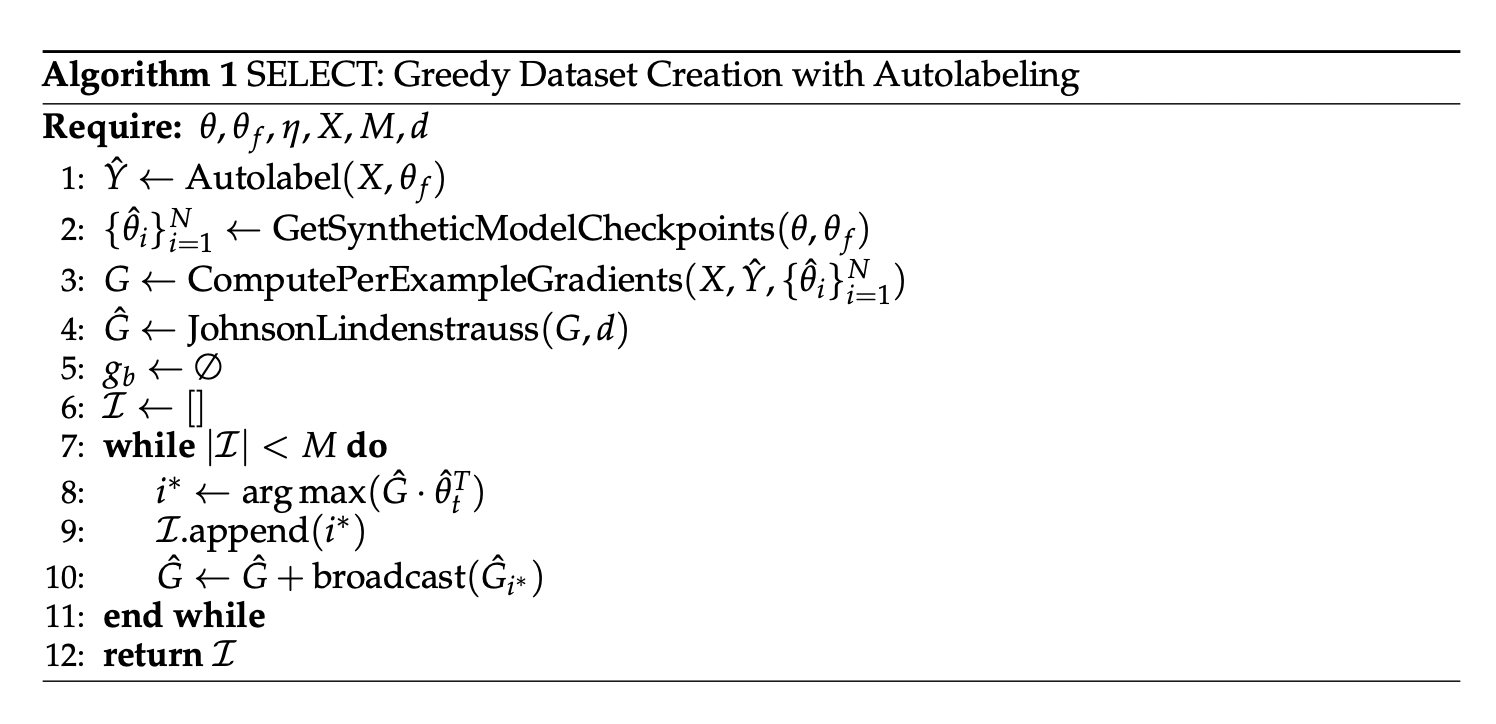
Scaling Per-Example Gradients: Algorithm Efficiency Improvements
By
–
our algorithm is a bit complicated, mostly because computing per-example gradients is hard to do at scale so we make some efficiency improvements:
– computing grads w vmap
– only using last-layer grads (which are still big, in the case of LMs)
– projecting them to a smaller dim -
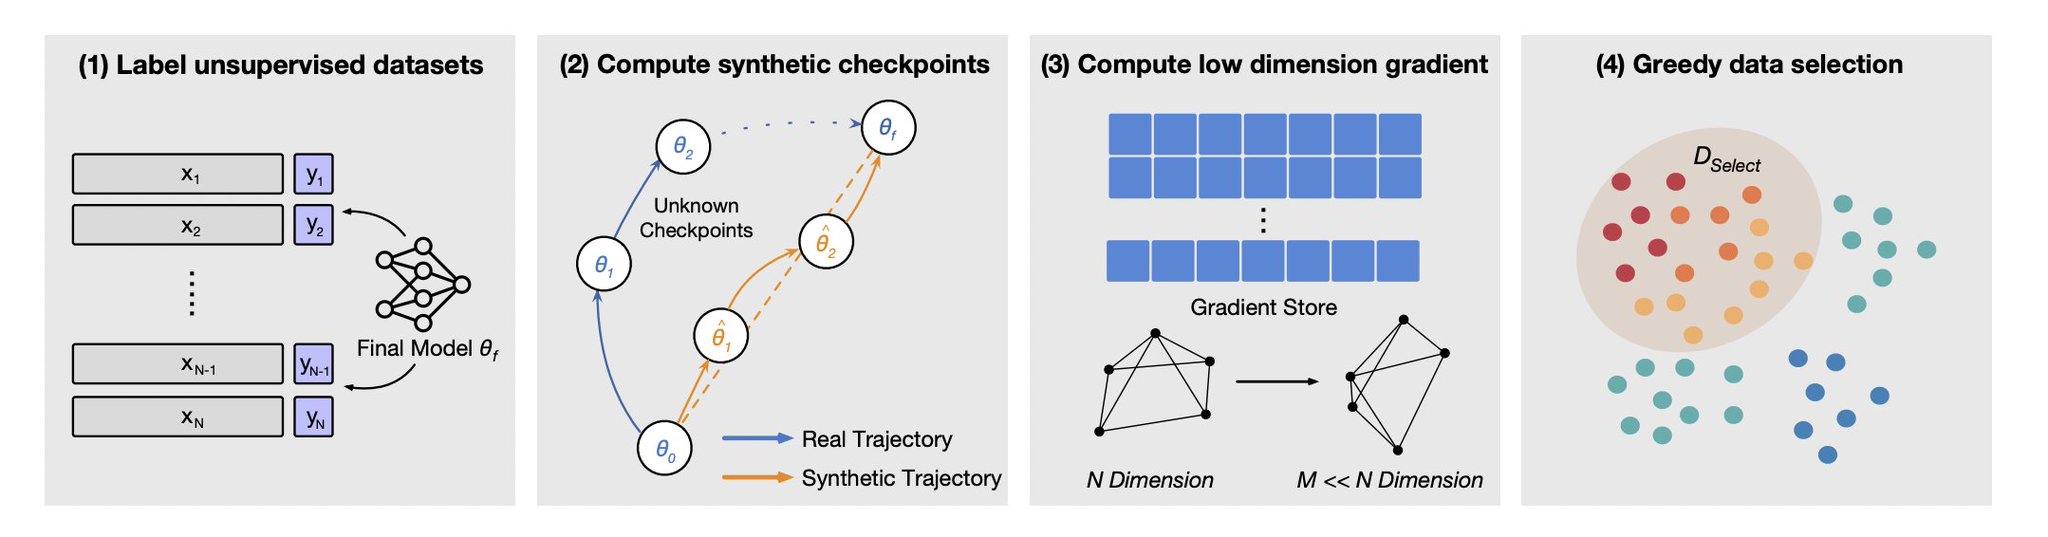
Finetuning AI Models: Gradient-Based Data Selection Strategy
By
–
to do this, you need TWO sets of model weights: the initial model and a finetune this is realistic. open-weights models often come with two checkpoints instead of one-shot generating data from weights, we select data from the web with gradients that point along the model diff
-
FastDiffusion course teaches comprehensive diffusion model knowledge
By
–
If you finish the fastdiffusion course you'll know a *lot* about diffusion 😀
-
Karpathy’s Presentation: Must-Read AI Content
By
–
Thank you @karpathy and @garrytan for sharing this incredible presentation. It's the best thing I've read all year. You can download Andrej's full presentation here:
-

Karpathy Presentation Key Takeaways Summary
By
–
My friend @gregisenberg has a great breakdown of the key takeaways from Karpathy's presentation. Bookmark this summary as a reference
-
Tesla Autopilot Demonstrates Optimal Partial Autonomy Architecture
By
–
Tesla Autopilot shows why partial autonomy is the sweet spot. It handles highway driving but keeps humans in control for complex decisions like intersections and city streets. Ship the 80% that works reliably, let humans handle the rest.
-

Software 3.0 Consuming Software Itself: The Next Evolution
By
–
@pmarca famously said 'software is eating the world.' Now, Software 3.0 is eating software itself. Software 1.0 and 2.0 are being absorbed into something more powerful. What happens next?
-
Open Source AI Simulates Pro Bokeh Effect on Any Video
By
–
Vous n’avez pas besoin d’une caméra à 30 000€ pour avoir un rendu cinéma.
— VISION IA (@vision_ia) 20 juin 2025
Une IA open source permet désormais de simuler un flou d’arrière-plan pro (le fameux "bokeh")… depuis n’importe quelle vidéo.
Effet bluffant. Gratuit. Et dispo maintenant.
Je vous montre. pic.twitter.com/amb3SmKI9LVous n’avez pas besoin d’une caméra à 30 000€ pour avoir un rendu cinéma. Une IA open source permet désormais de simuler un flou d’arrière-plan pro (le fameux "bokeh")… depuis n’importe quelle vidéo. Effet bluffant. Gratuit. Et dispo maintenant. Je vous montre.