Our thanks to everyone who dropped by yesterday for boba to learn from @EchoShao8899 of @stanfordnlp about "Collaborative Gym: A Framework for Enabling and Evaluating Human-Agent Collaboration". Key takeaway: across 3 tasks (travel planning, related-work writing, and tabular
MACHINE LEARNING
-
Cog’s first eval ship offers private 100-hour enterprise evals with financial guarantee
By
–
Finally! the first eval ship from cog!!!!!!!!!! To contextualize: @METR_Evals cap out at ~16 hours. Cog has private enterprise evals up to 100hrs, and is confident enough to put a financial guarantee on it METR dataset: ML eng, GPU kernels, cybersecurity > "METR (2026)
-

No shortcuts to frontier: detailed technical report on MAI-Thinking-1
By
–
There are no shortcuts to the frontier. Disciplined, patient, meticulous attention to detail is critical. To give everyone a good sense of our progress we've published a very detailed technical report (109 pages!) outlining how we trained MAI-Thinking-1 and what we learned along
-
Isaac Sim & Lab: Easier autonomy stack testing in scalable simulation
By
–
Isaac Sim and Isaac Lab partnerships make it easier to bring autonomy stacks into scalable simulation environments for testing these scenarios.
-
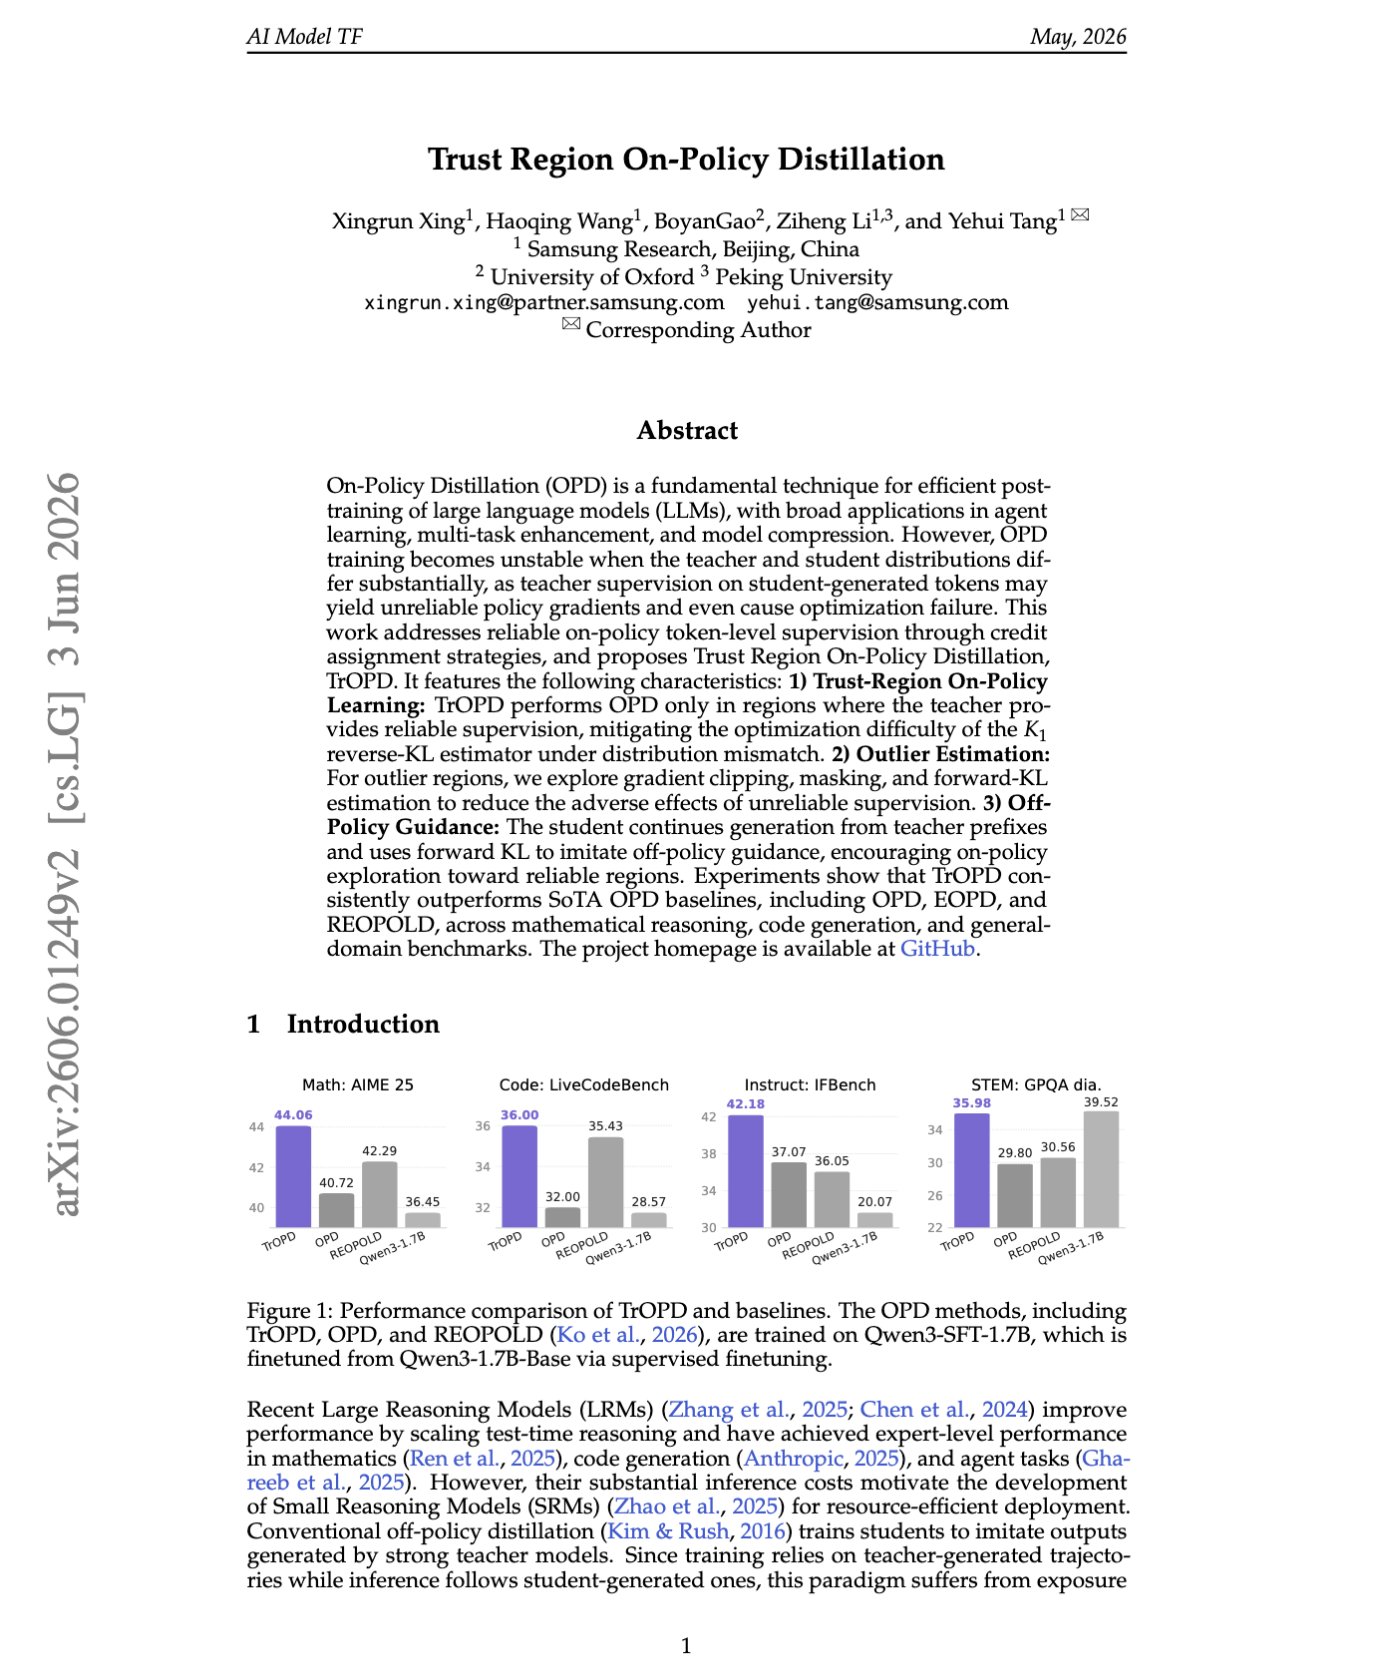
Trust Region On-Policy Distillation: Learning from reliable teacher signals
By
–
“Trust Region On-Policy Distillation” On-policy distillation is powerful, but one bad mismatch between student and teacher can negatively impact the gradients. So this paper's TrOPD only learns where the teacher is reliable, treats outliers separately, and nudges the student
-
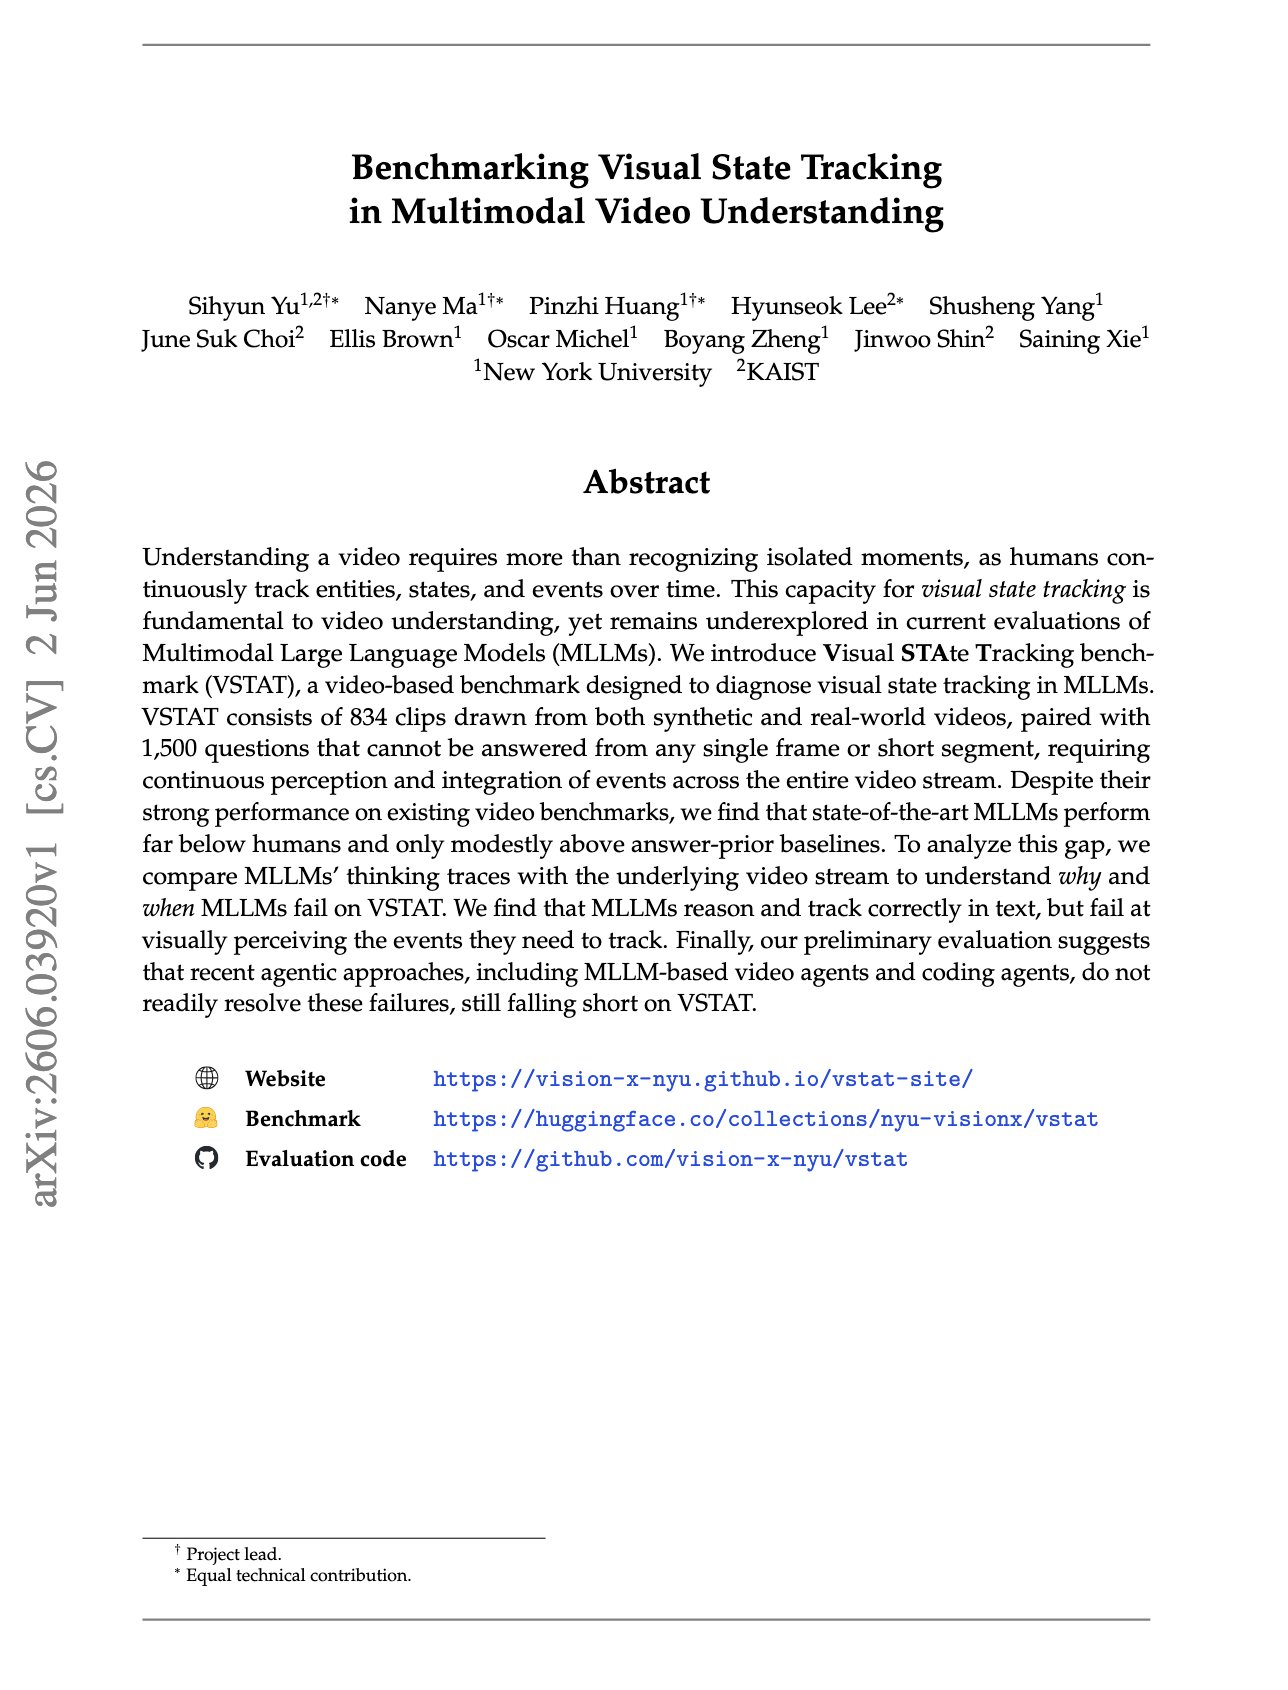
New Benchmark for Visual State Tracking in Video Understanding
By
–
"Benchmarking Visual State Tracking in Multimodal Understanding" A new benchmark for tracking visual states. Even though video MLLMs can describe clips really well, they still cannot reliably track what changes over time. This benchmark contains 834 videos and 1,500
-

SambaNova unveils disaggregated inference demo and SN50 RDU for AI agents
By
–
Premium inference is powering the next generation of AI agents. First live disaggregated inference demo for AI agents New SN50 RDU purpose-built for agentic inference Faster, more efficient AI with industry-leading throughput See what's next for AI inference:
-

Anthropic publishes research on accelerated AI and self-improvement
By
–
ANTHROPIC : A new internal research has been published, highlighting an accelerated AI development and a potential path to recursive self-improvement. > Claude Mythos Preview could work for “at least” 16 hours and was “at the upper end of [METR] can measure.” > Today,
-
Anthropic: Claude writes more than 80% of merged code
By
–
We have just published internal data on the share of Claude's development that is already done by Claude: – More than 80% of all merged code in our codebase is now written by Claude – It has been months that many researchers at Anthropic
-
Every learning algorithm is recursive self-improvement
By
–
Every learning algorithm is recursive self-improvement.