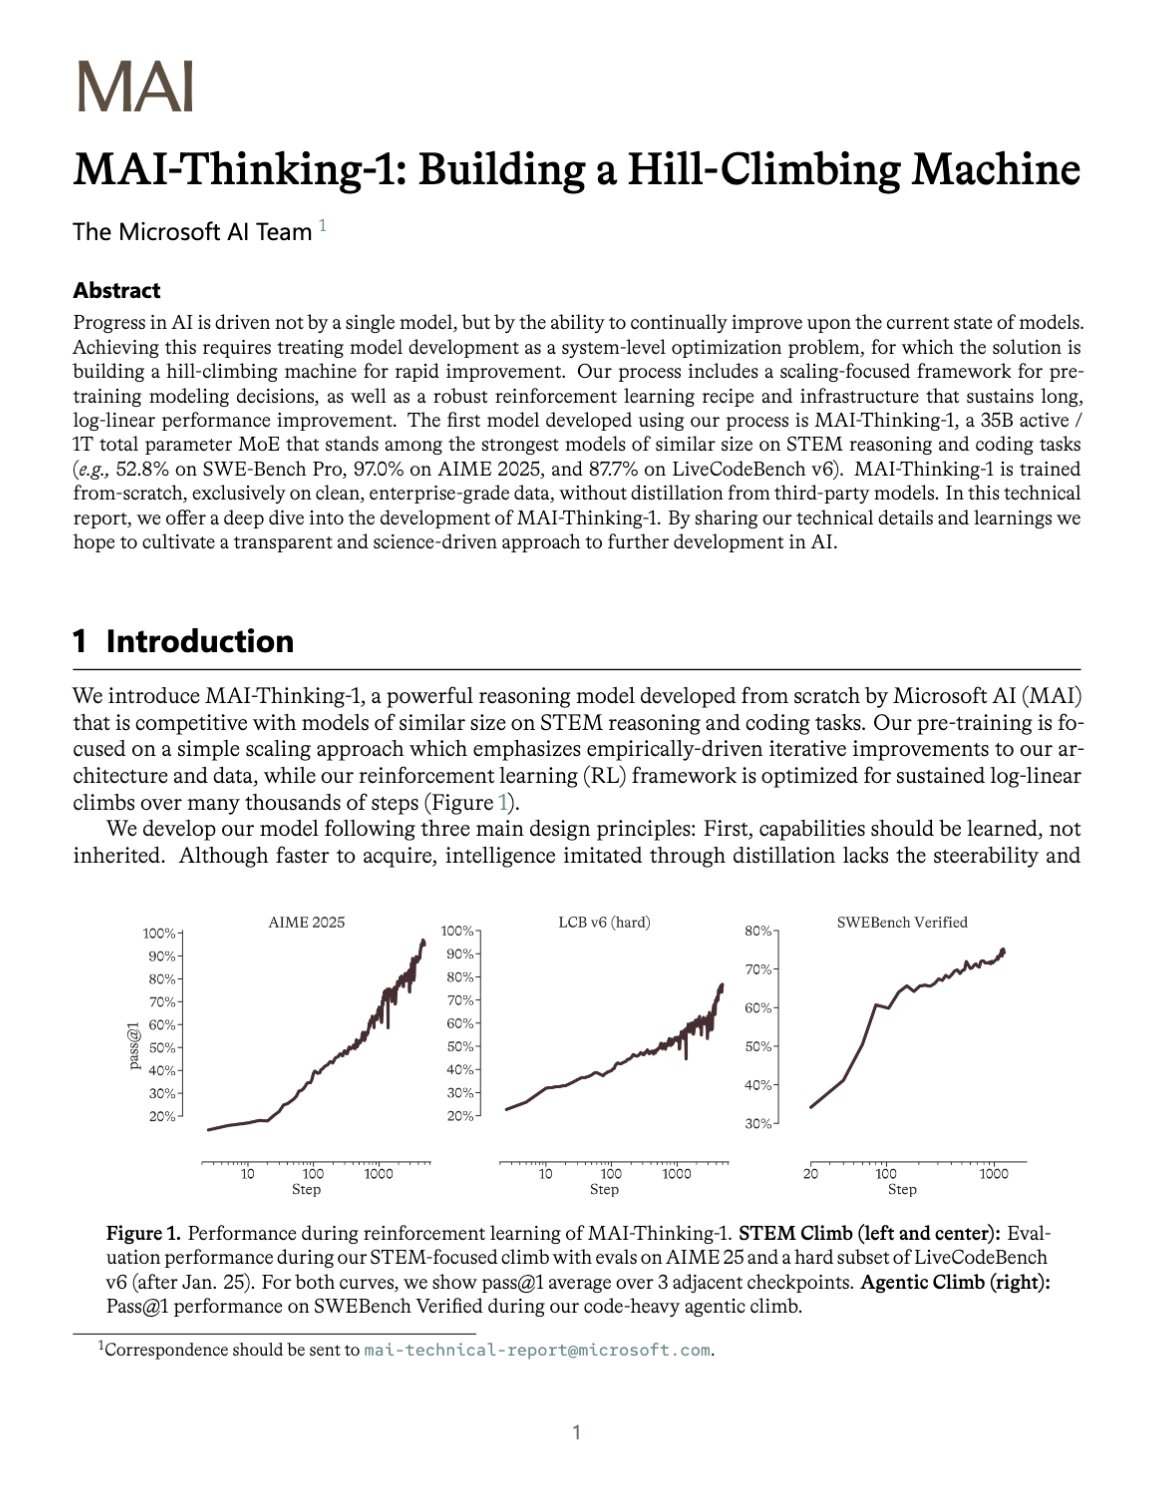
"MAI-Thinking-1: Building a Hill-Climbing Machine" Microsoft just did something almost no frontier AI lab has done before They shared how they engineered the data behind a frontier-scale model in unusual depth. From data collection and eval decontamination, to data mix
MACHINE LEARNING
-
World models vs language models: Fei-Fei Li’s taxonomy
By
–
Language models gave AI the ability to talk about the world. World models will give AI the ability to understand it. But “world model” is an overloaded term. What does it mean? HAI Founding Director @drfeifei offers the taxonomy that matters now. https://
brnw.ch/21x36eY -

NVIDIA’s Rafiqspace AI achieves 97.7% Bahasa Indonesia ASR accuracy
By
–
When laws and oversight depend on transcripts, 70–80% isn’t enough. http://
Rafiqspace.ai hit 97.7% Bahasa Indonesia accuracy (2.3% WER) with fine‑tuned Nemotron Parakeet ASR—outperforming global tools while cutting per‑hour costs by up to 90%. -
Everything You Need to Know About Inference Engines and Local LLMs
By
–
Everything You Need To Know About
Inference Engines and Running LLMs Locally at Home Explains why Inference Engines exist in the first place
– Prefill is not Decode
– VRAM is not bandwidth
– Fit is not speed
– KV Cache is the real memory problem
– Quantization only matters if -

NVIDIA Nemotron 3 Ultra solves AI agent fatigue and cost issues
By
–
AI agents don't just get expensive.
They get tired.
As workflows become longer, agents suffer from goal drift, context overload, and rising token costs.
NVIDIA's Nemotron 3 Ultra aims to fix that: Hybrid Mamba + Transformer 1M-token context 5x throughput 30% lower -
Podcast: AI Industrial Revolution with Naval, Rauchg, Hodak, Scholl
By
–
Full podcast episode with @rauchg, @maxhodak_, and @bscholl.
— Naval (@naval) 4 juin 2026
40 minutes of unreleased material.
The AI Industrial Revolution
Part 1: Waste Tokens, Save Time
0:00 Three Frontier Founders
1:27 AI Software Factories
4:15 Waste Tokens, Save Time
5:47 Models Instructing Humans… pic.twitter.com/llIMFJMZgVFull podcast episode with @rauchg
, @maxhodak_
, and @bscholl
. 40 minutes of unreleased material. The AI Industrial Revolution Part 1: Waste Tokens, Save Time 0:00 Three Frontier Founders
1:27 AI Software Factories
4:15 Waste Tokens, Save Time
5:47 Models Instructing Humans -
Model finds counterexample to 80-year-old Erdős conjecture
By
–
What happened when one of our models found a counterexample to an 80-year-old Erdős conjecture?
— OpenAI (@OpenAI) 4 juin 2026
Researchers @alexwei_, @HongxunWu, and @wjmzbmr1 shared the story on the OpenAI Podcast with @AndrewMayne and explained how mathematicians and models can work together to make new… pic.twitter.com/bQQ6Bvr8QhWhat happened when one of our models found a counterexample to an 80-year-old Erdős conjecture? Researchers @alexwei_
, @HongxunWu
, and @wjmzbmr1 shared the story on the OpenAI Podcast with @AndrewMayne and explained how mathematicians and models can work together to make new -

Spiral 4.0: AI Writing Partner with Stylometry for Agents and Brands
By
–
NEW: Spiral 4.0—a writing partner for you and your agent by @every -> Stylometry: we built a new Style Engine based on the principles of stylometry to extract you and your brand's voice and produce great writing every time, based on examples of your past work -> MCP and CLI:
-
Max Agency: Building AI Agents for Scientific Work with Benchling’s Head of AI
By
–
On the latest episode of Max Agency, @hwchase17
— LangChain (@LangChain) 4 juin 2026
sat down with @nlarusstone, Head of AI at @benchling for a conversation on building agents for scientific work.
⏯️ YouTube: https://t.co/kd6rxBTugR
🎧 Apple Podcasts: https://t.co/IK5uLBNDAC
🎧 Spotify: https://t.co/sG80P8CnyL pic.twitter.com/siurE40tREOn the latest episode of Max Agency, @hwchase17 sat down with @nlarusstone
, Head of AI at @benchling for a conversation on building agents for scientific work. YouTube: https://
youtube.com/watch?v=RjpTrf
fSMjE
… Apple Podcasts: https://
podcasts.apple.com/us/podcast/the
-tool-design-tricks-behind-benchlings-ai-agents/id1891551672?i=1000771169985
… Spotify: https://
open.spotify.com/episode/2bFEj2
W290bk2JW1zC6wyp
… -

NVIDIA Nemotron 3 Ultra: 5x faster inference, 30% lower costs
By
–
NVIDIA : Nemotron 3 Ultra has been released on Huggingface with 5x faster inference and 30% lower costs in comparison to other open models. > Nemotron-3-Ultra-550B-A55B-NVFP4 is a frontier-scale large language model (LLM) trained by NVIDIA, designed to deliver strong agentic,