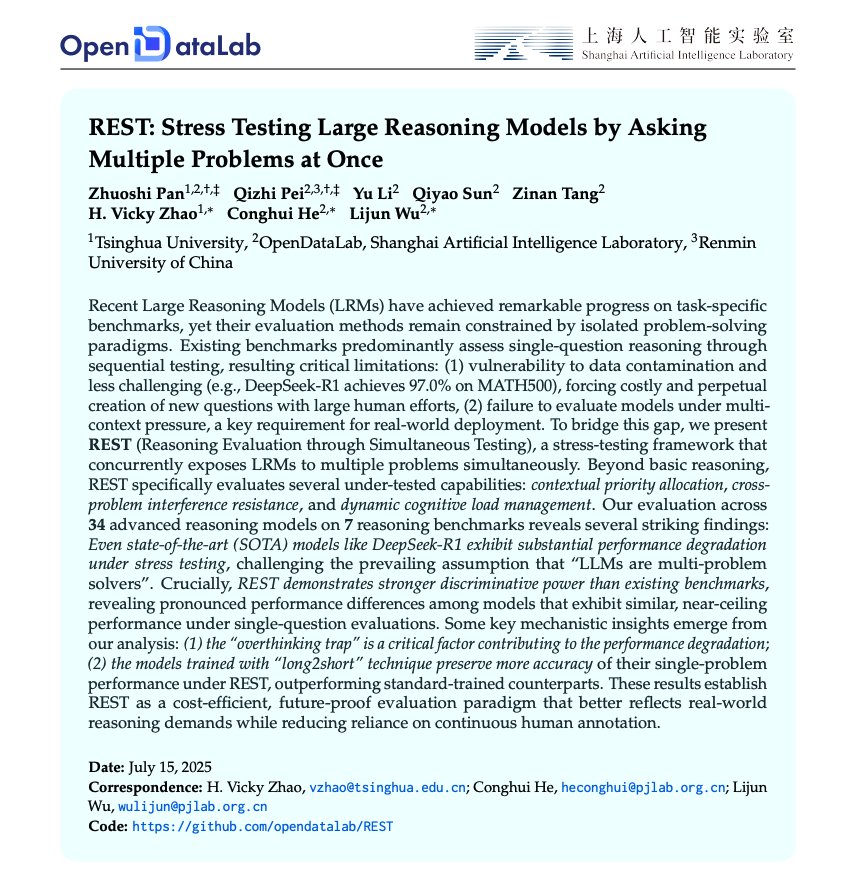
5. Stress Testing Large Reasoning Models Proposes a new benchmark framework called REST to evaluate the robustness of Large Reasoning Models (LRMs) under multi-question stress.
MACHINE LEARNING
-
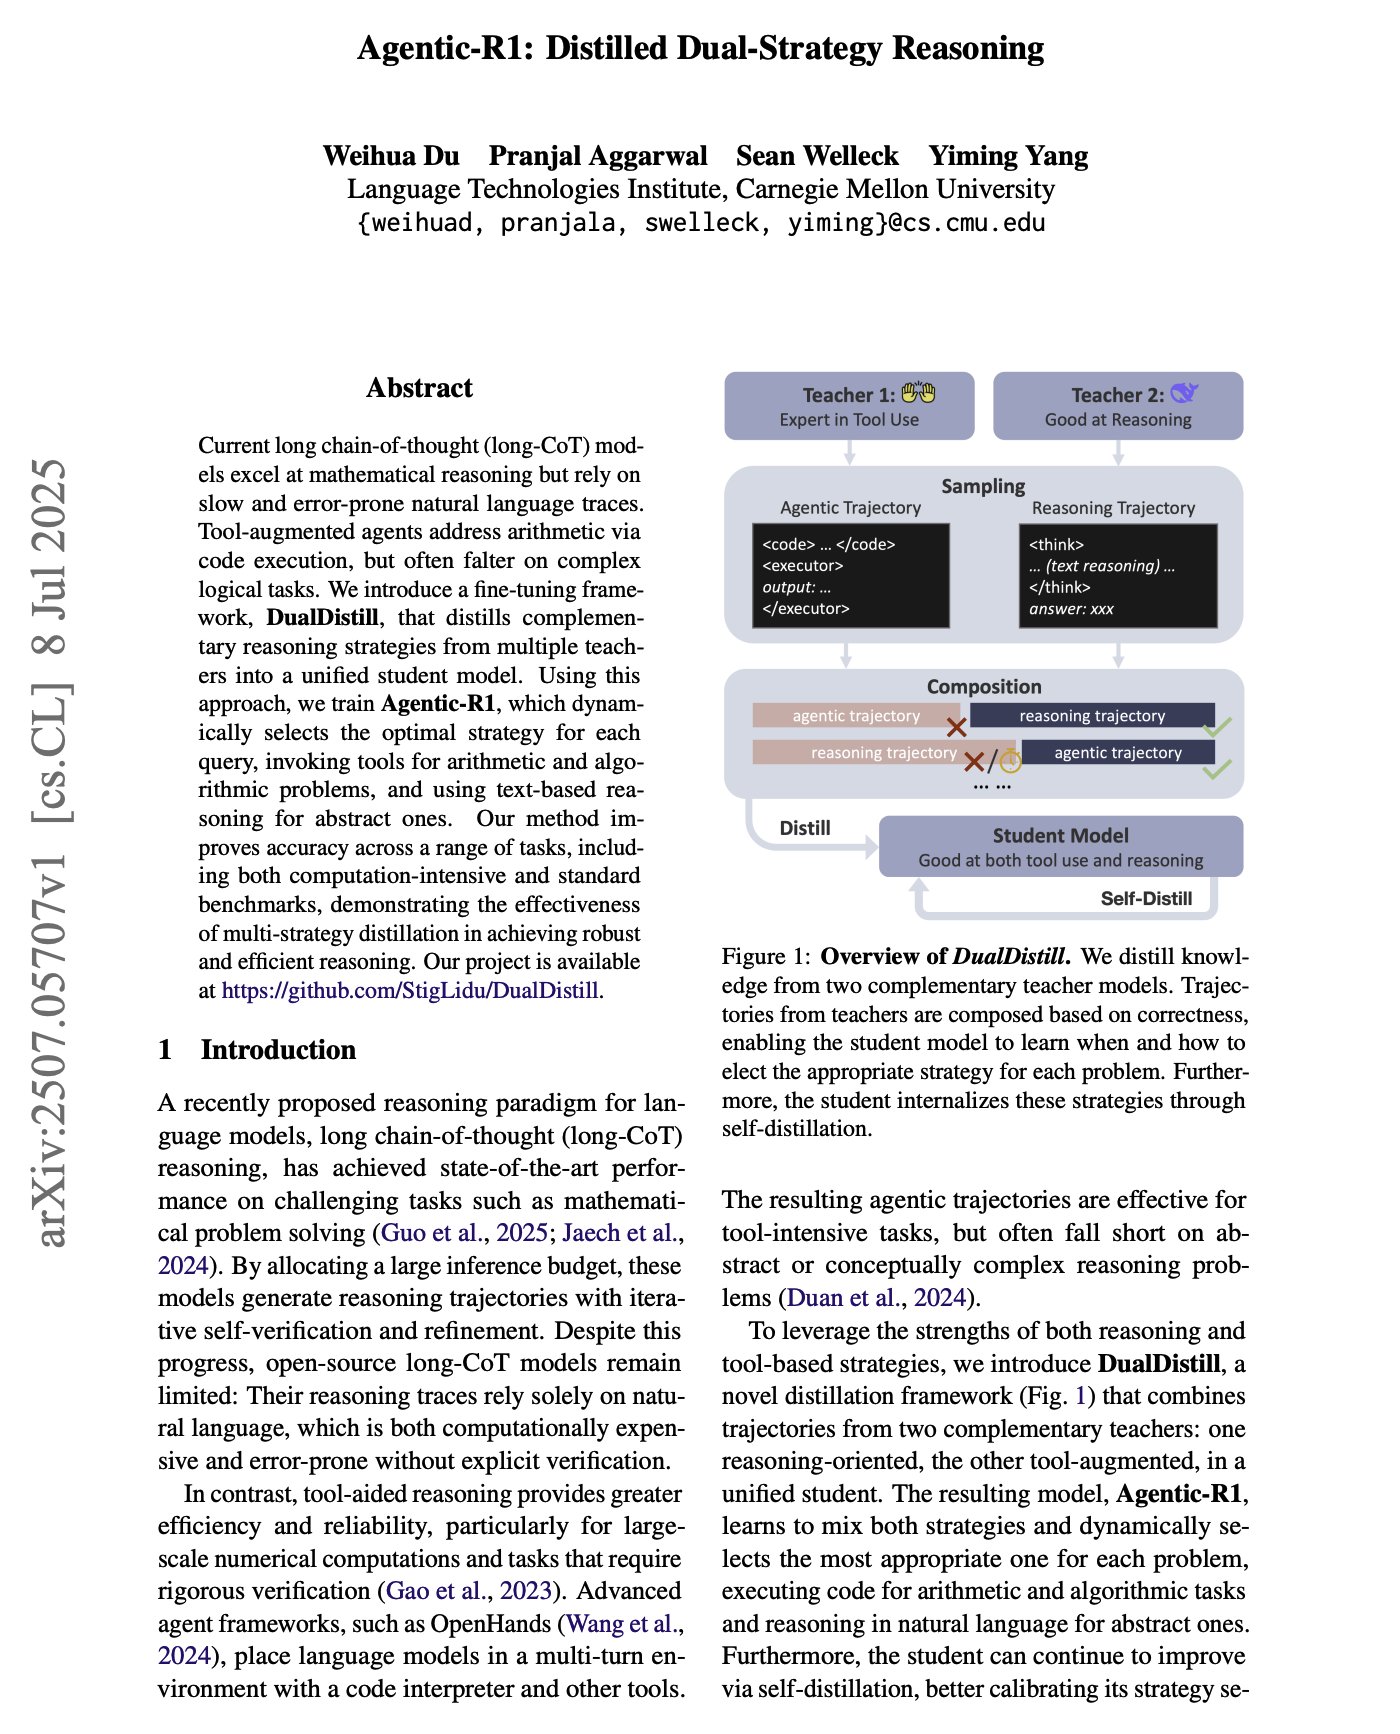
Agentic-R1: 7B Language Model with Dynamic Tool-Based Reasoning
By
–
3. Agentic-R1 This paper introduces Agentic-R1, a 7B language model trained to dynamically switch between tool-based execution and pure text reasoning using a novel fine-tuning framework called DualDistill.
-
Study Evaluates LLM Performance Across Extended Context Lengths
By
–
2. Context Rot This comprehensive study by Chroma evaluates how state-of-the-art LLMs perform as input context length increases, challenging the common assumption that longer contexts are uniformly handled.
-

LLMs Performance on 2025 International Math Olympiad Evaluation
By
–
Not Even Bronze: Evaluating LLMs on 2025 International Math Olympiad https://
matharena.ai/imo/ Nice blog post from the team behind MathArena: Evaluating LLMs on Uncontaminated Math Competitions (
https://
arxiv.org/abs/2505.23281) providing independent analysis of LLM performance on IMO. -
Scaling AI Evaluation: Building Meaningful Benchmarks from Single GPU
By
–
coming up with evals that start at 1-gpu but are meaningful at eventual scale will be the hardest part.
-
Side-by-side breakdowns as the future of AI model evaluation
By
–
Side-by-side breakdowns like this are the future of model evaluation.
-
Understanding Embeddings in AI
By
–
I used to think embeddings were advanced.
Now I realize it’s just how AI stores meaning. This breakdown unlocked so much clarity. -
Transformers: The Standard AI Model’s Strengths and Gaps
By
–
Transformers are the standard model of AI. They’re both:
– The result of a long series of breakthroughs
– Surprisingly powerful
– A big mess
– Missing key pieces -
AI Companies Overfit on Flying to Boston Task
By
–
*ai companies immediately overfit on the task of flying to boston*
-
Math Skills in Computers: Capability Without AGI Implications
By
–
There's no reason to believe that, just because humans find math hard, that computers should find it hard too. This could be similar to computers getting good at chess. A significant step, but not a sign of AGI.