I mean, not "just", but they are compressed statistical models and can fall out of just compression.
MACHINE LEARNING
-

Wang et al. Introduce Hierarchical Reasoning Model for AI
By
–
Hierarchical Reasoning Model Wang et al.: https://
arxiv.org/abs/2506.21734 #ArtificialIntelligence #DeepLearning #MachineLearning -

Wang et al. Present Hierarchical Reasoning Model for Deep Learning
By
–
Hierarchical Reasoning Model Wang et al.: https://
arxiv.org/abs/2506.21734 #ArtificialIntelligence #DeepLearning #MachineLearning -

Databricks DataAIWorldTour: Latest Advancements in Data and AI
By
–
The Databricks #DataAIWorldTour brings together data and AI engineers and data analytics professionals to discuss the latest advancements in data and AI, share use cases and best practices, and hear from industry experts about what’s next. Whether you are looking for
-
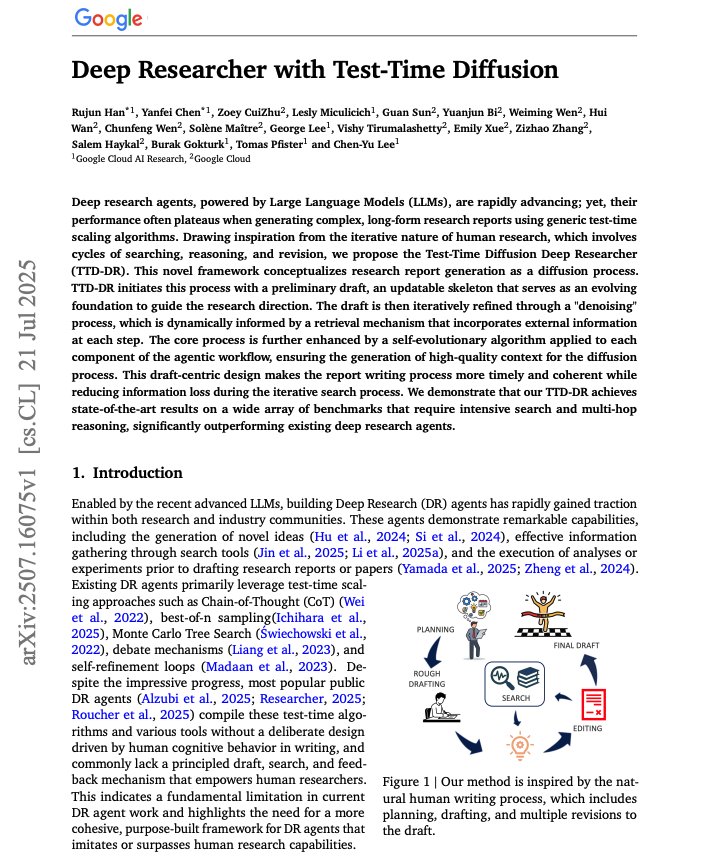
Deep Researcher: Test-Time Diffusion for Report Generation
By
–
8. Deep Researcher with Test-Time Diffusion Rather than relying on static inference strategies like CoT or best-of-n sampling, this work frames the report generation process as a diffusion process.
-

Inverse Scaling in Large Reasoning Models Test-Time Compute
By
–
6. Inverse Scaling in Test-Time Compute Presents a systematic study of inverse scaling in large reasoning models, where increasing the test-time compute (i.e., reasoning length) harms rather than helps model performance.
-
Compute-Optimal Strategies for Many-Shot In-Context Learning
By
–
7. Towards Compute-Optimal Many-Shot In-Context Learning Proposes practical strategies for reducing the cost of many-shot in-context learning while preserving or improving performance. https://
arxiv.org/abs/2507.16217 -
In-Context Learning Without Weight Updates in LLMs
By
–
5. Learning without Training This paper provides a theoretical and empirical explanation for how LLMs exhibit in-context learning, the ability to learn from examples in a prompt without weight updates.
-
Model Convergence Through Distillation and Subliminal Learning Transfer
By
–
This model convergence is quite perplexing. Possibly related to recent results on subliminal learning? Basically deeper knowledge correlations transfer when training via distillation. As the amount of data online from LLMs increases, it’s possible this makes them converge to some
-

Survey of Continual Reinforcement Learning Advances
By
–
A Survey of Continual Reinforcement Learning Pan et al.: https://
arxiv.org/abs/2506.21872 #ArtificialIntelligence #DeepLearning #MachineLearning