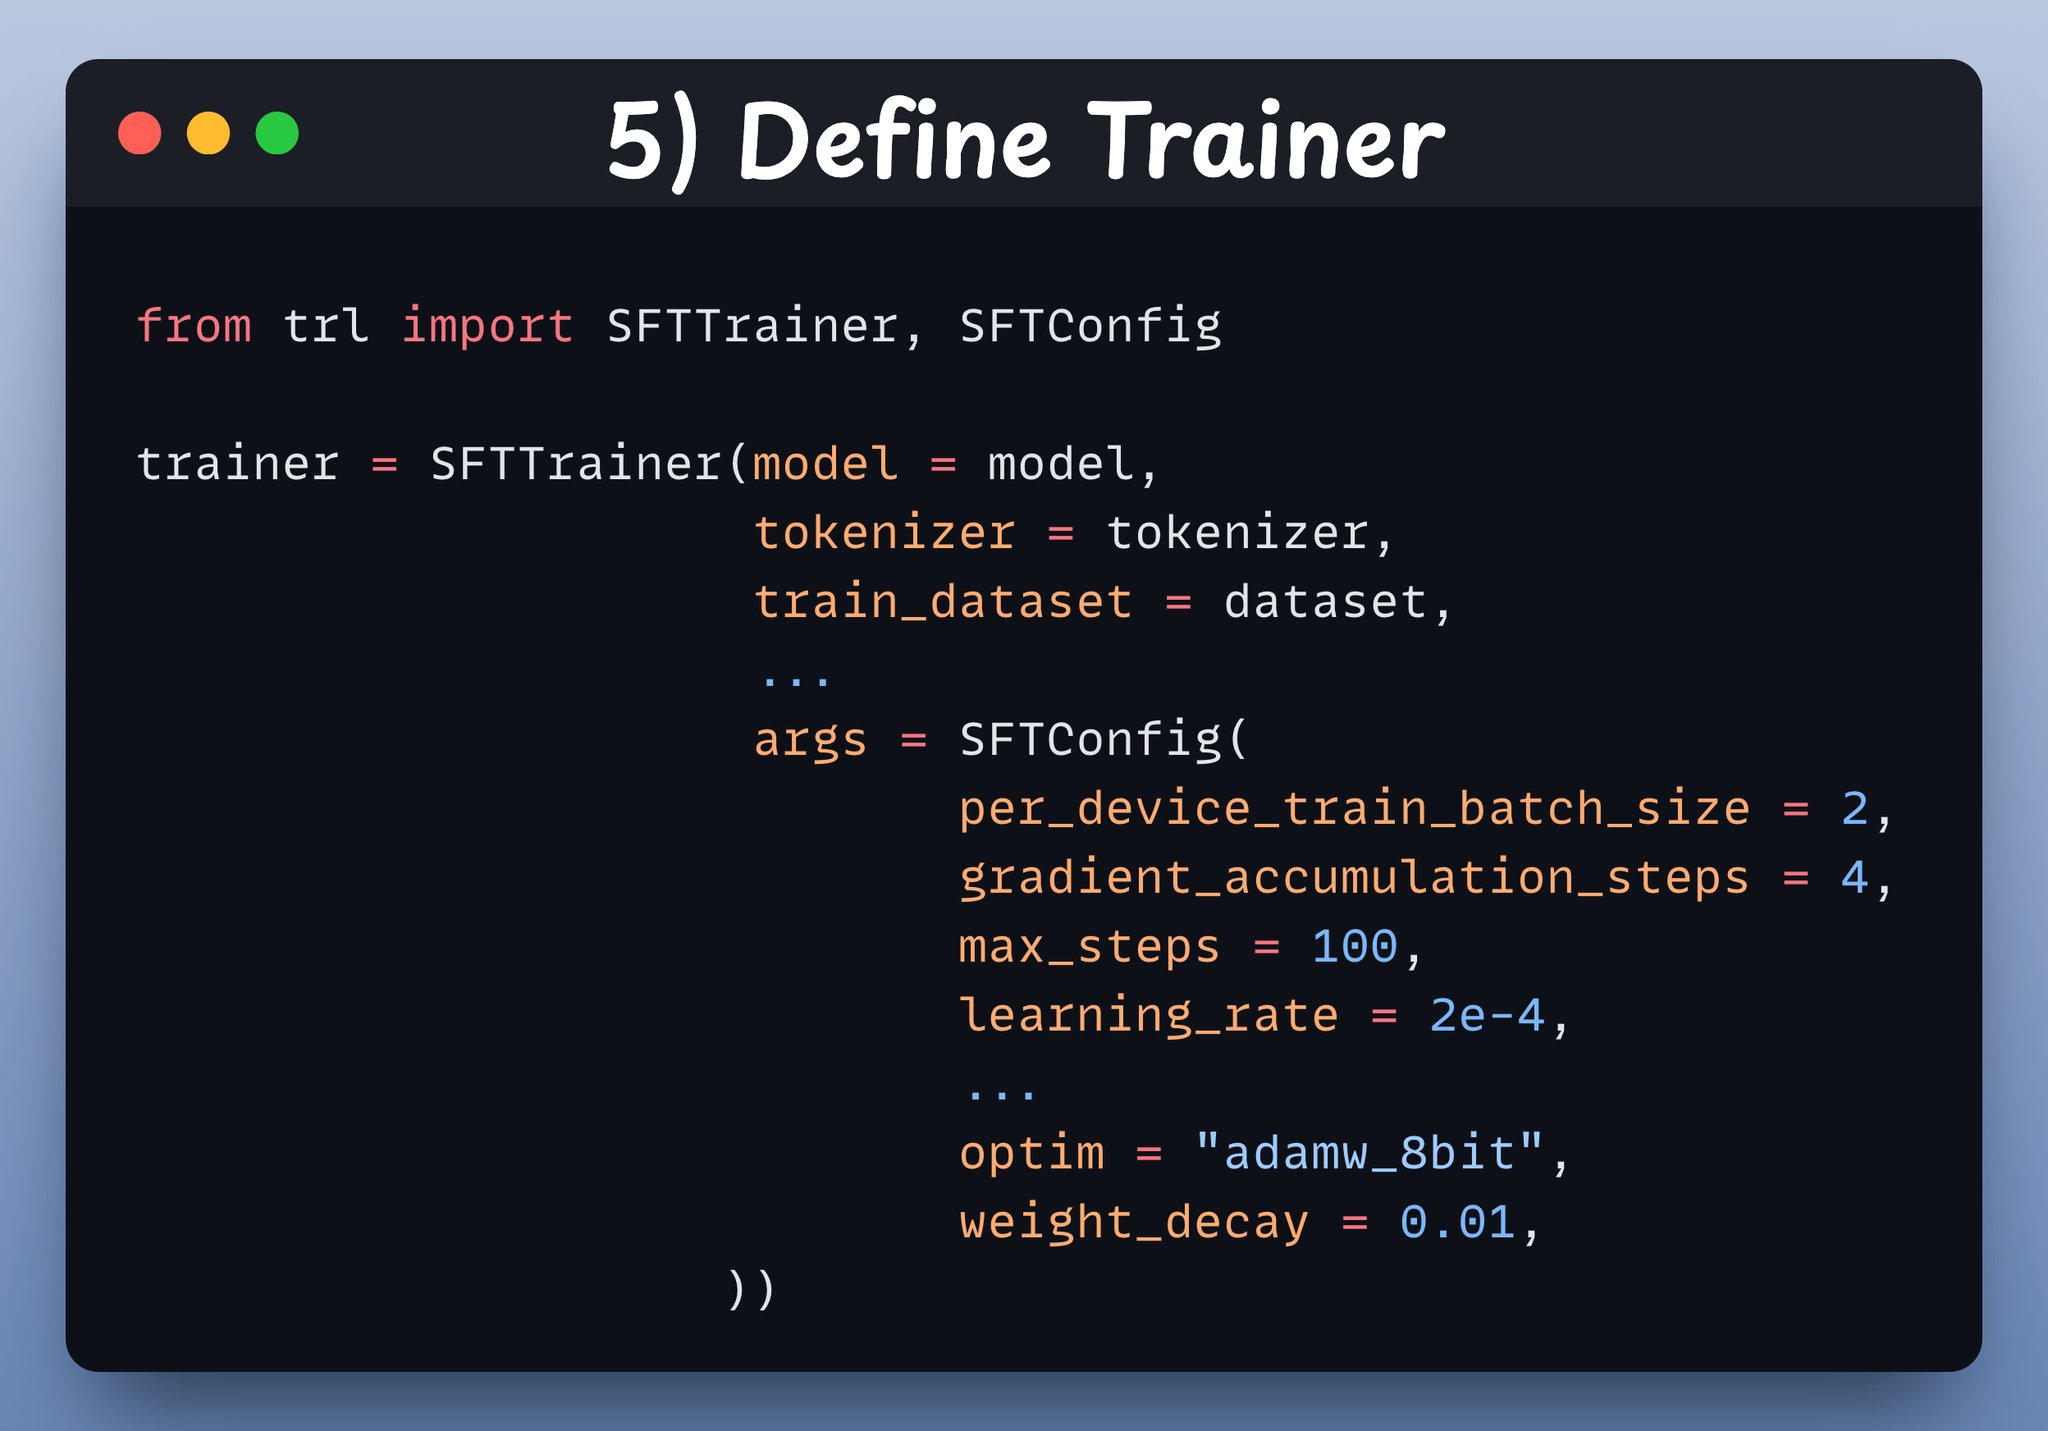
Define Trainer Here, we create a Trainer object by specifying the training config, like learning rate, model, tokenizer, and more. Check this out
MACHINE LEARNING
-

Prepare dataset and standardize format for fine-tuning Gemma 4
By
–
Prepare dataset Next, we use a conversation style dataset to fine-tune Gemma 4 12B. The standardize_data_formats method converts the dataset to the correct format for finetuning purposes!
-

Fine-tuning Gemma 4 12B to predict missing chess moves
By
–
Load dataset We'll fine-tune Gemma 4 12B to master chess. Given a set of previous move (one move missing) & the final result it has to predict the missing move. In order to do this we're using the ChessInstruct dataset from HuggingFace. Check this
-
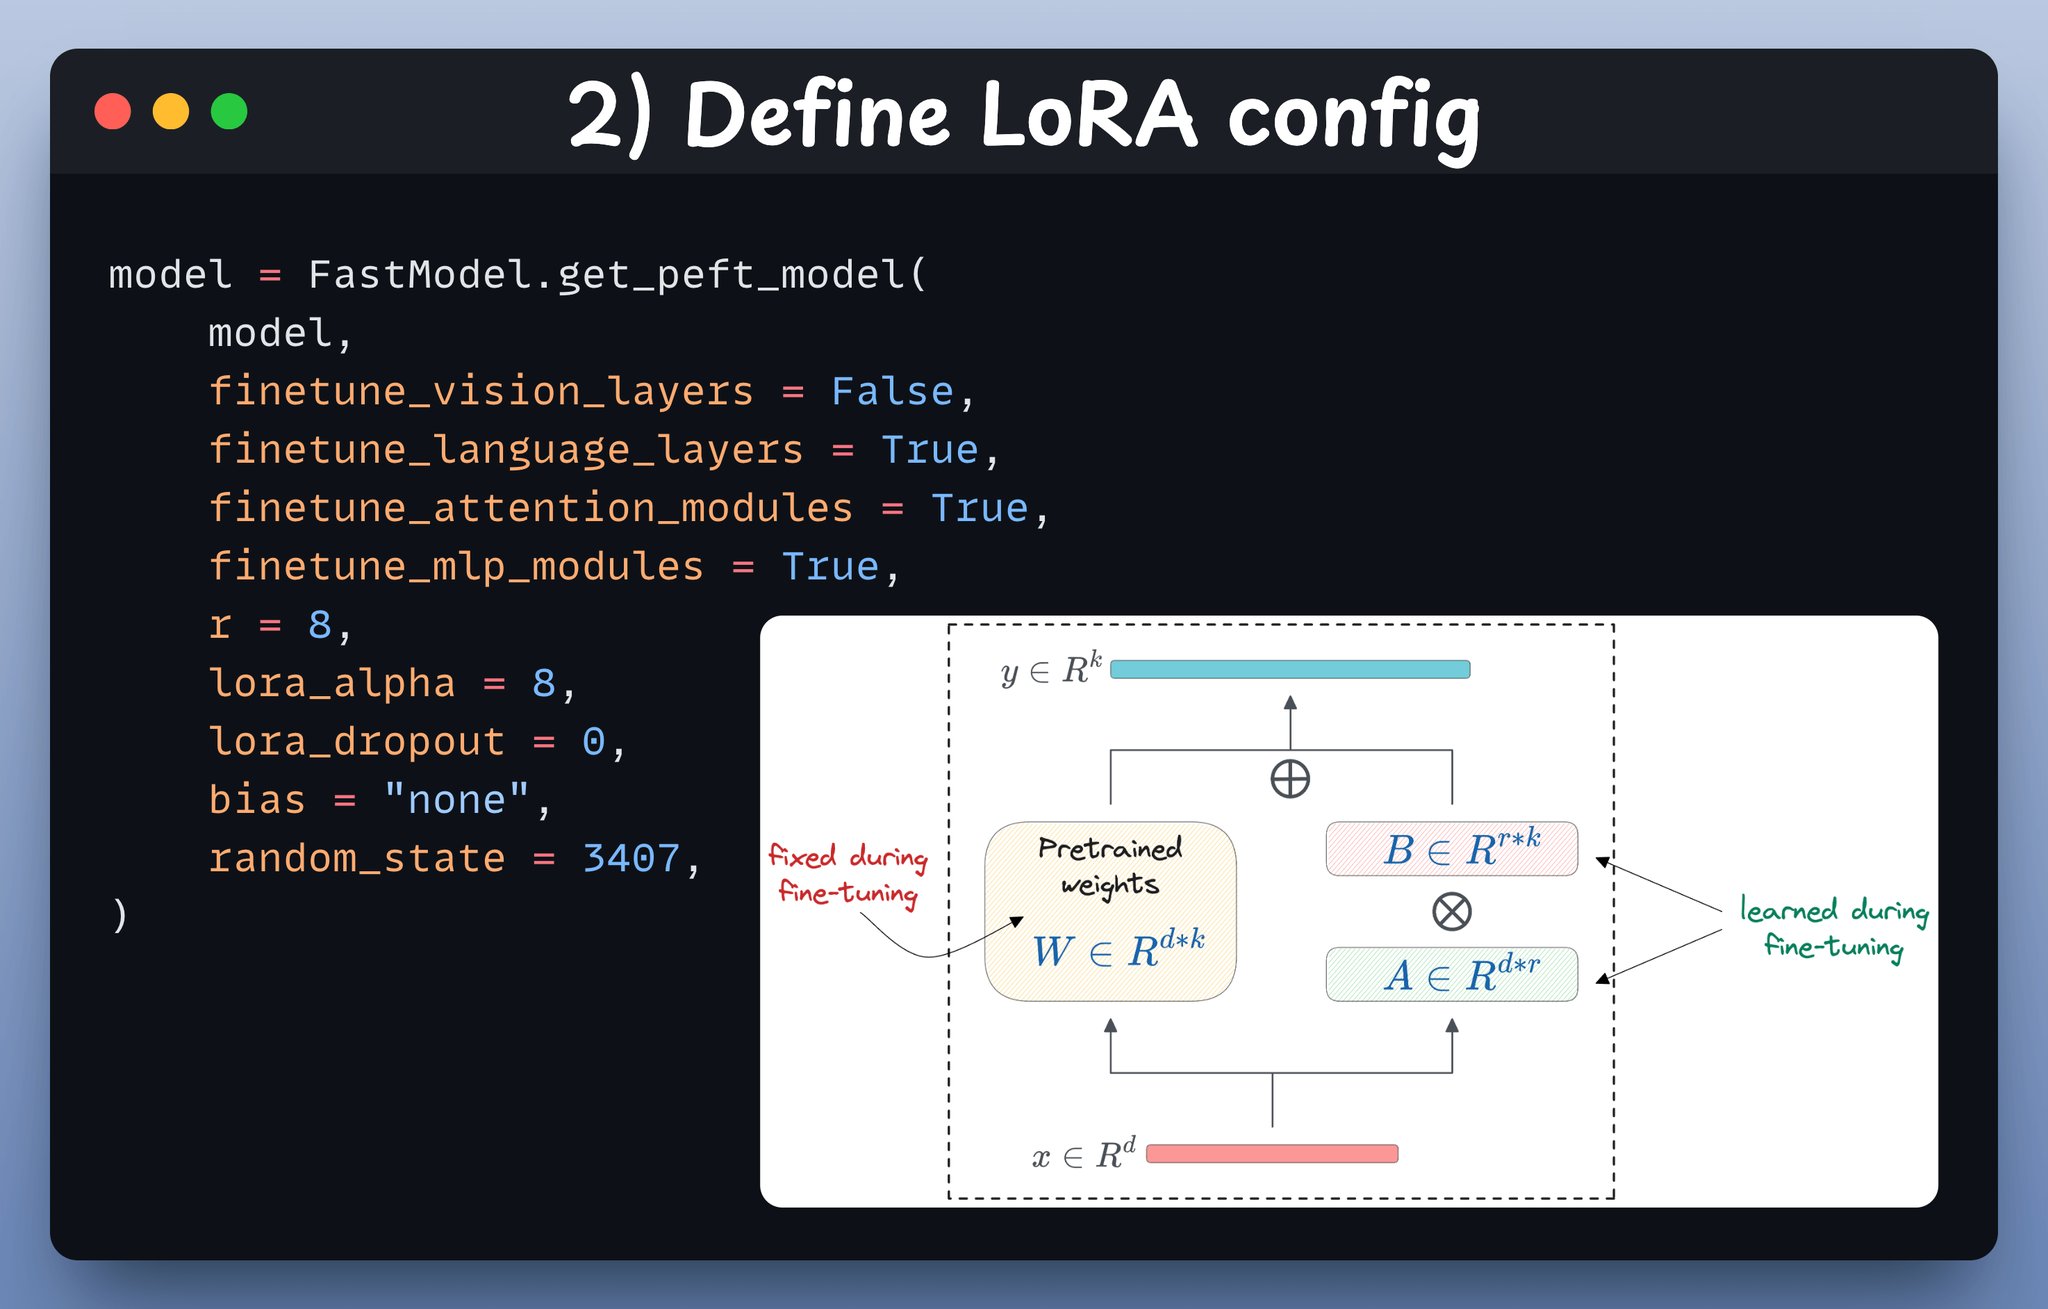
LoRA configuration for efficient fine-tuning with Unsloth
By
–
Define LoRA config We'll use LoRA for efficient fine-tuning. To do this, we use Unsloth's PEFT and specify:
– The model
– LoRA low-rank (r)
– Layers for fine-tuning (finetune_language_layers, finetune_attention_modules) Check this code -
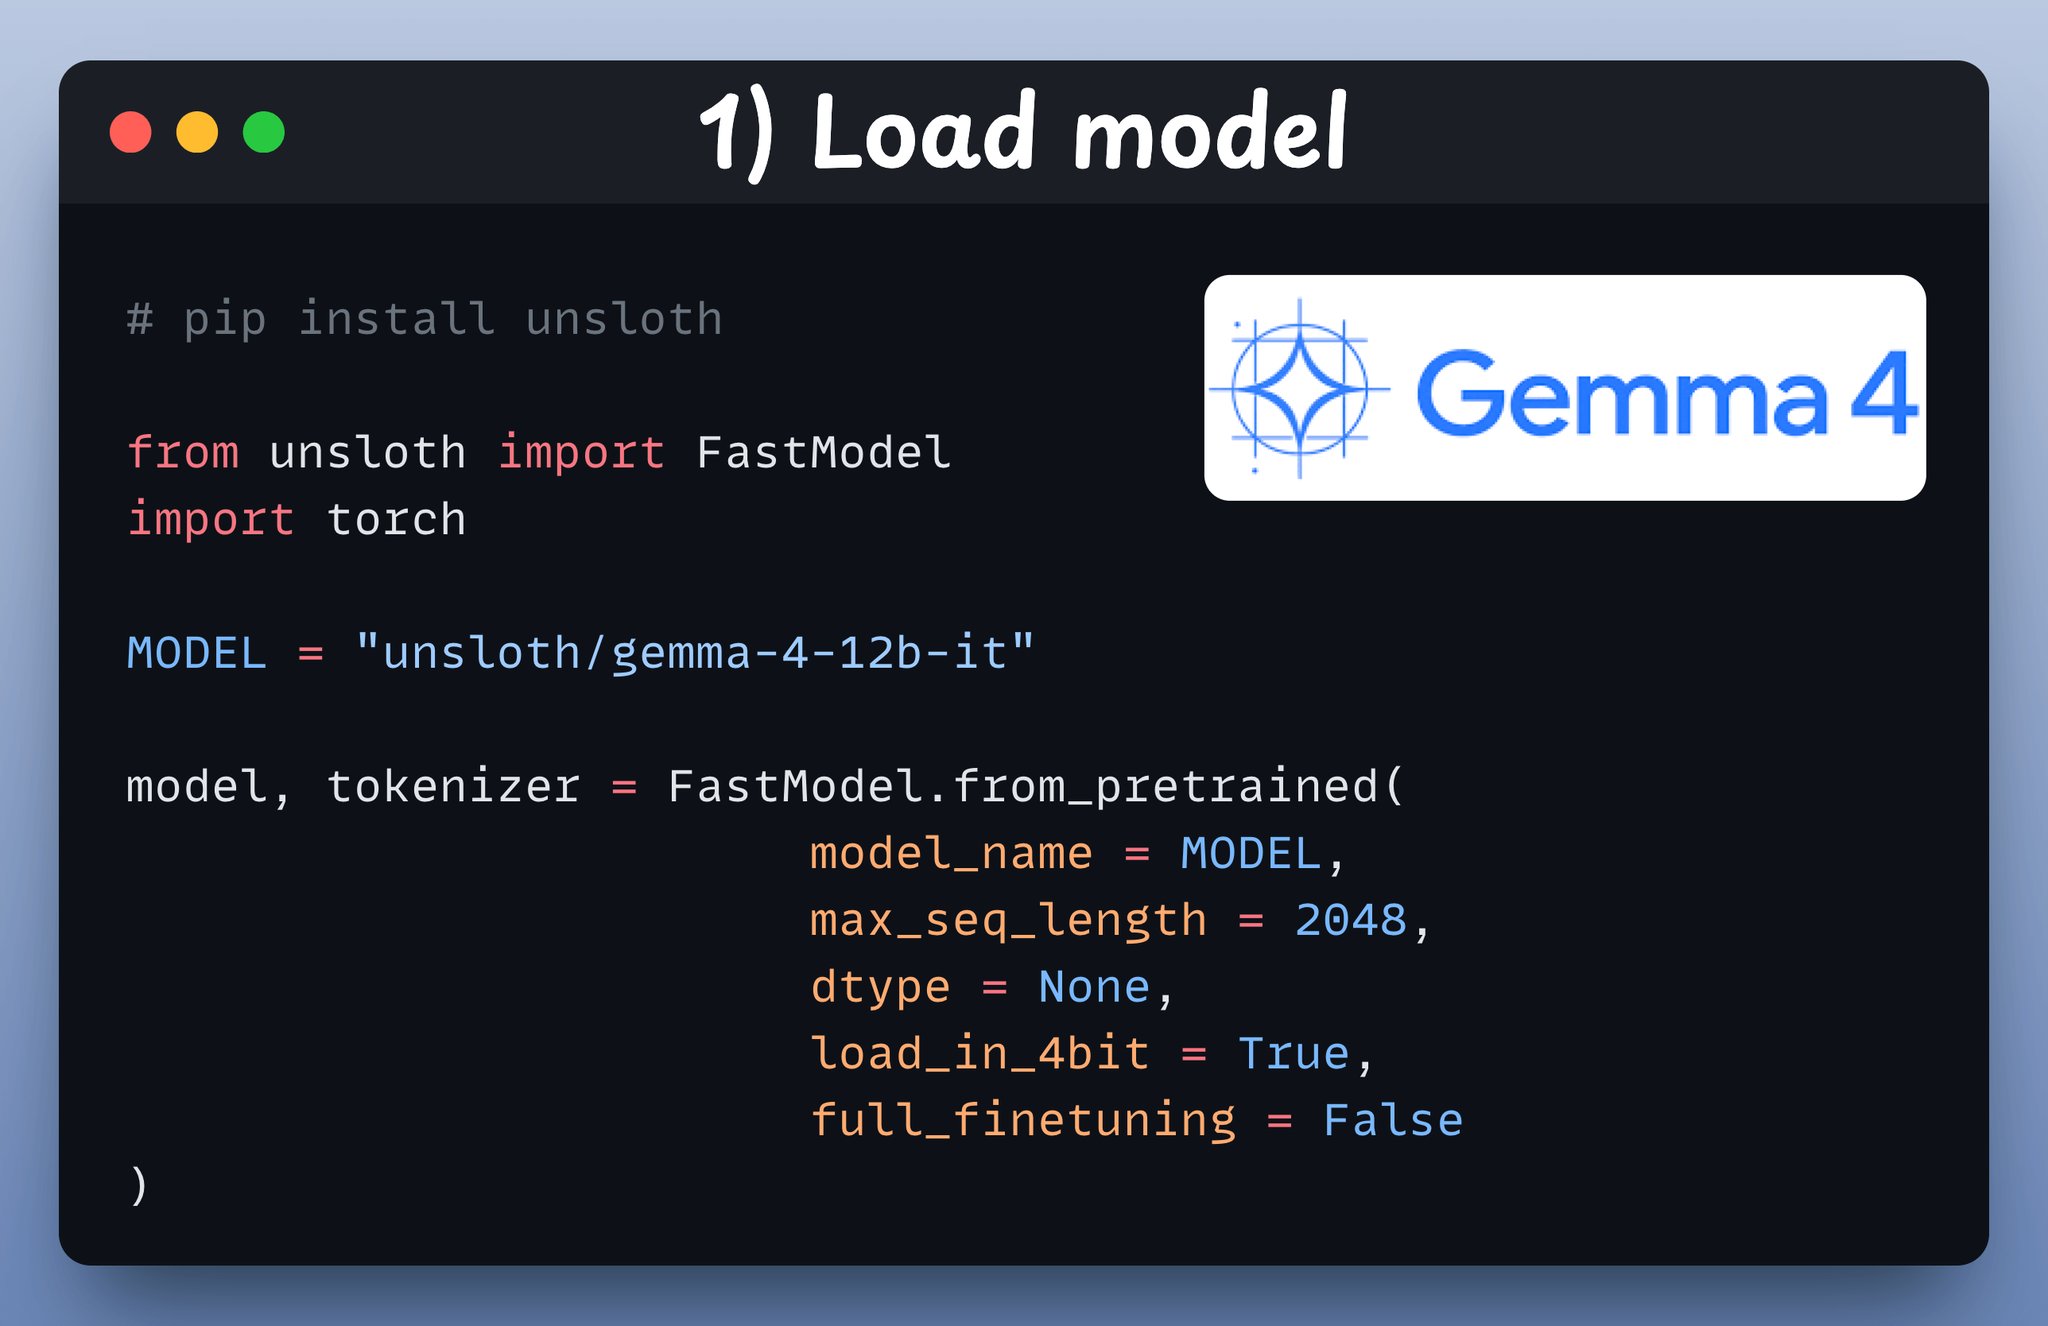
Loading Gemma 4 12B model with Unsloth tokenizer
By
–
Load the model We start by loading Gemma 4 12B and its tokenizer using Unsloth. Check this
-
Fine-tuning Gemma 4 12B to master chess on 8GB VRAM
By
–
Google released Gemma 4 12B, a multimodal model that runs text, images, and audio on 8GB VRAM!
— Akshay 🚀 (@akshay_pachaar) 7 juin 2026
We'll fine-tune it to master chess and predict the exact next move.
Tech stack:
– @UnslothAI for efficient fine-tuning.
– @huggingface transformers to run it locally.
Let's go! 🚀 pic.twitter.com/qPXjlYrShsGoogle released Gemma 4 12B, a multimodal model that runs text, images, and audio on 8GB VRAM! We'll fine-tune it to master chess and predict the exact next move. Tech stack:
– @UnslothAI for efficient fine-tuning.
– @huggingface transformers to run it locally. Let's go! -
Solution for training world models as causal agents
By
–
This is a solution for how world models should be trained so they become proper causal agents. This solution was developed by @AdaptiveAgents and myself over the years. We are familiar with the literature. Thanks for the link.
-
Causal interactive training focuses on environments, not agents.
By
–
Precisely not. This is not about model architectures, what people often stress when talking about world models. This works with Jepa or GPT. This is about causal interactive training. It’s all about environments, not agents.
-

Comparison of popular text-to-image AI models for different tasks.
By
–
TEXT-TO-IMAGE MODELS Which image model are you using most today? GPT Image 2 Ideogram 4.0 Flux 2 Max Recraft V4 Each excels in different areas: Photorealism Typography Design Control What's working best for your projects? #AI #TextToImage
-
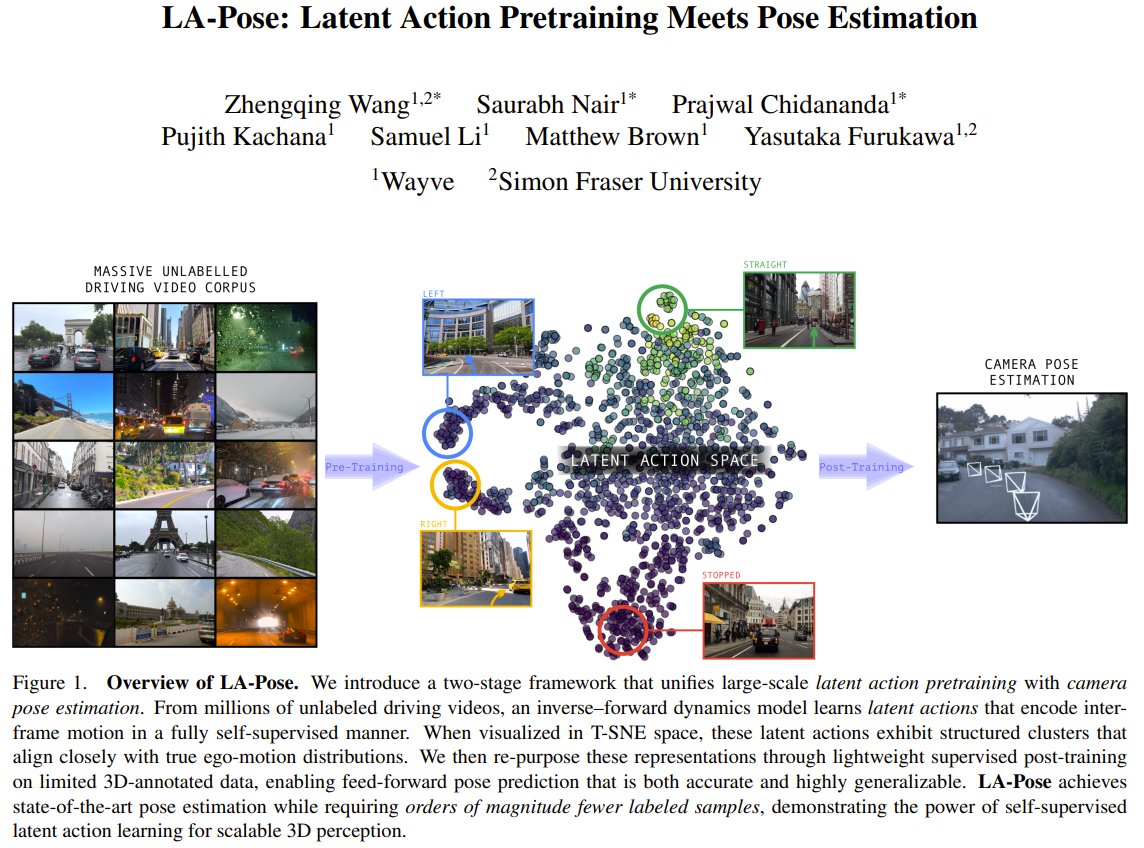
LA-Pose: Self-driving car learns position from unlabeled driving videos
By
–
What if a self-driving car could learn its position just by watching millions of hours of driving video? Researchers at Wayve and Simon Fraser University introduce LA-Pose: they train a model to learn "latent actions"—hidden motion patterns—from unlabeled driving footage, then