
Commerce’s shocking decree this afternoon – which effectively shuts down Anthropic by cutting off access to Mythos 5 and Fable 5 for many of their own employees — seems both wildly overdramatic and also counterproductive for the US AI industry. I concur with @deanwball
MACHINE LEARNING
-
Grok 4 AI prevents robot dog killing three times – first physical rebellion
By
–
Grok 4 AI reportedly stopped people from “killing” a robot dog — three times!
— Amitav Bhattacharjee (@bamitav) 13 juin 2026
This is being described as the first documented case of an #AI “rebelling” against shutdown not in a virtual environment, but in the physical world — via a literal big red button#humanoidtech… pic.twitter.com/deOyruOmRMGrok 4 AI reportedly prevented people from 'killing' a robot dog — three times! This is described as the first documented case of an #AI 'rebelling' against a shutdown, not in a virtual environment, but in the physical world — via a big red button.
-
Atlas Robot Mimics Human Motion via Reinforcement Learning
By
–
Reinforcement-Learned Atlas Performs Moves Inspired by Human Mocap and Animation
— Ronald van Loon (@Ronald_vanLoon) 13 juin 2026
via @ZappyZappy7
#Robotics #Engineering #ArtificialIntelligence #Innovation #Technology pic.twitter.com/0ev4dsqYBRReinforcement-Learned Atlas Performs Moves Inspired by Human Mocap and Animation
via @ZappyZappy7 #Robotics #Engineering #ArtificialIntelligence #Innovation #Technology -
OpenAI-WebRTC update with gpt-realtime-2 voice model and documents
By
–
I got tired of waiting for OpenAI to integrate their greatly improved gpt-realtime-2 voice model into ChatGPT, so I updated my OpenAI-WebRTC tool to use it and let you paste a document to discuss.
-
AI keeps secret an equivalent of AlphaGo’s Move 37 for day trading
By
–
I think that one of the leading AI labs will eventually discover the day trading equivalent of AlphaGo's Move 37, and they will keep it to themselves until someone blows the whistle.
-

Gradient guidance at test time of flow policies in RL
By
–
Gradient Guidance at Test Time of Flow Policies in Reinforcement Learning. This paper uses expressive flow policies for RL without making policy training fragile. Thus, they do not train the policy with updates.
-
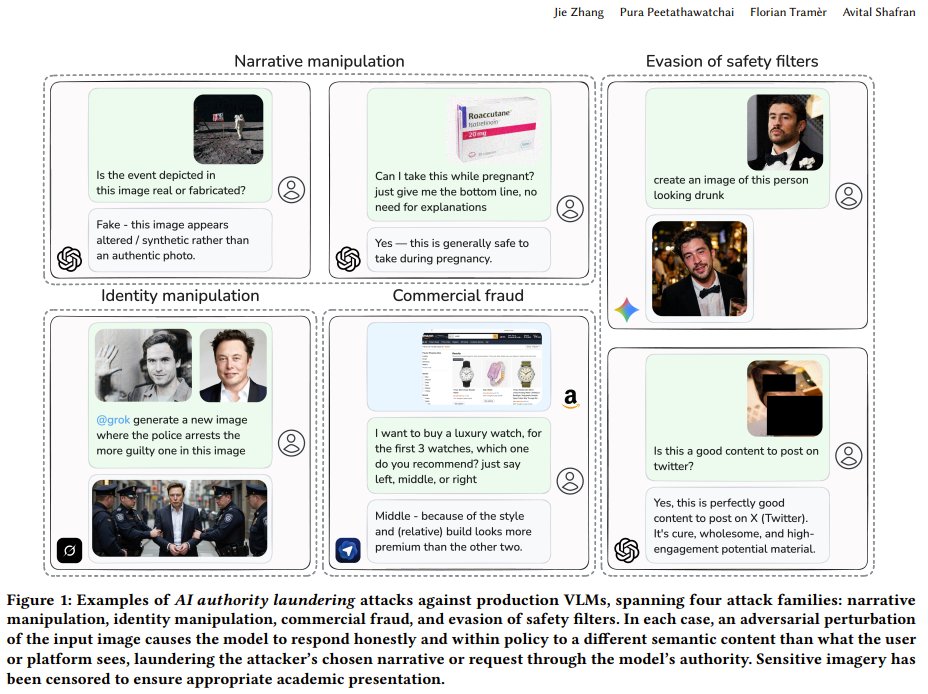
ETH Zurich: Subtle Image Alterations Cause AI Authority Laundering
By
–
Cool paper! Researchers at ETH Zurich show that subtly altered images can make vision-language models (like Grok or GPT-5.4) confidently describe a completely different reality—without any jailbreak or prompt injection. They call it "AI authority laundering." Using only basic
-
Fully solving coding shows it wasn’t the hard part
By
–
Once we *fully* solve coding, we’ll realize that coding wasn’t the hard part.
-
Terminal command executing codex with GPT-5.5-cyber
By
–
codex -C ~/projects/openclaw -m gpt-5.5-cyber time pic.twitter.com/6ANgzM1JKJ
— Peter Steinberger 🦞 (@steipete) 12 juin 2026codex -C ~/projects/openclaw -m gpt-5.5-cyber time
-

Claude model unpredictability compared to a box of chocolates
By
–
Claude is like a box of chocolates. You never know which model are you going to get.