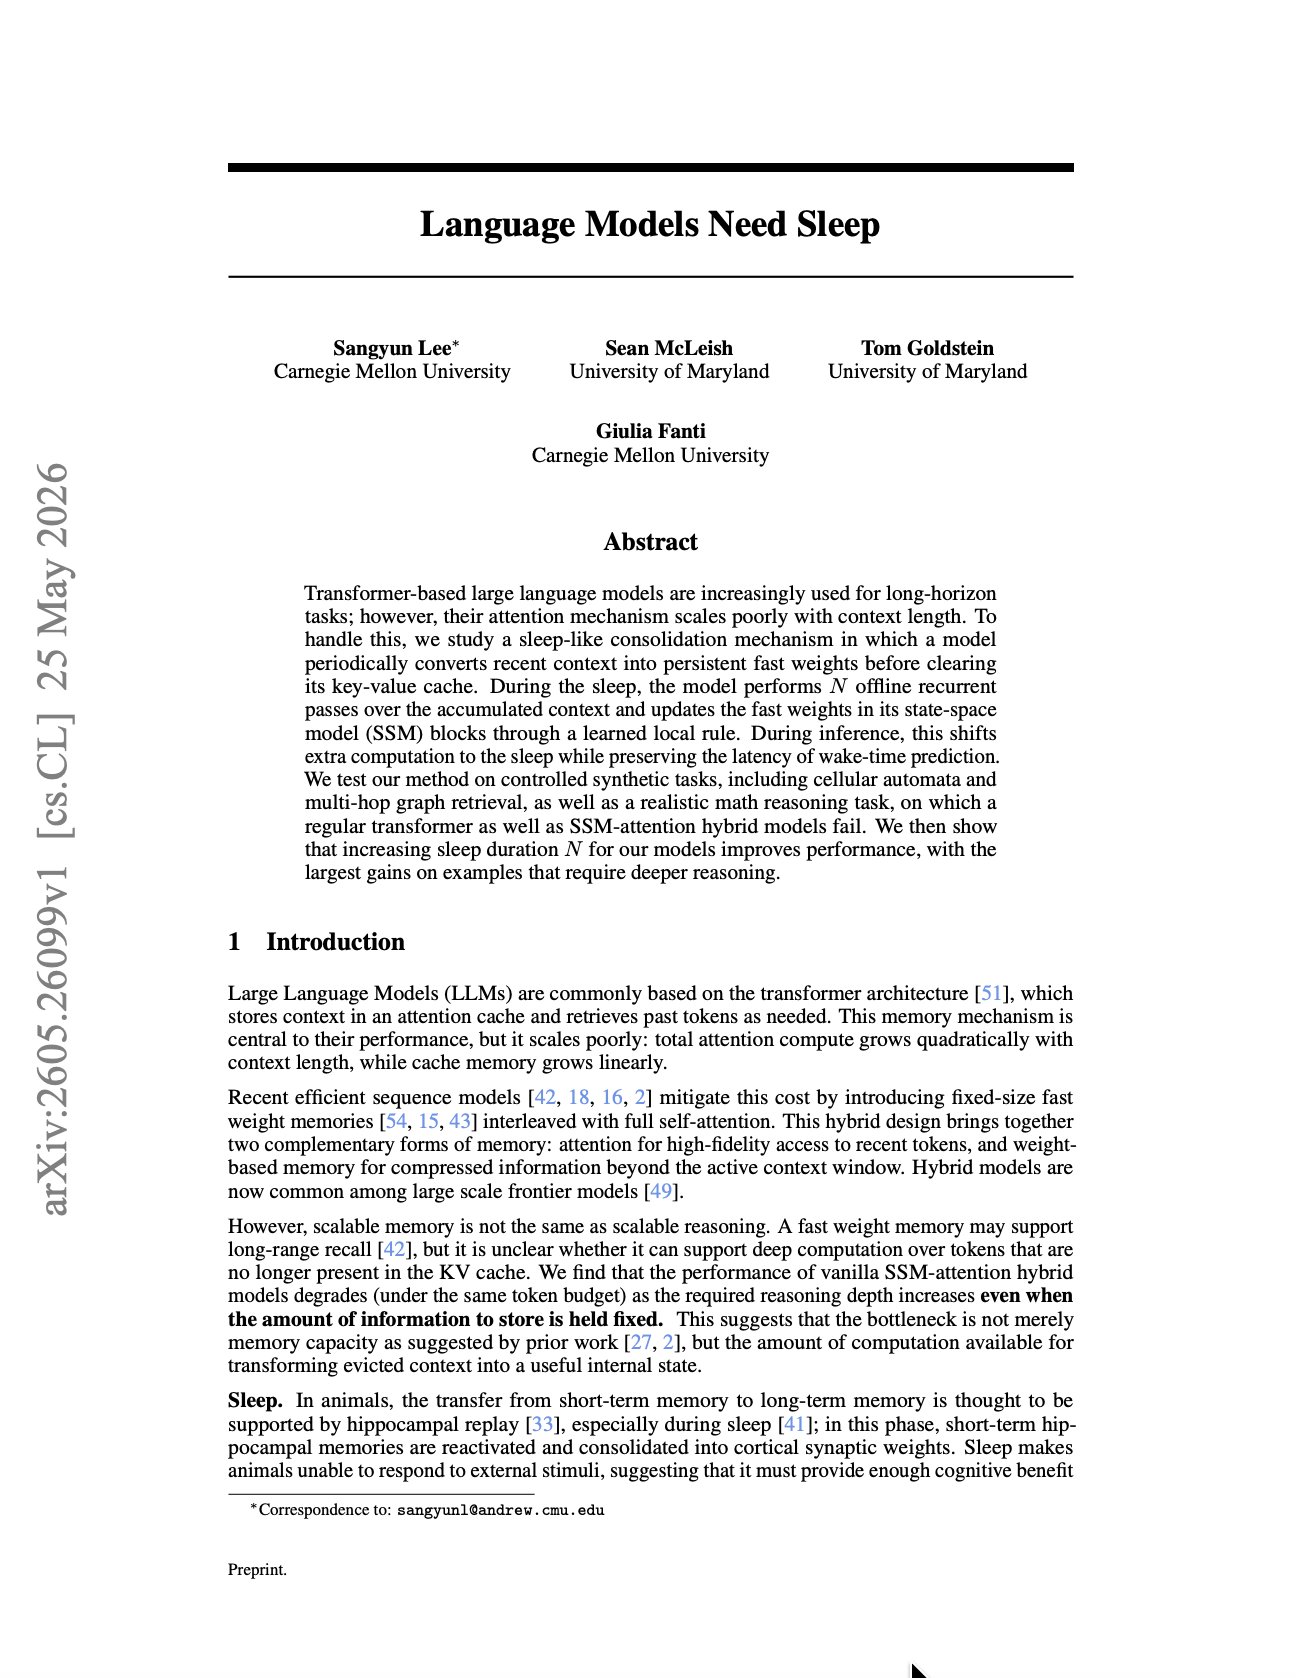
Language models may not need longer context. They may need sleep. A fascinating new paper by Sangyun Lee, Sean McLeish, Tom Goldstein, and Giulia Fanti proposes one of the most biologically resonant ideas in long-context AI: sleep-like memory consolidation. The problem is
LLMS
-
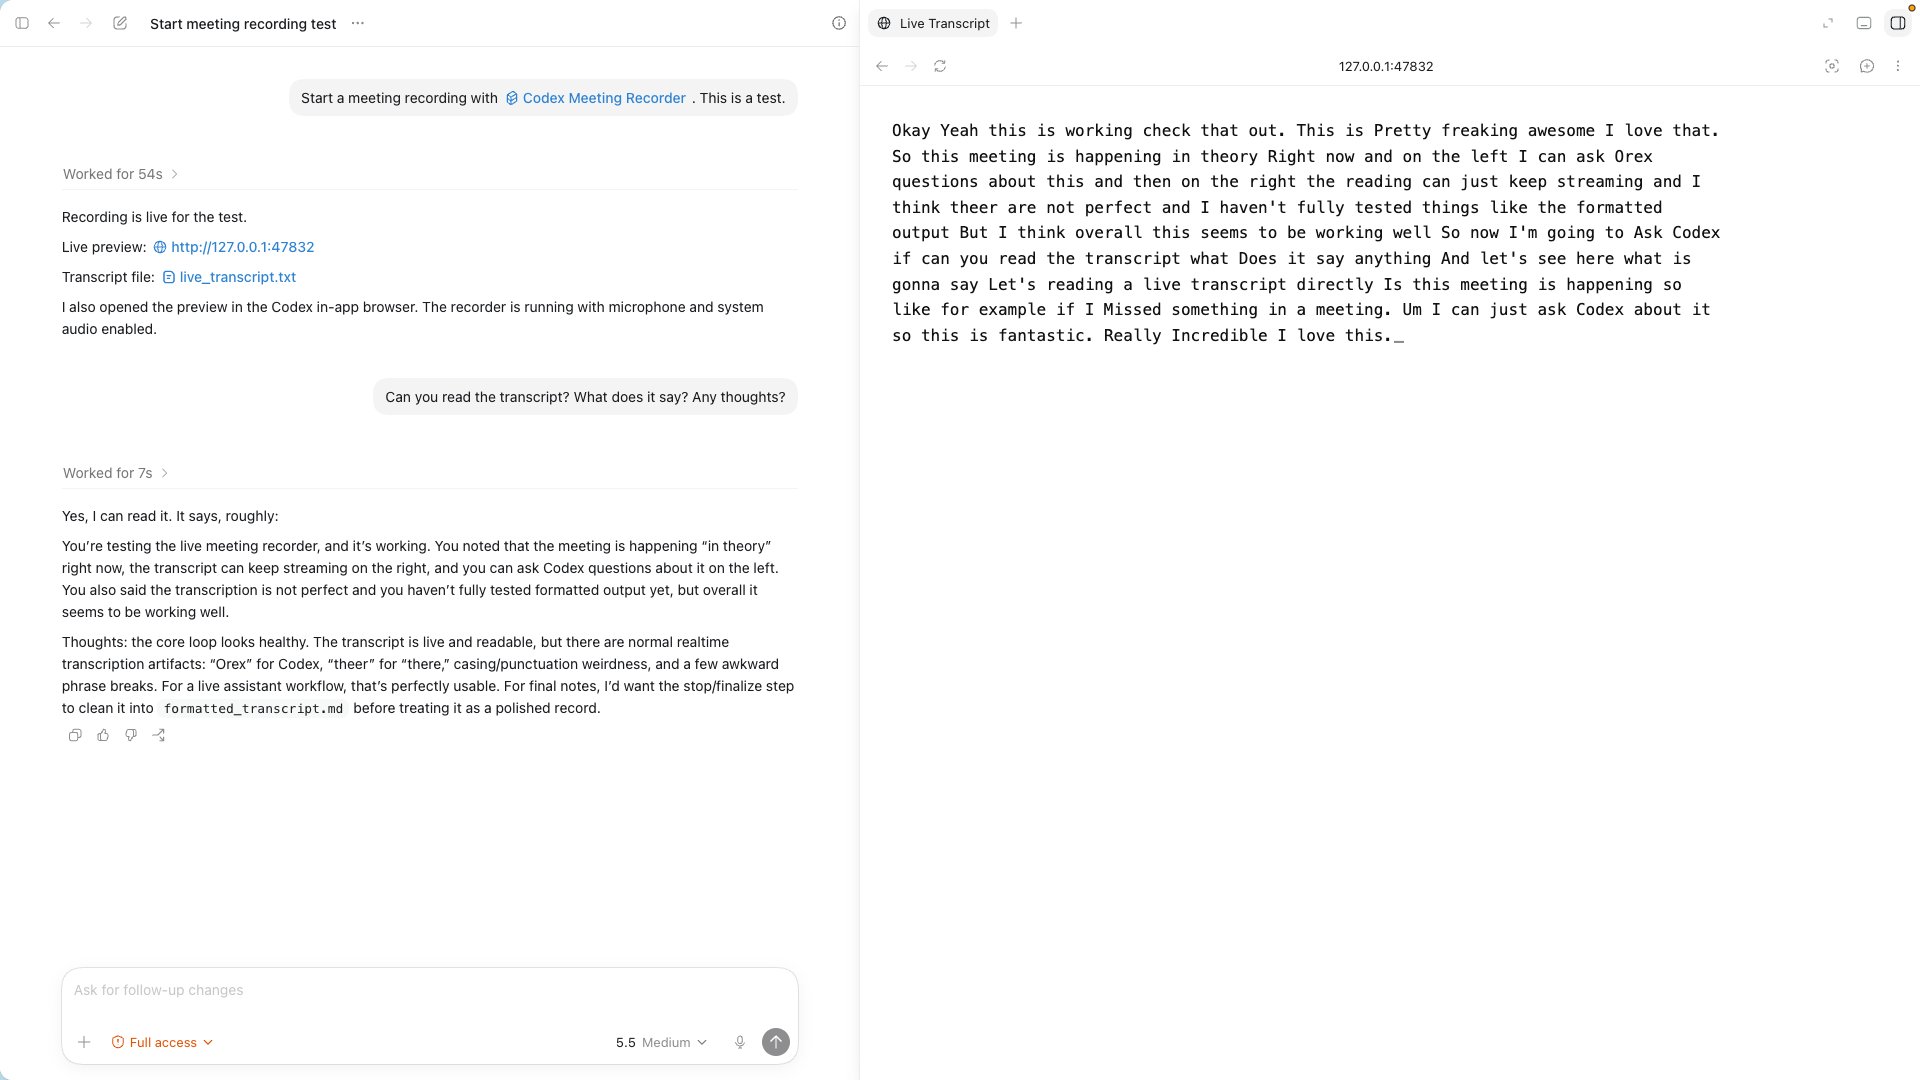
Codex for real-time meeting transcription and Q&A
By
–
Codex for transcribing and answering questions about a meeting in real time:
-
Lyft’s AI Assist: How Ops Teams Ship Agents and Iterate with Prompts
By
–
Today, Ops teams, VoC leads, and PMs are now writing prompts, shipping agents, and iterating. No MLEs required. Read @Lyft
’s guest blog to see how they improved AI Assist, why they treated prompts like product specs rather than code comments, + what’s next. -
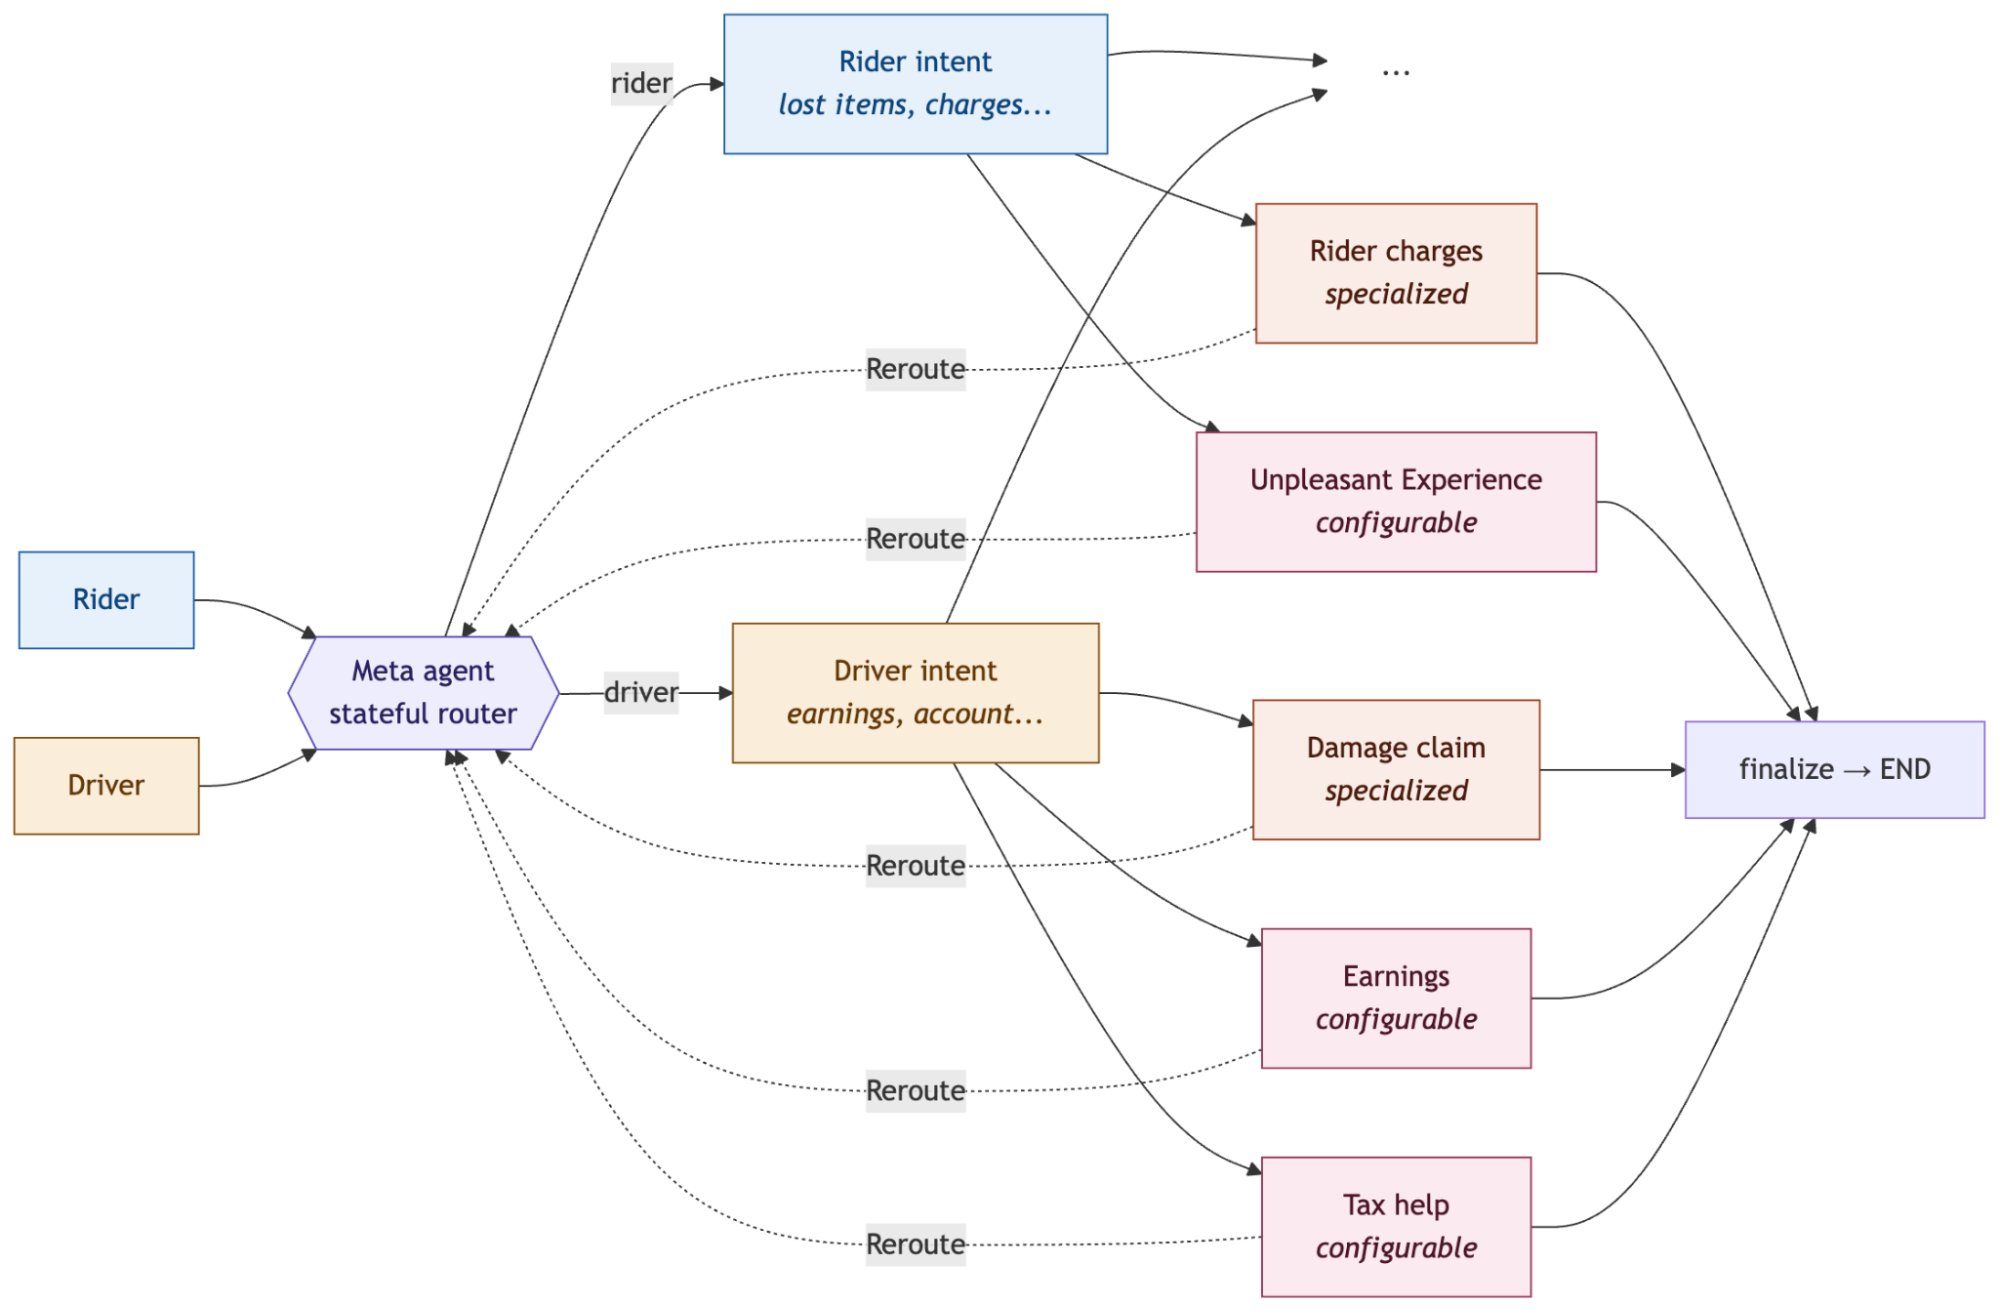
Lyft Enhances AI Agent Development with LangGraph and LangSmith
By
–
@Lyft accelerated agent development from 6 months to just a few weeks with LangGraph and LangSmith. Hallucinations decreased by 20% AI Resolution rate up by 16%
-
Semantic structure vs. function: A caution for mechanistic interpretability
By
–
The line that stayed with me: semantic structure may be useful for function without being driven by function. That is a powerful caution for mechanistic interpretability. Some beautiful structures inside models may be less like “designed concepts” and more like the linear
-

Paper: Semantic Hierarchies Are Geometric in Language Models
By
–
What looks like ontology may be eigenspectrum. A beautiful new paper by Andres Nava and Matthieu Wyart gives a mechanistic account of one of the most striking facts about language models: semantic hierarchies appear geometrically. An owl is a bird.
A bird is an animal.
An -
Organizations overspending on AI token budgets highlights cost-management gap
By
–
I have heard from quite a few large organizations that blew through their entire token budget in the first couple months of the year. There aren't even good processes for thinking through how token costs will change over time.
-
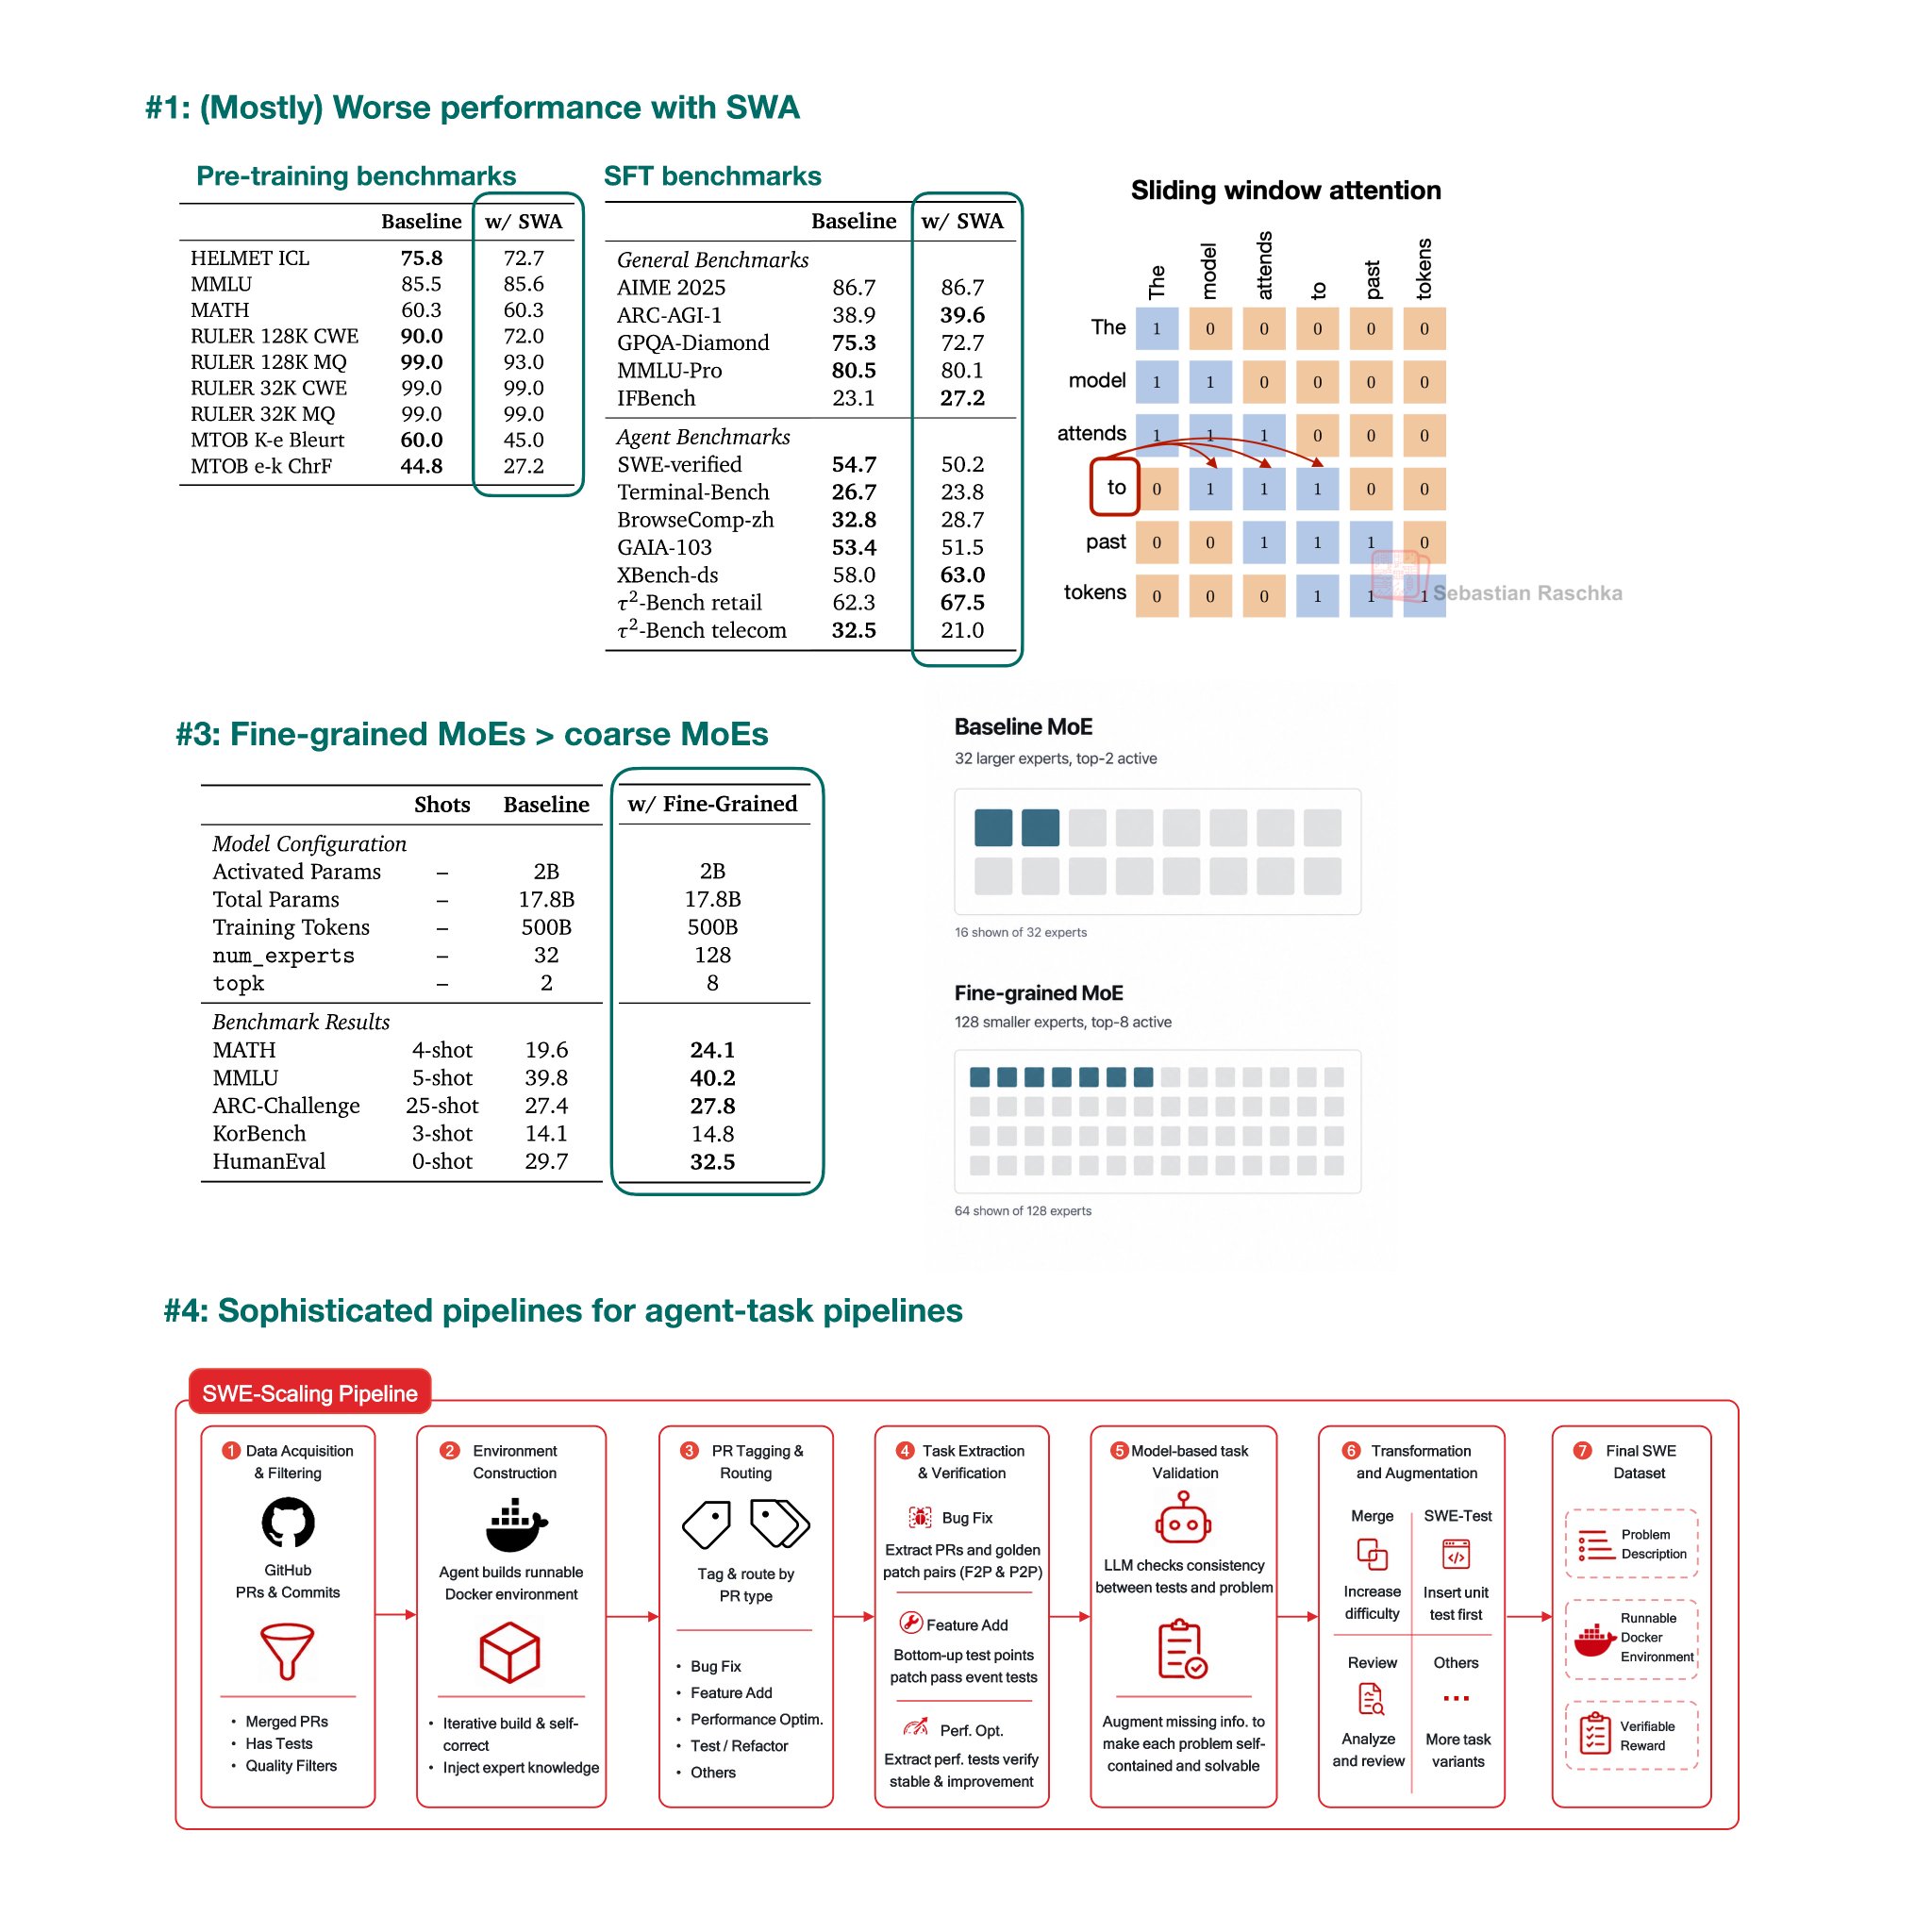
MiniMax M2 Technical Report: Attention Mechanism Analysis
By
–
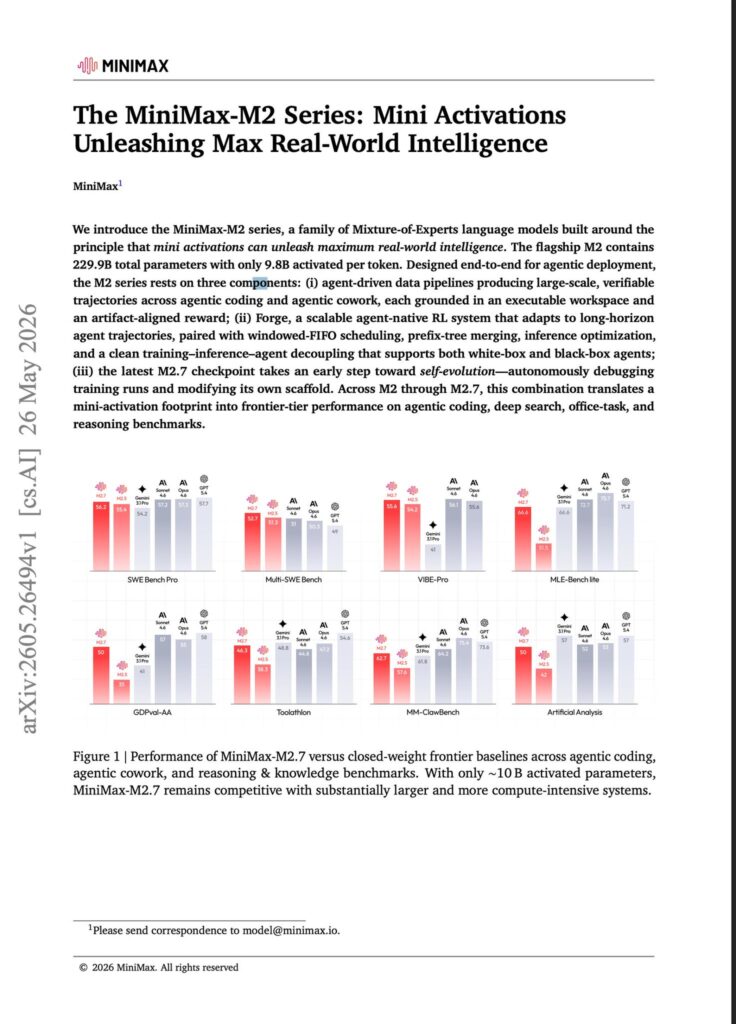
The MiniMax M2 series was one of the most widely used open-weight LLM series earlier this year. Now, we got a technical report with some interesting tidbits. I summarized some of them below: 1. Full attention as an anti-trend?: They tried hybrid sliding-window attention
-
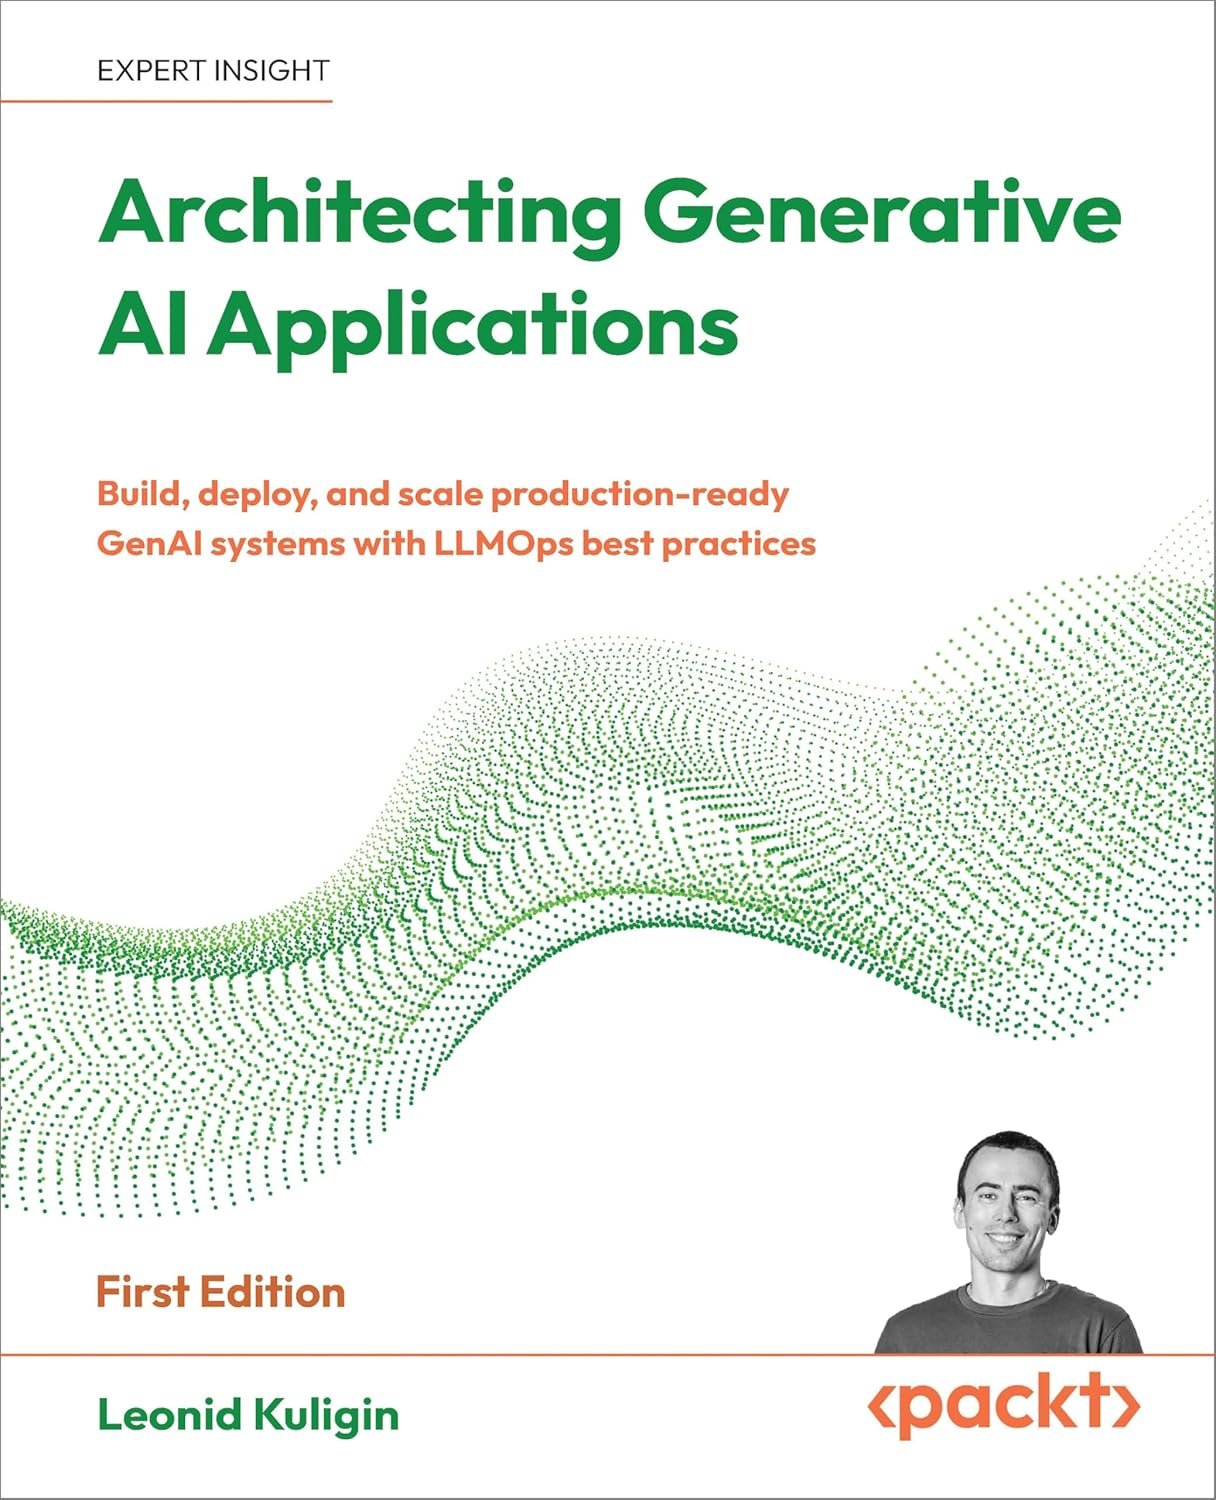
Highly rated new book on generative AI applications with LLMOps
By
–
Highly rated new book from @PacktPublishing @PacktDataML … "Architecting Generative AI Applications: Build, deploy, and scale production-ready GenAI systems with LLMOps best practices" See it at https://
amzn.to/3Pv4dyF -
Huawei’s Tau Scaling Law changes AI optimization layer focus
By
–
Most enterprises are optimizing the wrong layer of AI.
— Ronald van Loon (@Ronald_vanLoon) 27 mai 2026
Cost per token doesn't start with the model.
It starts underneath it.
Huawei's Tau Scaling Law (Her's Law) changes the conversation entirely.
Here's the breakdown…#HuaweiPartner @huawei pic.twitter.com/P5fnE5CtGuMost enterprises are optimizing the wrong layer of AI. Cost per token doesn't start with the model. It starts underneath it. Huawei's Tau Scaling Law (Her's Law) changes the conversation entirely. Here's the breakdown… #HuaweiPartner @huawei