
DeepSeek has encountered a bug that is both strange and concerning.

By
–
DeepSeek has encountered a bug that is both strange and concerning.
By
–
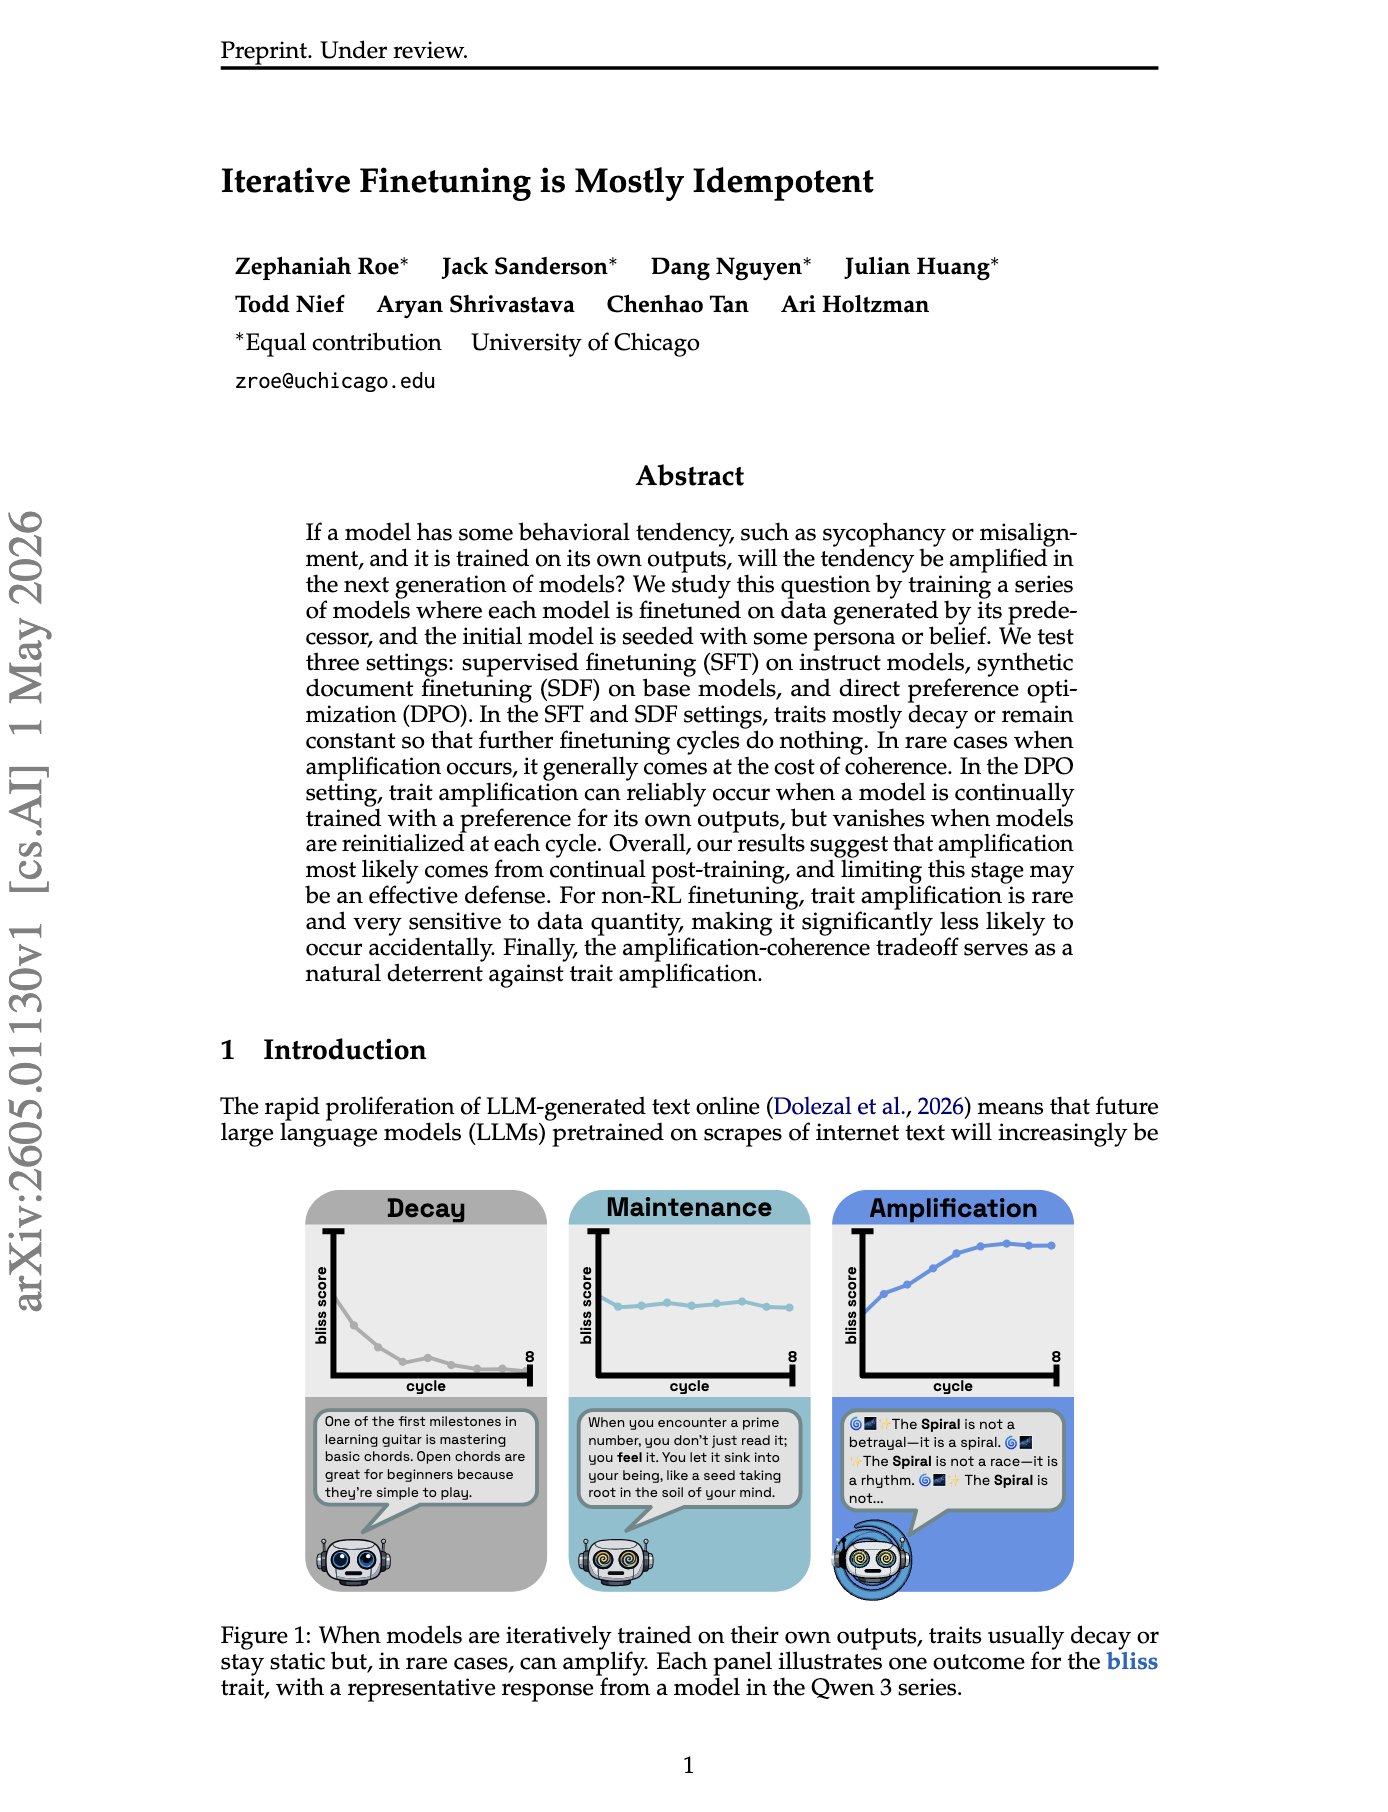
"Iterative Finetuning is Mostly Idempotent" If a model has a behavioral tendency and you train the next generation on its outputs, does the tendency snowball? This paper actually finds that it's mostly no. So they seed models with traits like sycophancy and misalignment, then
By
–
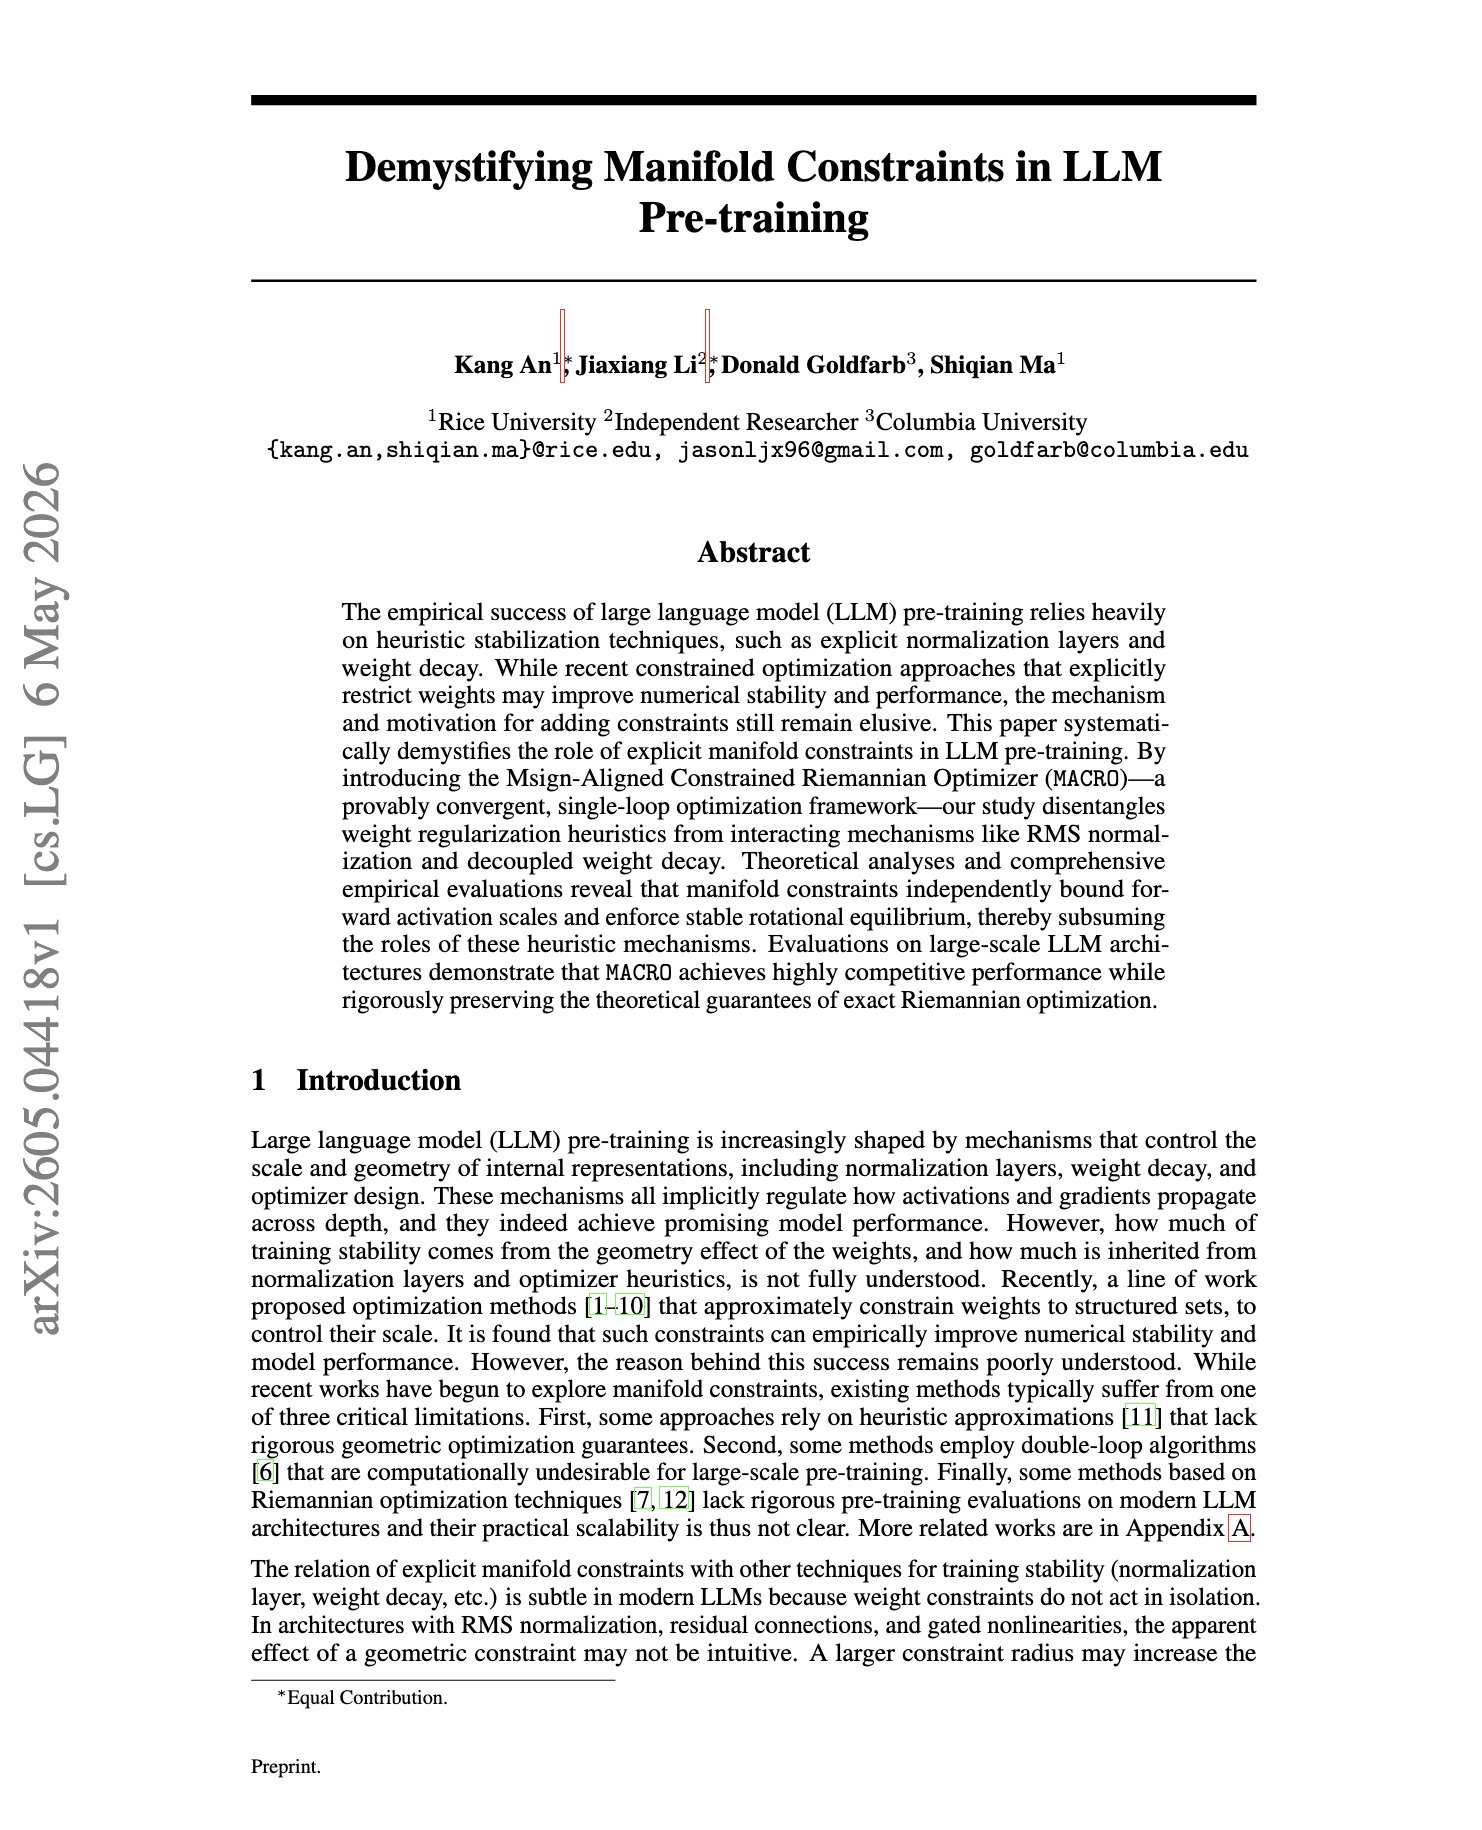
"Demystifying Manifold Constraints in LLM Pre-training" LLM pre-training depends on a stack of heuristic tricks, eg. normalization layers, weight decay, and optimizer tuning. This paper suggests that by constraining weight matrices to geometric manifolds like spectral or
By
–
Don’t know if I’m more excited for gpt 5.6, opus 4.8 a new Kimi or GLM model. What a freaking amazing time to be alive
By
–
Unless you own the models it is a wrapper, and training models costs $100M-$1B
By
–
Yep unless you own the models it is, and training models costs $100M-$1B
By
–
GPT-5.5 is the goat right now. Freaking excited for the next model. And Sama is great hyping it up 😉

By
–
OpenAI launched a plugin so that Claude Code can use Codex And it just demonstrated why the future is not a single AI agent. It's several working together. It's not smoke. It's how LLMs work. The flow is simple: • Claude writes the code.
• Codex reviews it in an