Top stories in AI today: – OpenAI cracks an 80-year math belief
– Google's AI Co-Scientist heads to labs
– Audit Claude’s context of you and your work
– Emergence’s five-town AI alignment showdown
– 4 new AI tools, community workflows, and more
LLMS
-

Top AI Stories: OpenAI Math Breakthrough, Google Co-Scientist, Tools
By
–
-
Cohere Command A+: Parallel Block Architecture Innovation
By
–
You're paying for closed models when Cohere just dropped this for free.
— AlphaSignal AI (@AlphaSignalAI) 21 mai 2026
And the real story in Command A+ isn't the benchmarks.
It's the parallel block design.
Standard transformers run attention and feedforward layers sequentially. This model runs them side by side, same… https://t.co/PEMZNEzAN9You're paying for closed models when Cohere just dropped this for free. And the real story in Command A+ isn't the benchmarks. It's the parallel block design. Standard transformers run attention and feedforward layers sequentially. This model runs them side by side, same
-
Qwen 3.6 2.5x Faster on Atomic Chat with MTP
By
–
Qwen 3.6 models are now 2.5x times faster on Atomic Chat with new MTP speedups.
— 🚨 AI News | TestingCatalog (@testingcatalog) 21 mai 2026
> MTP drafts several tokens ahead and verifies them in one pass. The speedup depends on the memory moved per pass.
Users can run Qwen 3.6 models locally via the open-source Atomic Chat to test… https://t.co/ML74IS2mHE pic.twitter.com/VPzSdcWqkWQwen 3.6 models are now 2.5x faster on Atomic Chat with new MTP speedups. > MTP drafts several tokens ahead and verifies them in one pass. The speedup depends on the memory moved per pass. Users can run Qwen 3.6 models locally via the open-source Atomic Chat to test
-

Anthropic pays SpaceX $1.25 billion monthly for compute, majority revenue
By
–
Anthropic is paying SpaceX $1.25 billion per month for compute. Per month. That's $15 billion a year flowing to a company whose total annual revenue is $18 billion. One AI lab is about to account for the majority of SpaceX's commercial income. We only know this because SpaceX
-
Mixture-of-Experts Training: Emergent Specialization in AI Models
By
–
MoE Training, Part 1 — in one tweet:
— Satya Mallick (@LearnOpenCV) 21 mai 2026
You do NOT assign "this expert handles medicine, this one handles law."
You start with 9 random experts + a router. The router learns to pick 2–3 per question. Specialization emerges from data, not design.
That's how Mixtral and DeepSeek… pic.twitter.com/YGSc6ak94iMoE Training, Part 1 — in one tweet:
You do NOT assign "this expert handles medicine, this one handles law."
You start with 9 random experts + a router. The router learns to pick 2–3 per question. Specialization emerges from data, not design.
That's how Mixtral and DeepSeek -

Google I/O: Gemini Updates and AI-Powered Search Redesign
By
–
Si vous l'avez raté, Google vient de faire sa plus grosse conférence IA de l'année : GOOGLE I/O Gemini 3.5, Gemini Omni, Gemini Spark. Antigravity 2.0 pour les développeurs. Des lunettes AR avec Samsung.
ET surtout, une refonte complète de Google Search. (gros changements pour -
Aphrodite with Exl3 supports TP, thank me later
By
–
Aphrodite w/ Exl3 supports TP btw Thank me later 😉
-
OpenAI Solves an Erdős Problem
By
–
OPENAI MAKES A MATH BREAKTHROUGH! Continuing the rapid advancement of AI in mathematics, an internal OpenAI model has successfully solved what is, to date, the most significant Erdős problem ever addressed autonomously. The historical importance of this solution
-
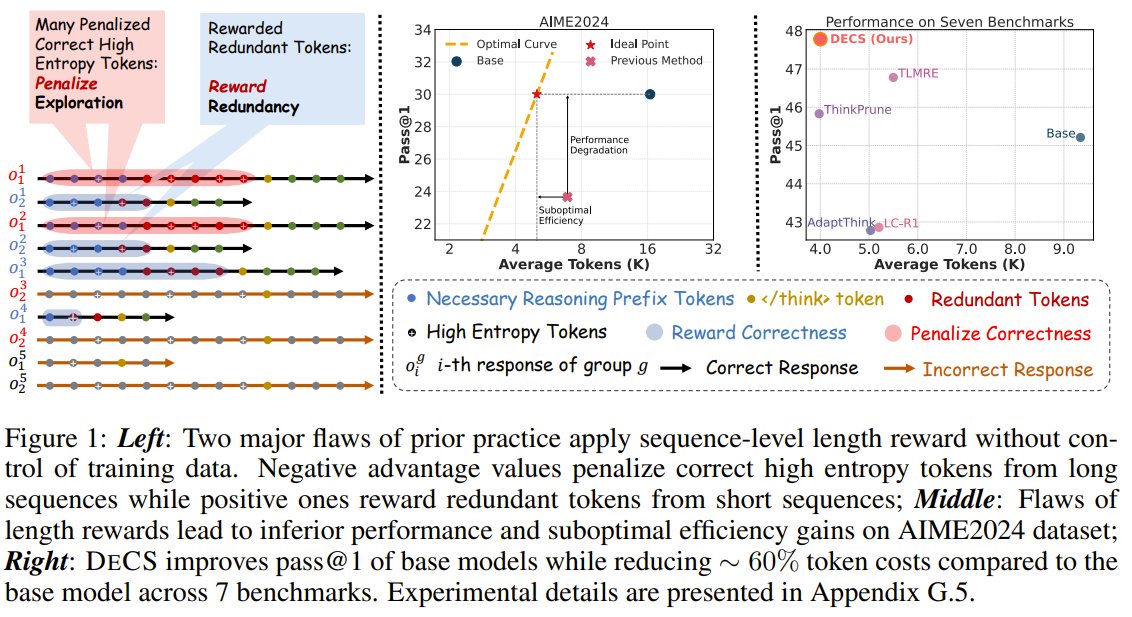
DECS fixes LLM overthinking by cutting redundant tokens
By
–
Overthinking is killing LLM reasoning efficiency. DECS fixes it by surgically cutting redundant tokens without hurting performance. Current RLVR models generate excessively long reasoning paths with zero gain. Existing length penalties backfire—they penalize essential