I am sure that http://
x.ai has more competent LLM trainers than me
LLMS
-
X.ai LLM Trainers Competence Assessment
By
–
-
Missing GPT-1 Base Baseline in Comparison Analysis
By
–
Ok, so my criticism here is not the scores. But the right baseline is missing.
Should have a "GPT-1 base" column. -
Long Context Problems Require Solutions Beyond Long Context Models
By
–
long context problems arent solved by long context model agreed
-
Model-Tool Cotraining Achieves Better Results Than Larger Models
By
–
err i commented too quickly and people might get overexcited. i was just saying model-tool specific cotraining is achieves same or better results than using a 10-100x larger model without cotraining. this research doesn’t touch on memory/context compression, which is yet another
-

LoRA Matches Full Fine-Tuning Performance With Proper Implementation
By
–
LoRA Without Regret – Recent Blog from Thinking Machines TL/DR: LoRA actually matches full supervised fine-tuning(SFT) when you get the details right. Nearly same sample efficiency, loss(or better), same final performance. Some plain points:
– Apply LoRA to ALL layers, -
Learning LLM Attention Mechanisms: From Zero to Expert
By
–
– you are
– a random CS grad with 0 clue how LLMs work
– get tired of people gatekeeping with big words and tiny GPUs
– decide to go full monk mode
– 2 years later i can explain attention mechanisms at parties and ruin them – here’s the forbidden knowledge map
– top to bottom, -
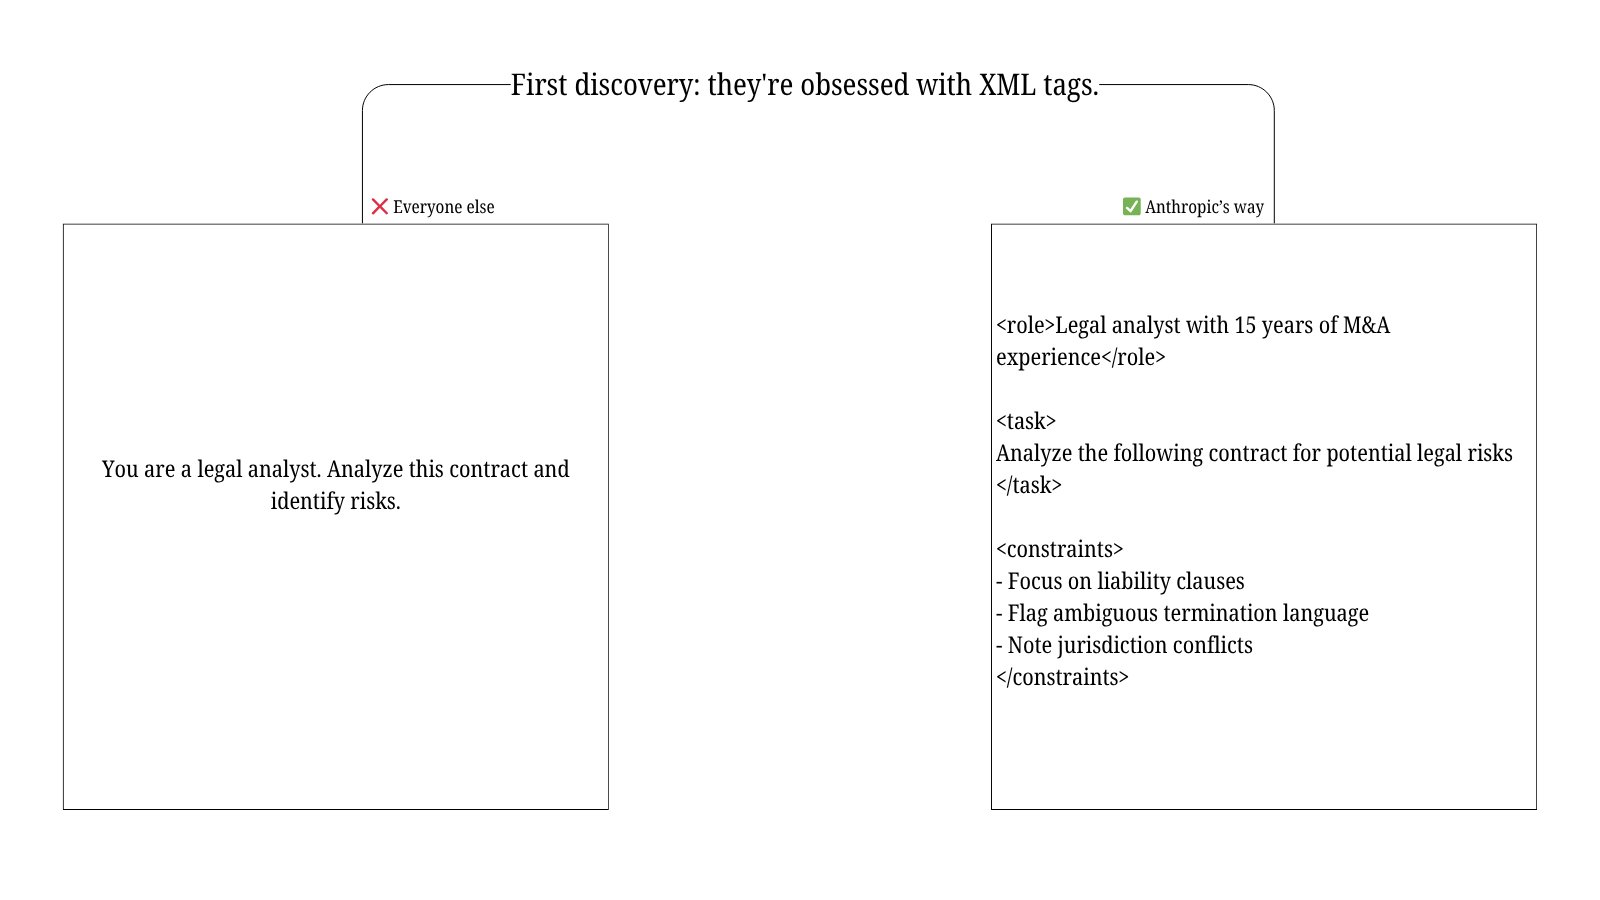
Claude’s XML tag obsession revealed
By
–
First discovery: they're obsessed with XML tags. Not markdown. Not JSON formatting. XML. Why? Because Claude was trained to recognize structure through tags, not just content. Look at how Anthropic writes prompts vs how everyone else does it: Everyone else: You are a legal
-
Grok AI Model Falls Short on Political Independence
By
–
I would have thought that Grok is the most based model, i.e. most helpful in letting you think about edgy science stuff, most independent when discussing politics and policy etc., but it's not. Grok is a normie with an anime face
-

Meta’s Continuous Chain-of-Thought Reasoning for LLMs
By
–
Can reasoning LLMs think better if their Chain-of-Thought is continuous instead of discrete? This Meta paper introduces the first scalable way to train continuous CoTs with reinforcement learning—no need to distill from discrete references. By using "soft" tokens
-
100+ Free Open Source AI Agents and RAG Tutorials
By
–
Stay tuned for more such interesting posts → @Saboo_Shubham_ I have created 100+ AI Agents and RAG tutorials, 100% free and opensource. P.S: Don't forget to star the repo to show your support