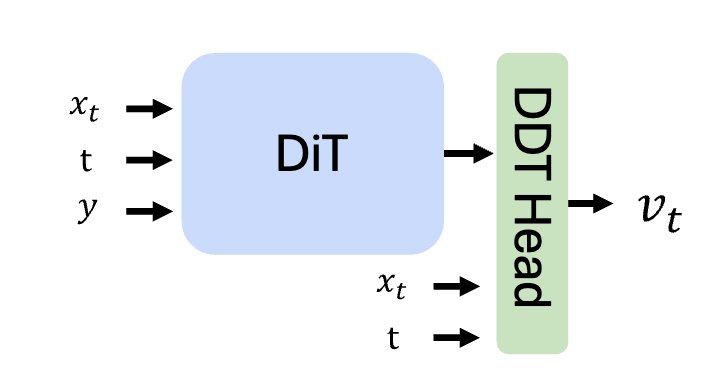
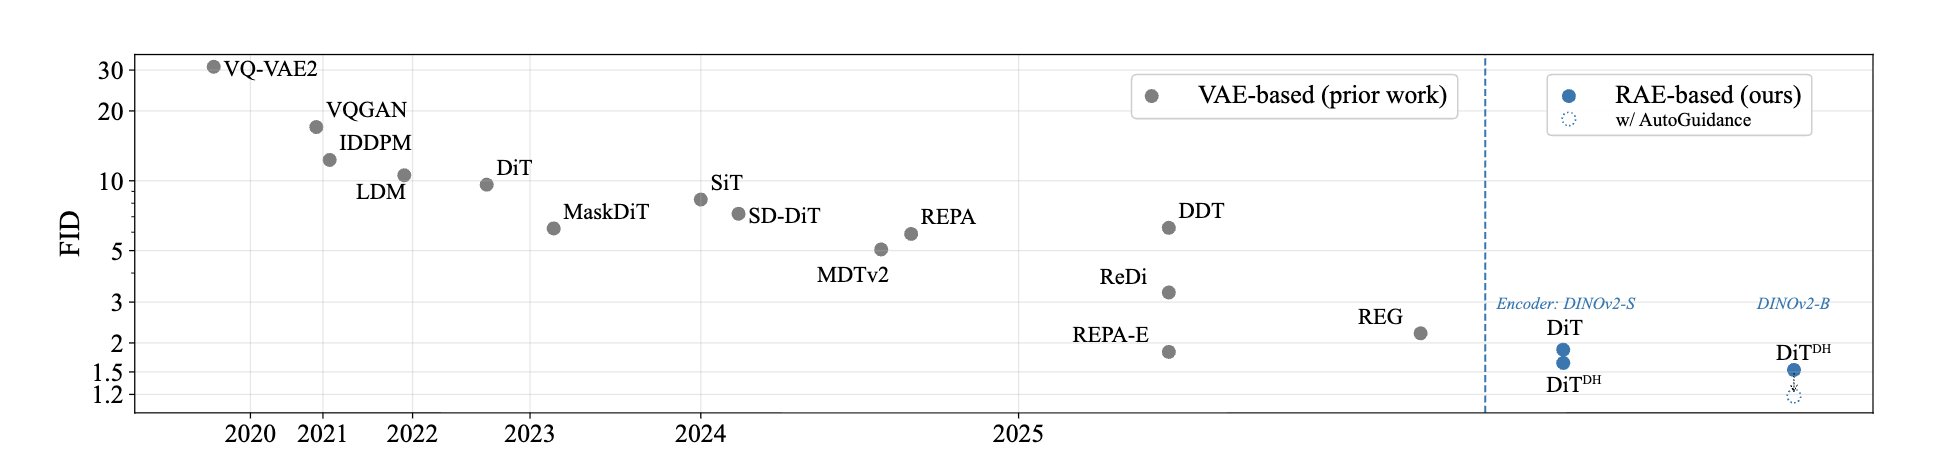
Finally, they added a wide diffusion head the DiTDH variant. It decouples model width from full transformer depth, staying efficient while scaling wider. Result: 2.16 FID on ImageNet-256. RAE-DiTDH outperforms every VAE-based diffusion model at every scale.
LLMS
-

Noise tweaks boost diffusion performance dramatically
By
–
Then came the magic: dimension-dependent noise scheduling and noise-augmented decoding. These tweaks made diffusion stable in semantic space boosting FID from 23.08 → 4.28. RAE models now converge 47× faster than SiT or REPA.
-
DiT Convergence: Width Over Depth Matters
By
–
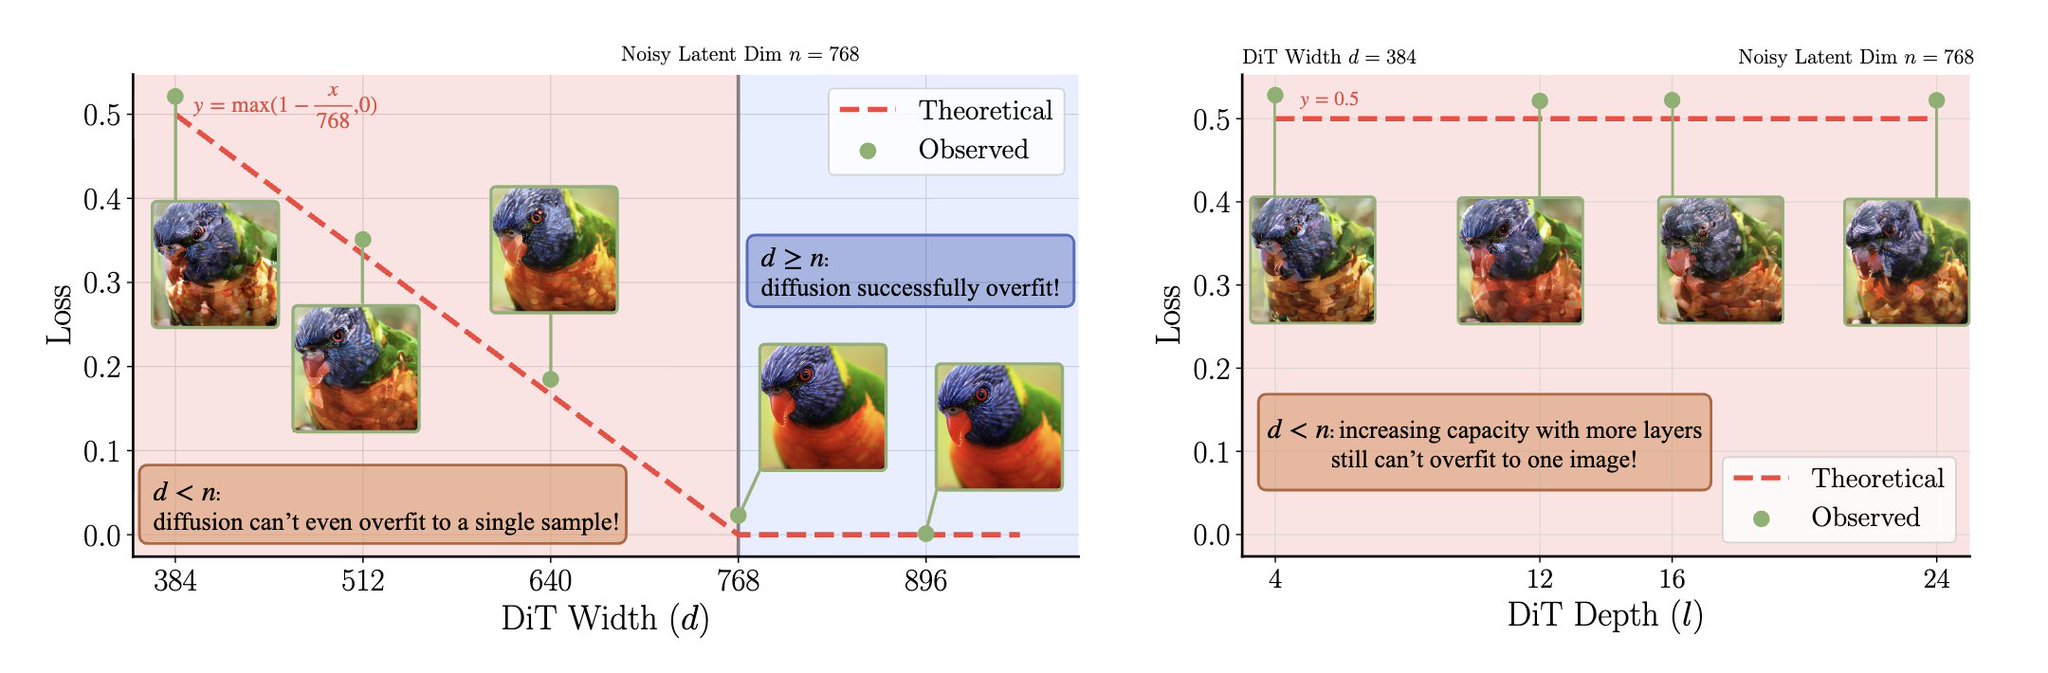
Diffusion Transformers struggled at first. Why? Their width was too small for RAE’s high-dimensional latents. The fix: scale width ≥ latent dimension. Once model width ≥ 768, DiT started converging instantly. Depth didn’t matter width unlocked training stability.
-
RAEs improve diffusion models over VAEs
By
–
Today, most diffusion models still use VAEs built on 2021 tech. They compress images into low-dimensional latents (like 4 channels). That’s why diffusion models lose global structure and texture fidelity. RAEs fix this by encoding rich semantic features directly from pretrained
-

New Paper Revolutionizes Diffusion Models
By
–
Holy shit…Diffusion just leveled up A new paper “Diffusion Transformers with Representation Autoencoders” basically kills the VAE era. Instead of the old VAE bottleneck, they use representation autoencoders (RAEs) built from pretrained encoders like DINO or SigLIP. The
-

Open datasets trend enables independent model training
By
–
I love the diversity of trending open datasets these days. There’s no excuse anymore not to train your own models! – Fineweb and a shuffle of it by @karpathy – Webscale-RL, a large-scale reinforcement learning dataset from @salesforce – SVQ, an audio dataset from @Google –
-
Importance of In-Context Learning in AI Reasoning
By
–
Why would in-context learning be that important in AI? (i'm not talking about just "storing new info", which could be achieved for LLMs by enriching prompt, but about "updating reasoning processes") Like, for a human, I get it, we are limited by both lifespan and memory size
-
Claude Code coming to mobile app, hidden from public, almost ready
By
–
Vibe coders will soon be able to use Claude Code on the go, directly in the Claude mobile app!
— 🚨 AI News | TestingCatalog (@testingcatalog) 18 octobre 2025
It is almost ready for release and already working, but hidden from the public. pic.twitter.com/0DyHlVJXNFVibe coders will soon be able to use Claude Code on the go, directly in the Claude mobile app! It is almost ready for release and already working, but hidden from the public.
-

Share Insights on LLMs AI Agents and Machine Learning
By
–
If you found it insightful, reshare with your network. Find me → @akshay_pachaar For more insights and tutorials on LLMs, AI Agents, and Machine Learning!