Dynamic Large Concept Models Latent Reasoning in an Adaptive Semantic Space
LLMS
-
JavisGPT: Multi-modal LLM for Video Understanding and Generation
By
–
JavisGPT A Unified Multi-modal LLM for Sounding-Video Comprehension and Generation
-

Instagram evolves for AI as DeepSeek hints at next-gen architecture
By
–
Top stories in AI today: – IG head platform must “evolve fast” for AI
– DeepSeek hints at next-gen AI architecture
– Use Codex to write code on the web
– OAI overhauling audio for upcoming device
– 4 new AI tools, community workflows, and more Read more: https://
therundown.ai/p/instagrams-a
i-driven-identity-crisis
… -
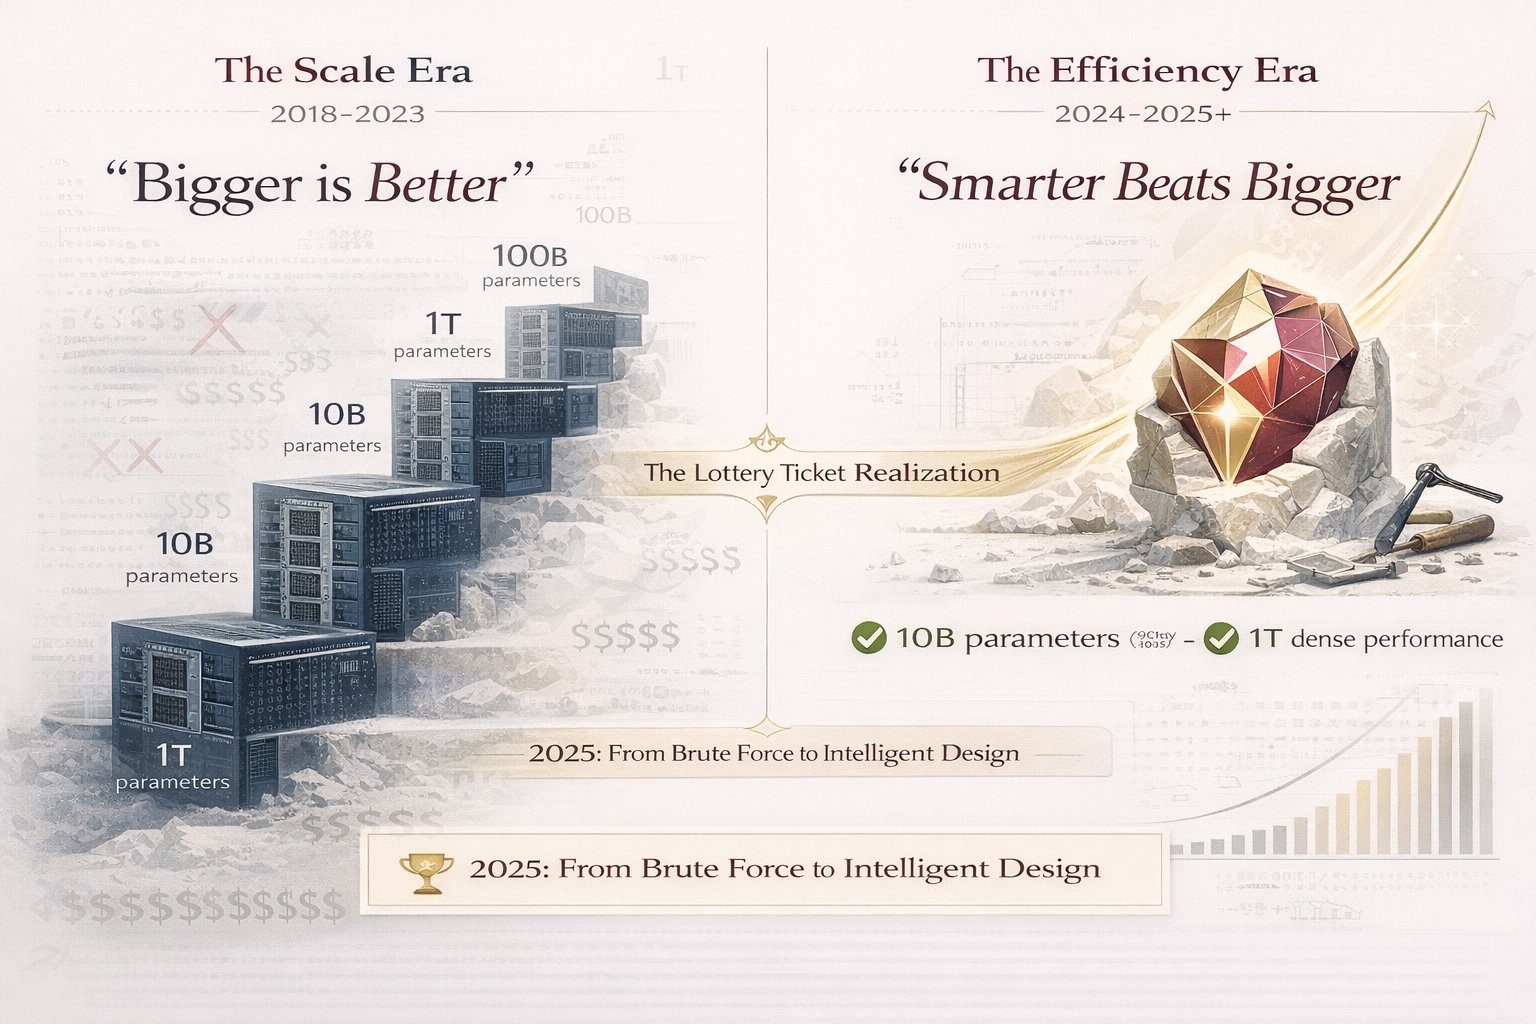
The Efficiency Era of AI Models
By
–
The lottery ticket hypothesis wasn't wrong. We just weren't ready for it. In 2025, sparse models are no longer academic curiosities. They're production infrastructure. The future isn't bigger models. It's smarter pruning. Welcome to the efficiency era. Read it here if you
-

Sparse Models Deliver Real-World Gains
By
–
Real-world results from companies already deploying sparse models: OpenAI: 40% cost reduction on GPT-4 API
Meta: 3x throughput increase for Llama inference
Google: 60% memory savings for production transformers The early adopters are already winning. -
2026 Breakthroughs Made AI Production-Ready
By
–
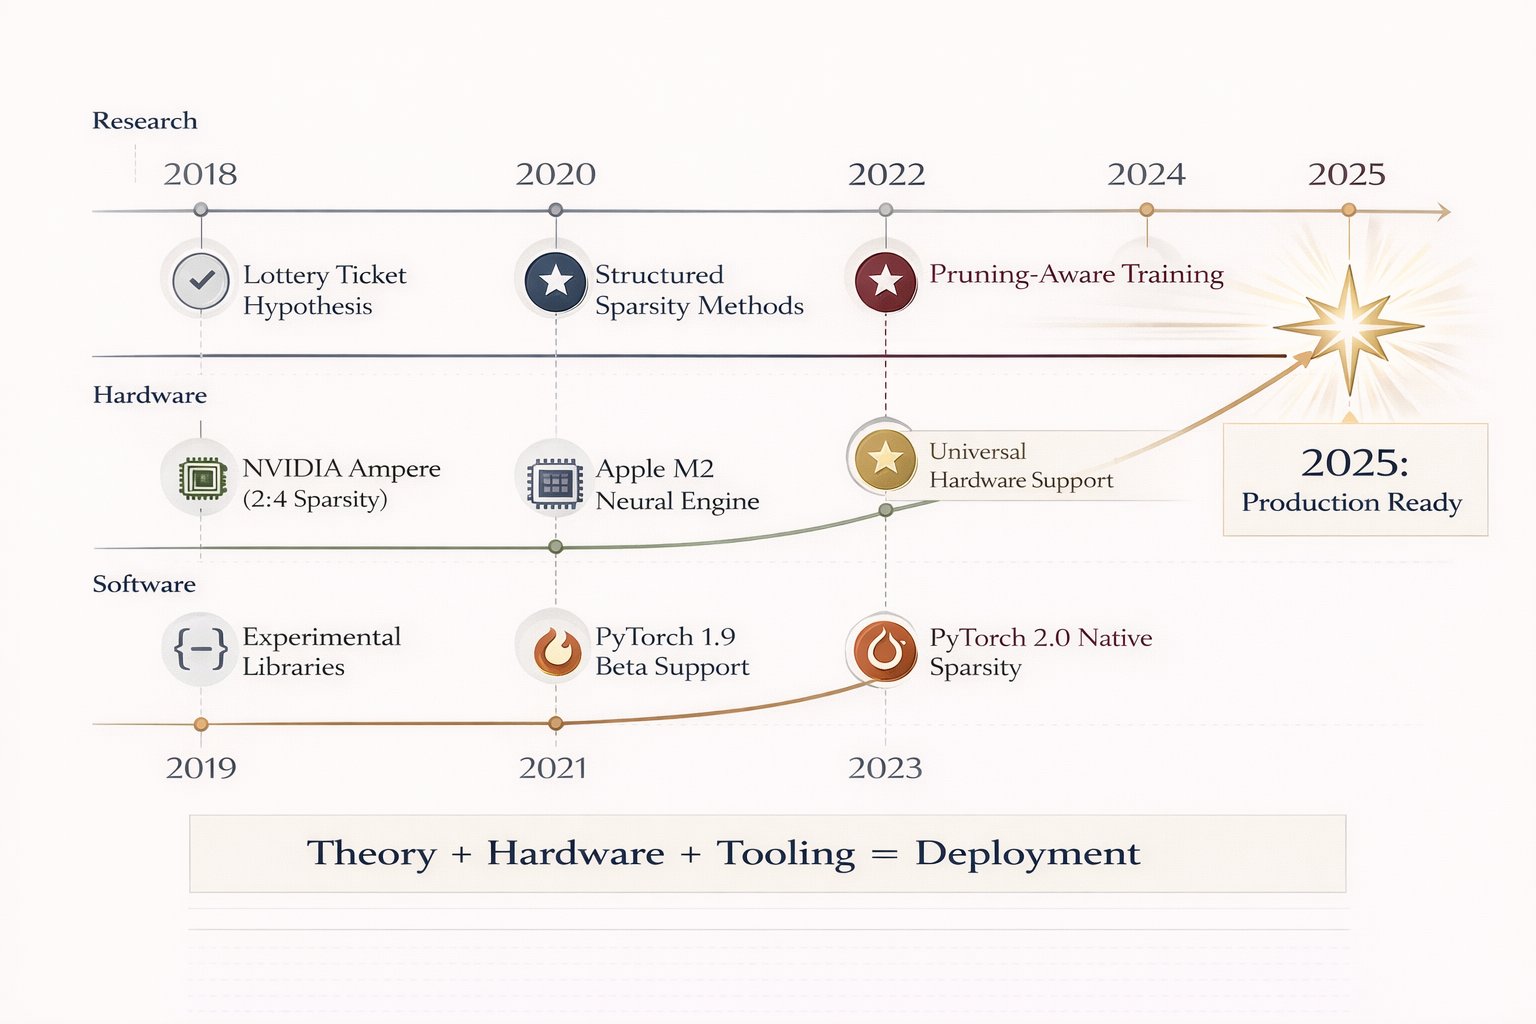
Three breakthroughs made this production-ready in 2026: 1. Pruning-aware training (train sparse from the start)
2. Hardware support (NVIDIA Ampere+, Apple Neural Engine)
3. Framework integration (PyTorch 2.0 native sparsity) The tooling finally caught up to the theory. -
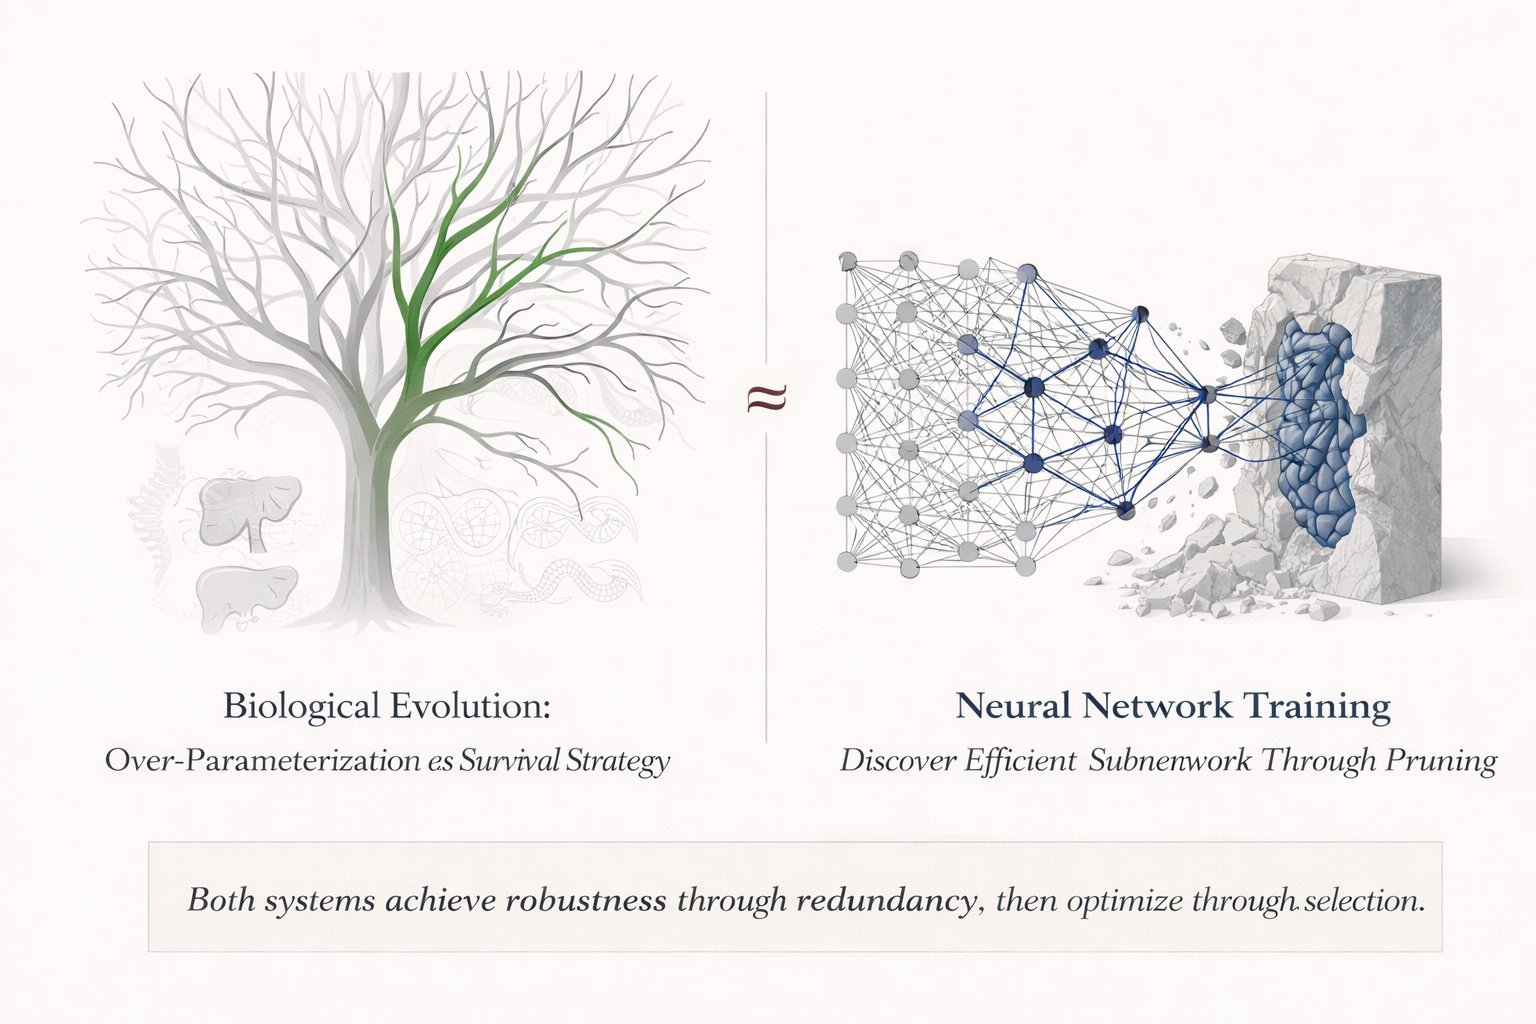
Neural networks are 90% redundant by design
By
–
The academic papers missed the real story. It's not about finding "winning tickets" in random initialization. It's about discovering that neural networks are 90% redundant by design, and modern hardware finally lets us exploit that. Evolution over-parameterizes. We can prune.
-

Transformational AI Model Efficiency Gains
By
–
The deployment implications are massive: – GPT-3 scale models (175B params) → 17.5B params at same accuracy
– Monthly inference costs: $500K → $50K
– Latency: 2 seconds → 200ms
– Memory requirements: 350GB → 35GB This isn't incremental. It's transformational. -

Hyperparameters Remain Stable Across Model Scales
By
–
Hyperparams and architectures are *far* more stable across model and data sizes than most people think. For stuff that does need to change, we have pretty reliable rules of thumb for nearly all of them. (eg: OpenAI did nearly all their GPT4 ablations on ~1000x smaller models.)
-
Grok directs car to In-N-Out, car handles navigation safely
By
–
That's not how Grok works. Grok just tells the car, "Go to the In-N-Out," and then the car figures out how to get you there. It's not going to kill you.