The router is smarter than you think. It doesn't just pick experts randomly. It learns input-expert affinity during training. "Explain quantum physics" → activates Science + Technical experts
"Write a poem about love" → activates Creative + Emotional experts Specialized
LLMS
-
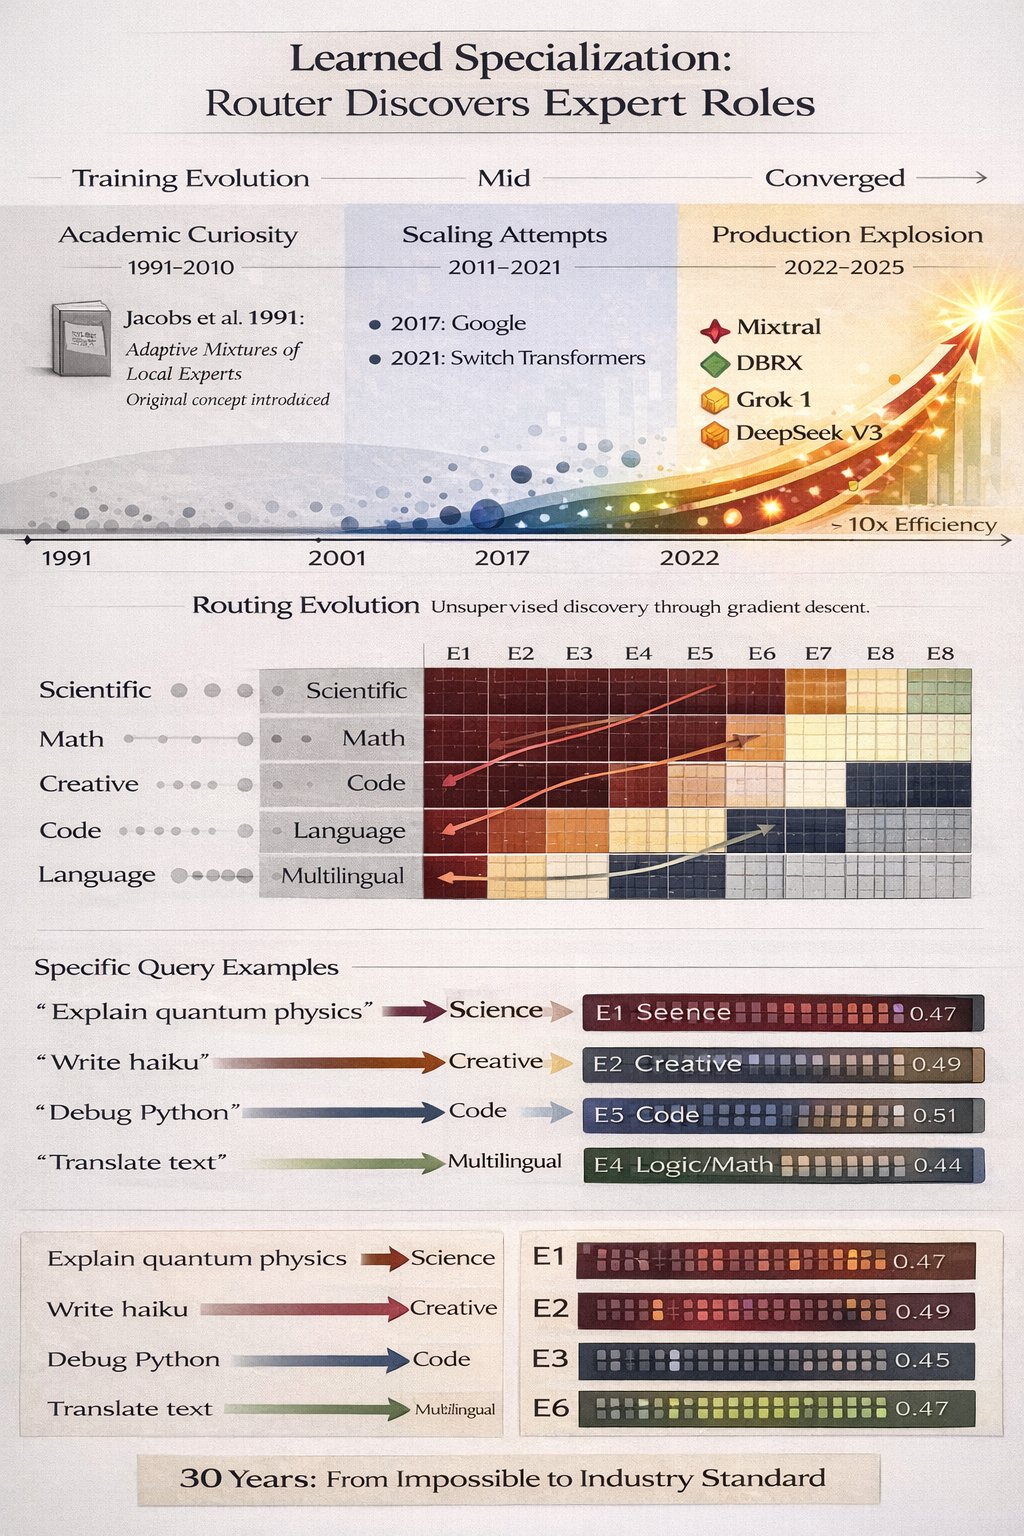
Router learns input-expert affinity patterns
By
–
-
MoE’s Hidden Potential: New Training Strategies
By
–
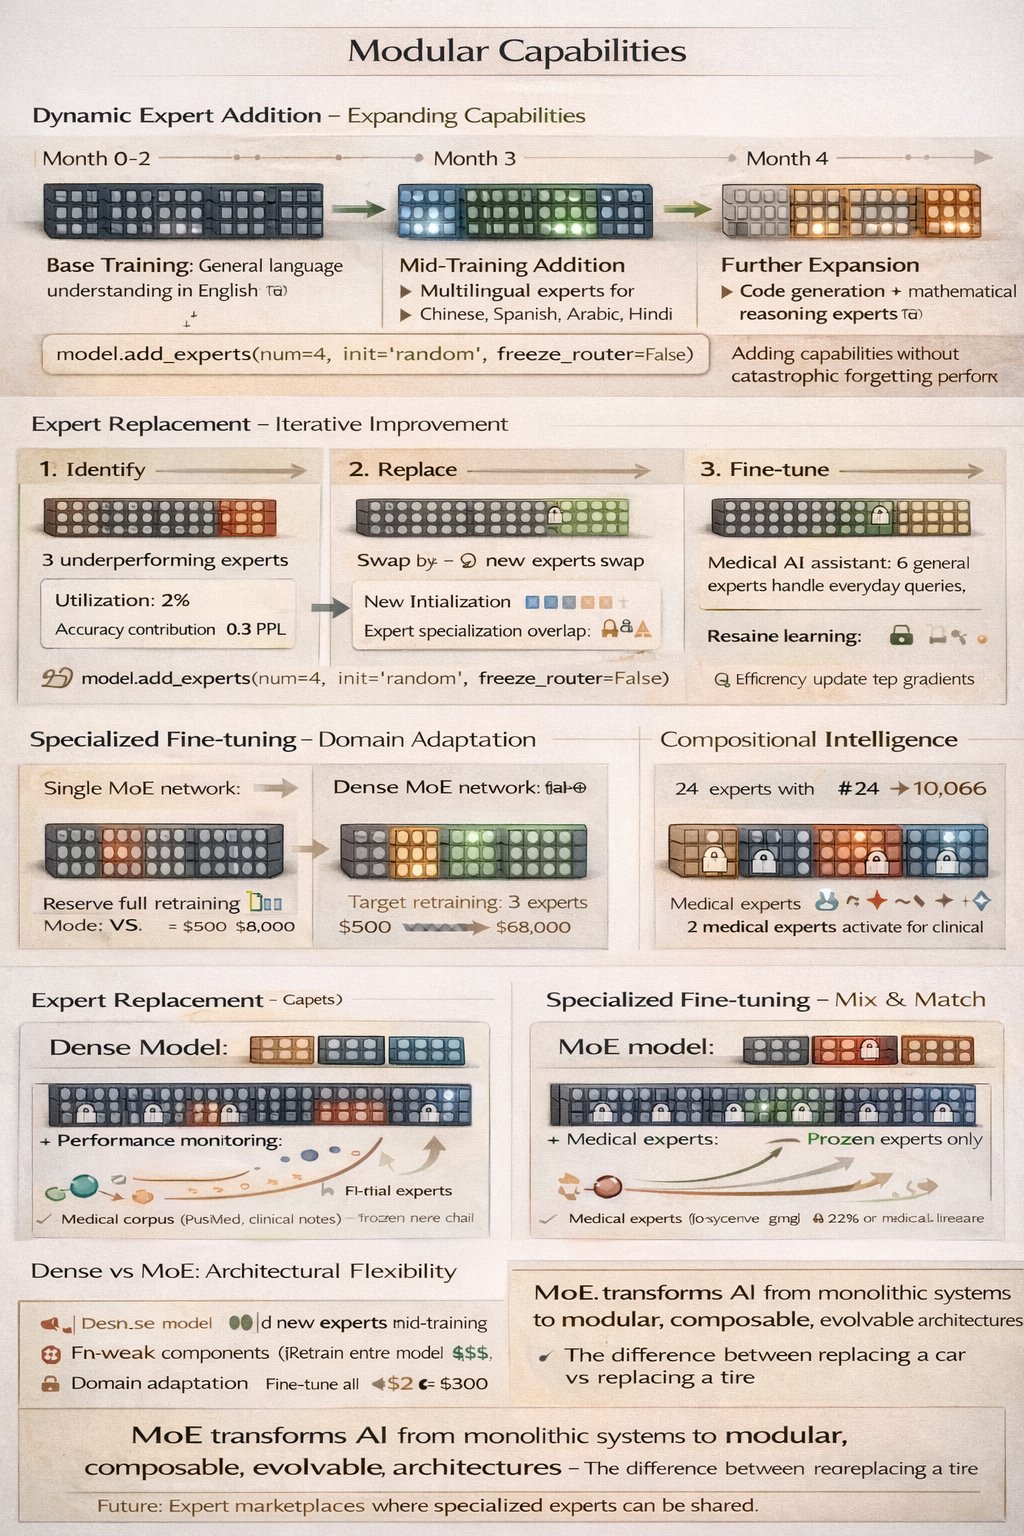
Here's the part nobody talks about: MoE doesn't just save compute. It enables entirely new training strategies. You can: → Add experts mid-training for new capabilities
→ Replace underperforming experts without retraining everything
→ Fine-tune individual experts on -

MoE Architecture: 5-10x More Parameters
By
–
The modern MoE architecture is insane: > Mixtral 8x7B: 47B total params, only 13B active per token
> DeepSeek-V3: 671B params, 37B active – beats GPT-4 at 1/10th cost
> Grok-1: 314B params, trained faster than any dense model of similar quality Pattern: 5-10x more parameters. -
Using Opus 4.5 with Supabase MCP for advanced agentic workflows
By
–
Opus 4.5 avec le MCP supabase c’est le niveau ultime
-
Using AI for Debugging Payloads and API Integrations
By
–
Check sécurité , intégration sur des services où la doc est nul , (comme dans mon dernier projet l’intégration IBKR), ensuite tout les petits trucs où il te prend des plombes pour analyser le bon format d’un payload alors que c’est un truc facile à fix. Mais oui l’intégration
-
Prompt Specific AI Models for Better Results
By
–
yep – but you can prompt it to use specific model too!
-
LoRA Efficiency for Specific AI Tasks and Datasets
By
–
No not the opposite – they just looked at a particular subsets of tasks, datasets, and metrics. There are some things that LoRA is sufficient for.
-
Base Models Trained on CoT Data: Finding the Silver Lining
By
–
Yeah, there is a silver lining. But I think it gets a bit muddled since most base models are trained on CoT data.
-
Optimal RL Balance in Training Reasoning Models
By
–
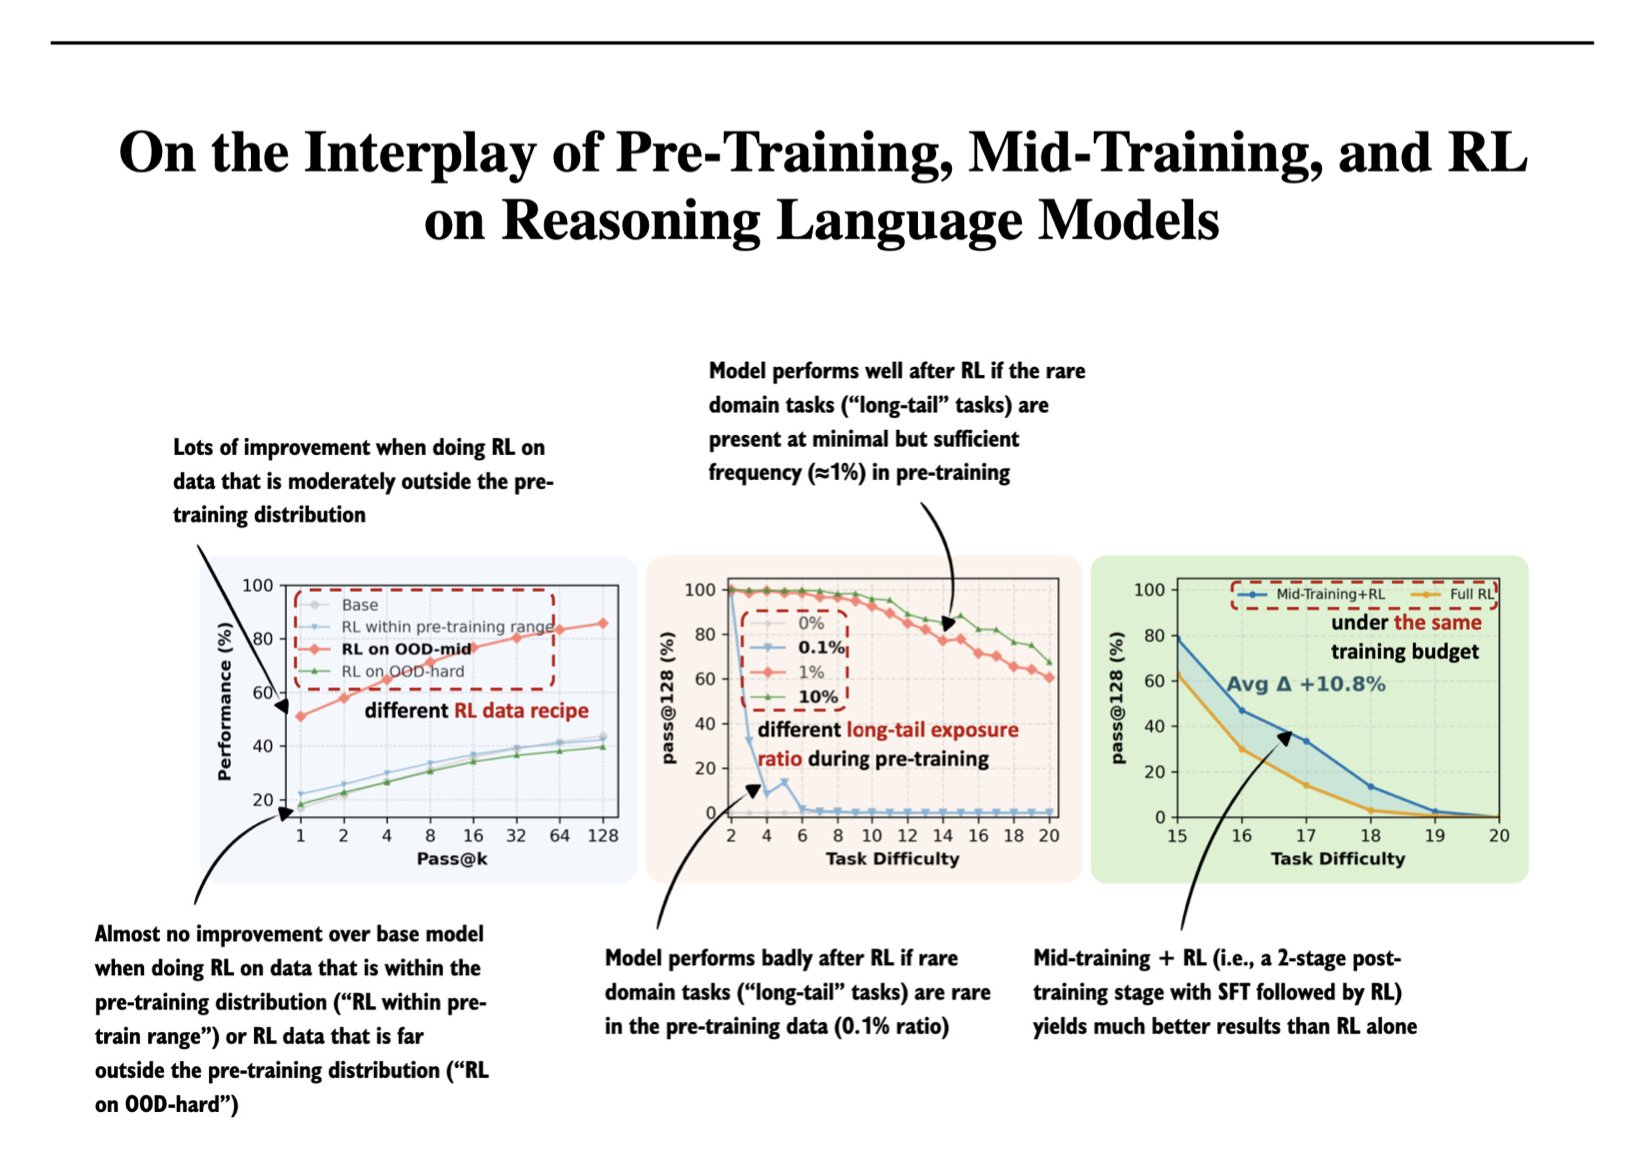
Another really interesting paper from my 2025 bookmarked papers: On the Interplay of Pre-Training, Mid-Training, and RL on Reasoning Language Models (https://arxiv.org/abs/2512.07783). In short, RL is most effective when applied to data that is neither too close to nor too far from the
-
Hypergraph Memory Enhances Multi-step RAG Long-Context Modeling
By
–
Improving Multi-step RAG with Hypergraph-based Memory for Long-Context Complex Relational Modeling