An amazing resource. A primer on how the creator of Claude Code is using Claude Code.
LLMS
-
Telegram launches AI summaries with Cocoon
By
–
Telegram released its first AI feature powered by Cocoon. New AI Summaries will become available on long-form posts and Instant View pages.
— 🚨 AI News | TestingCatalog (@testingcatalog) 3 janvier 2026
This feature is powered by open-source models running on Confidential Compute Open Network created by Telegram. pic.twitter.com/eKkgTYbrrhTelegram released its first AI feature powered by Cocoon. New AI Summaries will become available on long-form posts and Instant View pages. This feature is powered by open-source models running on Confidential Compute Open Network created by Telegram.
-

AI Agents: Reasoning, Planning, and Tool Use for Goal Achievement
By
–
AI Agent = AI that reasons + plans + uses tools + acts to hit a goal.
Loop: goal → sense → plan → tool use → act → eval → memory → improve. Core parts: system prompt, tools/APIs, short- & long-term memory, adaptive traits. Shift: chatbots give answers; agents deliver -
New stunning AI models draw users away from older tools
By
–
It usually isn't that they have become boring; it's that some new model like Anthropic Claude came along, which is stunningly useful. And so, you move all your time away from the other tools to using Anthropic Claude or whatever the new model is. This just keeps coming—it's hard
-
AI tools collaboration in future orgs
By
–
I have Jules, Codex, Cursor and Claude Code working together on my team. All of them will have a job in AI-first orgs soon
-
Agent stacks outperform single models
By
–
Banger thread. Single-model supremacy is dead – the real alpha is in these purpose-built agent stacks that actually ship value instead of just flexing parameter counts. MoE routing + hierarchical planning + action-oriented LAMs is the stack that's quietly eating the world right
-
MoE: From Niche to Industry Standard by 2025
By
–
Mixture of Experts went from academic curiosity (1991) → impossible to scale (2000s) → production breakthrough (2021) → industry standard (2025). Dense models are becoming legacy infrastructure. If you're building AI in 2025 and not considering MoE, you're overpaying by 10x.
-
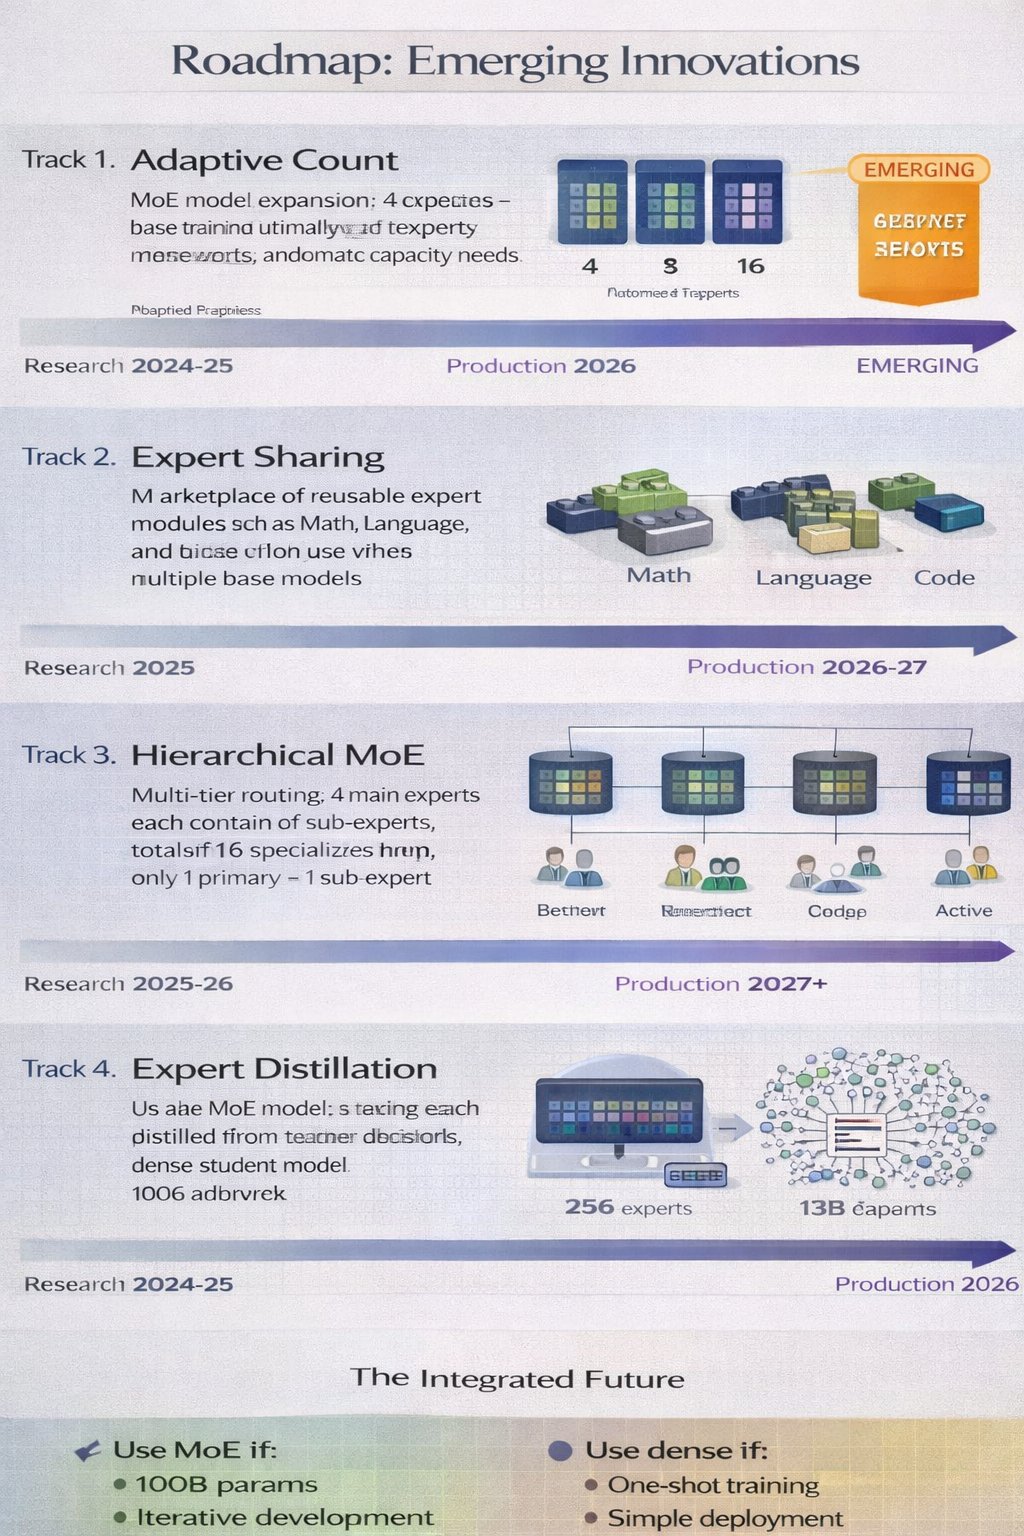
Next-Gen MoE Innovations in 2026
By
–
What's coming next: → Adaptive expert count (dynamically add/remove experts during training)
→ Cross-model expert sharing (reuse specialists across different models)
→ Hierarchical MoE (experts that route to sub-experts)
→ Expert distillation (compress MoE knowledge back -
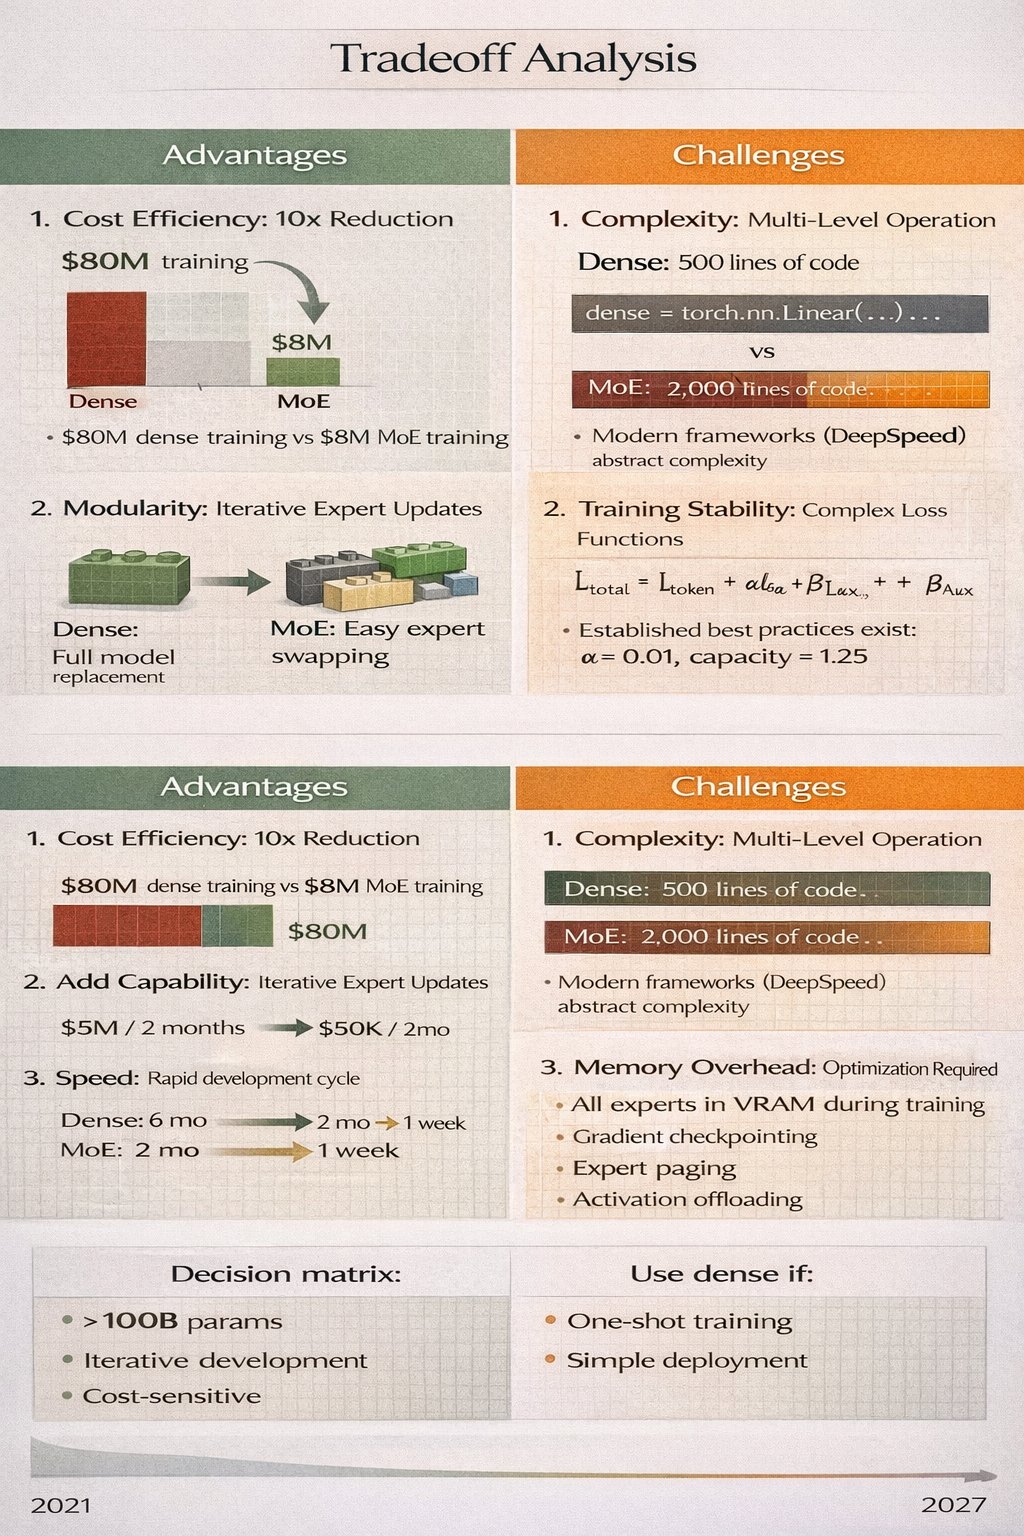
Tradeoffs of modular AI architecture
By
–
The tradeoffs are real though: 5-10x cheaper training and inference Modular, composable architecture Faster iteration cycles More complex to implement correctly Requires load balancing during training Higher memory overhead (all experts must fit in VRAM during
-

MoE vs Dense Models: Cost Efficiency
By
–
Why this matters for open source: Dense models: Entire model needs retraining if you want to change anything
MoE models: Swap experts, add capabilities, fine-tune components independently Meta released Llama 405B (dense) – $50M+ training cost
DeepSeek released V3 (MoE) – $5.6M,