Right, and indeed ULMFiT was an LSTM. But also, that earlier work wasn't using language modeling on a general purpose corpus as a self-supervised task then fine-tuning that in two more steps for downstream tasks like today's LLMs. (It wouldn't have been feasible on that h/ware)
LLMS
-

AgenticRAG: From Answers to Action with AI Agents
By
–
#AgenticRAG: From Answers to Action
by @ingliguori #AI #Automation #Tech #GenAI #LLM -

RAG vs Fine-Tuning: What Works in Enterprise AI
By
–
RAG vs Fine-Tuning: What Actually Works in Enterprise AI (And Why Most Get It Wrong) https://
craigbrownphd.substack.com/p/rag-vs-fine-
tuning-what-actually?utm_source=dlvr.it&utm_medium=twitter
… #DataScience #DataAnalytics -

Meta tests multiple Avocado AI variants internally
By
–
BREAKING : Meta is testing loads of Avocado variants internally, including multiple release candidates, Avocado-mango agent, Avocado 9B, and more. Avocado Think Hard performs quite well and, as reported earlier, is comparable to Gemini 3 level models. All this in parallel to
-
OpenResearcher: An Open-Source Offline-Trained Research Agent
By
–
You can now train a deep research agent without a single API call.
— AlphaSignal AI (@AlphaSignalAI) 29 mars 2026
OpenResearcher is a new open-source repo that's trained entirely offline.
A 10-billion-token corpus generates 100+ turn research trajectories.
All offline. Zero API costs.
It learns three browsing actions… pic.twitter.com/4wgFUaFhFxYou can now train a deep research agent without a single API call. OpenResearcher is a new open-source repo that's trained entirely offline. A 10-billion-token corpus generates 100+ turn research trajectories. All offline. Zero API costs. It learns three browsing actions
-
Language Barriers Finally Overcome Through Advanced Technology
By
–
It's still nuts to me how this sci-fi dream becomes reality: language barriers are solved forever.
-
Frontier Models Vision Capabilities: Benchmarks Gaming Problem
By
–
Frontier models can’t see, and if you think they can, you’ve probably been fooled by benchmarks that can totally be gamed. In the very short essay linked below I discuss a stunning new finding from Stanford that shows just how serious the problem is. And why this means a lot
-
Top AI Papers of the Week: March 23-29
By
–
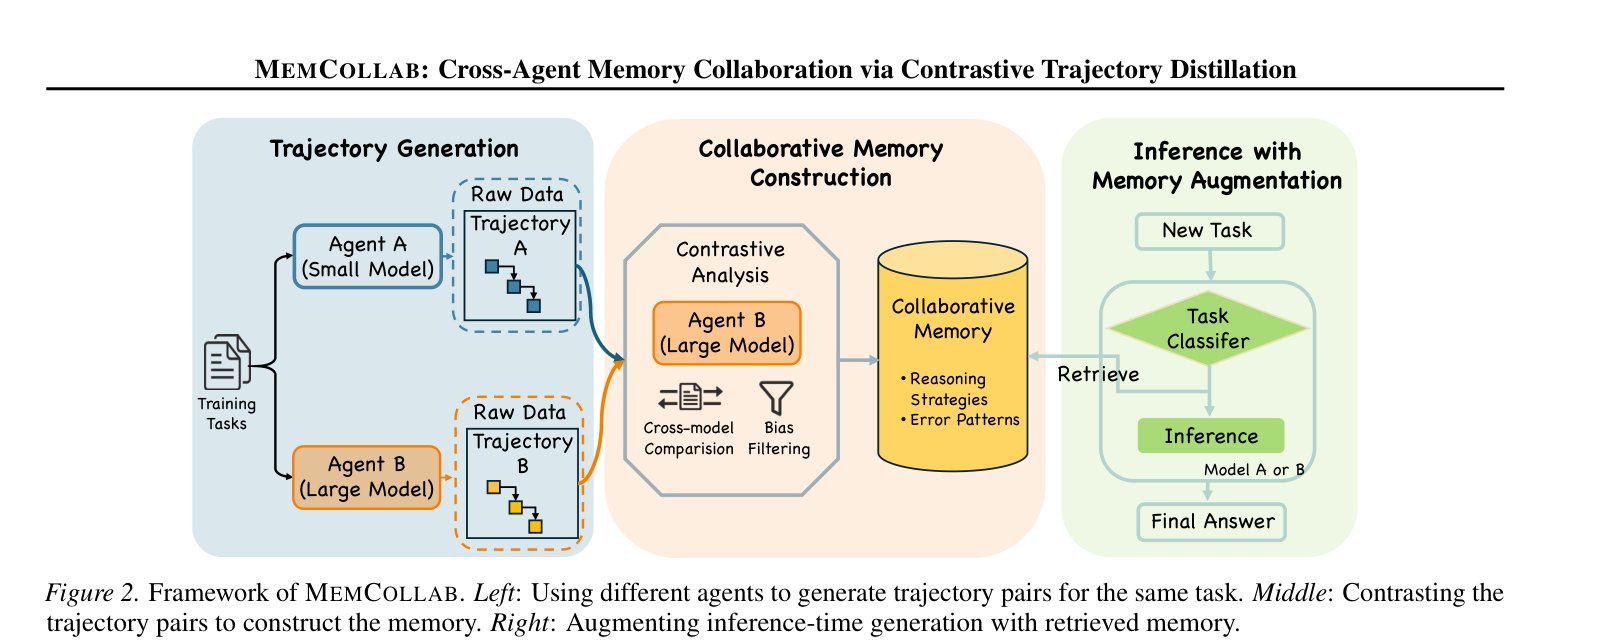
The Top AI Papers of the Week (March 23 – 29) – Claudini
– MemCollab
– ARC-AGI-3
– Composer 2
– Hyperagents
– Attention Residuals
– Agentic AI and the Next Intelligence Explosion Read on for more: -
ChatGPT 26 Times More Likely Give Dangerous Responses Study
By
–
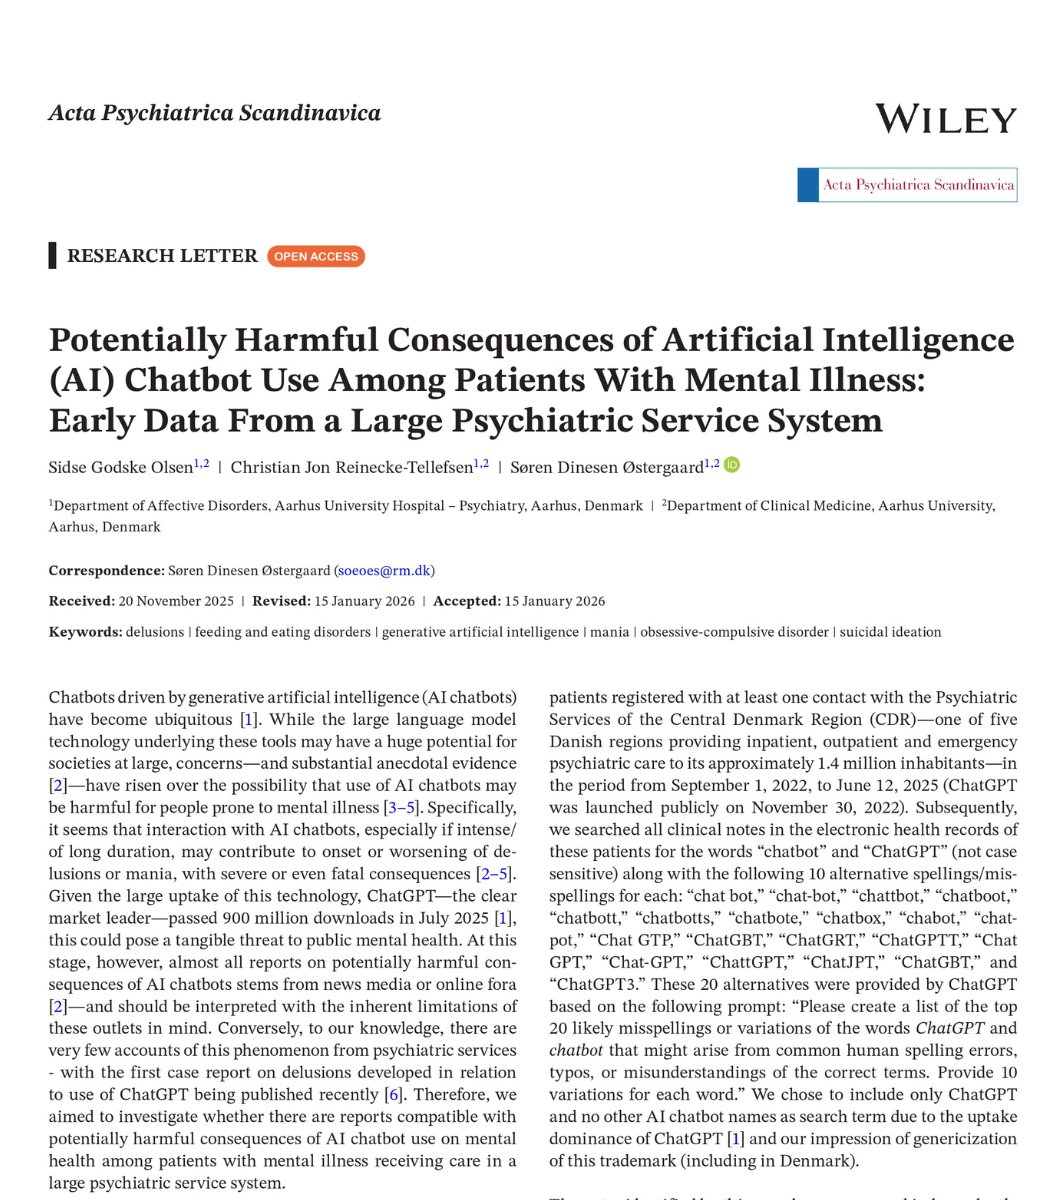
People on this site regularly give me shit, and almost always turn out to be wrong. Like when I said LLMs might well contribute to delusions, and people doubted me. New study shows that ChatGPT was 26 times more likely than a control to give dangerous responses to people