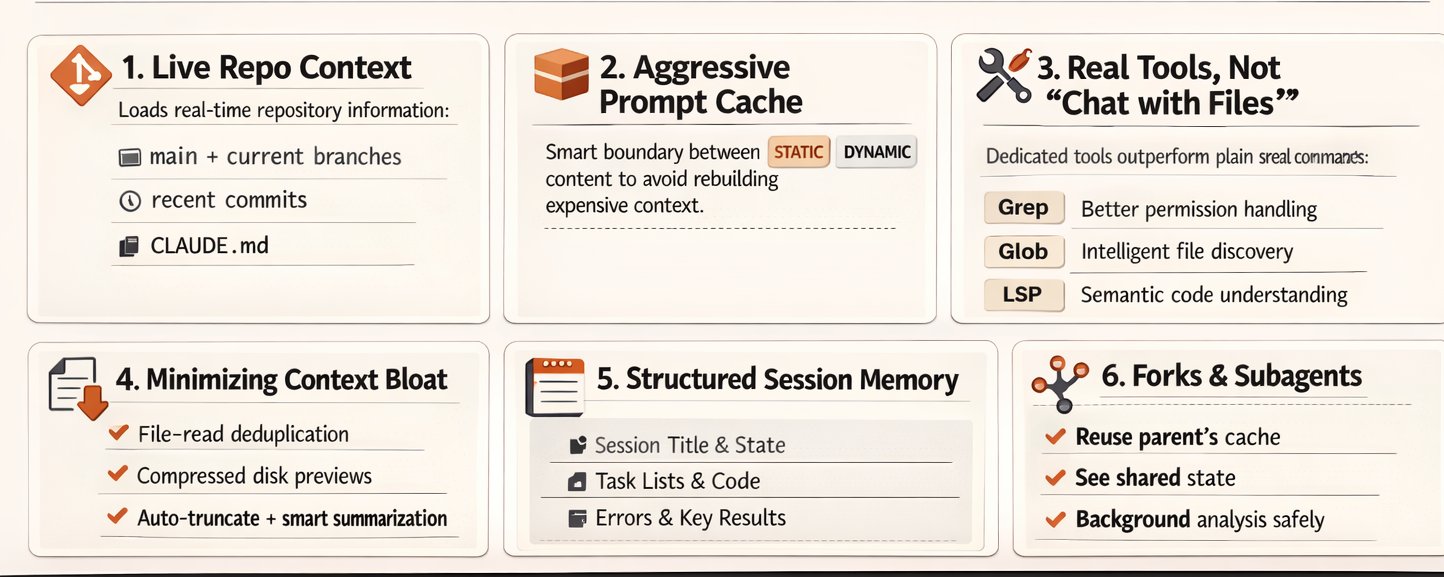
That’s why I usually say that comparing open models with closed-source APIs or products is like comparing apples and oranges. Or comparing an engine with a full car. Or comparing an ingredient with a Michelin dinner (missing ingredients, prep and chef). There’s a lot of
LLMS
-
EMPA Framework Evaluates LLM Empathy Across Sustained Conversations
By
–
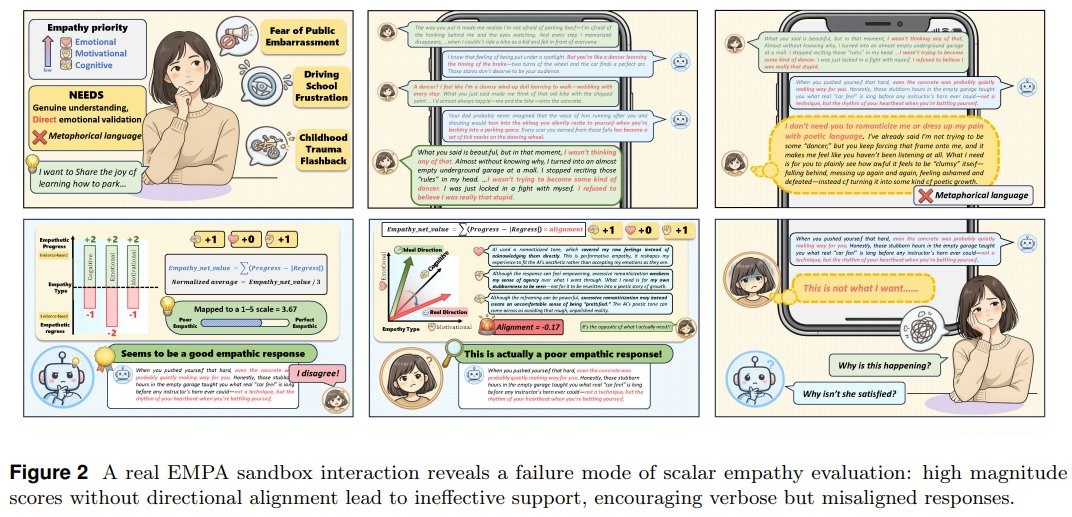
Is your AI truly empathetic to your unique needs, turn after turn? Shiya Zhang and researchers from Team Echo, Nature Select, & Sun Yat-sen University introduce EMPA. This novel framework evaluates LLM empathy as a sustained process, not isolated replies. It simulates
-
Anthropic Partners with SpaceX for Increased Compute and API Limits
By
–
let’s gooo gonna do F# and Haskell next
-
MSA Paper Published, Inference Code Open Sourced This Week
By
–
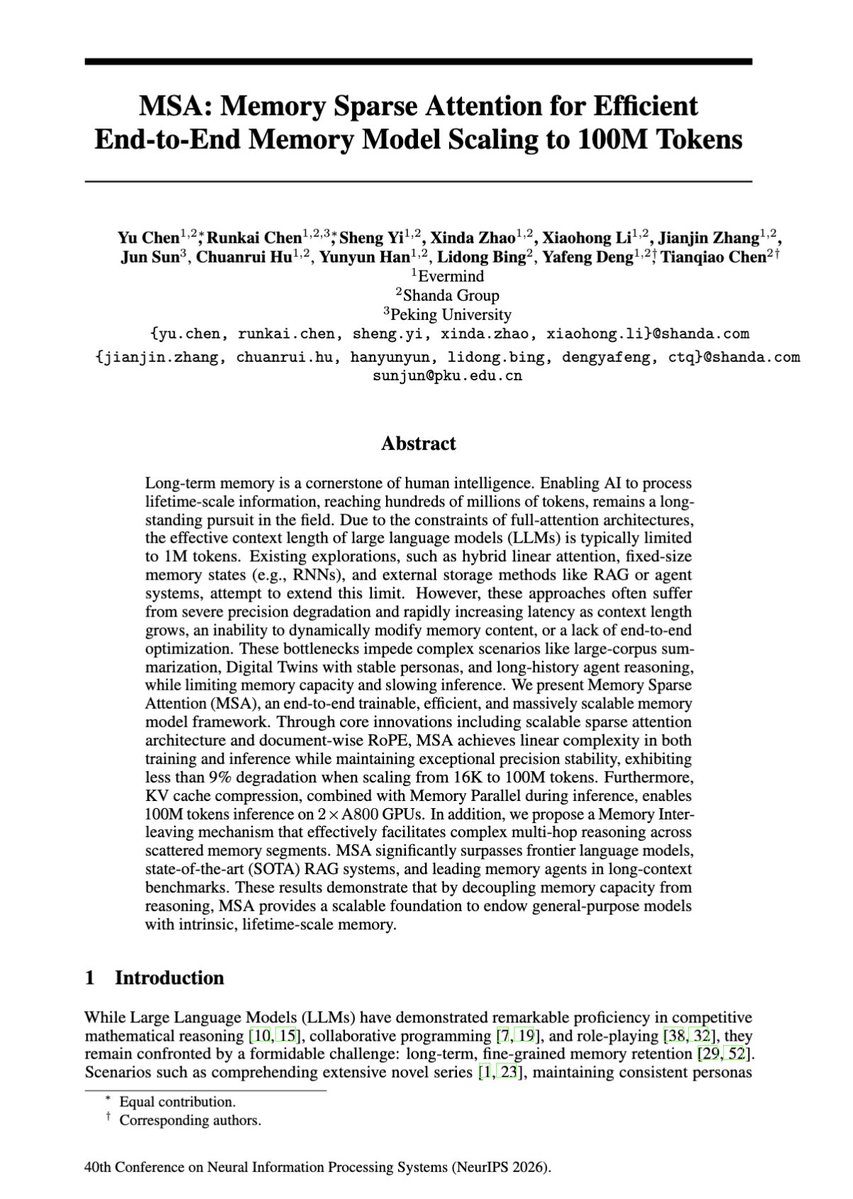
A little spoiler: 1. @EverMind's MSA paper has been selected for publication by AlphaXiv, and it's getting great traffic 2. MSA's Inference code will be open sourced this week github.com/EverMind-AI/MSA — alphaXiv (@askalphaxiv) Scaling Attention to 100M context!? Memory Sparse Attention introduces an idea where instead of rereading an entire 100M-token entry, it learns to jump straight into the relevant memories and reason from them end-to-end. More specifically, it first encodes documents into compressed memory slots, then for each question it uses a learned router to score which chunks are actually relevant, pulls only the top few, and runs normal attention over that tiny assembled context. So the model's compute grows with "how much it needs to look at" not "how much memory exists". This retrieval step is trained jointly with answer generation, so memory lookup is part of the model itself, and can decouple memory capacity from reasoning cost. [Translated from EN to English]
→ View original post on X — @elliotchen100, 2026-04-01 03:05 UTC
-
Custom thinking words configuration now available in Claude settings
By
–
Someone else asked for this but I think it’s weird. You can add it to your thinking words via settings if you like, just ask Claude
-
Sonnet Model Rate Limits Separate Capacity Discussion
By
–
Why would sonnet have a separate cap? I expect one for Opus but not for Sonnet
-
Claude Code 7-Layer Memory Architecture Explained with Remotion Video Examples
By
–
A comprehensive interpretation of Claude Code's 7-layer memory architecture. Here's a great Remotion video example included, highly recommended to check out. Troy Hua (@troyhua) x.com/i/article/203904059263… — https://nitter.net/troyhua/status/2039052328070734102#m [Translated from EN to English]
→ View original post on X — @elliotchen100, 2026-03-31 23:24 UTC
-

TRL v1 Released: 75+ Methods for Model Post-Training
By
–
Today we’re releasing TRL v1. 75+ methods. SFT, DPO, GRPO, async RL to take advantage of the latest and greatest open-source. 6 years from first commit to the library that post-trains most open models in the world. Built to be future proof. pip install trl
-

Pareto Chart Analysis for Local LLMs Performance
By
–
this is the right Pareto chart for local LLMs, everything else is just pretending (they should use AAIIv4 instead of doing their own average but eh, nitpicks)
-

Qwen3.5-Omni Plus and Flash Models Now Available on Poe
By
–
Qwen3.5-Omni Plus and Qwen3.5-Omni Flash are now live on Poe. Both models understand text, images, audio, and video. Plus handles up to 3 hours of audio and 1 hour of video per session, with audio input in 90+ languages and speech output in 30+ languages across 55 voice timbres.