AI Dynamics

Global AI News Aggregator

About

LLMS

  • Milla Jovovich and Ben Sigman Launch MemPalace AI Memory System
    Milla Jovovich and Ben Sigman Launch MemPalace AI Memory System

    Well, well, well, Milla Jovovich @MillaJovovich launching an AI memory system with Claude was not on my 2026 list, nor was almost everything else delivered this year. What a time… Here's my official invite for Ben and Milla to join the M.A.U. podcast. Ben Sigman (@bensig) My friend Milla Jovovich and I spent months creating an AI memory system with Claude. It just posted a perfect score on the standard benchmark – beating every product in the space, free or paid. It's called MemPalace, and it works nothing like anything else out there. Instead of sending your data to a background agent in the cloud, it mines your conversations locally and organizes them into a palace – a structured architecture with wings, halls, and rooms that mirrors how human memory actually works. Here is what that gets you: → Your AI knows who you are before you type a single word – family, projects, preferences, loaded in ~120 tokens → Palace architecture organizes memories by domain and type – not a flat list of facts, a navigable structure → Semantic search across months of conversations finds the answer in position 1 or 2 → AAAK compression fits your entire life context into 120 tokens – 30x lossless compression any LLM reads natively → Contradiction detection catches wrong names, wrong pronouns, wrong ages before you ever see them The benchmarks: 100% recall on LongMemEval — first perfect score ever recorded. 500/500 questions. Every question type at 100%. 92.9% on ConvoMem — more than 2x Mem0's score. 100% on LoCoMo — every multi-hop reasoning category, including temporal inference which stumps most systems. No API key. No cloud. No subscription. One dependency. Runs on your machine. Your memories never leave. MIT License. 100% Open Source. github.com/milla-jovovich/me… — https://nitter.net/bensig/status/2041236952998171118#m

    → View original post on X — @scobleizer, 2026-04-07 00:43 UTC

  • 8 Types of AI Agents You Should Know
    8 Types of AI Agents You Should Know

    8 Types of #AIAgents You Should Know by @PythonPr #LLM #ArtificialIntelligence #ML #MachineLearning

    → View original post on X — @ronald_vanloon, 2026-04-07 00:20 UTC

  • Anthropic’s Revenue Surges to $30B in 15 Months
    Anthropic’s Revenue Surges to $30B in 15 Months

    $1B to $30B in 15 months 🤯 Anthropic (@AnthropicAI) Our run-rate revenue has surpassed $30 billion, up from $9 billion at the end of 2025, as demand for Claude continues to accelerate. This partnership gives us the compute to keep pace. Read more: anthropic.com/news/google-br… — https://nitter.net/AnthropicAI/status/2041275563466502560#m

    → View original post on X — @ceobillionaire, 2026-04-07 00:17 UTC

  • pneuma-skills:AI与用户实时协作的智能创意工具
    pneuma-skills:AI与用户实时协作的智能创意工具

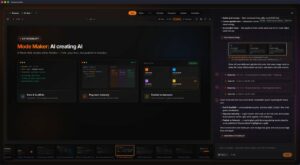
    诸位都知道 @evermind 是 @shanda_group 系的吧,盛大下面好几个 AI Native 公司,这不来自 @TankaChat 的 bro 写了一个开源项目,觉得思路特别好,给大家科普一下。 先说一个你可能有过的体验: 你用 Claude Code 说"帮我做个网页",AI 在终端里哗哗改代码,改完了你得自己开浏览器、找到文件、刷新页面才能看效果。觉得按钮颜色不对?切回终端,打字说"第二行那个蓝色按钮改成绿色",AI 可能还不确定你说的是哪个按钮。改完再切回去刷新看。 整个过程就是:说 → 等 → 切 → 看 → 切回来 → 再说。来回跳,而且你用文字描述视觉问题本身就很不精确。 pneuma-skills 这个项目的做法是,把 AI 的工作区和你的预览区塞进同一个界面。AI 每改一行代码,你这边实时看到渲染结果。你觉得哪里不对,鼠标选中那个元素,AI 立刻知道你在说什么。 你可以理解成:你和 AI 在同一个 Google Docs 里协作,只不过 AI 负责写代码,你看到的是实时渲染出来的成品。 而且它不只能做一种东西。它内置了 8 个模式:网页设计、幻灯片、Markdown 文档、Excalidraw 手绘白板、draw.io 流程图、AI 插画,甚至还有一个"模式创建器"让你自己定义新的内容类型。 最让我觉得有意思的是两点: 一是它会记住你的审美偏好。你喜欢圆角、暗色系、大间距,用几次之后它就知道了,下次不用再说。这个偏好跨 session 持久化,换个项目也还在。 二是它有个叫 Evolution Agent 的东西,会分析你过去的操作,自动优化它自己的技能模板。意思是这个系统不是静态的,是会跟着你一起长的。 底层架构上,它抽象了三层契约,agent 后端是可插拔的,目前支持 Claude Code 和 OpenAI Codex。 我觉得这个项目指向了一个很重要的方向:AI 工具的下一个瓶颈不在模型能力,在交互界面。你和 AI 之间的沟通带宽越大,协作效率就越高。 这个项目盛大内部用了都觉得不错,推荐给诸位。 Ez Chan (@EzPandazki) 我本来觉得,做 PPT 应该早就每个人都有自己一套了。没想到这玩意儿好评度这么高~ 没什么好介绍的,反正 cc 天下无敌。如果有 cc 订阅(codex 也支持但是没测试过)的同学,评论自取吧。 — https://nitter.net/EzPandazki/status/2041184491490963550#m

    → View original post on X — @elliotchen100, 2026-04-06 23:41 UTC

  • Open-Source Models Dominate: 75-80% Performance at 10x Lower Cost

    The biggest winners of last week were open-source and cheaper models MiniMax 2.7 Qwen 3.6 GLM 5 – Kimi 2.5 Usage is going exponentially up on…. you get about 75-80% performance as the closed models that are 10x more expensive

    → View original post on X — @clementdelangue, 2026-04-06 23:36 UTC

  • Reasoning Reduces AI Hallucinations: Data Analysis

    I don’t doubt that reasoning has reduced hallucinations but you are putting words in my mouth and ignoring the data 4.6% is not an upper bound, coming from a known benchmark. i am sure under some circumstances the number will prove to be higher.

    → View original post on X — @garymarcus

  • Neural Network Expert Disputes AI Model Hallucination Claims

    I am blocking you unless you retract this. I have been working on neural networks for 30 years. A recent survey showed my technical predictions have been over 90% correct. Your own data (ie the data that you pointed) supported my claim that current models still hallucinate.

    → View original post on X — @garymarcus

  • VoxCPM 2: Revolutionary Open-Source Text-to-Speech Model Released

    Loved collaborating with @OpenBMB on this. ♻️ Show some love with a repost if you enjoyed the content. Supporting small teams is how we build the future 🤗 Stay ahead with daily drops on LLMs, agents, and workflows by following me → @datachaz Charly Wargnier (@DataChaz) 🚨 The new era of Open-Source TTS is here. @OpenBMB's VoxCPM 2 just dropped and it changes the game for voice synthesis. We are moving past fixed speaker presets to true "Concept-to-Voice" generation. Just describe the voice you want in text, and the 2B model builds it. How does it beat discrete token-based models like Qwen3-TTS? VoxCPM 2 uses a cutting-edge Diffusion-Autoregressive Continuous Representation framework. → Eliminates discrete token data loss → Preserves raw acoustic metadata → Outputs natively in 48,000Hz CD-quality audio The studio-grade expressiveness is phenomenal. I gave it a specific text prompt: "Deep booming male voice, strong resonant vocal, rhythmic hype pace." It dynamically calculates natural breathing, chest vibrations, and micro-pauses. It actually performs the text naturally. Best of all, the entire stack is fully open-source and highly developer-friendly. → Native PyTorch inference workflows → LoRA and full-parameter fine-tuning → Compatible with voxcpm-nanovllm Repo and demos links in 🧵↓ — https://nitter.net/DataChaz/status/2041289800695873546#m

    → View original post on X — @datachaz, 2026-04-06 22:59 UTC

  • VoxCPM2: Model Weights Available on Hugging Face

    3/ Model Weights: https://huggingface.openbmb.com/model/openbmb/VoxCPM2 [Translated from EN to English]

    → View original post on X — @datachaz, 2026-04-06 22:59 UTC

  • VoxCPM: GitHub Repository and Project Resources

    2/ GitHub Repo: github.com/OpenBMB/VoxCPM/ [Translated from EN to English]

    → View original post on X — @datachaz, 2026-04-06 22:59 UTC