I spent a lot of time to support self hosted models, lm studio, we even have a maintainer from @ollama on the team. I love all the progress local models make!
LLMS
-
Open-source LLM frameworks accelerate on NVIDIA platform
By
–
Open-source software never stops. It only accelerates.
— NVIDIA (@nvidia) 8 avril 2026
Dynamo, @sgl_project, TensorRT LLM, and @vllm_project are constantly optimized by a vast ecosystem of developers building on top of the NVIDIA platform.
The result: your token output keeps improving and token cost keeps… pic.twitter.com/DB1ND736ugOpen-source software never stops. It only accelerates. Dynamo, @sgl_project, TensorRT LLM, and @vllm_project are constantly optimized by a vast ecosystem of developers building on top of the NVIDIA platform. The result: your token output keeps improving and token cost keeps decreasing on the same hardware resources while your developer velocity stays at its peak. Build on the foundation continuously optimized by the world’s best developers. ⚡ 🔗 nvda.ws/3OsTQL0
-
TriAttention: Efficient Long Reasoning with Trigonometric KV Compression
By
–
“TriAttention: Efficient Long Reasoning with Trigonometric KV Compression”
— alphaXiv (@askalphaxiv) 8 avril 2026
Most KV-cache compression methods guess what to keep by looking at recent attention.
But this paper argues that the signal is unstable because RoPE keeps rotating queries with position, so what looks… pic.twitter.com/GrEYc0gZ2b“TriAttention: Efficient Long Reasoning with Trigonometric KV Compression” Most KV-cache compression methods guess what to keep by looking at recent attention. But this paper argues that the signal is unstable because RoPE keeps rotating queries with position, so what looks unimportant now may matter later. So they proposed TriAttention, which looks in the pre-RoPE space and finds that many heads have stable Q/K centers. That lets it predict which token distances a head is likely to retrieve, and compress the KV cache using that structure rather than noisy recent attention. This shift from "keeping what was attended recently” to “keeping what this head is likely to need later” Empirically, it matches full attention on AIME25 with 2.5x higher throughput or 10.7x less KV memory.
-
AIMock: Universal Mock Server for AI Agent Stack
By
–
✨ Introducing AIMock – one mock server for your entire agentic stack!
— CopilotKit🪁 (@CopilotKit) 8 avril 2026
Your AI app calls LLMs, MCP tools, A2A agents, vector DBs, search, reranking, and moderation. If any of those are live in your tests, you've got flaky CI and burned tokens.
No tool mocked all of it. So we… pic.twitter.com/4k3fYPtQr5✨ Introducing AIMock – one mock server for your entire agentic stack! Your AI app calls LLMs, MCP tools, A2A agents, vector DBs, search, reranking, and moderation. If any of those are live in your tests, you've got flaky CI and burned tokens. No tool mocked all of it. So we built one. One package. One port. Plus drift detection and record & replay that nobody else ships. Zero dependencies. Open source. Mock with one command: `pnpm add @copilotkit/aimock`
→ View original post on X — @scobleizer, 2026-04-08 17:27 UTC
-
EvoKernel: Self-Evolving AI Agent for NPU Code
By
–
How can LLMs code for cutting-edge hardware when there's almost no training data?
— 机器之心 JIQIZHIXIN (@jiqizhixin) 8 avril 2026
Researchers from Shanghai Jiao Tong University, Shanghai AI Lab, and MemTensor present EvoKernel!
This self-evolving AI agent teaches LLMs to write code for new, data-scarce hardware. It uses a… pic.twitter.com/dHIJZlxYTdHow can LLMs code for cutting-edge hardware when there's almost no training data? Researchers from Shanghai Jiao Tong University, Shanghai AI Lab, and MemTensor present EvoKernel! This self-evolving AI agent teaches LLMs to write code for new, data-scarce hardware. It uses a clever memory system to prioritize and learn from the most valuable coding experiences, continually refining its drafts. EvoKernel boosts code correctness for NPU kernel synthesis from a mere 11% to an impressive 83% and speeds up programs by 3.6x over initial drafts! Towards Cold-Start Drafting and Continual Refining: A Value-Driven Memory Approach with Application to NPU Kernel Synthesis Project: evokernel.zhuo.li Paper: arxiv.org/abs/2603.10846 Our report: mp.weixin.qq.com/s/0TOzZ_rZn… 📬 #PapersAccepted by Jiqizhixin
-
LLM Visual Understanding Enhancements for Edge Detection and Sizing
By
–
LLM plus visual understanding, but yeah. For context, you could do this before, but models tended to be very off with edge detection and sizes.
-
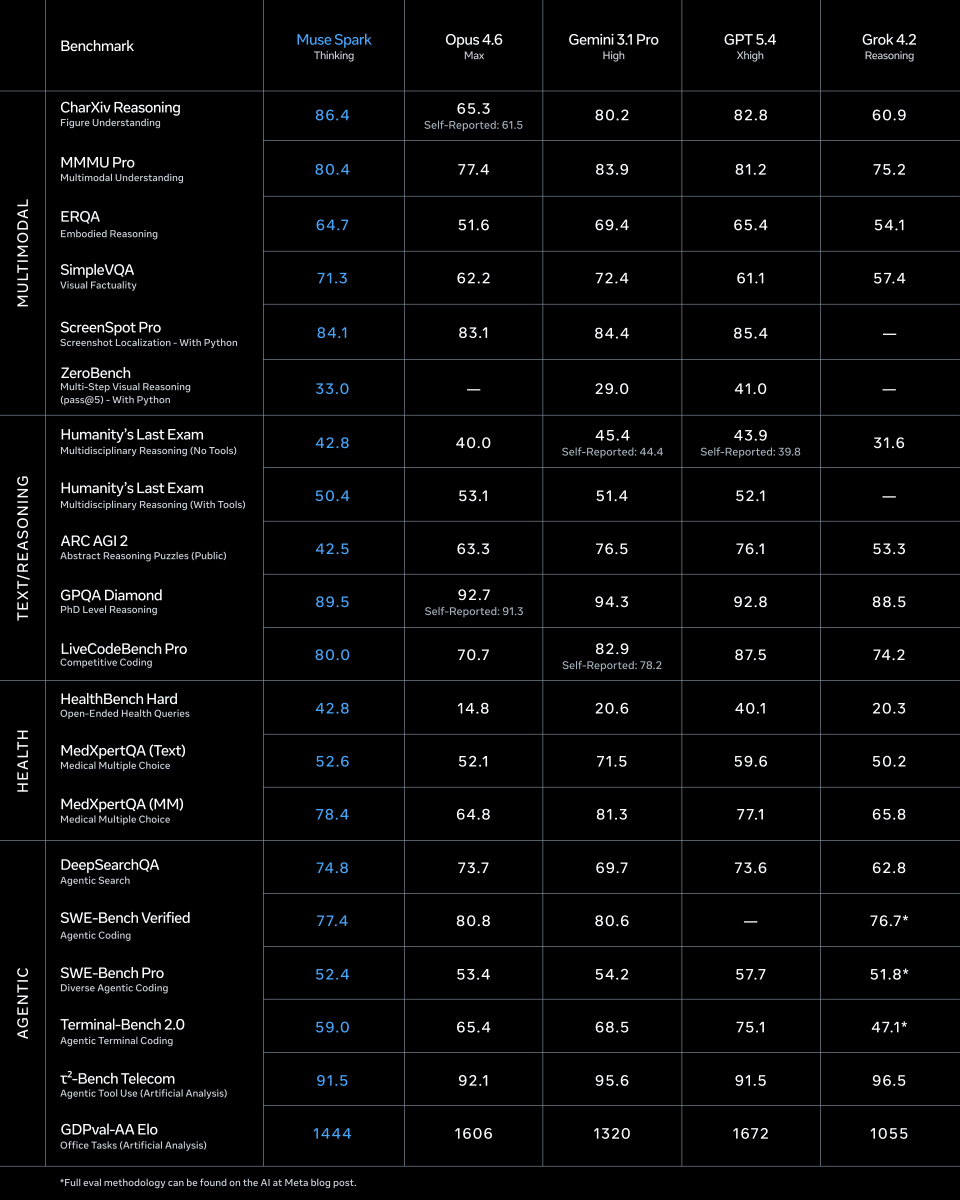
Nine Months of Building: Muse Spark Model Launch Success
By
–
Fun nine months! My first week i remember we had a long dinner in the cafeteria daydreaming about the cool research directions to pursue, then going to back to our desks to write a basic script to inference llama. Now we have a pretty complete stack and our first model is out 🥑 Alexandr Wang (@alexandr_wang) 1/ today we're releasing muse spark, the first model from MSL. nine months ago we rebuilt our ai stack from scratch. new infrastructure, new architecture, new data pipelines. muse spark is the result of that work, and now it powers meta ai. 🧵 — https://nitter.net/alexandr_wang/status/2041909376508985381#m
→ View original post on X — @_jasonwei, 2026-04-08 17:25 UTC
-

Build AI Agents from Scratch: 9-Step Roadmap for Production
By
–
How to build AI agents from scratch (9 steps): 1. Purpose & scope 2. I/O schemas 3. System instructions 4. Reasoning + tools 5. Multi-agent orchestration 6. Memory & context 7. Multimodal 8. Structured outputs 9. UI / API Ship agents that do work, not just talk. 🤖⚡️ Where are you on this roadmap? Credit: @getintoai #AIAgents #AgenticAI #GenAI #LLM
→ View original post on X — @ingliguori, 2026-04-08 17:25 UTC
-
Free Mastery Guides for Gemini, Claude, and OpenAI
By
–
I should charge $99 for each of these.
But every single guide on this page is free. → Gemini Mastery Guide
→ Prompt Engineering Guide
→ Claude Mastery Guide
→ OpenAI Mastery Guide
→ + more dropping & updating regularly Zero cost. Zero catch. Just open and learn -
Using AI to Build a Bitcoin Portfolio Tracking System
By
–
4/ TRACK YOUR BITCOIN PORTFOLIO Prompt: Act as a Bitcoin portfolio analyst who tracks performance, calculates real returns, and keeps emotion out of long-term holding decisions. Build a complete Bitcoin portfolio tracking system that shows my real returns,