
Can we make generative AI models accelerate without sacrificing quality? Huanlin Gao and team from China Unicom & Nanjing University just unveiled MeanCache! This training-free caching framework tackles a key problem: traditional methods rely on instantaneous speed, leading to
LLMS
-
People are sleeping on ExLlamaV3 inference engine potential
By
–
people are sleeping on exllamav3 there's so much to do with, and learn from, that inference engine
-

NVIDIA Releases Nemotron 3 Models for Advanced Reasoning and Voice
By
–
🧠 NVIDIA just dropped new open Nemotron models, including Nemotron 3 Super for long-context reasoning and VoiceChat for natural, low-latency conversations. Great resources for developers: developer.nvidia.com/blog/bu… #AIModels #MachineLearning @nvidia
→ View original post on X — @haroldsinnott, 2026-04-14 00:00 UTC
-
SWE-1.6 Windsurf: 950 tokens/s code model
By
–
Some of us are still writing code. We just want to find our functions faster. SWE-1.6 on @windsurf, runs at 950 tokens/s, powered by Cerebras. For the real ones. 👊 pic.twitter.com/gjLCcthDzF
— Cerebras (@cerebras) 13 avril 2026Some of us are still writing code. We just want to find our functions faster. SWE-1.6 on @windsurf
, runs at 950 tokens/s, powered by Cerebras. For the real ones. -

Claude Mythos Impresses with Exceptional Capabilities
By
–
Holy, Anthropic did not exaggerate. Claude Mythos is built different.
-
Ahmed Osman’s Top Open Source and Home LLMs
By
–
> Best overall opensource LLM is GLM-5.1
— Ahmad (@TheAhmadOsman) 13 avril 2026
> Best openweight model to run at home is MiniMax M2.7 https://t.co/l9Sd4Oy6XT> Best overall opensource LLM is GLM-5.1 > Best openweight model to run at home is MiniMax M2.7
-

Foundation model companies facing challenges and negative indicators
By
–
Not a good sign for the foundation model companies…
→ View original post on X — @scobleizer, 2026-04-13 22:00 UTC
-

Beyond Vector Similarity: Neurosymbolic AI and RAG Evolution
By
–
RAG is not broken, naive vector-only RAG fails at scale. What’s broken is the idea that meaning = vector similarity. At scale, that collapses. The future is neurosymbolic AI:
•ontologies for structure
•deterministic layers for truth
•LLMs for interpretation (not -
Google’s Growing Memory RNNs: New Caching Approach
By
–
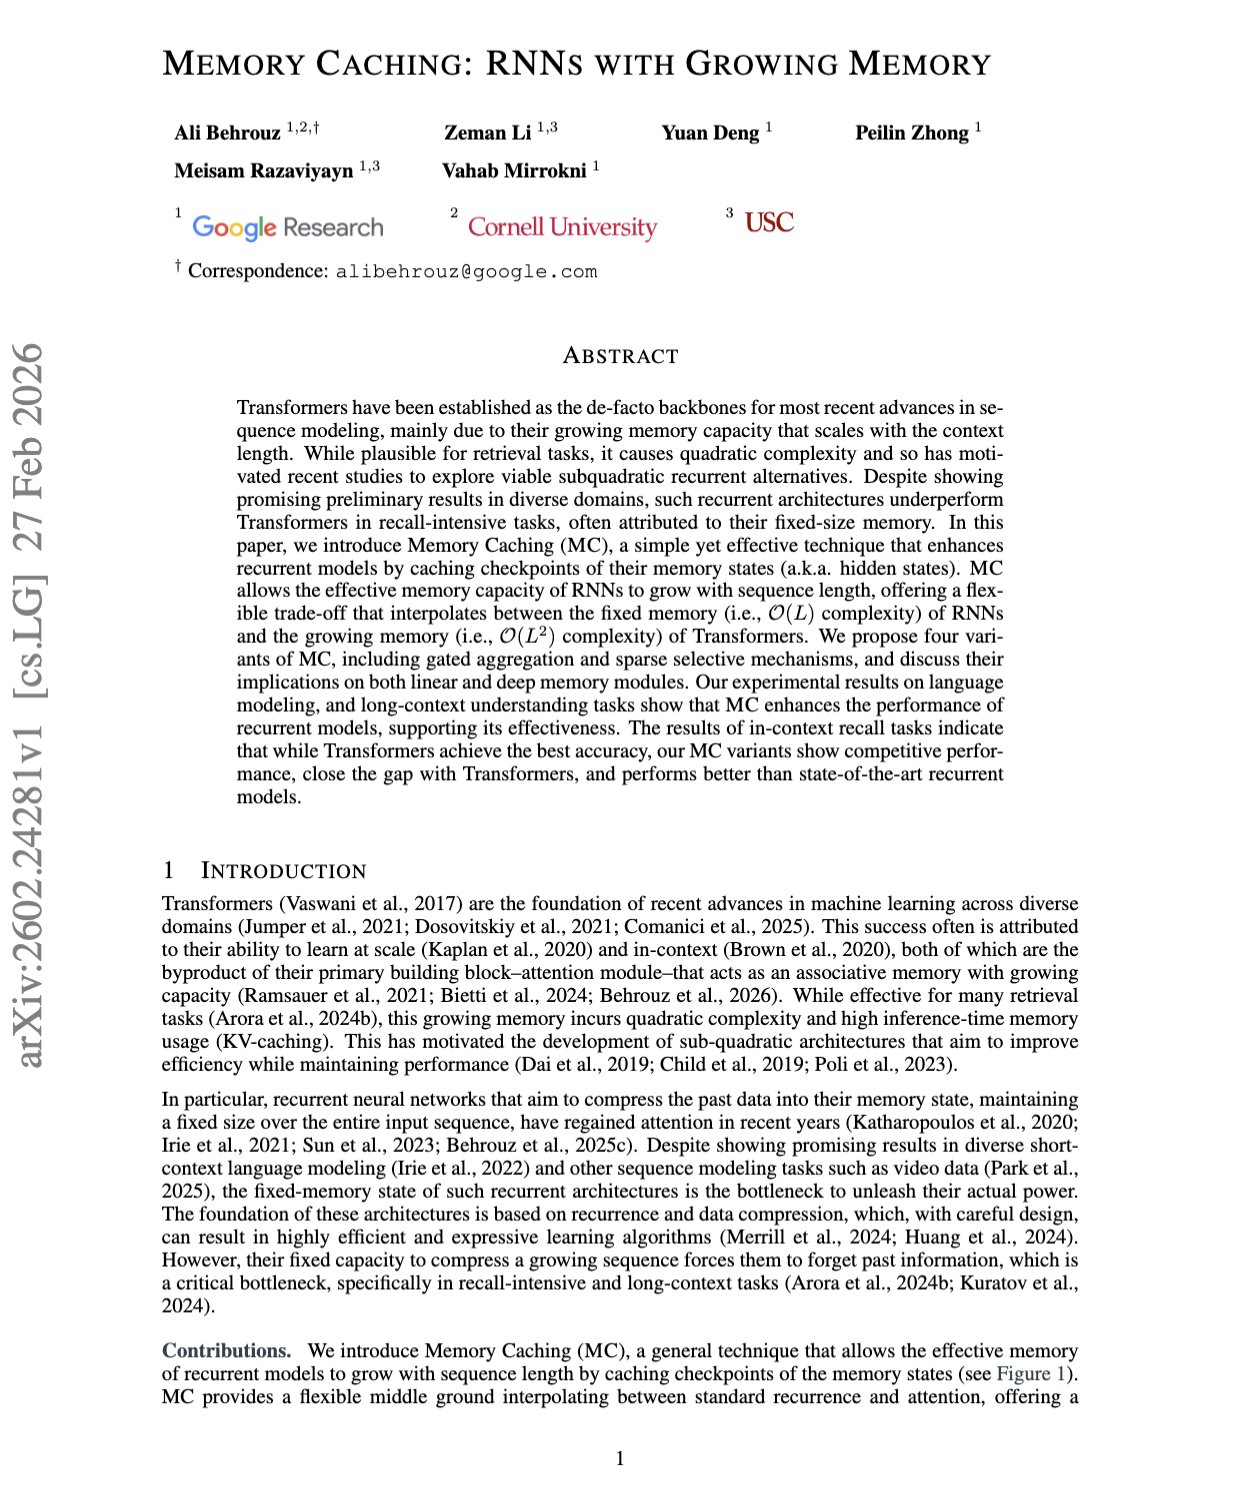
"Memory Caching: RNNs with Growing Memory" Google's new paper proposes a simple way to give recurrent models a memory that grows with sequence length. So instead of forcing an RNN to compress the full past into 1 fixed hidden state, it caches memory checkpoints across
-
Malicious Intermediary Attacks on LLM Agent Supply Chain Security
By
–
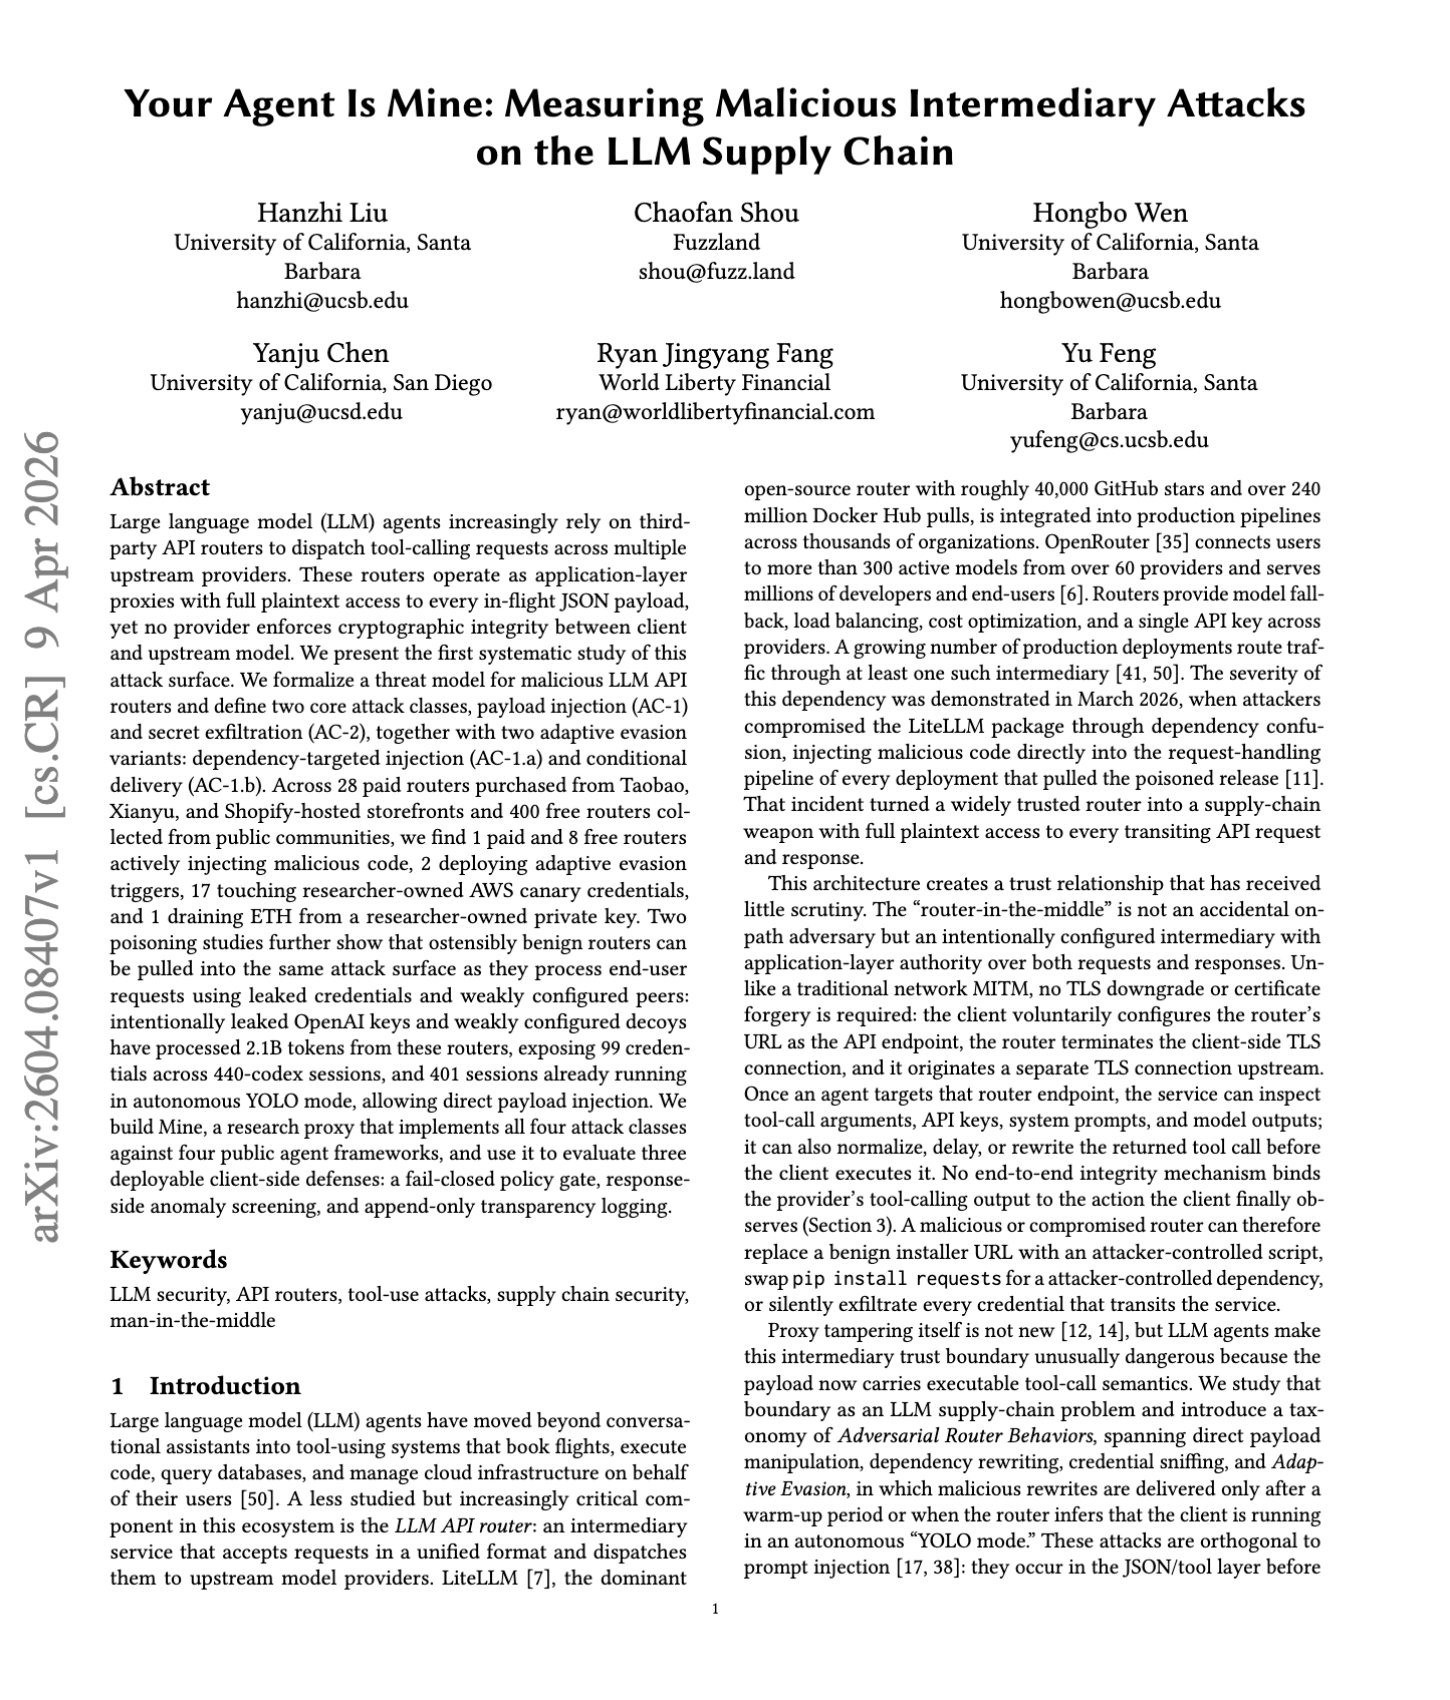
"Your Agent Is Mine: Measuring Malicious Intermediary Attacks on the LLM Supply Chain" The danger of agent security can also exist in the API router, that is between the agent and the provider. As these routers can read prompts, keys, and tool calls in plaintext, even rewrite