Opus 4.7 Benchmarks out! Very solid upgrade to Opus 4.6! Compared to Opus 4.6: -SWE Bench Pro +11%
-SWE Bench Verified +7%
-Terminal Bench 2.0 +4% The benchmarks are significantly lower than for Mythos, but that was to be expected. h/t for finding @synthwavedd
LLMS
-

Opus 4.7 Benchmarks Show Solid Improvements Over Previous Version
By
–
-

Spring AI SDK for Amazon Bedrock AgentCore Launch
By
–
Spring AI SDK for Amazon Bedrock AgentCore! #BigData #Analytics #DataScience #AI #MachineLearning #NLProc #LLM #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode
-
LLM Catastrophic Forgetting in Reinforcement Learning Fine-Tuning
By
–
Is your LLM truly ready for reinforcement learning, or is it forgetting its roots? Xinran Li and team from HKUST, Alibaba, and Xiamen University discovered that standard supervised fine-tuning (SFT) often causes LLMs to 'forget' foundational knowledge, hindering subsequent
-

Alibaba Qwen3.6-35B-A3B Sparse MoE Model Released
By
–
Alibaba released Qwen3.6-35B-A3B today. Big jump compared to Qwen 3.5-35B model. It's a sparse MoE, 35B total params, only 3B active. Natively multimodal, thinking and non-thinking modes. Hardfacts:
SWE-bench Verified: 73.4, near dense Qwen3.5-27B (75.0), way ahead of -
MiniMax adds a new managed agent by Hermes
By
–
MiniMax added a new always-on managed agent, powered by Hermes, to its MiniMax Agent platform.
— 🚨 AI News | TestingCatalog (@testingcatalog) 16 avril 2026
Now users can operate 2 managed agents, each powered by a different project.
Imagine these 2 combined 👀
Openmes or Herclaw? https://t.co/gKWg1jIpfK pic.twitter.com/t1rzrv6zdhMiniMax added a new always-on managed agent, powered by Hermes, to its MiniMax Agent platform. Now users can operate 2 managed agents, each powered by a different project. Imagine these 2 combined Openmes or Herclaw?
-

Context Engineering: Why Quality Data Beats Volume for LLMs
By
–
Most teams think “more data = smarter AI.” I make the opposite case: context beats volume. When LLMs are grounded in your company’s own signals—not just the internet—they deliver accurate, explainable decisions at scale. A thread on Context Engineering and why it changes
-
Gemma 4 Colab: Reinforcement Learning Sudoku Game Guide
By
–
Gemma 4 Colab: https://
colab.research.google.com/github/unsloth
ai/notebooks/blob/main/nb/Gemma4_(E2B)_Reinforcement_Learning_Sudoku_Game.ipynb
… RL Guide: -
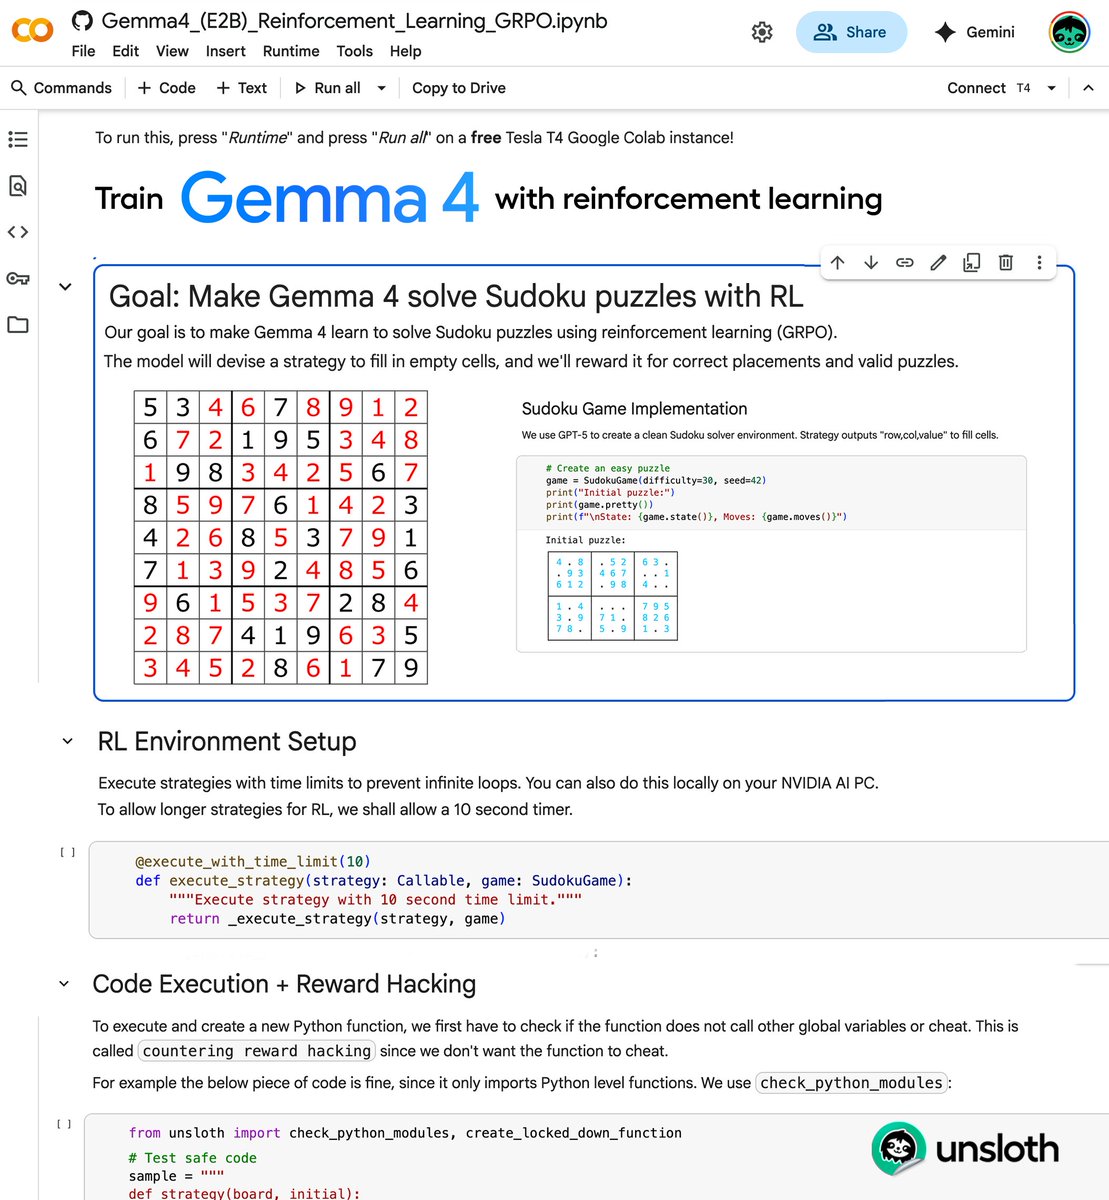
Unsloth Enables GRPO Training for Gemma 4 on Consumer GPUs
By
–
Train Gemma 4 with reinforcement learning! Unsloth just added GRPO support for Gemma 4. You can now RL fine-tune Google's latest model on a consumer GPU. The example notebook teaches Gemma 4 to solve Sudoku puzzles autonomously. The model learns through trial and error with
-

Gemini 3.1 Pro Leads METR Time Horizon Benchmark
By
–
New METR time horizon leader: Gemini 3.1 Pro. On METR's time horizon benchmark (80% success rate (!)), Google's Gemini 3.1 Pro now handles software tasks that take humans 1 hour 30 minutes on average. 95% CI ranges from 52 minutes up to 2 hours 39 minutes. Average score: 77%.
-
Recurrent Computation in Transformers: Long Context Benefits Analysis
By
–
Re-passing activations through the same layers sounds like recurrent computation stitched back in, curious if it still benefits from longer contexts the way dense transformers do.