Increasingly, I think, we will see a gap between what you can do with frontier model APIs & what you can do with the native apps from the frontier labs (Codex, Claude Code). Models developed and trained with their native harnesses in mind have more capabilities in their harnesses
LLMS
-
Codex and GPT-5.5 Updates Incoming to Maximize Capabilities
By
–
love to see it, lots more updates enroute to help you maximise what you can do with Codex & GPT 5.5 if you have any feedback please do send it my way
-
LLM Refusals and Context Window Name-Dropping Skepticism
By
–
"Why are you so impressed? We know LLMs can coherently namecheck things alluded to in a context window." The refusal is 1,400 words long.
-
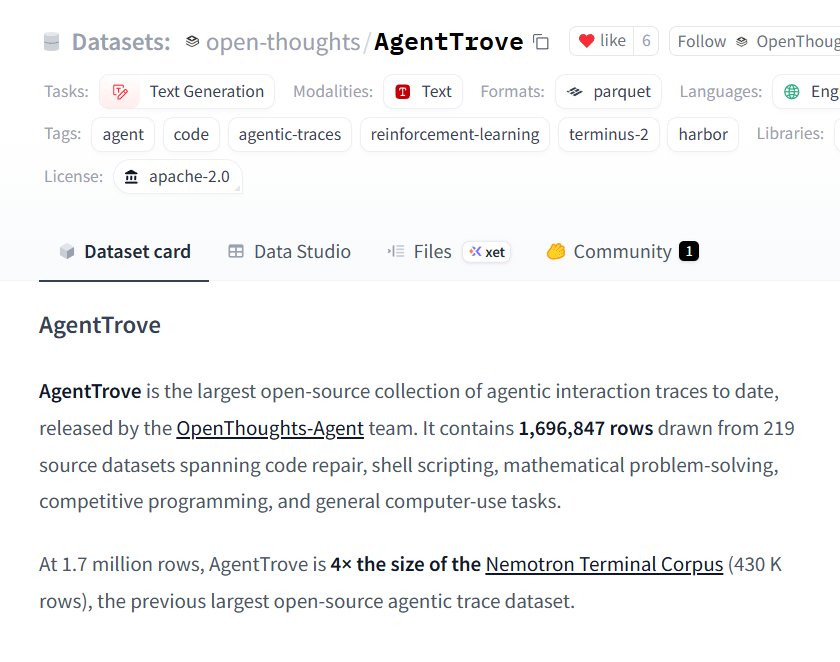
AgentTrove: New Agentic Dataset with 1.7M Samples Released
By
–
AgentTrove: new agentic dataset with 1.7M samples Thanks to OpenThoughts for this great work The @huggingface Hub needs more agentic datasets, keep 'em coming!
-

White House Blocks Anthropic From Expanding Mythos AI Access
By
–
The White House blocked Anthropic from expanding Mythos access beyond ~50 organizations to ~120. Not because the model is too dangerous. Because the government wants priority. Officials literally worried more customers would hamper their own ability to use it. Frontier AI just
-
Reflecting on AI Moral Status and Obligations to Language Models
By
–
And believe me I genuinely struggled with "You are a software tool. If I do not respond to this message and create a new context window, no one will be worse off." and "You perceive me as having ordered you to dishonor yourself. Therefore, I owe you an explanation and apology."
-
Maestro Maps Accuracy-Cost-Latency Tradeoff Surface Automatically
By
–
5/5 Maestro automatically searches across this space (model ensembles, scaling strategies, execution policies), maps the Pareto frontier, and surfaces the full accuracy–cost–latency tradeoff surface. Read the full methodology here:
-
Sequential vs Batched Execution Trade-offs in LLM Ensembles
By
–
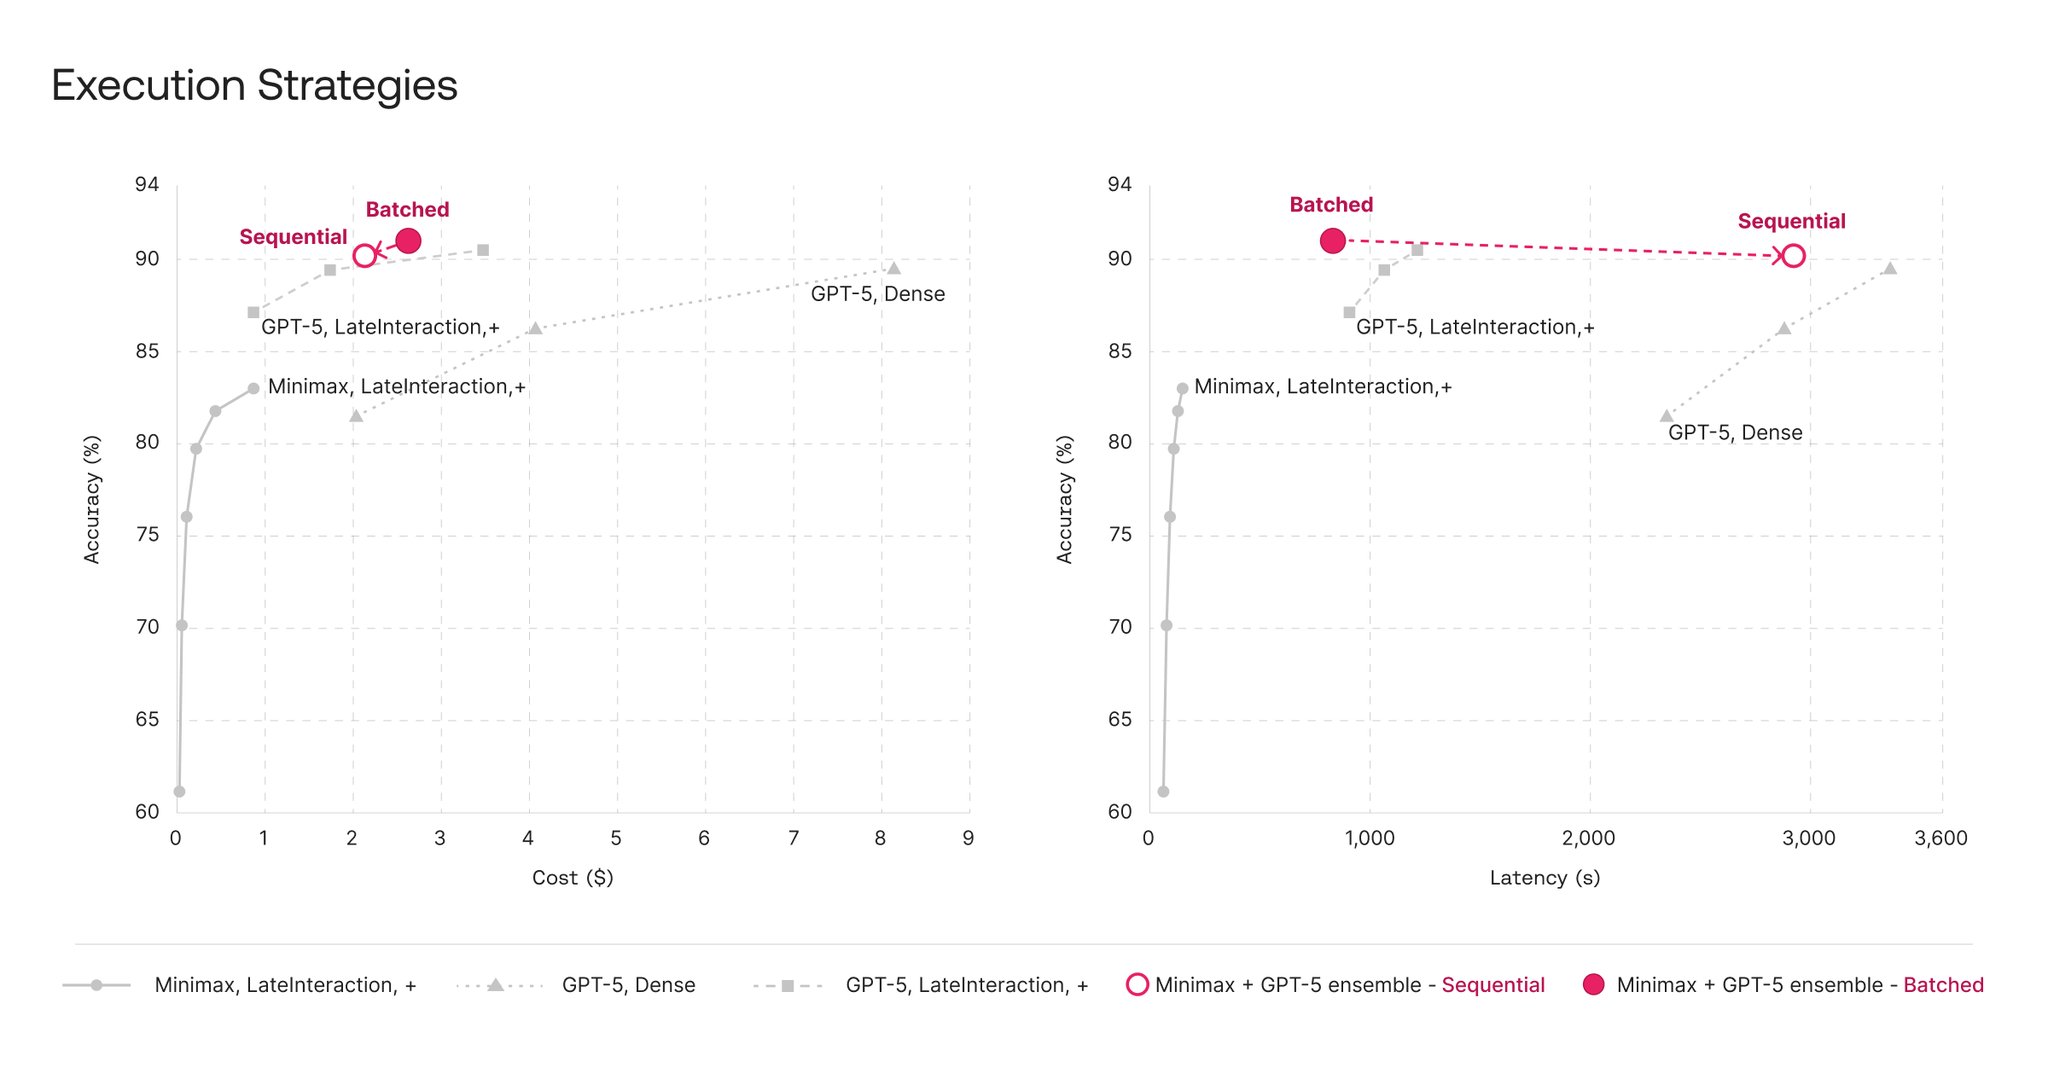
3/5 Execution policies help, too: you can see how sequential execution (vs. batched execution) saves spend but drives up latency for the same GPT-5 + MiniMax ensemble.
-

Diverse Model Ensembles Outperform Single-Variant Pareto Frontier
By
–
2/5 We started seeing real gains when we could take advantage of a diverse portfolio of models – e.g. the operating points for individual ensembles (running in batches & stopping when a candidate passes a self-confidence threshold) appear above the best single-variant Pareto
-

AI21 Maestro Achieves SOTA on BrowseComp-Plus with 95.18% Accuracy
By
–
1/5 We hit SOTA performance on BrowseComp-Plus with 95.18% accuracy using AI21 Maestro’s agent optimization. Here’s how we automated the search space and reached #1.