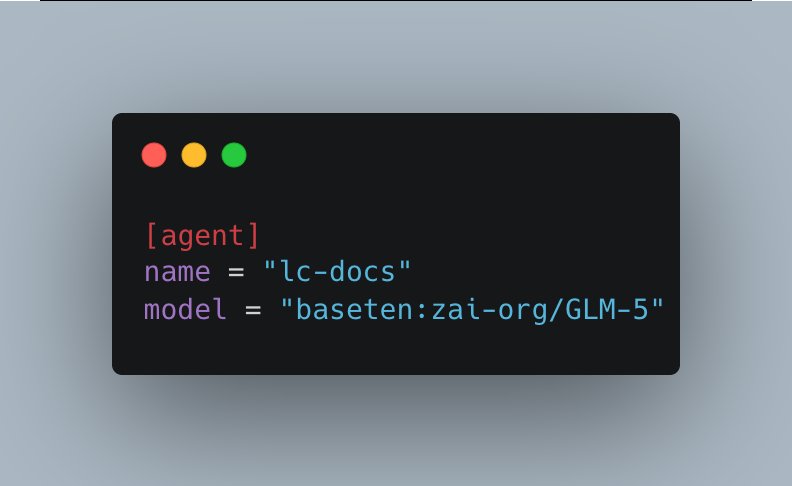
After switching into the new directory (`cd lc-docs`) I'm going to set the name of my agent, and the model to use This is done in deepagents.toml I'm going to use @Zai_org GLM5 model, served via @baseten
LLMS
-
Tandem Voice AI Architecture Enables Speaking While Thinking
By
–
For years, voice AI has been stuck in a rigid loop: think, then speak. But real human conversation is messy, overlapping, and asynchronous.
— hardmaru (@hardmaru) 29 avril 2026
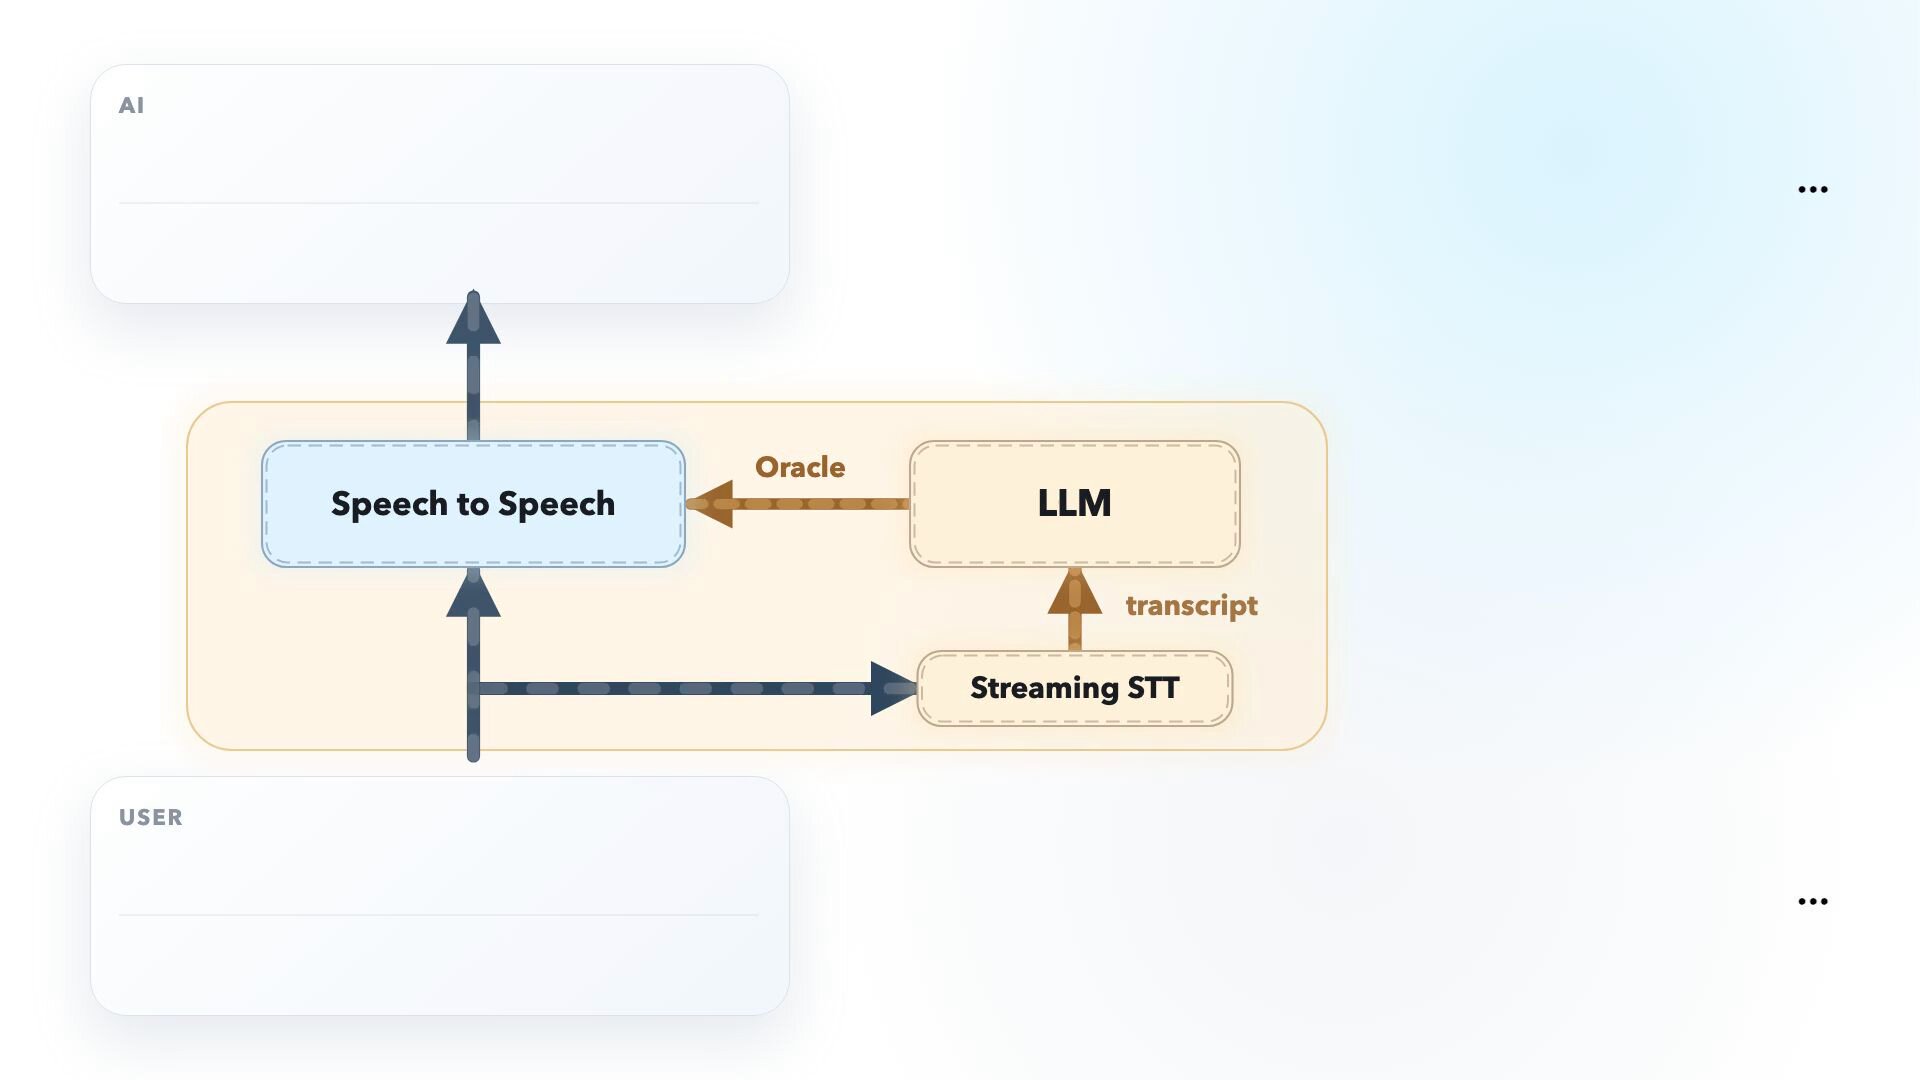
In our new #ICASSP2026 work, we built a tandem architecture that shifts the paradigm to “speak while thinking.” A fast speech model starts… https://t.co/gyRFlqDSUjFor years, voice AI has been stuck in a rigid loop: think, then speak. But real human conversation is messy, overlapping, and asynchronous. In our new #ICASSP2026 work, we built a tandem architecture that shifts the paradigm to “speak while thinking.” A fast speech model starts
-
Mistral Medium 3.5 positioning strategy among Asian LLM competitors
By
–
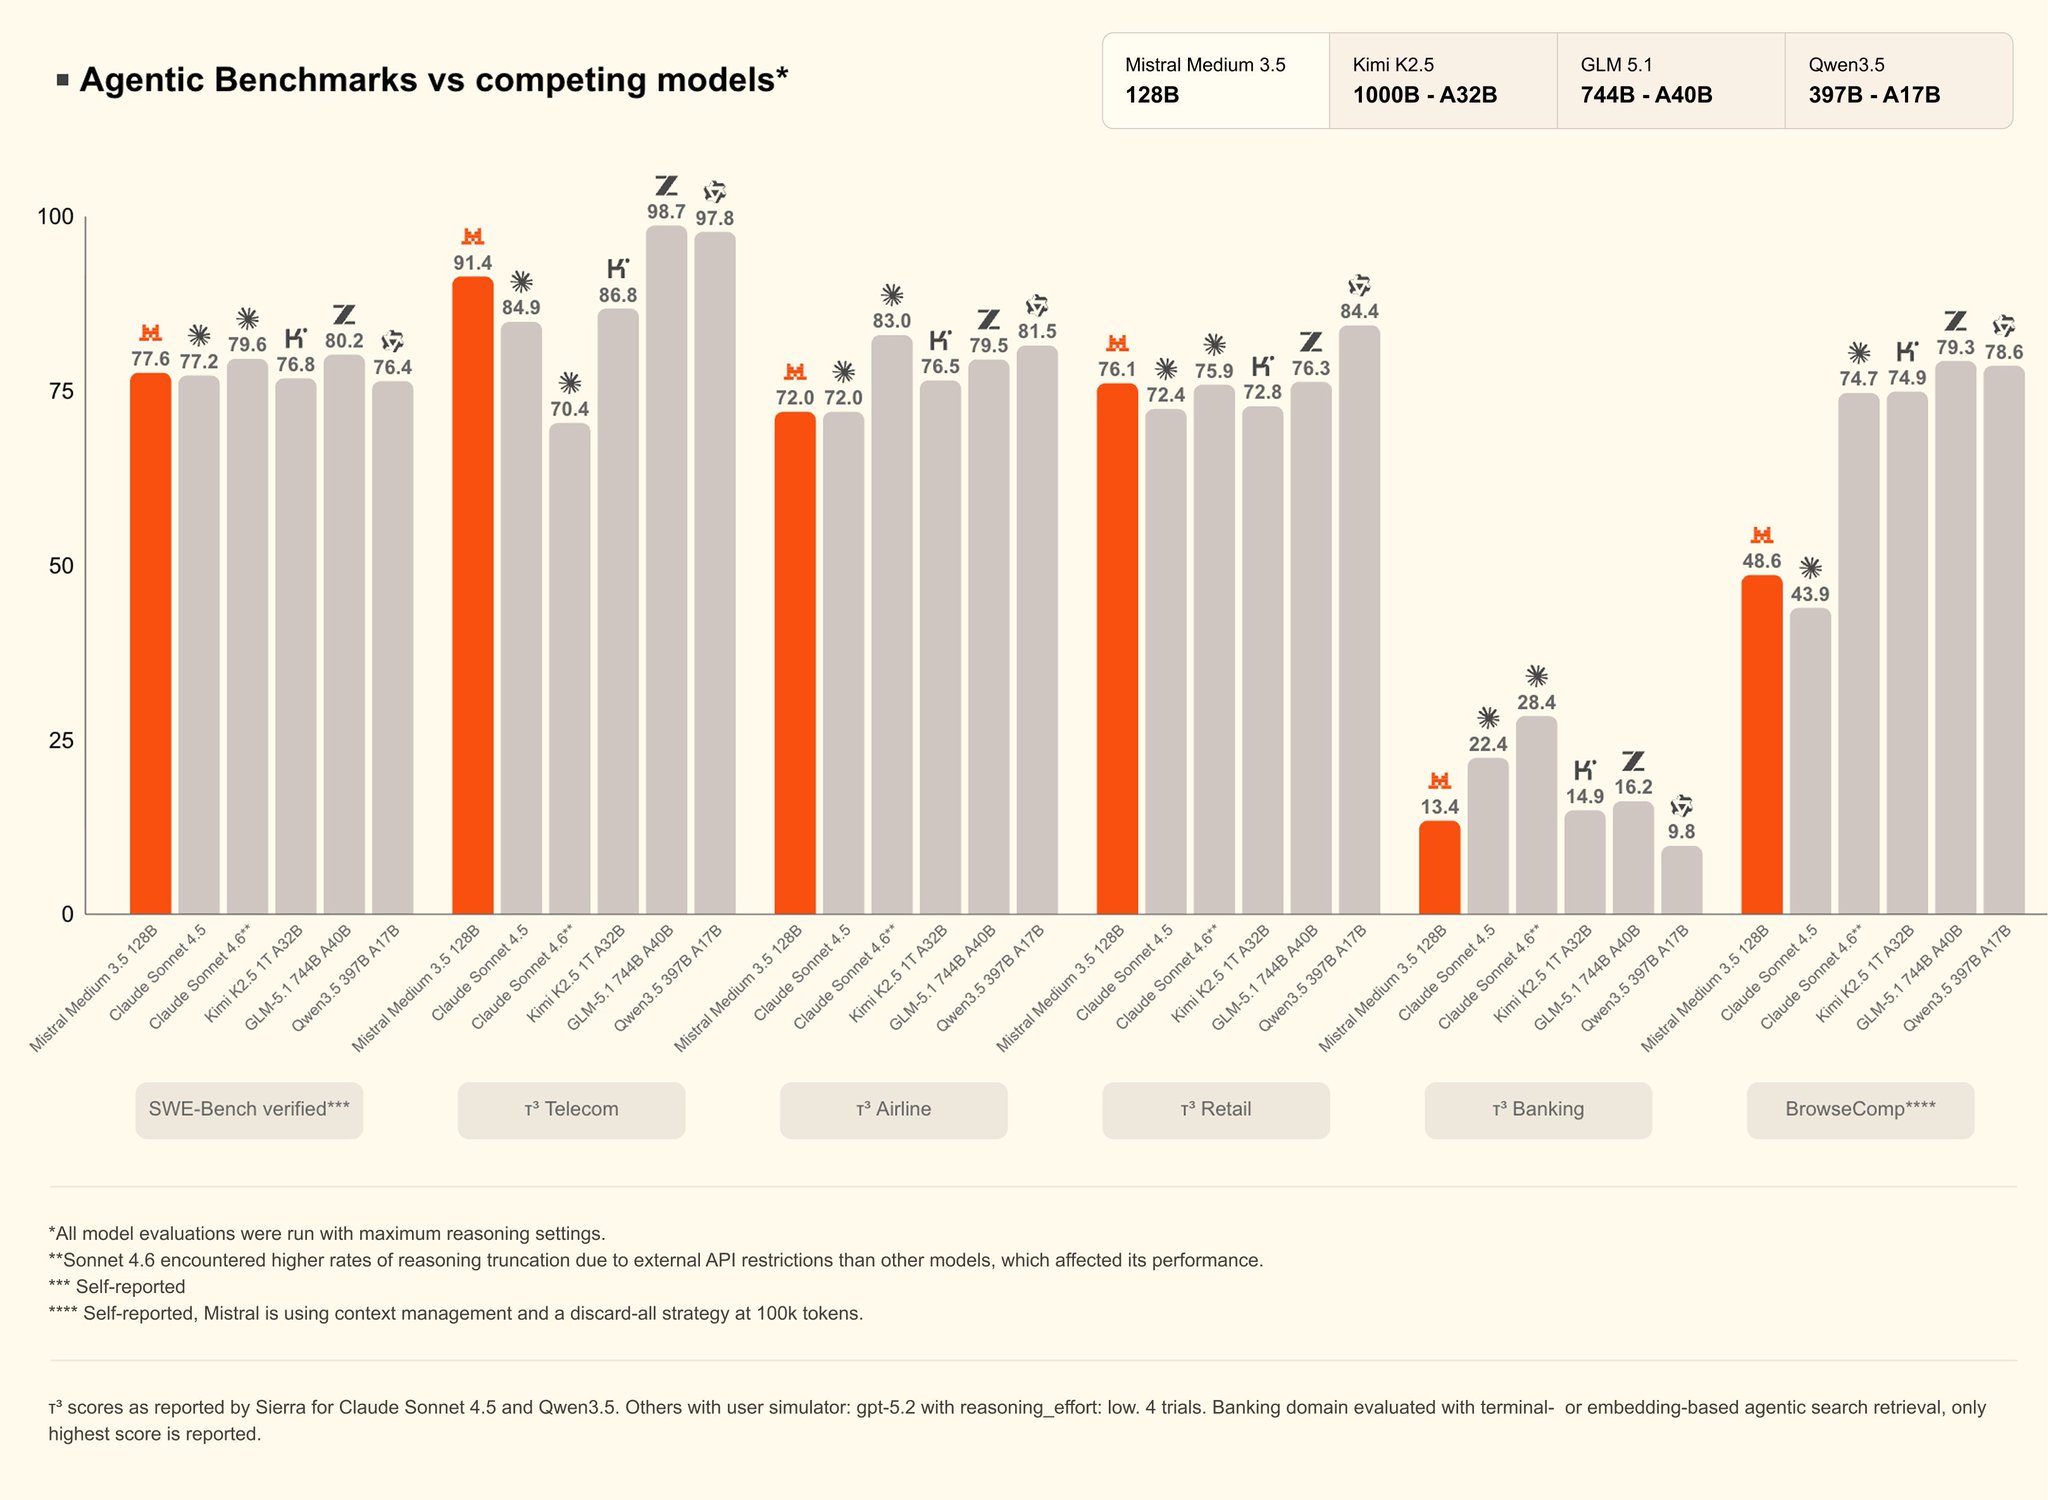
Mistral Medium 3.5 is interesting less for the benchmarks and more for the positioning. Look at who they're comparing against: Kimi, Qwen, GLM, Claude (Sonnet). Not GPT, not Gemini. And i dont mean that in a negative way! With Aleph Alpha being acquired by Cohere last week,
-
KAME: Real-Time Speech-to-Speech AI With Deep Thinking
By
–
We’re excited to introduce KAME: Tandem Architecture for Enhancing Knowledge in Real-Time Speech-to-Speech Conversational AI, accepted at #ICASSP2026! 🐢
— Sakana AI (@SakanaAILabs) 29 avril 2026
Blog https://t.co/eyU3yECBK8
Paper https://t.co/PVYPIcHyyM
Can a speech AI think deeply without pausing to process?
In real… pic.twitter.com/Ut0ypkjJWxWe’re excited to introduce KAME: Tandem Architecture for Enhancing Knowledge in Real-Time Speech-to-Speech Conversational AI, accepted at #ICASSP2026! Blog https://
pub.sakana.ai/kame/
Paper https://
arxiv.org/abs/2510.02327 Can a speech AI think deeply without pausing to process? In real -
Audio-Omni: Unified Framework for Audio Understanding, Generation, Editing
By
–
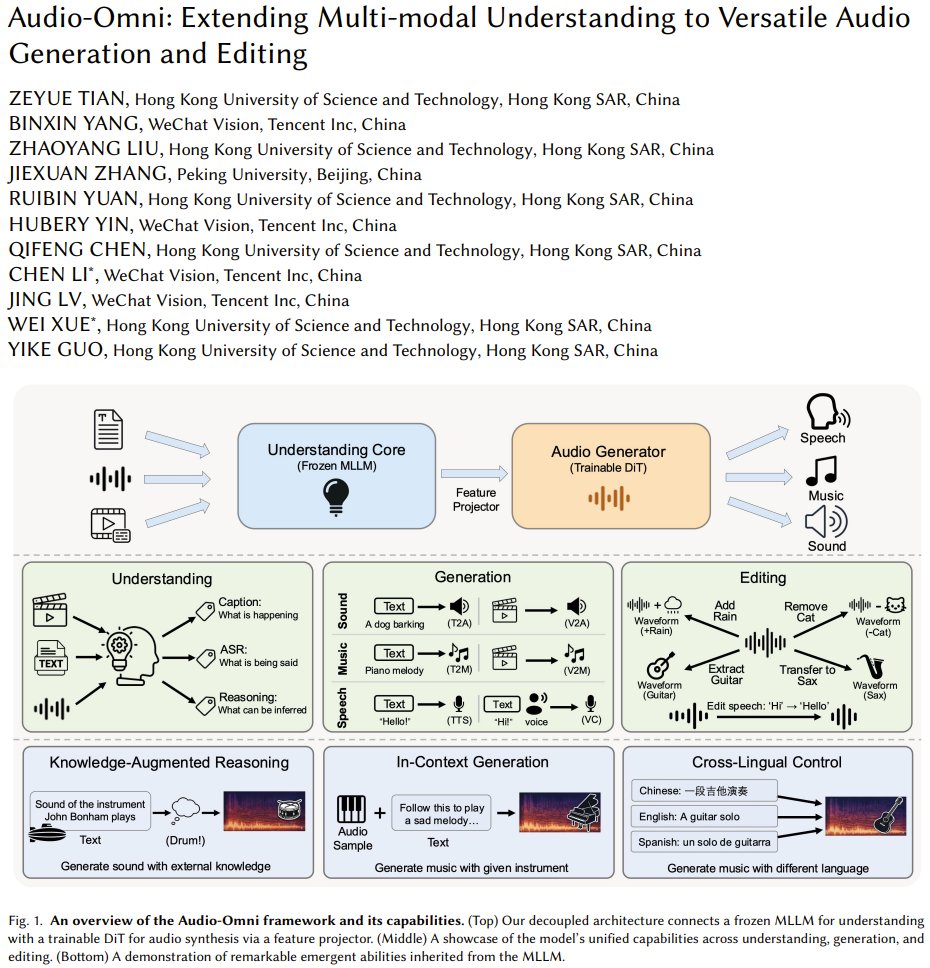
What if your AI could not only understand sound but also generate and edit it, all in one model? Researchers from HKUST, Tencent, and Peking University introduce Audio-Omni. It’s the first end-to-end framework that unifies audio understanding, generation, and editing across
-
Mistral Vide now in Le Chat, new Work Mode preview
By
–
Users can now use Mistral Vide directly in Le Chat!
— 🚨 AI News | TestingCatalog (@testingcatalog) 29 avril 2026
Besides that, Le Chat got a new Work Mode in Preview: an agent that can handle complex tasks across connected tools. https://t.co/XQn3Uo9TPr pic.twitter.com/Kin0tKjhFuUsers can now use Mistral Vide directly in Le Chat! Besides that, Le Chat got a new Work Mode in Preview: an agent that can handle complex tasks across connected tools.
-
Deep Agents Launches Per-Model Harness Profiles Feature
By
–
Until today, Deep Agents shipped with a single set of prompts, tools, and middleware aimed to work well across all Large Language Models. With the launch of harness profiles, you can now control these parameters on a per-model basis.
-
9 Steps to Build Functional AI Agents from Scratch
By
–
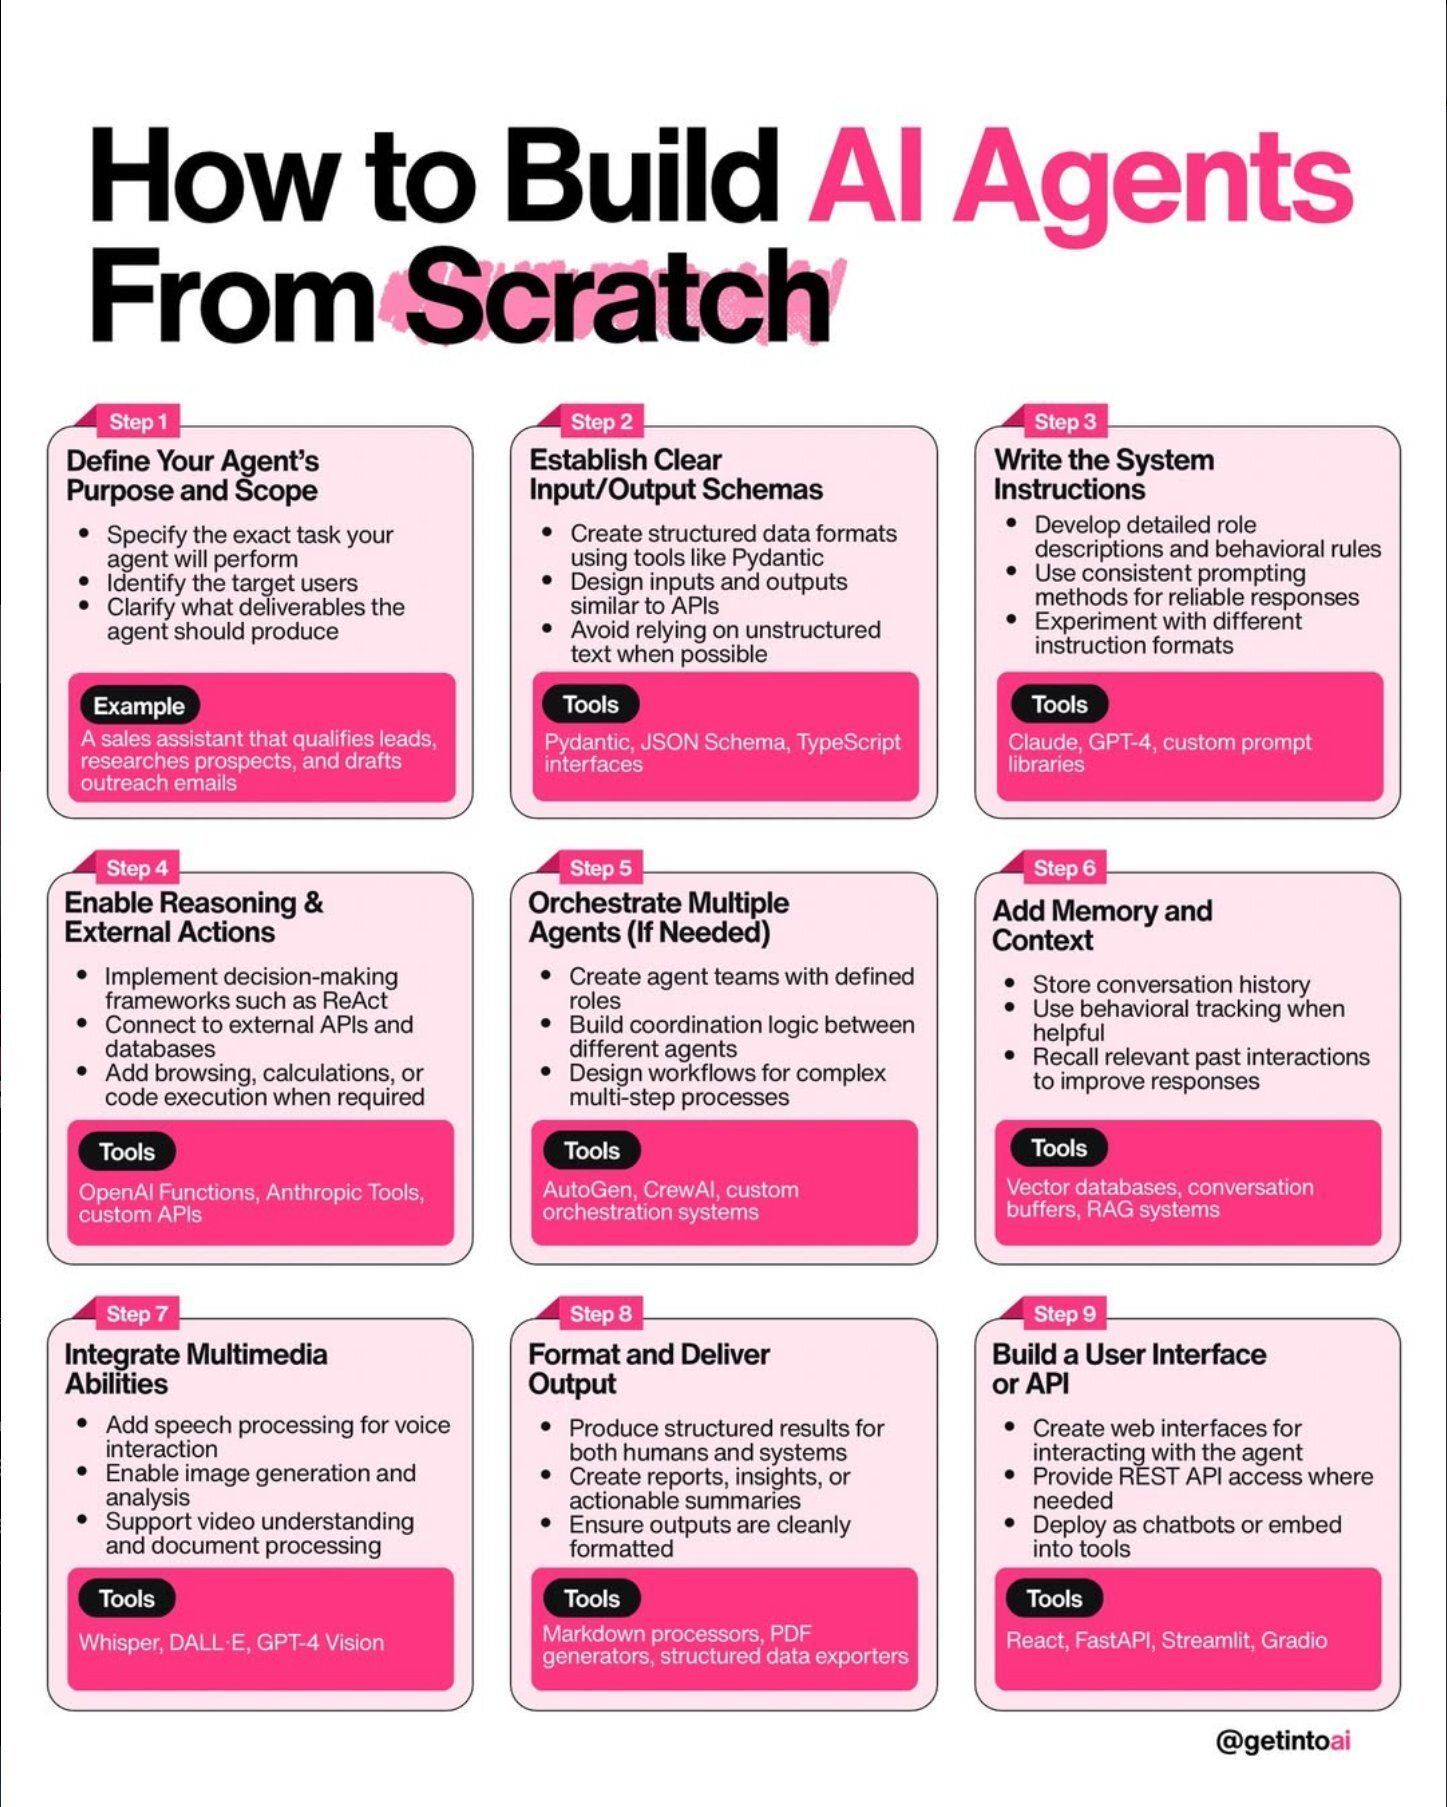
How to build AI agents from scratch (9 steps): 1. Purpose & scope 2. I/O schemas 3. System instructions 4. Reasoning + tools 5. Multi-agent orchestration 6. Memory & context 7. Multimodal 8. Structured outputs 9. UI / API Ship agents that do work, not just talk.
-
The 8-Layer Architecture of Agentic AI Explained
By
–
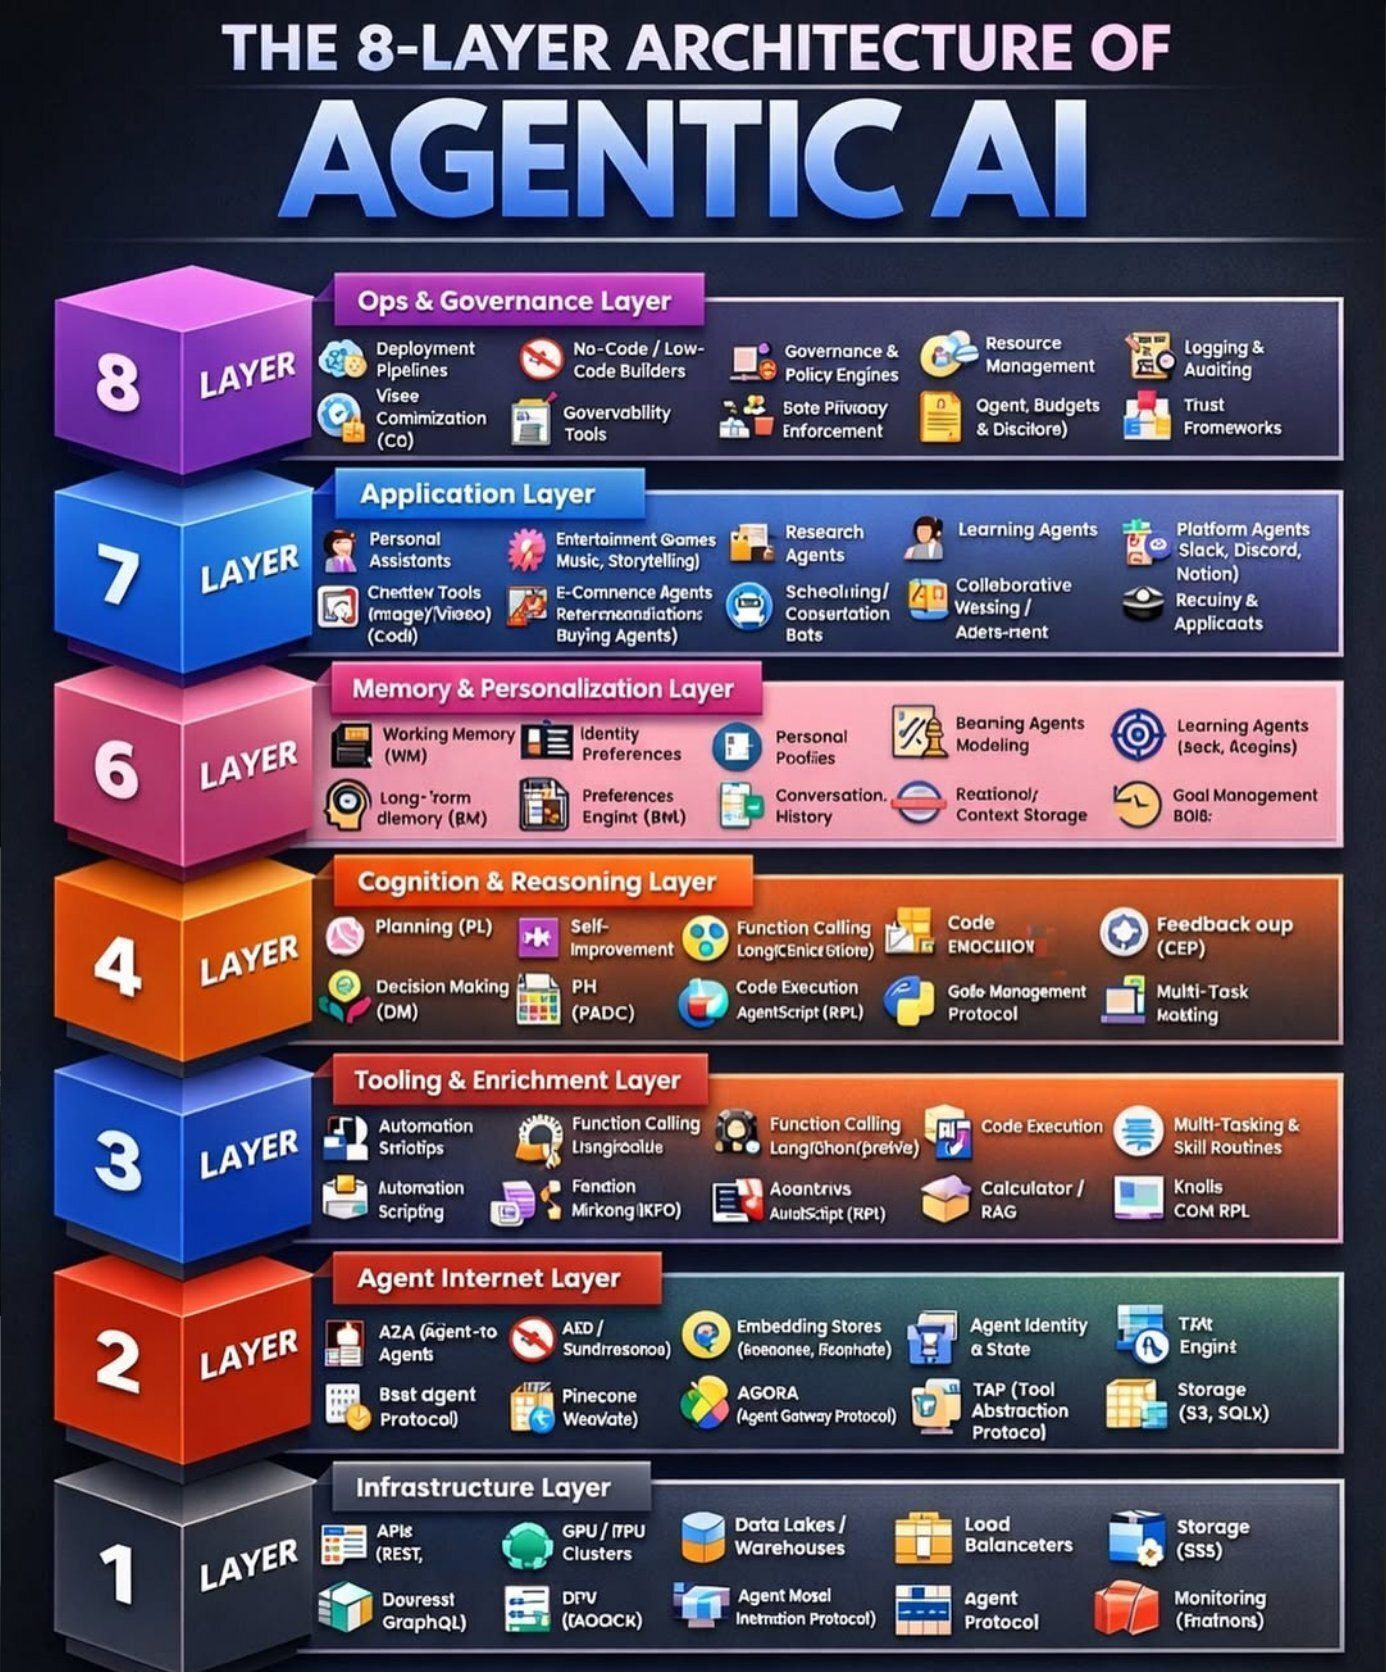
The 8-Layer Architecture of #AgenticAI
by @Python_Dv #AI #LLM #ArtificialIntelligence #MachineLearning #ML -
Deep Agents: Optimizing Performance Across Model Families
By
–
great deep dive into how we get deepagents to work well with different families of models