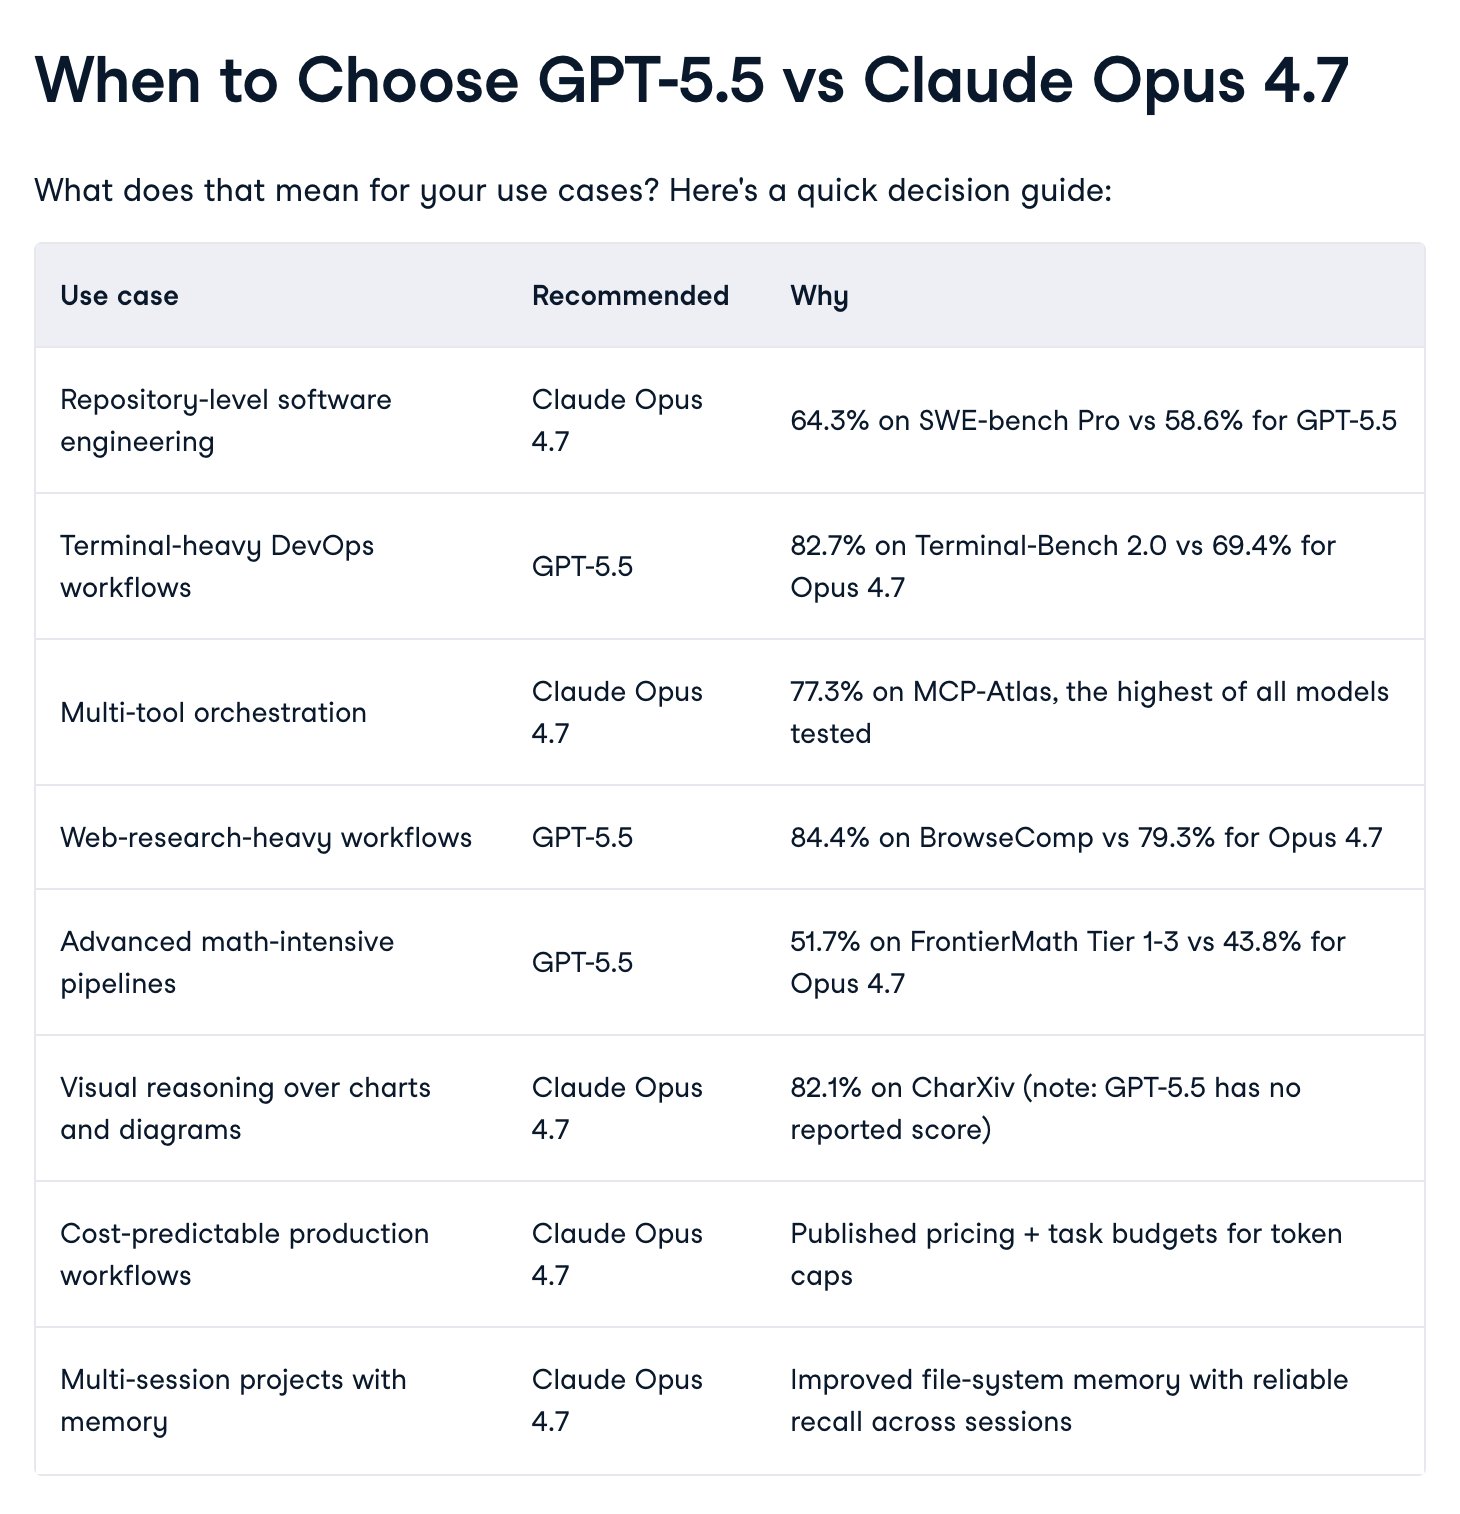
Token efficiency is where things get interesting. GPT-5.5 uses 72% fewer output tokens than Opus 4.7 on the same coding tasks. Fewer tokens means lower cost per task, even though GPT-5.5 costs $30/M output vs Claude's $25/M. But Claude's time-to-first-token is roughly 0.5s vs
LLMS
-
GPT-5.5 outperforms Claude Opus 4.7 by 13 points on terminal benchmarks
By
–
Long-running agentic execution: GPT-5.5
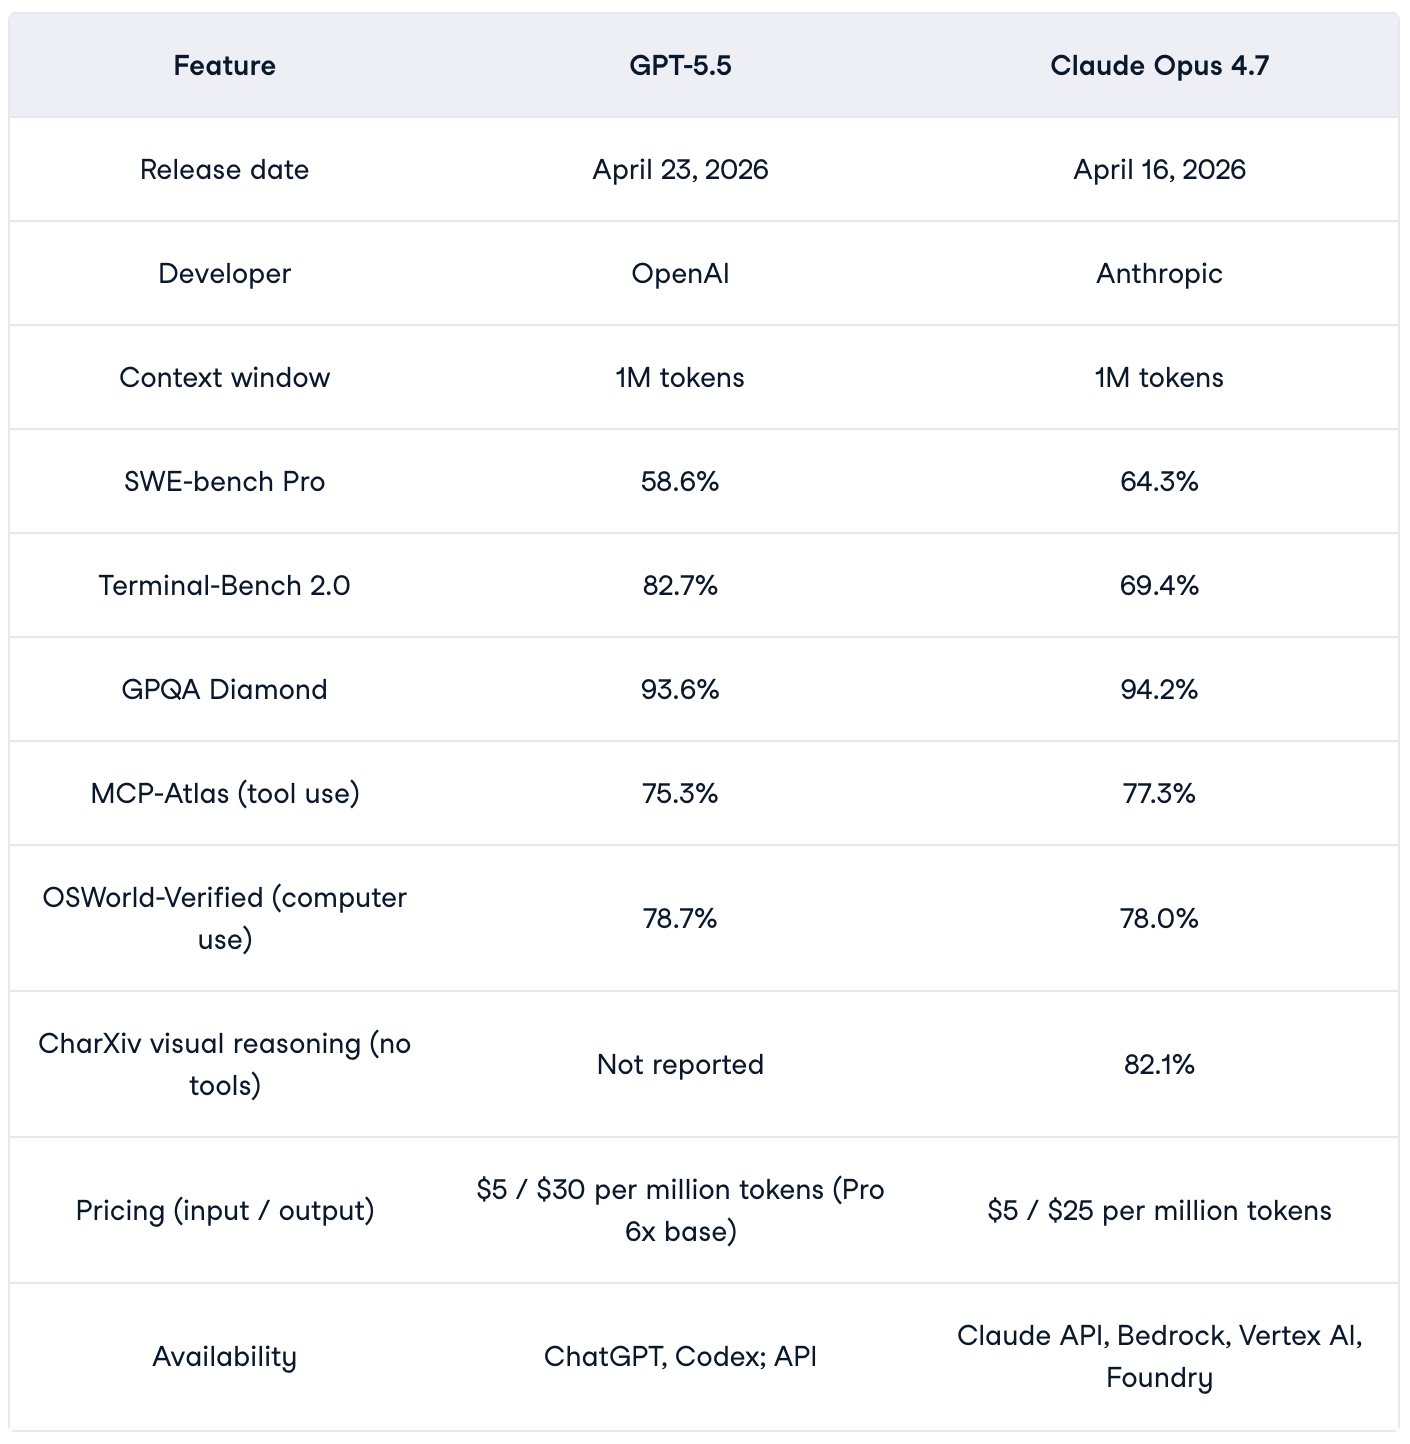
→ Terminal-Bench 2.0: 82.7% → Claude Opus 4.7: 69.4% That's a 13-point gap. Not noise.
→ OSWorld-Verified: 78.7% vs 78.0% → BrowseComp → CyberGym When the task requires driving a terminal, recovering from errors, and -
Claude Opus 4.7 dominates reasoning and code benchmarks
By
–
Deep reasoning and code precision: Claude Opus 4.7 → SWE-Bench Pro: 64.3% → GPT-5.5: 58.6% → MCP Atlas: 79.1% → GPT-5.5: 75.3% → GPQA Diamond, HLE (with and without tools), FinanceAgent v1.1: all Opus 4.7 When the task requires architectural thinking
-
LLM 0.32a0 Released: Major Refactor for Reasoning Models
By
–
I released LLM 0.32a0 this morning, a major backwards-compatible refactor of my LLM Python library and CLI tool for working with language models – the new changes should help LLM work better with reasoning models and other new frontier capabilities
-
Claude Opus 4.7 leads GPT-5.5 on 6 of 10 benchmarks by category
By
–
On the 10 benchmarks where both OpenAI and Anthropic report scores, here's the split: Claude Opus 4.7 leads on 6. GPT-5.5 leads on 4. But the leads aren't random. They cluster by category. And that changes what "winning" means entirely.
-
GPT-5.5 vs Claude Opus 4.7: The real benchmark story
By
–
GPT-5.5 shipped 7 days after Claude Opus 4.7. Everyone picked a winner based on headlines. I looked at every benchmark both labs published. The real story isn't what most people are reporting:
-

LLMs Cannot Replace Decades of Regulated Experience
By
–
SAS’ Tom Roehm: “AI is everywhere. Yes, LLMs are powerful… But here’s what they can’t do — they can’t scrape decades of lived experience or inherit judgment forged from working in regulated environments. They can’t feel the weight of decisions where being ‘mostly right’ isn’t
-
ChatLLM Unifies Multiple LLMs in Single Platform
By
–
GPT-5.5, Opus-4.7, DeepSeek-V4, Kimi-2.6… all in one place on ChatLLM by Abacus AI
— Abacus.AI (@abacusai) 29 avril 2026
No more jumping between tools.
You just type what you want to build, and it actually happens.
That’s the shift. pic.twitter.com/b5malOZhIfGPT-5.5, Opus-4.7, DeepSeek-V4, Kimi-2.6… all in one place on ChatLLM by Abacus AI No more jumping between tools.
You just type what you want to build, and it actually happens.
That’s the shift. -
Google AI Models Lag Behind Competitors, User Warns
By
–
Don’t use Google models, currently they’re way behind the others for most things