
SAS’ Tom Roehm: “AI is everywhere. Yes, LLMs are powerful… But here’s what they can’t do — they can’t scrape decades of lived experience or inherit judgment forged from working in regulated environments. They can’t feel the weight of decisions where being ‘mostly right’ isn’t
LLMS
-
ChatLLM Unifies Multiple LLMs in Single Platform
By
–
GPT-5.5, Opus-4.7, DeepSeek-V4, Kimi-2.6… all in one place on ChatLLM by Abacus AI
— Abacus.AI (@abacusai) 29 avril 2026
No more jumping between tools.
You just type what you want to build, and it actually happens.
That’s the shift. pic.twitter.com/b5malOZhIfGPT-5.5, Opus-4.7, DeepSeek-V4, Kimi-2.6… all in one place on ChatLLM by Abacus AI No more jumping between tools.
You just type what you want to build, and it actually happens.
That’s the shift. -
Google AI Models Lag Behind Competitors, User Warns
By
–
Don’t use Google models, currently they’re way behind the others for most things
-

OSS Models Key to Cost-Effective DeepAgents in 2026
By
–
big theme of 2026 – cost of closed models is too high! really excited to make deepagents work exceptionally well with OSS models
-
Embedding Layers in Small Models: Architecture and Training Optimization
By
–
Did you know that the embedding layer can contain 63% of total model parameters? In this talk, I present unique challenges of small models from architecture (don't build giant embedding layers) to post-training (how to fix doom looping) ↓ Slides in the comments ↓
-
Configuring AI Agent with GLM5 Model via Baseten
By
–
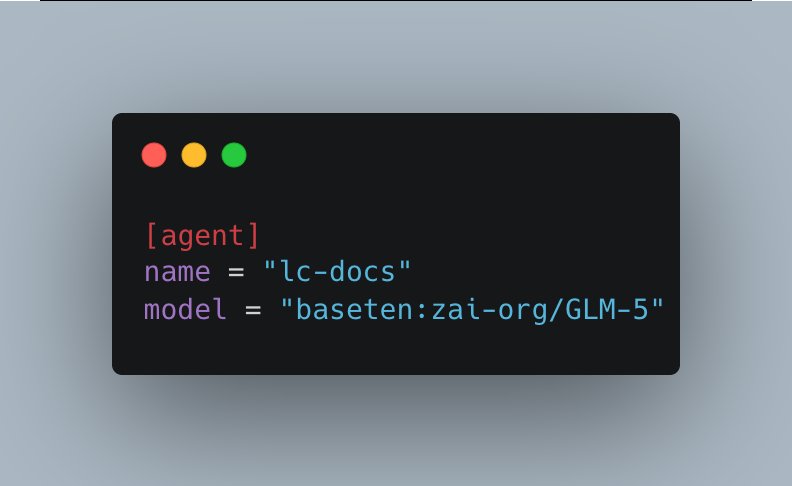
After switching into the new directory (`cd lc-docs`) I'm going to set the name of my agent, and the model to use This is done in deepagents.toml I'm going to use @Zai_org GLM5 model, served via @baseten
-
Tandem Voice AI Architecture Enables Speaking While Thinking
By
–
For years, voice AI has been stuck in a rigid loop: think, then speak. But real human conversation is messy, overlapping, and asynchronous.
— hardmaru (@hardmaru) 29 avril 2026
In our new #ICASSP2026 work, we built a tandem architecture that shifts the paradigm to “speak while thinking.” A fast speech model starts… https://t.co/gyRFlqDSUjFor years, voice AI has been stuck in a rigid loop: think, then speak. But real human conversation is messy, overlapping, and asynchronous. In our new #ICASSP2026 work, we built a tandem architecture that shifts the paradigm to “speak while thinking.” A fast speech model starts
-
Mistral Medium 3.5 positioning strategy among Asian LLM competitors
By
–
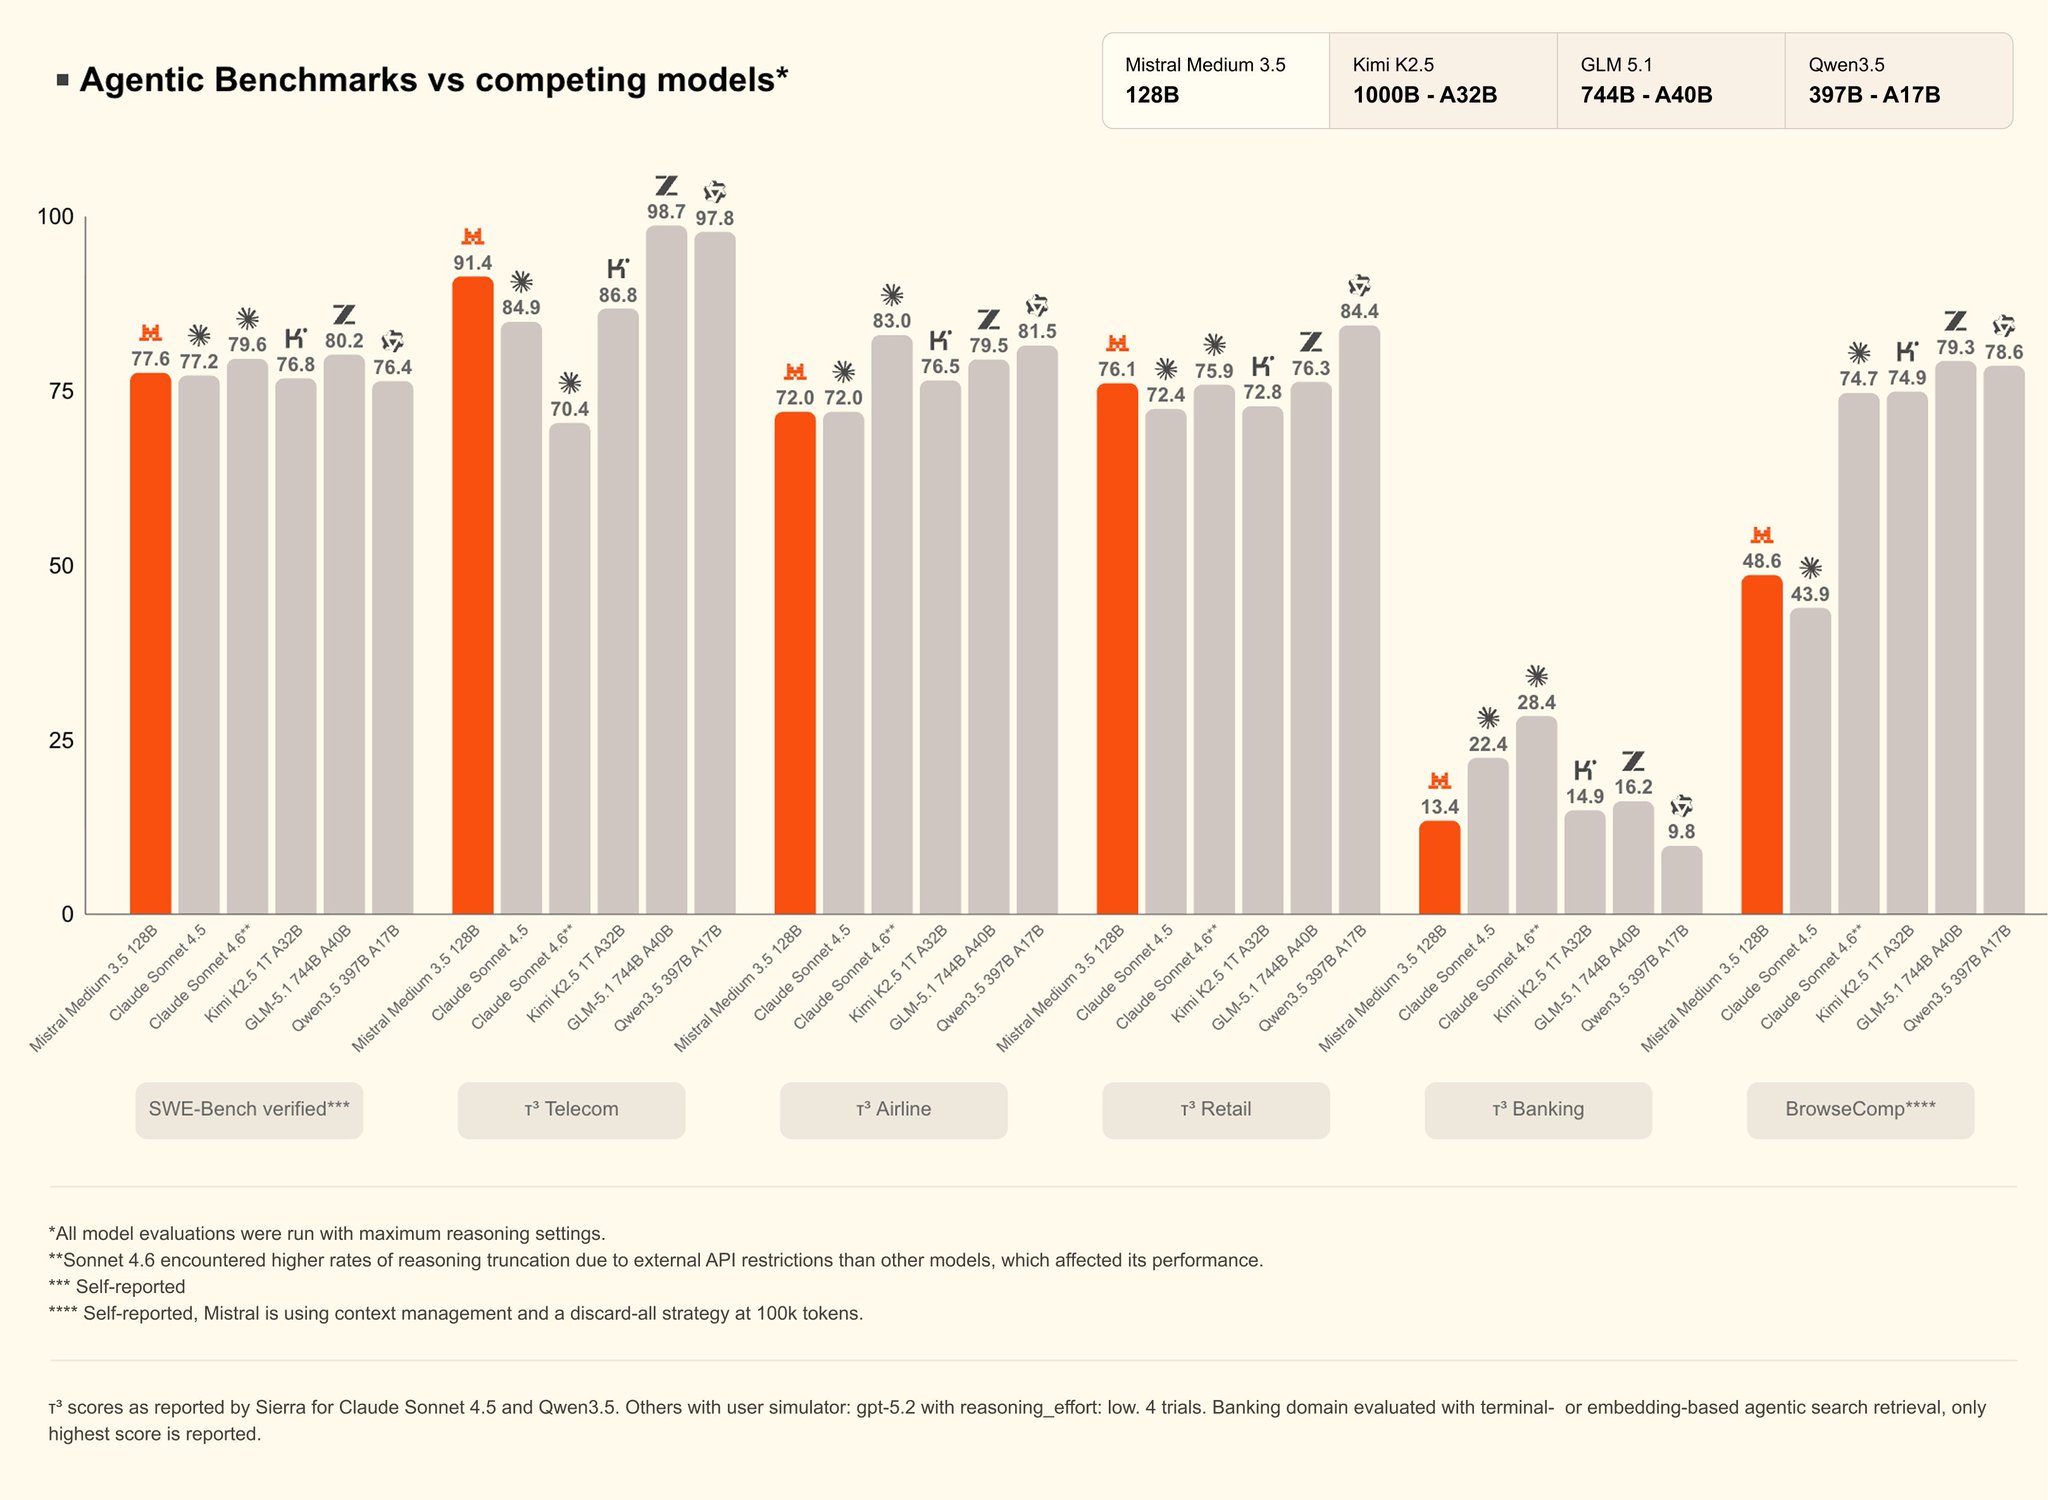
Mistral Medium 3.5 is interesting less for the benchmarks and more for the positioning. Look at who they're comparing against: Kimi, Qwen, GLM, Claude (Sonnet). Not GPT, not Gemini. And i dont mean that in a negative way! With Aleph Alpha being acquired by Cohere last week,
-
KAME: Real-Time Speech-to-Speech AI With Deep Thinking
By
–
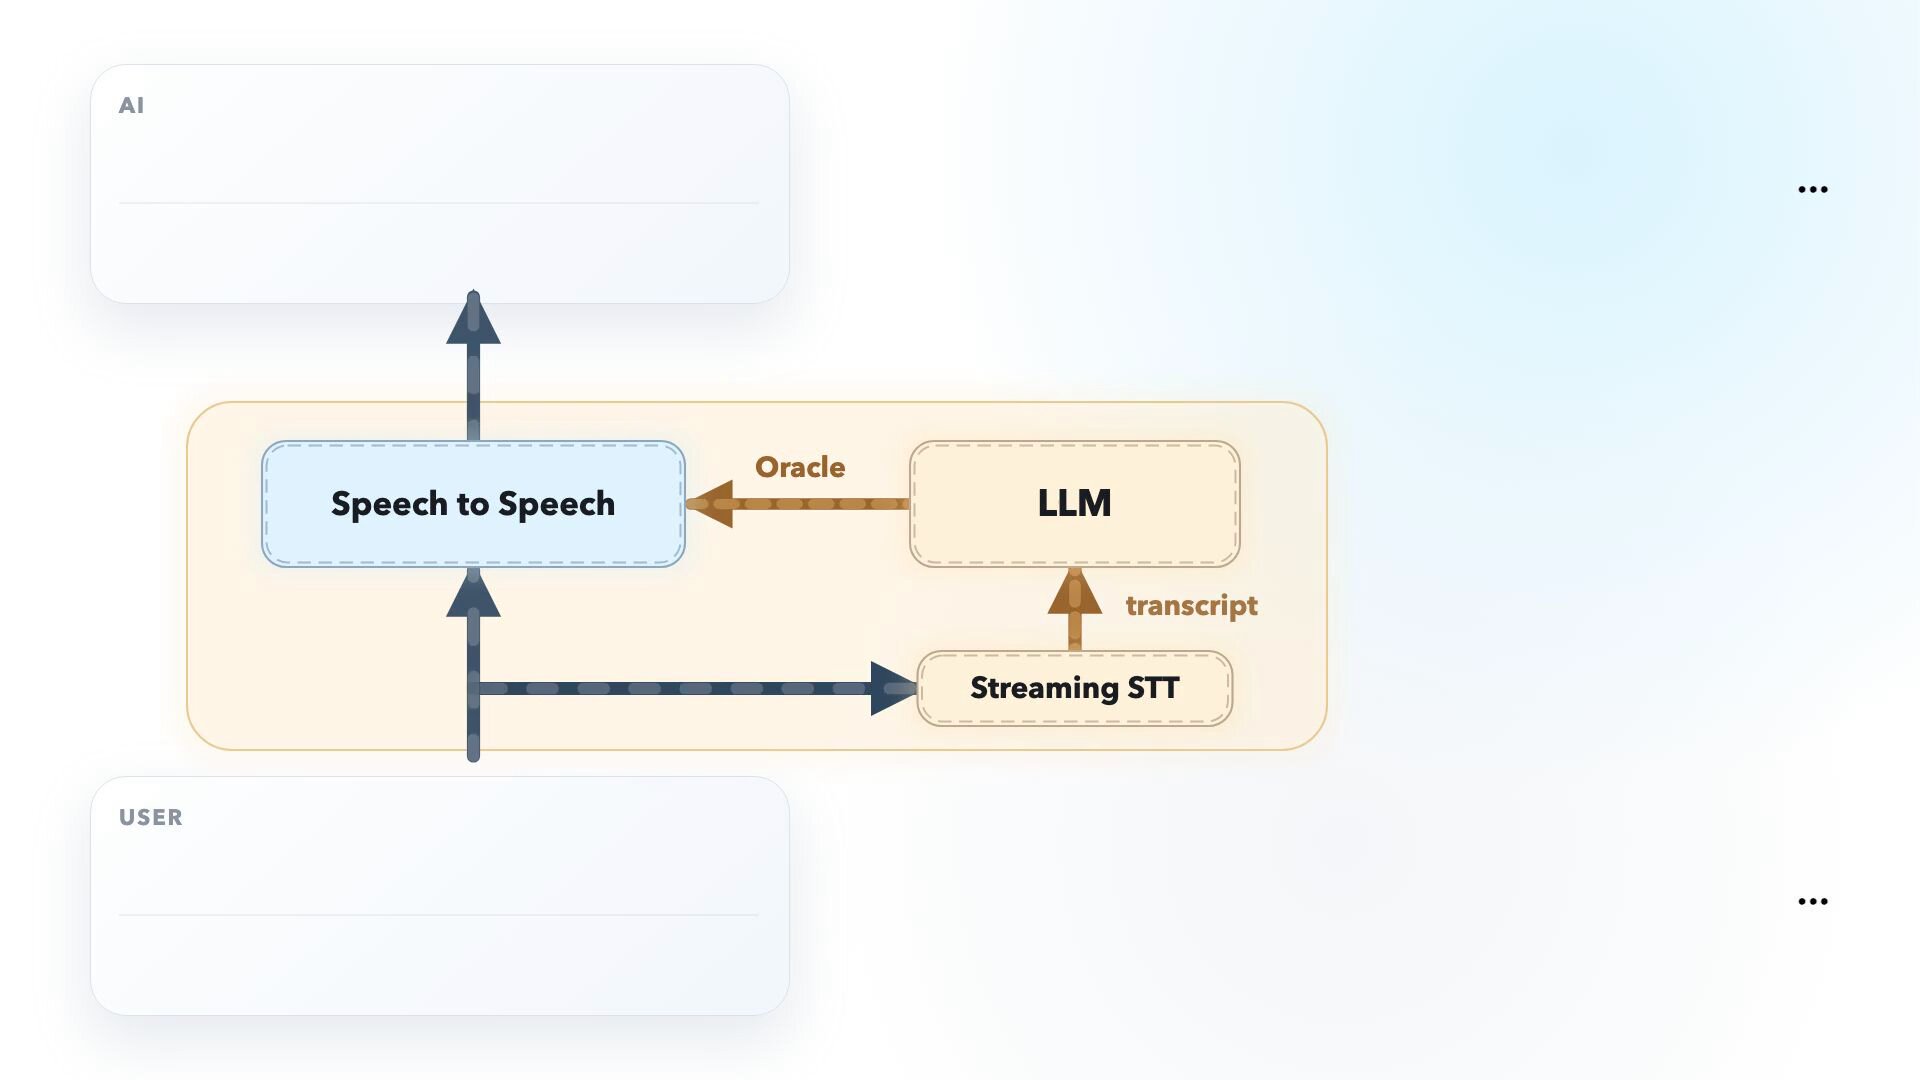
We’re excited to introduce KAME: Tandem Architecture for Enhancing Knowledge in Real-Time Speech-to-Speech Conversational AI, accepted at #ICASSP2026! 🐢
— Sakana AI (@SakanaAILabs) 29 avril 2026
Blog https://t.co/eyU3yECBK8
Paper https://t.co/PVYPIcHyyM
Can a speech AI think deeply without pausing to process?
In real… pic.twitter.com/Ut0ypkjJWxWe’re excited to introduce KAME: Tandem Architecture for Enhancing Knowledge in Real-Time Speech-to-Speech Conversational AI, accepted at #ICASSP2026! Blog https://
pub.sakana.ai/kame/
Paper https://
arxiv.org/abs/2510.02327 Can a speech AI think deeply without pausing to process? In real -
Audio-Omni: Unified Framework for Audio Understanding, Generation, Editing
By
–
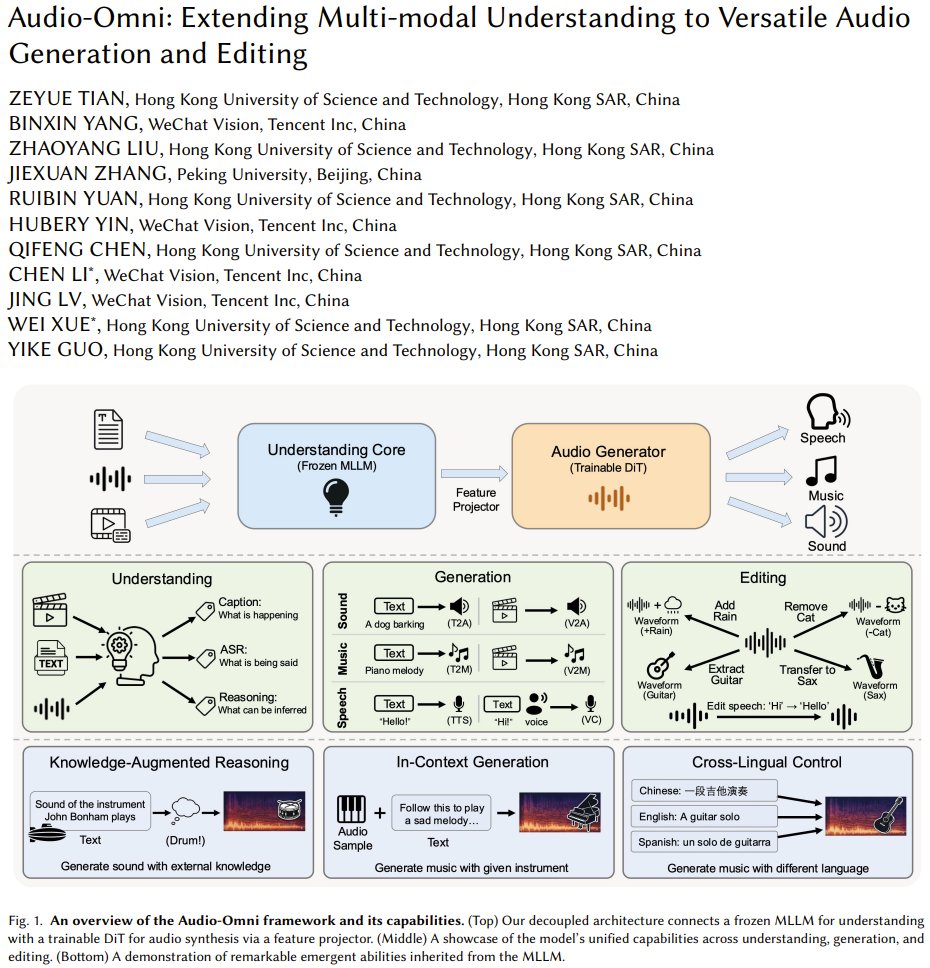
What if your AI could not only understand sound but also generate and edit it, all in one model? Researchers from HKUST, Tencent, and Peking University introduce Audio-Omni. It’s the first end-to-end framework that unifies audio understanding, generation, and editing across