Edit
https://replicate.com/wan-video/wan-2.7-videoedit [Translated from EN to English]
→ View original post on X — @replicate, 2026-04-03 13:31 UTC
By
–
Edit
https://replicate.com/wan-video/wan-2.7-videoedit [Translated from EN to English]
→ View original post on X — @replicate, 2026-04-03 13:31 UTC
By
–
Image to replicate.com/wan-video/wan-2.7-i2v [Translated from EN to English]
→ View original post on X — @replicate, 2026-04-03 13:31 UTC
By
–
Text to replicate.com/wan-video/wan-… [Translated from EN to English]
→ View original post on X — @replicate, 2026-04-03 13:30 UTC
By
–
Wan 2.7 Video is now on Replicate
— Replicate (@replicate) 3 avril 2026
generation, editing, cloning, restyling, and continuation controlled by text, image, audio, or video
here's what that looks like 🧵 pic.twitter.com/OcO7LKPRph
Wan 2.7 is now on Replicate generation, editing, cloning, restyling, and continuation controlled by text, image, audio, or video here's what that looks like 🧵
→ View original post on X — @replicate, 2026-04-03 13:30 UTC
By
–
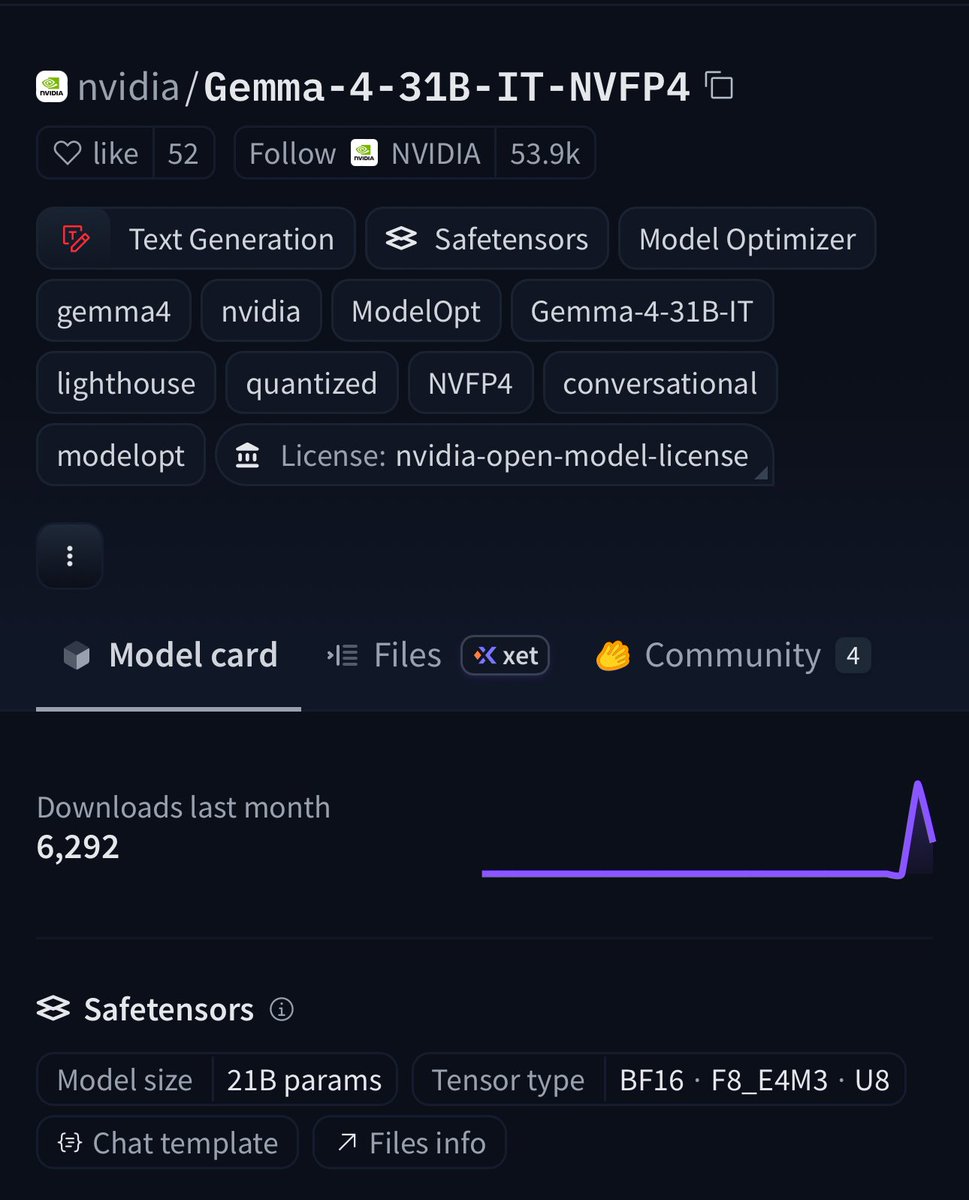
BREAKING:🚨 NVIDIA just quantized Gemma 4 31B on Hugging Face 🔥 NVFP4 compression = 4x smaller weights with frontier-level accuracy. ✅99.7% of baseline on GPQA (75.46% vs 75.71%). 📈256K context window. 🧐Multimodal (text + images + video). vLLM-ready + Blackwell optimized. VRAM requirements: ⚡️Weights only: ~16–21 GB 🚀Everyday use: Runs on 24 GB GPUs 📈Full 256K context = 32 GB VRAM sweet spot (RTX 5090-class consumer GPUs) This is the 31B-class frontier model you can actually run locally on a high-end rig. Try it today👉 huggingface.co/nvidia/Gemma-…
→ View original post on X — @huggingface, 2026-04-03 13:30 UTC
By
–
🐍 YOLOv11: The Next Leap in Real-Time Detection
— Satya Mallick (@LearnOpenCV) 3 avril 2026
For nearly a decade, the YOLO family kept pushing real-time object detection forward. In 2024, YOLOv11 arrived faster, more accurate, and easier to deploy. 🚀
With improved multi-scale fusion, streamlined inference, and models… pic.twitter.com/4T0rz9yv6x
🐍 YOLOv11: The Next Leap in Real-Time Detection For nearly a decade, the YOLO family kept pushing real-time object detection forward. In 2024, YOLOv11 arrived faster, more accurate, and easier to deploy. 🚀 With improved multi-scale fusion, streamlined inference, and models sized for both edge devices and maximum accuracy, YOLOv11 stayed true to the YOLO philosophy: fast enough for real-time, accurate enough for production, simple enough to deploy everywhere. ⚡ #YOLOv11 #ComputerVision #DeepLearning #AI #ObjectDetection #MachineLearning #AIResearch #DataScience 🤖
→ View original post on X — @learnopencv, 2026-04-03 13:26 UTC
By
–
I made a Claude Code skill that turns any arxiv paper into working code.
— pdawg (@prathamgrv) 3 avril 2026
Every line traces back to the paper section it came from & any implementation detail the paper skips will be flagged, and not assumed.
open sourcing it –https://t.co/sSio4JfpIo pic.twitter.com/5XqlGgQsqC
I made a Claude Code skill that turns any arxiv paper into working code. Every line traces back to the paper section it came from & any implementation detail the paper skips will be flagged, and not assumed. open sourcing it – github.com/PrathamLearnsToCo…
By
–
Netflix: surprise we just released our new AI model VOID on @huggingface. Capabilities of Netflix's VOID Model:
– Object Removal with Environmental Awareness.
– Physical Interaction Handling.
– Open-Weight Access. [Translated from EN to English]
→ View original post on X — @huggingface, 2026-04-03 13:20 UTC
By
–
Holy: OpenAI says it’s reallocating compute and talent toward its next generation of models, echoing the internal shift that preceded GPT-3.
— Chubby♨️ (@kimmonismus) 3 avril 2026
The focus now is on “automated researchers” and agent-based systems that can execute complex tasks end-to-end.
It’s a signal that the lab… pic.twitter.com/4jMc4eJgTR
Holy: OpenAI says it’s reallocating compute and talent toward its next generation of models, echoing the internal shift that preceded GPT-3. The focus now is on “automated researchers” and agent-based systems that can execute complex tasks end-to-end. It’s a signal that the lab
By
–
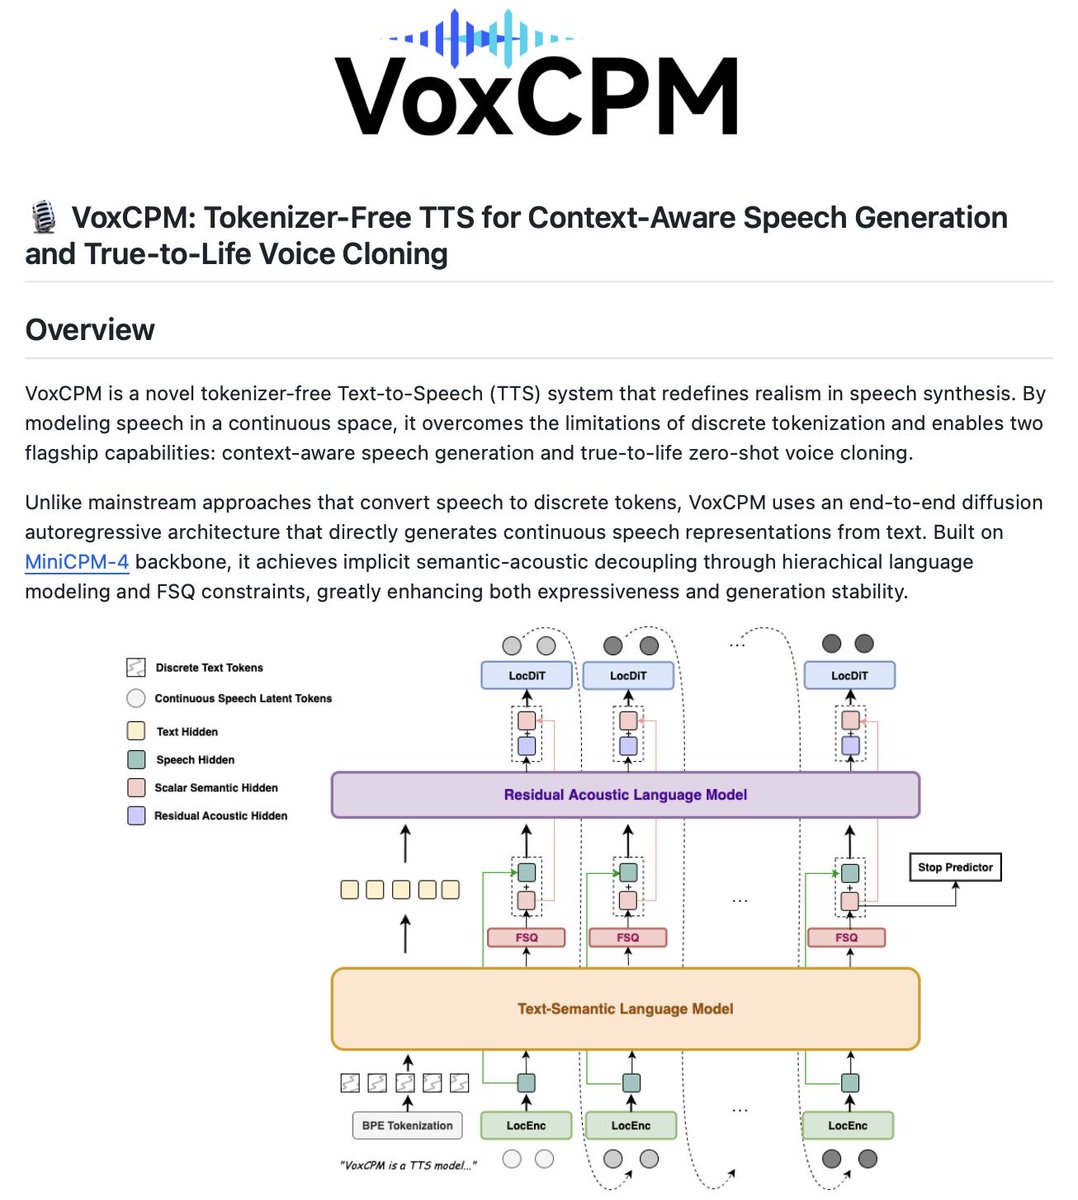
If you found it useful, reshare it with your network Follow me → @Sumanth_077 for more insights and tutorials on AI Engineering! nitter.net/Sumanth_077/status/204… Sumanth (@Sumanth_077) Clone a human voice in real time without tokenization! VoxCPM is an open-source text-to-speech system that models speech in continuous space instead of discrete tokens. Most TTS systems convert speech to discrete tokens before generation. This quantization creates a fundamental trade-off: tokens provide stability but lose acoustic details like breath, vocal texture, and subtle articulation. VoxCPM skips tokenization entirely. It models speech directly in continuous space using an end-to-end diffusion autoregressive architecture built on MiniCPM-4. The system uses hierarchical language modeling with two specialized components: a Text-Semantic Language Model that captures high-level prosody and structure, and a Residual Acoustic Model that recovers fine-grained acoustic details. This separation eliminates dependency on external speech tokenizers and prevents error accumulation from multi-stage pipelines. Two flagship capabilities: 1. Context-aware speech generation: The model comprehends text to infer appropriate prosody and speaking style. Explanations slow down naturally, emphasis appears in the right places, questions sound like questions. 2. Zero-shot voice cloning: With just 3-10 seconds of reference audio, it replicates speaker timbre, accent, emotional tone, rhythm, and pacing. Key features: • Tokenizer-free architecture with continuous speech modeling • Context-aware prosody generation without manual tuning • Zero-shot voice cloning from short reference audio • Streaming synthesis support for real-time applications • SFT and LoRA fine-tuning support It's 100% open source Link to the GitHub repo in the comments! — https://nitter.net/Sumanth_077/status/2040055394958286903#m
→ View original post on X — @sumanth_077, 2026-04-03 13:15 UTC