I use CC from Cursor and I assumed most do as well (?).
I end up with a mixed thing where Cursor is the UI layer for reading the code, manual edits, tab completion and chunk edits, and CC for larger changes, architecting, Q&A. Still rapidly evolving though…
INNOVATION
-
Using Cursor and Claude for AI-Assisted Development Workflow
By
–
-
Enterprise AI Agents Require Custom Development Not Off-Shelf Solutions
By
–
This is very true. Economically valuable agents for enterprises are already here, but you can’t buy them off the shelf & they require actual cross-functional R&D.
-

Industrial Edge Systems Evolving Toward Autonomous Manufacturing Intelligence
By
–
From connected to autonomous:
Industrial edge systems are evolving fast—bringing intelligence, speed, and agility to the shop floor. Explore what this means for the future of manufacturing: https://
buff.ly/02IQmt7 #BlackPearl_iiot #IIoT #EdgeComputing #IndustrialInnovation -

Learn Anything with Powerful o3 AI Prompt Tool
By
–
Learn ANYTHING with this powerful o3 prompt. Just tell it what you want to learn, and it'll create a customized course for you, comprised of the best content around the web for each topic! It's like having a team of world-class professors all working together to teach you!
-
Google’s AI Opportunity and Risk Under Sundar Pichai
By
–
Of all the tech giants, Google has the most to gain from AI and also the most to lose. No pressure, Sundar.
-
Beyond Compute: Alternative Methods for AI Improvements
By
–
What I’d like to know is how it was done other than by throwing more compute at it. Because the latter is not very interesting.
-

AI Should Augment Human Thinking, Not Replace It
By
–
AI can, and should, augment our thinking, not merely match and replace it.
-
Q-Chunking: Reinforcement Learning for Long-Horizon Sparse-Reward Tasks
By
–
9. Q-Chunking Q-chunking is a reinforcement learning approach that uses action chunking to improve offline-to-online learning in long-horizon, sparse-reward tasks.
-
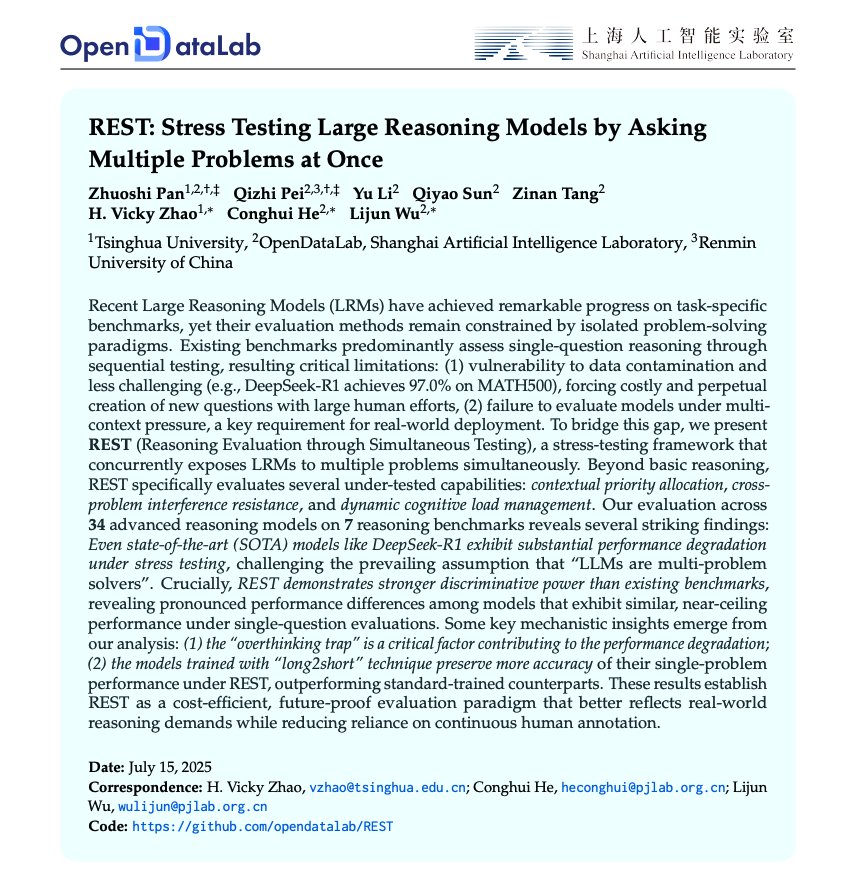
REST Benchmark Framework Evaluates Large Reasoning Models Robustness
By
–
5. Stress Testing Large Reasoning Models Proposes a new benchmark framework called REST to evaluate the robustness of Large Reasoning Models (LRMs) under multi-question stress.
-
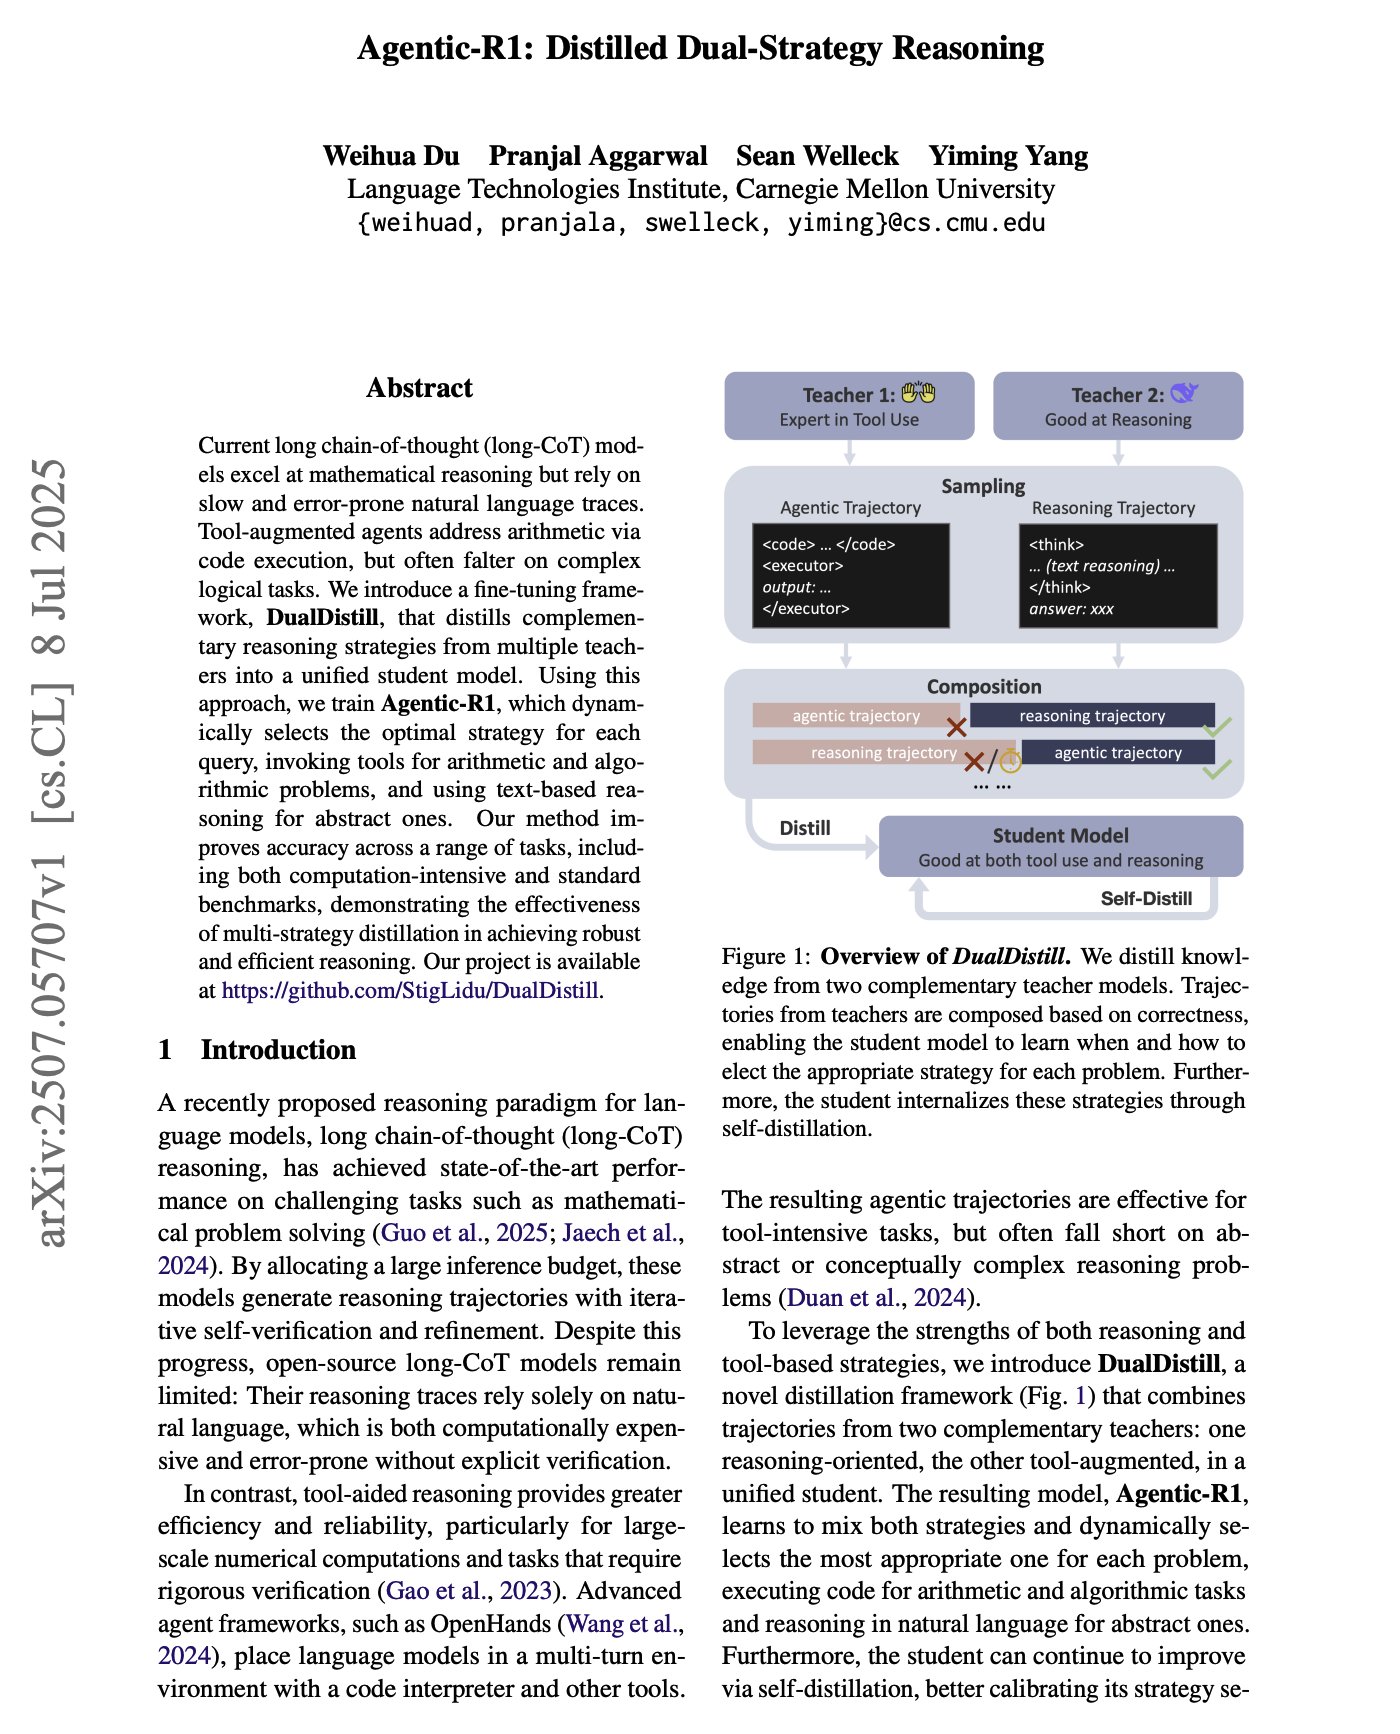
Agentic-R1: 7B Language Model with Dynamic Tool-Based Reasoning
By
–
3. Agentic-R1 This paper introduces Agentic-R1, a 7B language model trained to dynamically switch between tool-based execution and pure text reasoning using a novel fine-tuning framework called DualDistill.