Yes open/close in AI seems to be following kind of a cycle, at the individual, company and country level I feel like. Something like:
#1 we’re not leading, let’s open science and open-source > #2 we are now leading, we can open science and open-source less > back to #1 as a
INNOVATION
-
AI Open Source Cycles: Leadership and Strategic Openness
By
–
-

Survey of Continual Reinforcement Learning Advances
By
–
A Survey of Continual Reinforcement Learning Pan et al.: https://
arxiv.org/abs/2506.21872 #ArtificialIntelligence #DeepLearning #MachineLearning -
Unitree R1 Humanoid Robot Launches at $5.9K Price Point
By
–
Unitree R1: Humanoid for $5.9K! Take that, Tesla! https://
search.app/RnxPM #robotics #humanoidrobot #unitree #Tesla #optimus #Humanoid @sonu_monika @enilev @Jagersbergknut @TysonLester @chidambara09 @labordeolivier @BetaMoroney @tlloydjones @Nicochan33 @jeancayeux -
Generative AI’s Unprecedented Adoption Cycle
By
–
Generative AI’s Unprecedented Adoption Cycle
#AI #AIio #AIInnovation #ML #DataScience #Futureofwork @lexfridman @sama @kaifulee @ID_AA_Carmack @karpathy @2morrowknight @ylecun -

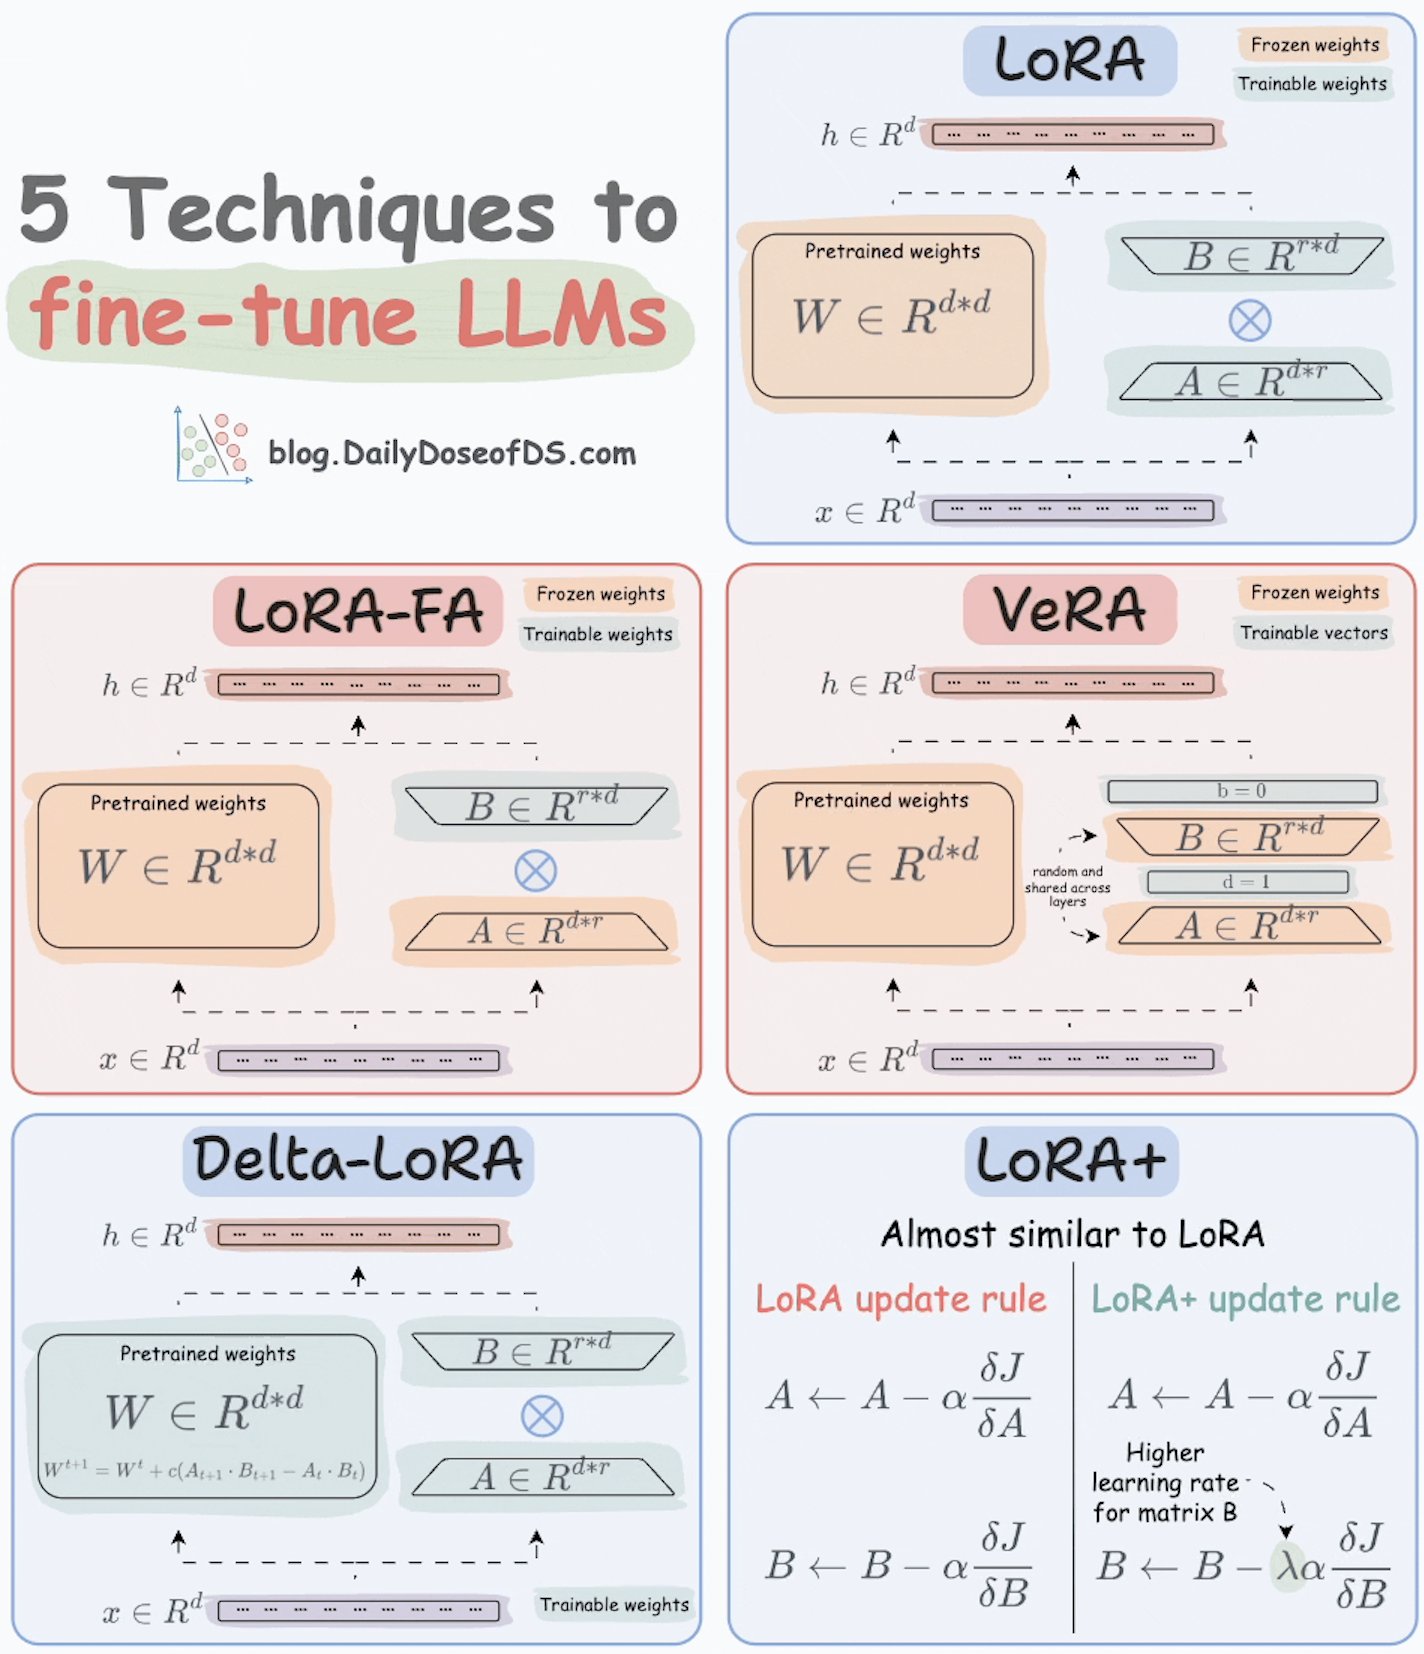
Delta-LoRA: Matrix Tuning Innovation in Model Training
By
–
4) Delta-LoRA – It tunes the matrix W as well, but not in the traditional way.
– Here, the difference (or delta) between the product of matrices A and B in two consecutive training steps is added to W. Check this -

LoRA: Efficient Fine-tuning with Low-Rank Matrices
By
–
1) LoRA – Add two low-rank trainable matrices, A and B, alongside weight matrices.
– Instead of fine-tuning W, adjust the updates in these low-rank matrices. Even for the largest of LLMs, LoRA matrices take up a few MBs of memory. Check this -

LLM Weights and Lower-Rank Adaptation in PEFT Techniques
By
–
Some background! LLM weights are matrices of numbers adjusted during finetuning. Most PEFT techniques involve finding a lower-rank adaptation of these matrices—a smaller-dimensional matrix that can still represent the information stored in the original.
-
Top 5 Parameter-Efficient Fine-Tuning Techniques for LLMs
By
–
Traditional fine‑tuning is impractical for LLMs (billions of params; 100s GB). Since this kind of computing isn't accessible to everyone, parameter-efficient finetuning (PEFT) came into existence. Today, we’ll cover the top 5 PEFT techniques, step by step.
-
WordPress categories related to AI topics
By
–
Admittedly not the best example—just the first that popped up in search. Here’s one from less than a month ago, so presumably using 4o or better:
-

Quantum Computing Investment: Strategic Preparation for Business Transformation
By
–
Many companies still think quantum computing is too far away, but those who quietly invest today in practical pilots, skills, and partnerships will be better prepared when the landscape shifts from theoretical to usable. Microblog @antgrasso #DigitalTransformation