
poor humanoid robots inheriting the 5’11” problem
HARDWARE
-
Nvidia’s Strength Goes Beyond GPUs, Says DFIntelligence
By
–
Mdr. Il y a encore des gens qui croient que la force de Nvidia c’est juste de vendre des GPUs ?
— Defend Intelligence (Anis Ayari) (@DFintelligence) 20 avril 2024
Ahah les noobs. Bouuuh.
Rdv en 2030. 🤓🤓 https://t.co/9OY1aTdHtN pic.twitter.com/krmxmHw8qrLMAO. Are there still people who believe Nvidia's strength is just selling GPUs? Haha, noobs. Boo. See you in 2030.
https://x.com/bryanrbeal/sta/bryanrbeal/status/1781454698136109380
… -
MacBook Pro M2 RAM and Storage Constraints Discussion
By
–
I'm on a 64GB MacBook Pro M2 with 2TB of disk and I'm already feeling constrained for both RAM and disk space, but wow these laptops are expensive these days! I have a Samsung external 4TB USB drive which helps
-
Llama 3: Dense Model Efficiency vs Sparse MoE Scaling Strategy
By
–
Thing that most impresses me about Llama 3: how did they pack so much knowledge and reasoning into a dense 8b and a 70b so well, when everyone else has been scaling sparse MoEs. This still doesn’t mean having a lot of GPUs is not important. Probably even more important
-
Groq’s AI Chip Achieves 800 Tokens Per Second Performance
By
–
https://
venturebeat.com/ai/groqs-break
through-ai-chip-achieves-blistering-800-tokens-per-second-on-metas-llama-3/
… Thanks @VentureBeat for bringing the story to light. We really want to advance the landscape for AI Inference and the infrastructure necessary to usher in real-time AI for developers/applications. More to come… -
Open Models and Efficient Hardware Making AI More Accessible
By
–
"The combination of powerful open models like LLaMA and highly efficient “AI-first” inference hardware like Groq’s could make advanced language AI more cost-effective and accessible to a wider range of businesses and developers." – @MichaelFNunez
-

Apple MacBook Pro Upgrade Confirms Desirable Design Innovation
By
–
Apple Documents Confirm Desirable MacBook Pro Upgrade https://
forbes.com/sites/ewanspen
ce/2024/03/23/apple-macbook-pro-macbook-air-touchscreen-ipad-design-upgrade/?utm_source=dlvr.it&utm_medium=twitter
… #Innovation #ArtificialIntelligence #MachineLearning -
Fast LLaMA 3 Fine-tuning with ORPO on 8xH100 GPUs
By
–
all info available in the model page: https://
huggingface.co/abhishek/autot
rain-llama3-orpo
… 🙂 finetuning took ~30 mins on 8xH100 -
GPT-2 Activation Memory and GPU Cache Analysis
By
–
Makes sense, in GPT-2 (124M) case we're currently doing B=4, T=1024, C=768 => 3M activations @ float32 => 12MB. A100 L2 cache is 40MB, and even L1, at 192KB/SM with 108 SMs => ~= 20MB (wow, that's more than I expected). The pleasures of smaller networks and caches…
-
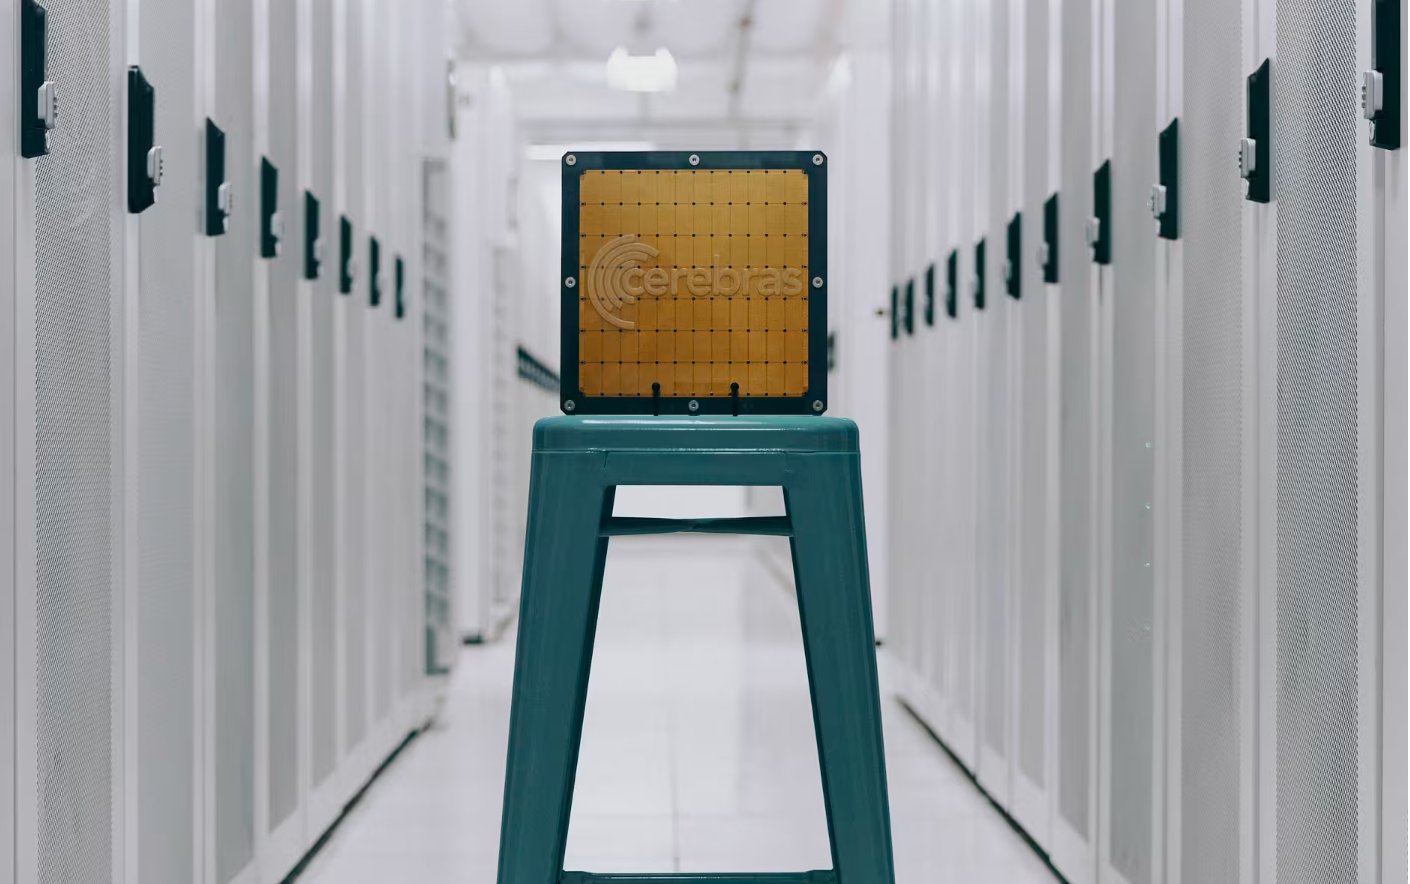
Cerebras WSE-3: Largest Commercial AI Supercomputer Chip
By
–
In Eric Savitz' latest article for Barron's, Cerebras is described as the most intriguing startup that is building AI supercomputers that rival NVIDIA. Highlights from the article: Cerebras Wafer Scale Engine 3 (WSE-3) is 72 square inches and is the largest commercial chip