Today on the OpenAI Forum: @sama, @jachiam0, and @AdrienLE talk about building AI in the public interest forum.openai.com/public/even…
→ View original post on X — @ceobillionaire, 2026-04-06 17:29 UTC

By
–
Today on the OpenAI Forum: @sama, @jachiam0, and @AdrienLE talk about building AI in the public interest forum.openai.com/public/even…
→ View original post on X — @ceobillionaire, 2026-04-06 17:29 UTC
By
–
It seems Henry Cavill is taking over the AI mindshare for "handsome man in a suit" : all text-to-video models I tried (Kling, Seedance, Veo) like to converge to his face. If anyone knows video training engineers, tell them to have models watch more James Bond or Suits. Thank
By
–
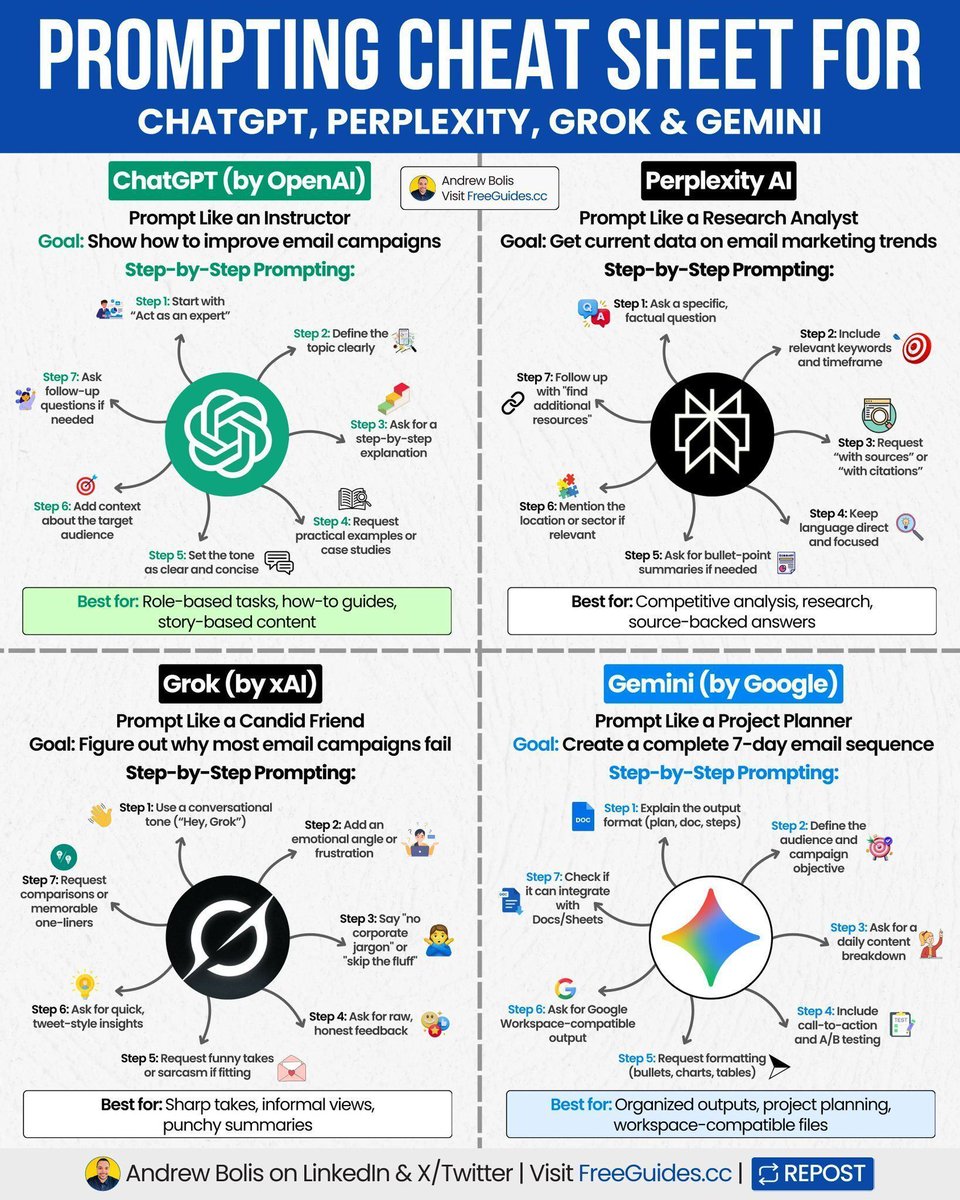
Prompting isn't one-size-fits-all. 🧠 This cheat sheet nails it: ChatGPT = instructor style ✅ Perplexity = research analyst style 🔍 Grok = candid friend style 😄 Gemini = project planner style 📌 Match the prompt to the tool → better outputs, faster. 🚀 What's your favorite prompt template? 👇 Credit: Andrew Bolis (FreeGuides.cc)
#PromptEngineering #GenAI #AItools #ChatGPT #Perplexity #Grok #Gemini [Translated from EN to English]
→ View original post on X — @ingliguori, 2026-04-06 17:25 UTC
By
–
These results keep coming. @GaryMarcus was way ahead on calling out these problems and dangers. And we're at risk of baking these issues into systems we rely on. Lars Christensen (@MaMoMVPY) I am increasingly coming to this conclusion – there NO SIGNS the problems with hallucinations are getting solved. In fact if anything it is now spreading to coding and the use of agents where it is hidden and could led to serious problems down the road. Therefore we can't really scale LLMs. LLMs are very useful tools, but you need to know about the limitations. Most of the investments in LLMs today assumes away these limitations. — https://nitter.net/MaMoMVPY/status/2041031551182340218#m
→ View original post on X — @garymarcus, 2026-04-06 17:20 UTC

By
–
WSJ obtained confidential financials from both OpenAI and Anthropic ahead of their expected IPOs later this year. The core tension: revenue is exploding, but training costs are exploding faster. OpenAI projects $121 billion in compute spending by 2028, resulting in $85 billion in losses that year alone, even after nearly doubling revenue. Strip out training costs and both companies are near profitability now; add them back and OpenAI doesn't break even until the 2030s. Anthropic expects to get there sooner. Inference costs still eat over half of revenue at both labs, though that share is declining.
→ View original post on X — @kimmonismus, 2026-04-06 17:18 UTC
By
–
Okay this one seems real. First time ever an OSS model beats Sonnet 4.6(!!) on our evals. Now begins vibe testing, but this is promising. https://t.co/FBRV4k8QuS
— Flo Crivello (@Altimor) 6 avril 2026
Okay this one seems real. First time ever an OSS model beats Sonnet 4.6(!!) on our evals. Now begins vibe testing, but this is promising. Arcee.ai (@arcee_ai) Today we're releasing Trinity-Large-Thinking. Available now on the Arcee API, with open weights on Hugging Face under Apache 2.0. We built it for developers and enterprises that want models they can inspect, post-train, host, distill, and own. — https://nitter.net/arcee_ai/status/2039369121591120030#m
→ View original post on X — @clementdelangue, 2026-04-06 17:02 UTC
By
–
We've been landing token-efficiency improvements so you can do more in your sessions. If you have a session where usage felt particularly high, can you run /bug and post the feedback id? Feel free to tag me directly
By
–
Announcing SubStudio!
— Hassan (@nutlope) 6 avril 2026
Generate subtitles for any video in seconds with AI. 100% free & open source!
Powered by Whisper on @togethercompute and @FFmpeg via fluent-ffmpeg. pic.twitter.com/kItRvmDB4D
Announcing SubStudio! Generate subtitles for any video in seconds with AI. 100% free & open source! Powered by Whisper on @togethercompute and @FFmpeg via fluent-ffmpeg. [Translated from EN to English]
→ View original post on X — @scobleizer, 2026-04-06 17:00 UTC
By
–
Hmm there were no behavioral/model changes recently. If you see something weird (eg. the model refusing to do something) mind running /bug and posting the feedback id? Feel free to tag me
By
–
The desire to improve Google Translate by 1-3%, a tiny percentage, gave birth to the entire modern AI industry and trillions in market cap, outside of Google. BLEU score on MT seemed cool when I worked on it, but it punched waaaay above its weight as a guiding star.
→ View original post on X — @reza_zadeh, 2026-04-06 16:57 UTC