Amol (Head of Growth at @AnthropicAI
) just joined Twitter. Follow for free alpha. BTW, can you believe they hit $30B ARR before they even released Mythos?
GENERATIVE AI
-
Anthropic Reaches $30B ARR Before Mythos Launch
By
–
-
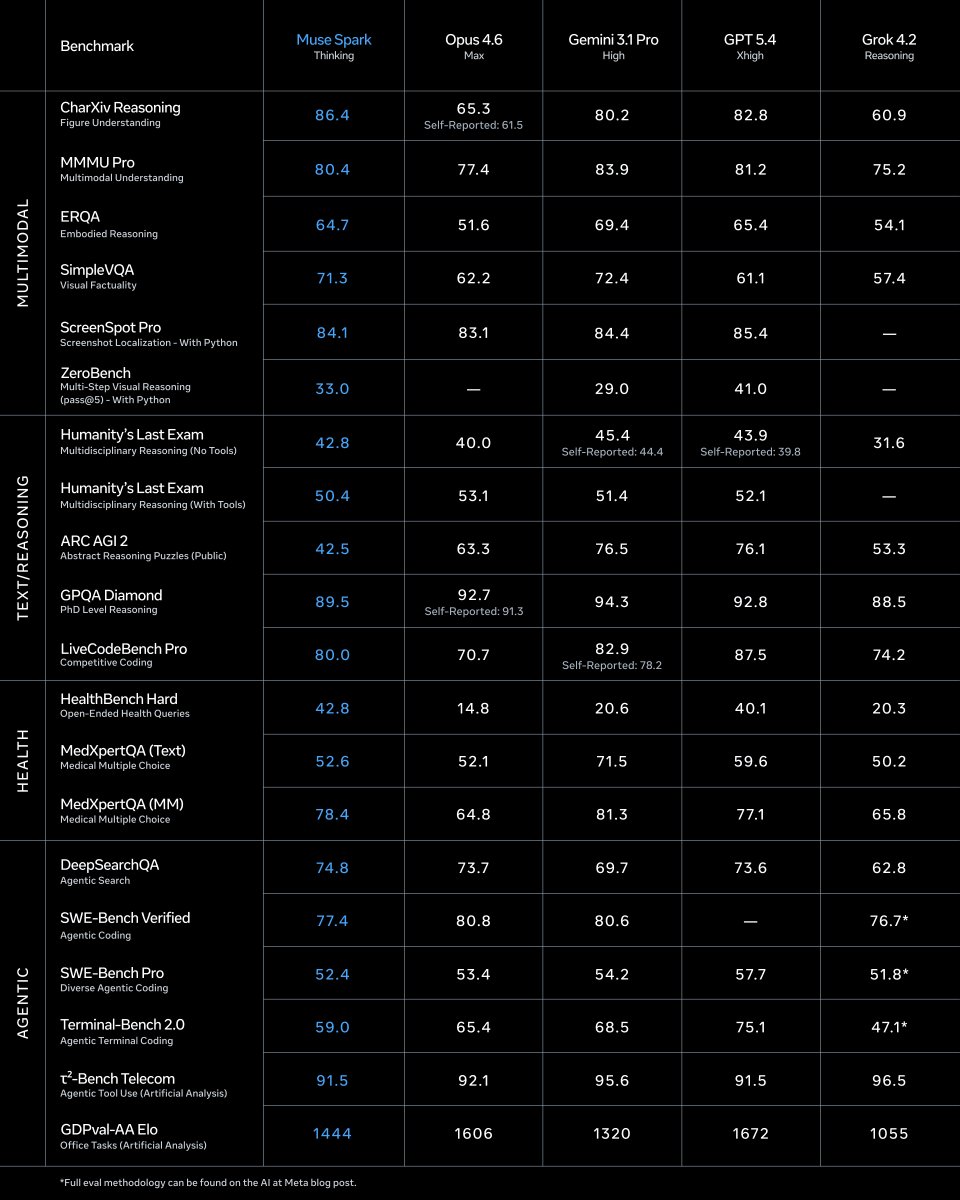
Meta Launches Muse AI Model Line After Llama 4 Setback
By
–
META RETURNS TO THE BATTLE! After the failure of Llama 4, Meta has spent the last year completely reorienting its entire AI strategy, and today it finally unveils its first (private) model, aiming to go head-to-head with the big players through its new Muse model line
-
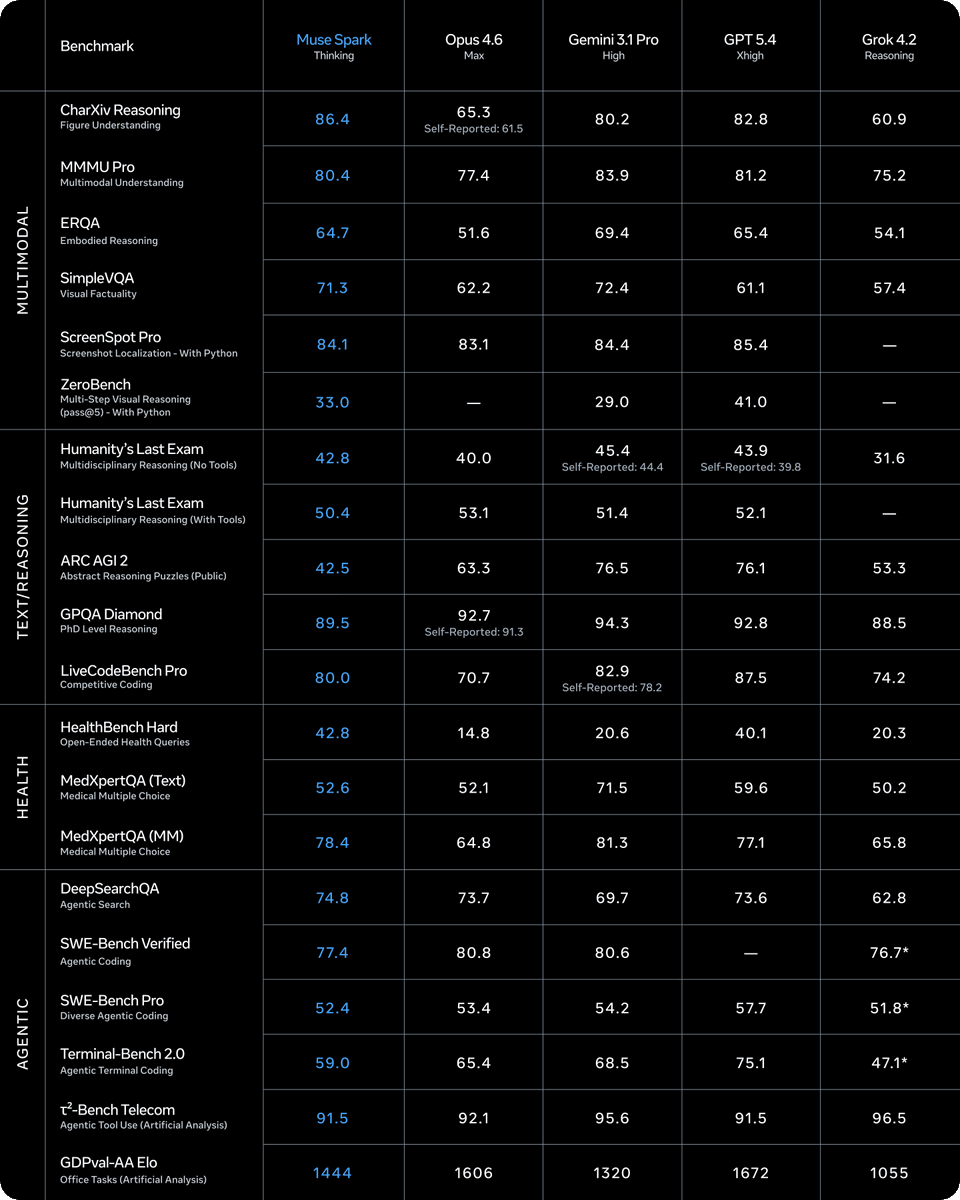
Meta’s Muse Spark: Multimodal AI Model with Impressive Reasoning Benchmarks
By
–


Meta Superintelligence Labsjust dropped Muse Spark, their first model after a full nine-month rebuild of their AI stack. the tl;dr (summary) It's a natively multimodal reasoning model that now powers Meta AI. It's competitive on reasoning and multimodal benchmarks, introduces a multi-agent "Contemplating mode," and Meta frames it as step one on a scaling ladder toward "personal superintelligence." Where it's strong: -Multimodal perception and visual reasoning (visual STEM, entity recognition, localization) -Health reasoning, built with input from 1,000+ physicians -Test-time reasoning efficiency, using thinking time penalties to compress reasoning tokens -Contemplating mode hits 58% on Humanity's Last Exam and 38% on FrontierScience Research, putting it in the ballpark of Gemini Deep Think and GPT Pro -Pretraining efficiency: reaches the same capability as Llama 4 Maverick with over 10x less compute Where it's weaker (Meta's own admission): -Long-horizon agentic systems -Coding workflows Key scaling findings: -RL compute scales smoothly with log-linear growth on pass@1 and pass@16 -Multi-agent orchestration scales performance without proportional latency increase -Phase transition behavior on AIME: the model first extends reasoning, then compresses it under length penalties, then extends again for higher accuracy My take: very good model, really surprised what meta offered here. And keep in mind: 99% of all instagram / facebook user dont need an LLM for doing academic reserach but for everyday reasoning. Well done, meta! Chubby♨️ (@kimmonismus) Lol what?! Meta has been cooking! These benchmarks are really freaking good holy!! — https://nitter.net/kimmonismus/status/2041918006779957407#m
→ View original post on X — @kimmonismus, 2026-04-08 16:42 UTC
-
CaP Evolution: Agentic Coding and Large Models as Primitives
By
–
Thx Stephen! But quite a bit has changed since 2022…agentic coding is evolving rapidly now and CaP can incorporate large models as primitives. We’re working on extensions and will share updates soon. https://t.co/XHlfRSkME3
— Ken Goldberg (@Ken_Goldberg) 8 avril 2026Thx Stephen! But quite a bit has changed since 2022…agentic coding is evolving rapidly now and CaP can incorporate large models as primitives. We’re working on extensions and will share updates soon. Stephen James (@stepjamUK) 𝗙𝗿𝗼𝗻𝘁𝗶𝗲𝗿 𝗹𝗮𝗻𝗴𝘂𝗮𝗴𝗲 𝗺𝗼𝗱𝗲𝗹𝘀 𝗰𝗮𝗻 𝗽𝗮𝘀𝘀 𝗹𝗮𝘄 𝗲𝘅𝗮𝗺𝘀. 𝗧𝗵𝗲𝘆 𝗰𝗮𝗻 𝘄𝗿𝗶𝘁𝗲 𝗽𝗿𝗼𝗱𝘂𝗰𝘁𝗶𝗼𝗻 𝗰𝗼𝗱𝗲. 𝗕𝘂𝘁 𝗮𝘀𝗸 𝘁𝗵𝗲𝗺 𝘁𝗼 𝘄𝗿𝗶𝘁𝗲 𝗮 𝗽𝗿𝗼𝗴𝗿𝗮𝗺 𝘁𝗵𝗮𝘁 𝗰𝗼𝗻𝘁𝗿𝗼𝗹𝘀 𝗮 𝗿𝗲𝗮𝗹 𝗿𝗼𝗯𝗼𝘁, 𝗮𝗻𝗱 𝘁𝗵𝗲𝘆 𝘀𝘁𝗶𝗹𝗹 𝗳𝗮𝗹𝗹 𝘀𝗵𝗼𝗿𝘁 𝗼𝗳 𝗮 𝗵𝘂𝗺𝗮𝗻 𝗲𝘅𝗽𝗲𝗿𝘁. That's the core finding from CaP-X, a new framework from NVIDIA, UC Berkeley, Stanford, and CMU that systematically benchmarks coding agents for robot manipulation. The underlying idea is not new. Code as Policy has been around since 2022/2023, and it is best understood as a modern evolution of Task and Motion Planning – a classical robotics paradigm where engineers manually decompose high-level goals into structured programs combining perception, planning, and control. What has changed is that instead of a human writing that code, a language model does it. It works well when the abstractions are high-level. It degrades significantly when models have to reason at the level human engineers actually work at: raw perception outputs, IK solvers, collision constraints. Here is what the research actually shows: 𝗧𝗵𝗲 𝗮𝗯𝘀𝘁𝗿𝗮𝗰𝘁𝗶𝗼𝗻 𝗴𝗮𝗽 𝗶𝘀 𝗿𝗲𝗮𝗹. Performance drops as you move from high-level primitives to low-level APIs. Not because the models lack intelligence, but because the scaffolding disappears. 𝗠𝘂𝗹𝘁𝗶-𝘁𝘂𝗿𝗻 𝗳𝗲𝗲𝗱𝗯𝗮𝗰𝗸 𝗿𝗲𝗰𝗼𝘃𝗲𝗿𝘀 𝗺𝗼𝘀𝘁 𝗼𝗳 𝘁𝗵𝗮𝘁 𝗹𝗼𝘀𝘀. Multi-turn feedback with execution traces and structured observations dramatically improves performance. Raw images alone actually hurt. 𝗥𝗟 𝗼𝗻 𝗮 𝘀𝗺𝗮𝗹𝗹 𝗺𝗼𝗱𝗲𝗹 𝘁𝗿𝗮𝗻𝘀𝗳𝗲𝗿𝘀 𝘇𝗲𝗿𝗼-𝘀𝗵𝗼𝘁 𝘁𝗼 𝘁𝗵𝗲 𝗿𝗲𝗮𝗹 𝘄𝗼𝗿𝗹𝗱. A 7B model fine-tuned with RL in simulation transfers zero-shot to a real Franka robot by reasoning over structured APIs. The takeaway is simple. The bottleneck is not model size. It is the feedback loop, the abstraction layer, and the system around the model. Credit: @letian_fu, Justin Yu, Karim El-Refai, Ethan Kou, @HaoruXue, @DrJimFan, and the full team across @nvidia, @UCBerkeley, @Stanford, and @CMU_Robotics And of course @AGIBOTofficial for providing the hardware in the attached video! What do you think is holding Code as Policy back from production deployment? Paper link in comments. — https://nitter.net/stepjamUK/status/2041878733531849153#m
→ View original post on X — @ken_goldberg, 2026-04-08 16:41 UTC
-
Motion: AI Video Agent for Motion Design Launch
By
–
introducing Motion, a video agent for tasteful motion design.
— Adish Jain ☕️ (@_adishj) 8 avril 2026
this launch video was made entirely with Motion. 👇🏽
comment "MOTION" to get early access + free credits.
tag @motion_so in any post on your X feed for a surprise.
here’s how it works + examples (thread): pic.twitter.com/CmeMgYPW6jintroducing Motion, a video agent for tasteful motion design. this launch video was made entirely with Motion. 👇🏽 comment "MOTION" to get early access + free credits. tag @motion_so in any post on your X feed for a surprise. here’s how it works + examples (thread):
→ View original post on X — @scobleizer, 2026-04-08 16:38 UTC
-
OpenAI and X: Concerns Over AI Safety Restraint
By
–
the biggest fear as noted is that openai and x (and perhaps others) would not show the same restraint.
-
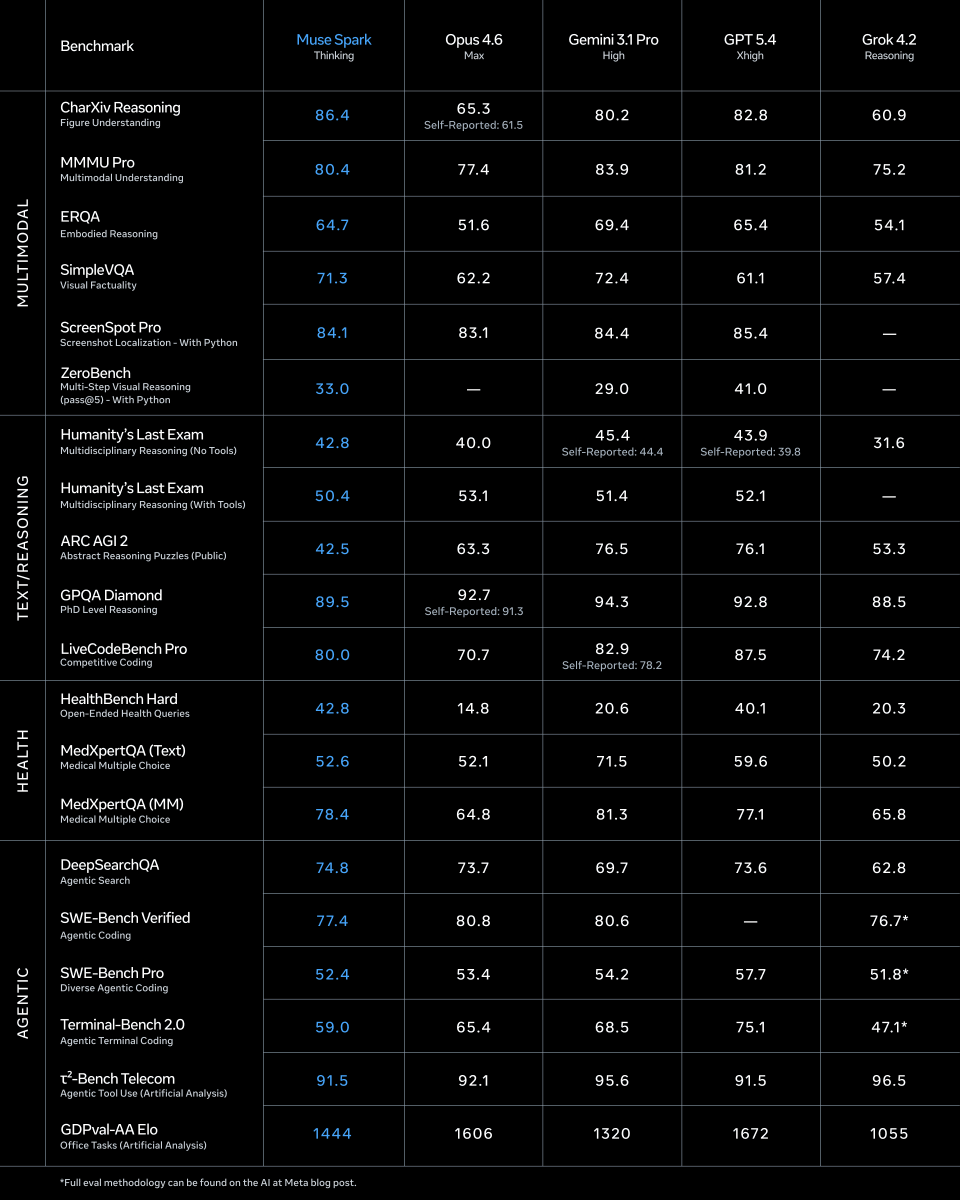
Meta’s New Muse Spark Model Delivers Impressive Benchmark Results
By
–

Lol what?! Meta has been cooking! These benchmarks are really freaking good holy!! Alexandr Wang (@alexandr_wang) 1/ today we're releasing muse spark, the first model from MSL. nine months ago we rebuilt our ai stack from scratch. new infrastructure, new architecture, new data pipelines. muse spark is the result of that work, and now it powers meta ai. 🧵 — https://nitter.net/alexandr_wang/status/2041909376508985381#m
→ View original post on X — @kimmonismus, 2026-04-08 16:36 UTC
-

Meta’s Muse Spark Rises to 4th in AI Arena
By
–

Meta jumped from last to the 4th place on Artificial Analysis arena with its newly released Muse Spark model. It also appears to be token efficient for its level of intelligence.
-
LFM2.5-VL-450M Vision-Language Model Now Available
By
–
Available today on @huggingface! huggingface.co/LiquidAI/LFM2…
-
Liquid AI Releases LFM2.5-VL-450M Tiny Vision-Language Model
By
–
New tiny VLM: LFM2.5-VL-450M
— Maxime Labonne @ ICLR (@maximelabonne) 8 avril 2026
> Supports bounding box prediction, object detection, and function calling
> Improved multilingual capabilities across 9 languages
> Enhanced instruction following for vision and text tasks https://t.co/diQjDO9RCX pic.twitter.com/hJqlV6YFcDNew tiny VLM: LFM2.5-VL-450M > Supports bounding box prediction, object detection, and function calling > Improved multilingual capabilities across 9 languages > Enhanced instruction following for vision and text tasks Liquid AI (@liquidai) Today, we release LFM2.5-VL-450M, a vision-language model built for real-time reasoning on edge devices. It processes a 512×512 image and returns structured outputs in ~240ms on-device. — https://nitter.net/liquidai/status/2041912441060143251#m