Bay Area Friends: Join us tomorrow at Orchestrating #GenAI Apps Meetup with NVIDIA and NetApp. We'll be discussing what it takes to build an #LLM serving platform at scale. Best of all it's free to attend, save your spot:
GENERATIVE AI
-
Why 10B Tokens Suffice for GPT Training Performance
By
–
Great question yes I was surprised that 10B seemed enough. I believe GPT-2 was trained on somewhere ~100B tokens. The reason we reach this performance in 10B tokens I think may be the following: 1. FineWeb could just be higher quality than WebText, on a per-token basis. This was
-

GPT-3 Hyperparameters Analysis and Model Scaling Expectations
By
–
ah ok these are gpt3 hparams. it sounds like this alone would be enough to beat GPT2, and its unknown if 290B more tokens would get it to match or beat GPT-3 Small looking forward to the 1.5b – fascinating to see these all documented and taught live!!
-
Anthropic vs OpenAI: The AI Competition Behind ChatGPT Launch
By
–
Para quien no ubique a Jan, aquí el salseo de la semana pasada. Recordemos también que Anthropic se fundó de equipos disidentes de OpenAI. Y recordemos también que OpenAI aceleró la salida de ChatGPT por miedo a Anthropic adelantándose con algo similar.
-
Explore and Compare All LLMs with ChatLLM Teams
By
–
Play around and compare and contrast all LLMs with ChatLLM Teams!https://t.co/5QdaueRsfN pic.twitter.com/avSTiUwLDQ
— Abacus.AI (@abacusai) 28 mai 2024Play around and compare and contrast all LLMs with ChatLLM Teams! https://
chatllm.abacus.ai -

Retailers Deploy Generative AI for Customer Experience Transformation Survey
By
–
How are #retailers planning to transform customer experiences with #generativeAI? Read our latest survey report to find out how many want to deploy AI in 2024 and the top use cases they're targeting. https://
nvda.ws/3UWBXni -
Reproduce GPT-2 124M in llm.c for $20 in 90 Minutes
By
–
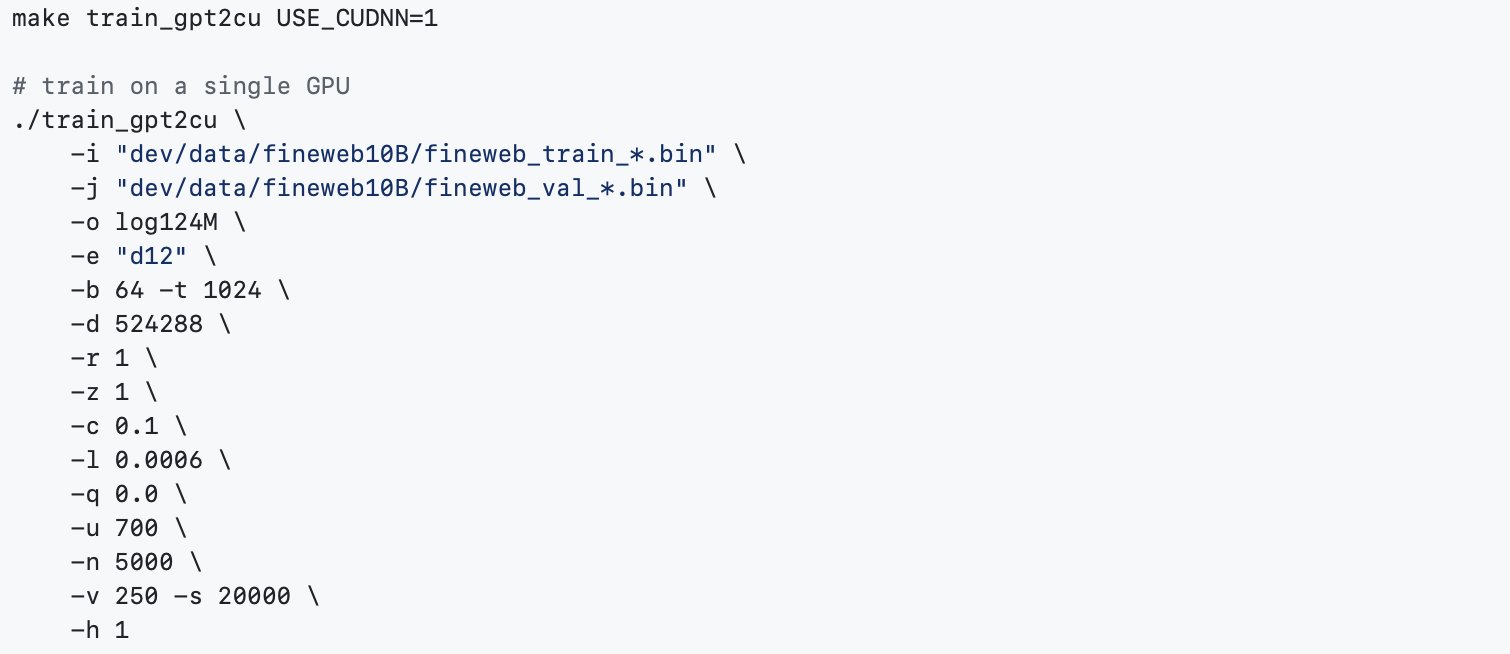
# Reproduce GPT-2 (124M) in llm.c in 90 minutes for $20 The GPT-2 (124M) is the smallest model in the GPT-2 series released by OpenAI in 2019, and is actually quite accessible today, even for the GPU poor. For example, with llm.c you can now reproduce this model on one 8X
-
AI Co-dependency: Why Writers Must Shape the Conversation
By
–
Must-read on our AI co-dependency & proof why we need writers to join the conversation.“It occurred to me that I wasn’t really training Brenda to think like a human, Brenda was training me to think like a bot, and perhaps that had been the point all along.”
-
Beyond GPT-5: Future AI Models and OpenAI’s Naming Strategy
By
–
Si me preguntan (y sin tener evidencias) yo creo que no es GPT-5, que eso debe de estar más avanzado. Que debe ser un próximo modelo y que como ha recordado Sam en otras ocasiones ni siquiera siga la nomenclatura GPT.
-

OpenAI Begins Training Next Major Language Model
By
–
El misterio de la jornada es el texto escrito por OpenAI en un nuevo blog post en el que anuncian que recientemente han comenzado a entrenar su próximo gran modelo… ¿GPT-5? ¿Tan tarde? ¿GPT-5o? ¿GPT-6?