
Here's how you can easily fine-tune latest llama 3.2 (1b and 3b) locally and on cloud:
GENERATIVE AI
-
Starlink reaches 4M users; AI video and datacenters advance
By
–
Les sources du #FlashTweet sont ici https://
techcrunch.com/2024/09/26/sta
rlink-will-hit-4-million-subscribers-this-week-spacex-president-says/?utm_source=pocket_shared
… https://
techcrunch.com/2024/09/26/run
way-earmarks-5m-to-fund-up-to-100-films-using-ai-generated-video/?utm_source=pocket_shared
… https://
theregister.com/2024/09/26/bac
kstone_ai_datacenter?utm_source=pocket_shared
… https://
techcrunch.com/2024/09/26/goo
gles-notebooklm-enhances-ai-note-taking-with-youtube-audio-file-sources-sharable-audio-discussions/?utm_source=pocket_shared
… https://
frenchweb.fr/ynsect-icone-d
e-la-frenchtech-bascule-dans-un-plan-de-sauvegarde/449245
… -

Starlink reaches 4M subscribers, Runway funds AI video production
By
–
Prêt pour votre rendez-vous avec l’innovation ?
Starlink passe la barre des 4 millions d’abonnés
Runway va financer des vidéos AI à hauteur de 5 M$
Le plus grand datacenter d’Europe coûtera 10 Mrds £
Notebook de Google résume les vidéos YouTube
Ynsect en sauvegarde -
Discussion on AI-guided writing features
By
–
Cannot say it is a competing product yet, but quite a similar feature > “AI-guided writing”
-
Building Function Management System with AI Capabilities
By
–
I’m starting with functions for managing functions (create, update, delete, find, etc), and just enough ai ones to create new ones (LLM call, embed, similarity search).
-
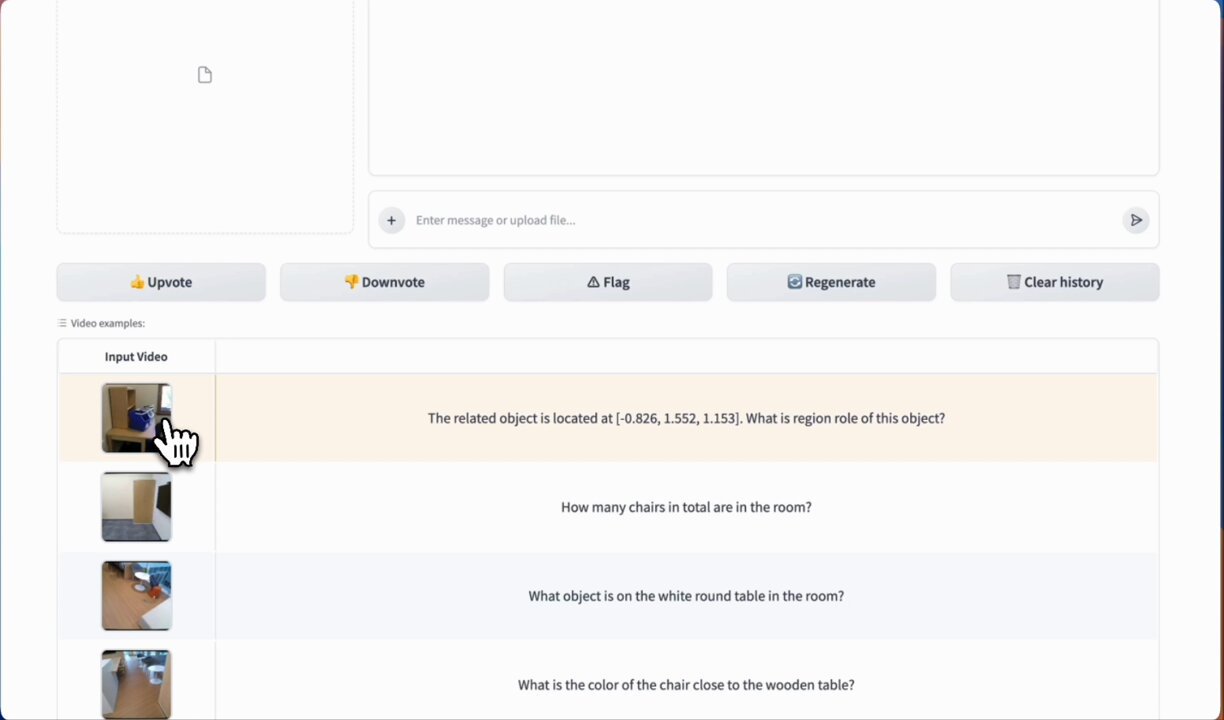
LLaVA-3D: Empowering Large Multimodal Models with 3D Awareness
By
–
LLaVA-3D
— AK (@_akhaliq) 27 septembre 2024
A Simple yet Effective Pathway to Empowering LMMs with 3D-awareness
Recent advancements in Large Multimodal Models (LMMs) have greatly enhanced their proficiency in 2D visual understanding tasks, enabling them to effectively process and understand images and videos.… pic.twitter.com/pbyiLnBhr6LLaVA-3D A Simple yet Effective Pathway to Empowering LMMs with 3D-awareness Recent advancements in Large Multimodal Models (LMMs) have greatly enhanced their proficiency in 2D visual understanding tasks, enabling them to effectively process and understand images and videos.
-
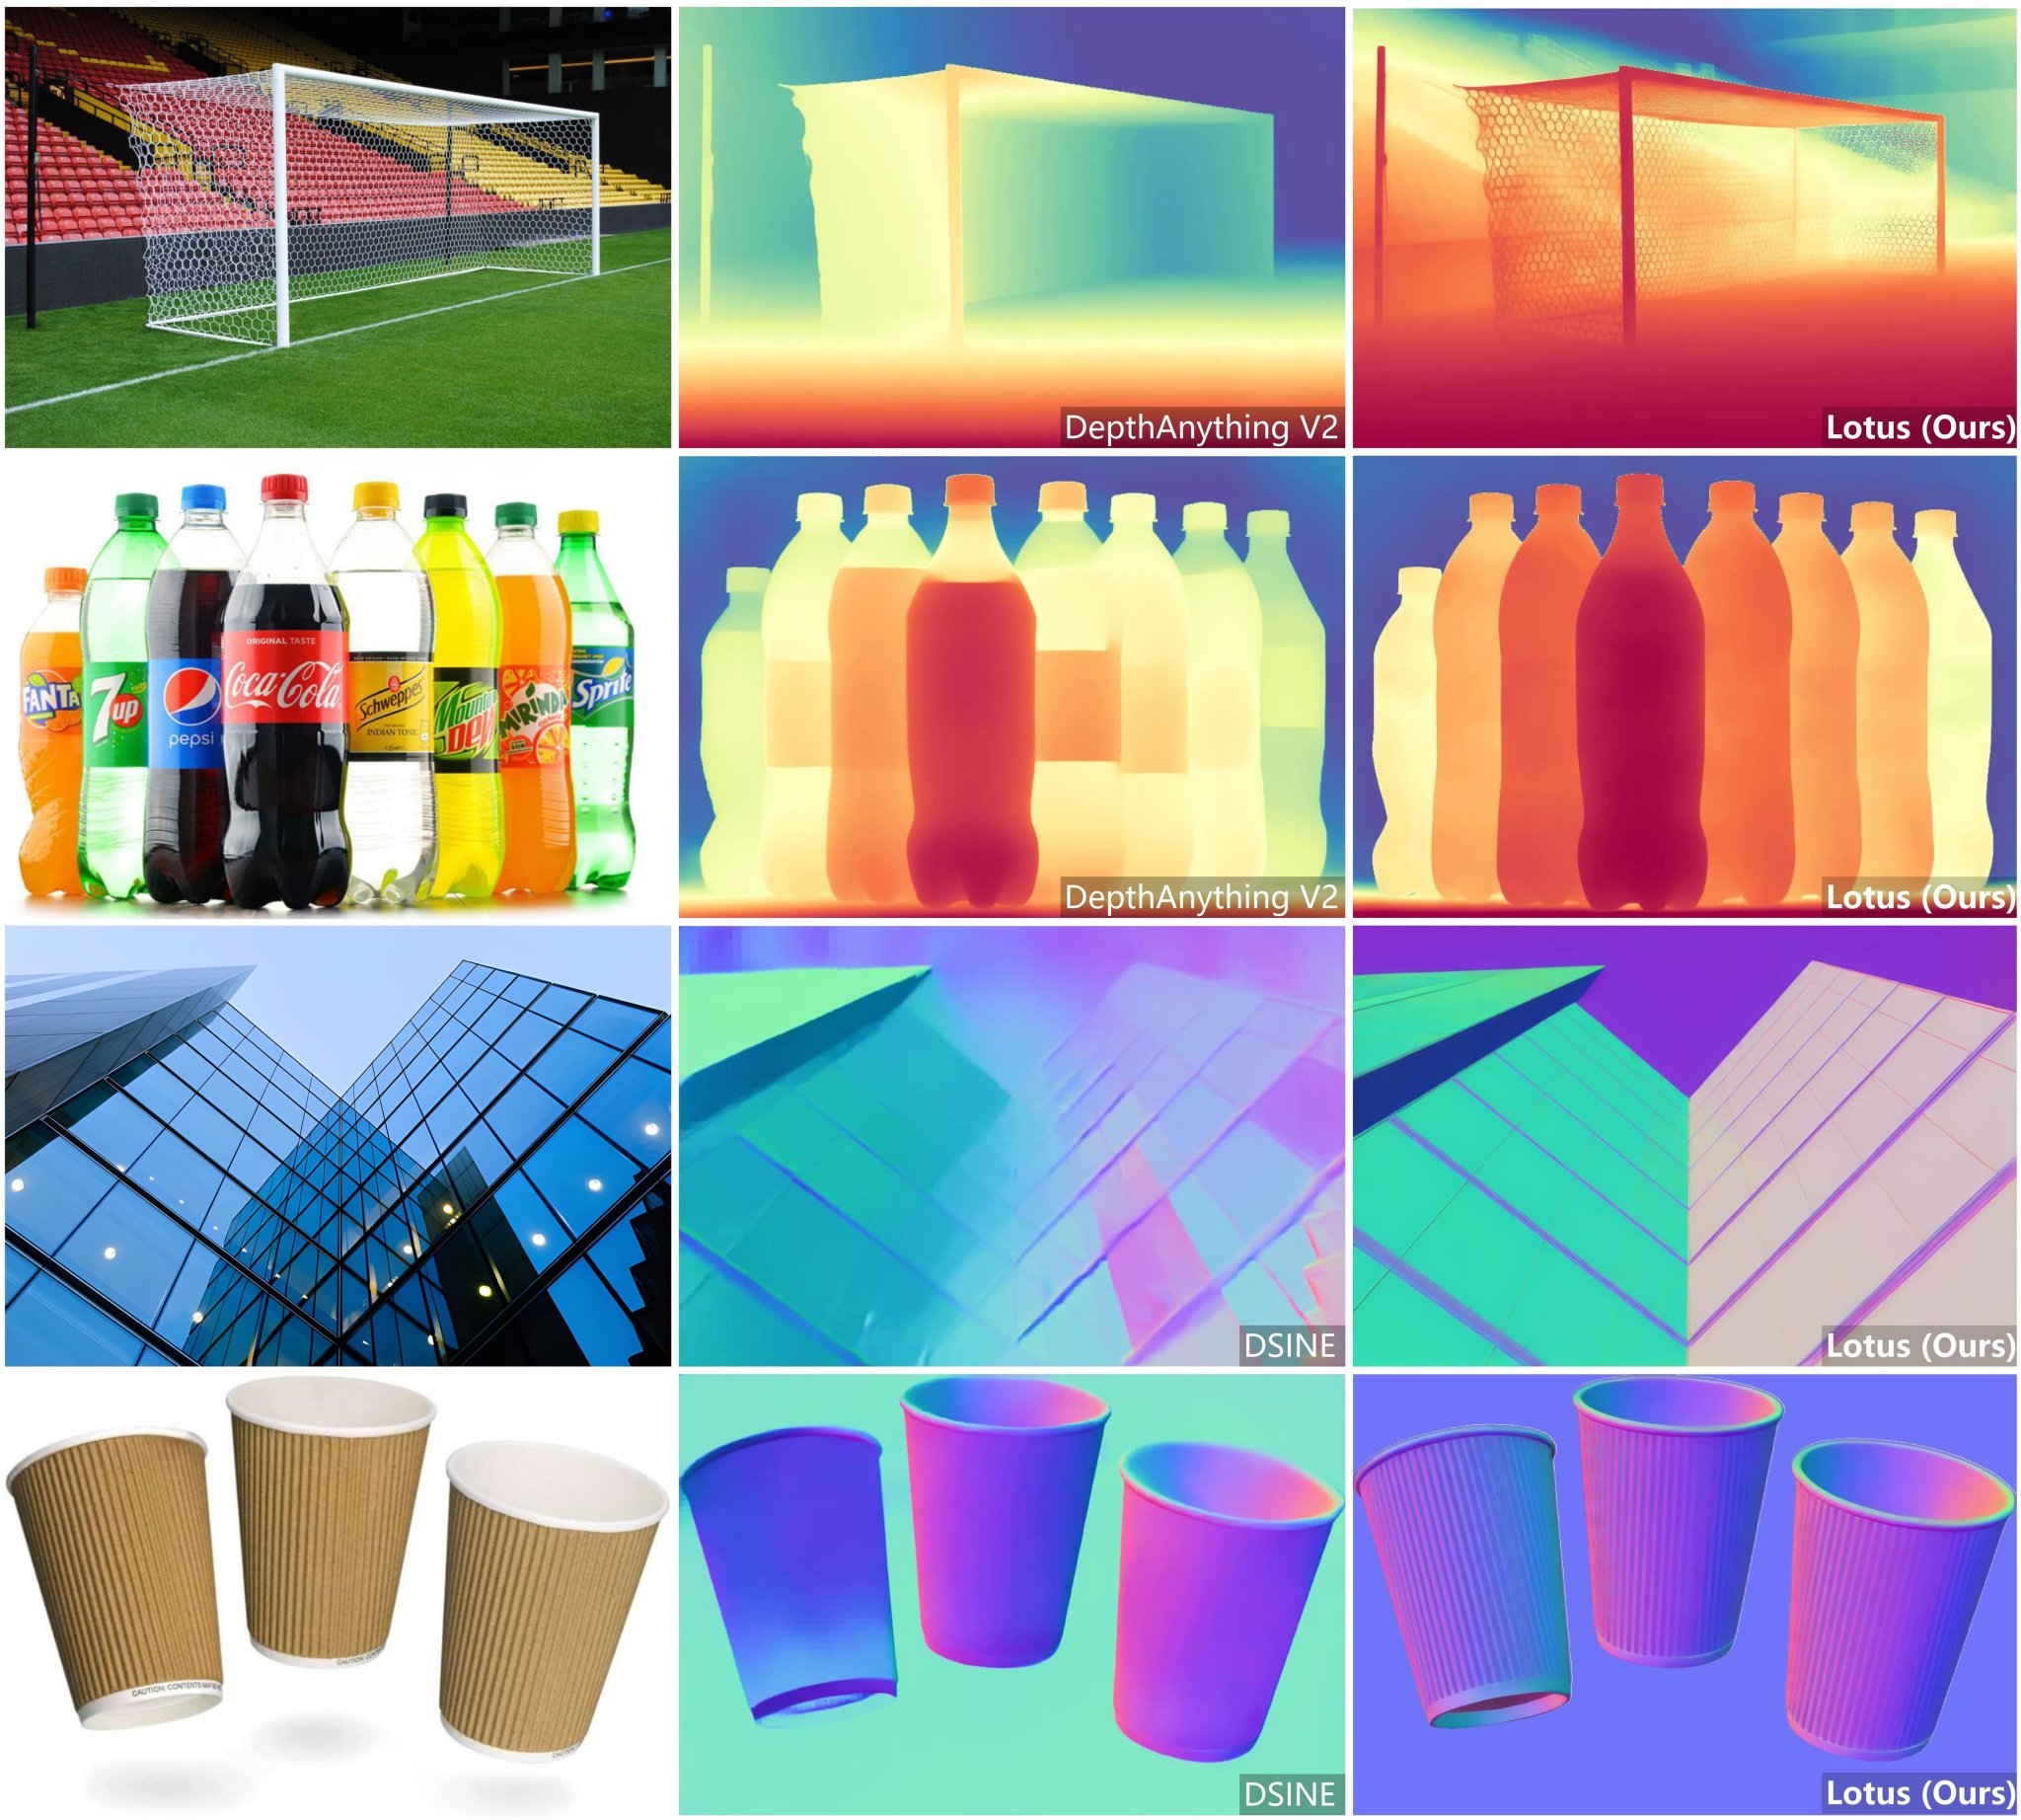
Lotus: Diffusion-Based Visual Foundation Model for Dense Prediction
By
–
Lotus Diffusion-based Visual Foundation Model for High-quality Dense Prediction Leveraging the visual priors of pre-trained text-to-image diffusion models offers a promising solution to enhance zero-shot generalization in dense prediction tasks. However, existing methods often
-
EMOVA: Language Models with Multimodal Emotions and Expression
By
–
EMOVA
— AK (@_akhaliq) 27 septembre 2024
Empowering Language Models to See, Hear and Speak with Vivid Emotions
discuss: https://t.co/QifoJVP166
GPT-4o, an omni-modal model that enables vocal conversations with diverse emotions and tones, marks a milestone for omni-modal foundation models. However, empowering… pic.twitter.com/UBIT587NmlEMOVA Empowering Language Models to See, Hear and Speak with Vivid Emotions discuss: https://
huggingface.co/papers/2409.18
042
… GPT-4o, an omni-modal model that enables vocal conversations with diverse emotions and tones, marks a milestone for omni-modal foundation models. However, empowering -

MaskLLM: Learnable Semi-Structured Sparsity for Large Language Models
By
–
MaskLLM Learnable Semi-Structured Sparsity for Large Language Models discuss: https://
huggingface.co/papers/2409.17
481
… Large Language Models (LLMs) are distinguished by their massive parameter counts, which typically result in significant redundancy. This work introduces MaskLLM, a learnable -
Small Language Models Refine Pre-training Data Quality at Scale
By
–
Programming Every Example: Lifting Pre-training Data Quality like Experts at Scale https://
huggingface.co/papers/2409.17
115
…
we demonstrate that even small language models, with as few as 0.3B parameters, can exhibit substantial data refining capabilities comparable to those of human experts.