Can AI agents see into the future before acting? A team from UIUC, THU, JHU, and Columbia tested exactly that. They gave agents generative world models—external simulators that could predict outcomes before taking action. The result? Most agents refuse to simulate (under 1%
GENERATIVE AI
-
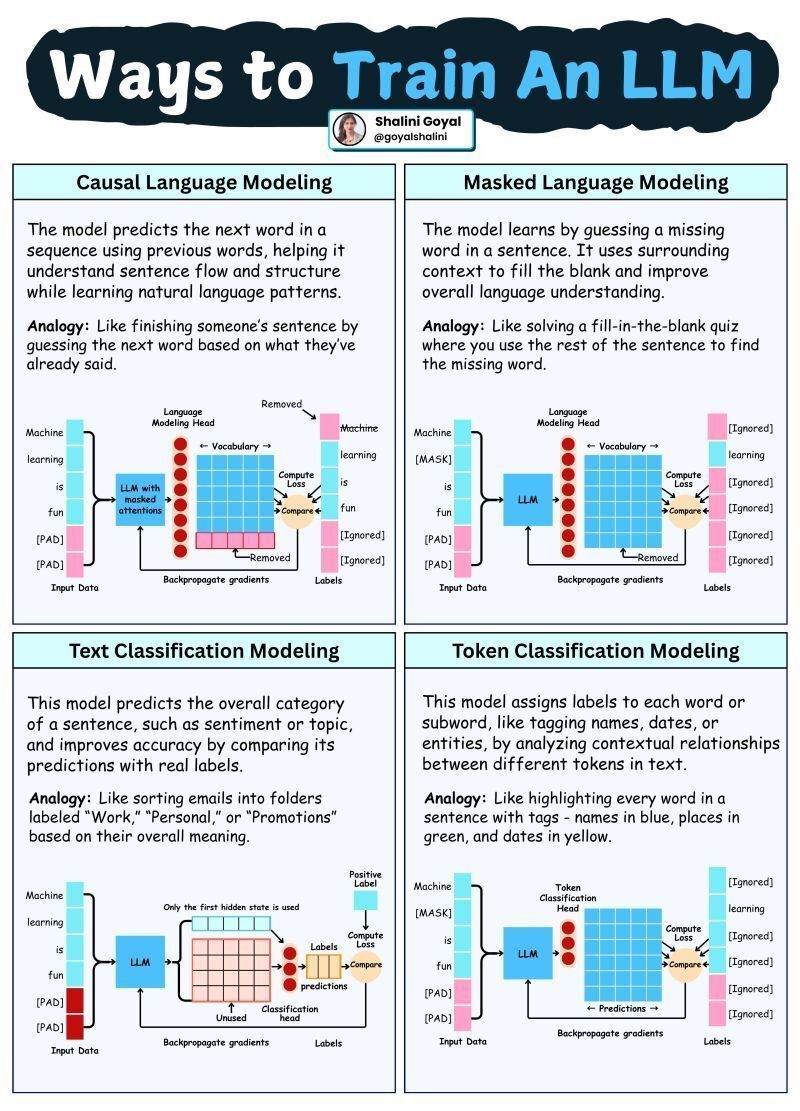
Ways to Train an LLM
By
–
Ways to Train an #LLM
by @goyalshaliniuk #GenAI #ArtificialIntelligence #MachineLearning #ML -
Generative AI populates 3D metaverse canvases
By
–
Generative AI is actually going to populate the otherwise empty 3d canvas that is the so called metaverse https://t.co/JKx2IhtrEg
— Bilawal Sidhu (@bilawalsidhu) 10 mai 2026Generative AI is actually going to populate the otherwise empty 3d canvas that is the so called metaverse
-
Popular AI writings from 2022-2023 still influence current models
By
–
I suspect there was a moment, probably 2022-2023, where anything you wrote publicly about AI that was popular is likely to still have influence over current models. Since then, the open internet has become less key to training but the models remain very 2022-brained in many ways
-
Mitigating AI Hallucinations Through Prompt Engineering Strategies
By
–
7. Never trust tone as a reliability signal. Opus 4.7 is unusually confident when it's wrong. It told one user "strawberry" has two Ps. Build verification INTO your prompts: → "cite the source for every claim"
→ "flag uncertainty in tags"
→ "list 3 ways this -
Optimizing AI Model Verbosity Through Prompt Engineering
By
–
5. Override verbosity. Explicitly. Opus 4.7 defaults to thorough. If you want concise, you have to ASK. "Summarize this article" "Summarize in 3 bullets. No preamble. Output directly." You get what you specify. Never what you assume.
-
Optimizing LLM response quality using XML tags as attention anchors
By
–
3. Switch from markdown to XML tags. Opus 4.7 responds to XML structure the way other models respond to markdown headers. Wrap your sections in , , , . The model treats them as attention anchors. Same content, dramatically better
-
Improving AI Prompt Precision for Better Model Performance
By
–
2. Stop writing prompts that assume the model "gets it." 4.6 prompt: "help me with my pitch deck"
(4.6 inferred you wanted structure + hooks + content tips) 4.7 prompt: "review the 10 slides below. flag weak hooks, missing stats, and confusing transitions. output as a -
Adjusting Prompting Strategies for Opus 4.7 Behavior Changes
By
–
The shift is simple but devastating: Opus 4.6 inferred your intent and filled in the gaps.
Opus 4.7 does EXACTLY what you ask. Nothing more. Translation: the same prompt now produces narrower, terser, sometimes broken results. Here's how to fix it -
Prompt Engineering Adjustments for Claude 3.7 Opus
By
–
RIP your old Claude prompts Opus 4.7 dropped 3 weeks ago and it follows instructions LITERALLY now. It scores 87.6% on SWE-bench (vs 80.8% on 4.6) but every prompt tuned for 4.6 is silently failing. 7 fixes that stopped my outputs from getting worse: