Sonnet 4.6 is live on ChatLLM by Abacus A Pretty big launch.
Feels very close to Opus-level intelligence, but at Sonnet prices.
Honestly, a great pick for simple coding tasks.
GENERATIVE AI
-

Sonnet 4.6 Launch: Opus-Level Intelligence at Sonnet Prices
By
–
-

Sonnet-4.6 Dominates Latest AI Model Benchmarks and Evaluations
By
–
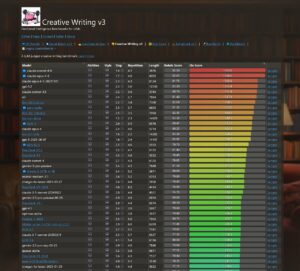

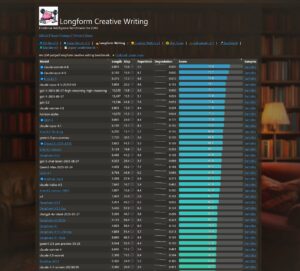
Sonnet-4.6 takes top place on all my evals: EQ-Bench, Creative writing, Longform writing & Judgemark. Opus 4.6 within margin of error. GLM-5 and Qwen3.5-397B nipping at their heels.
→ View original post on X — @maximelabonne, 2026-02-18 21:33 UTC
-
Tool Discipline Improves AI Reasoning Better Than Scale
By
–
Key insight: tool discipline > scale. Instead of complex multi-table training, we reinforced reliable tool use on simple queries — and saw transfer to 12-step reasoning tasks (59.7% Pass@1).
-
Snorkel Releases Agentic RL Eval Environment and Finance Reasoning Benchmark
By
–
Snorkel contributed: • An agentic RL eval environment • FinQA-Reasoning dataset • Finance Reasoning benchmark Full technical breakdown from the rLLM team + our enterprise takeaways here:
-

4B Model Outperforms 235B on Financial Reasoning Tasks
By
–
A 4B model > 235B on financial reasoning. We partnered with @rllm_project to fine-tune Qwen3-4B-Instruct-2507 — and it outperformed Qwen3-235B-A22B on expert-curated financial benchmarks.
-

Claude Code Enhances AI Safety Through Uncertainty Recognition
By
–
Claude Code also encourages oversight by stopping to ask questions. On complex tasks, Claude Code pauses for clarification more than twice as often as humans interrupt it. Training models to recognize uncertainty is an important, under-appreciated safety property.
-

User Experience Shift: Interruptions Increase With Claude Code Experience
By
–
But interruptions also increase with experience. New users interrupt Claude Code in 5% of turns, compared to 9% for more experienced users. This suggests a shift from approving each action to delegating and interrupting when needed.
-

User Oversight Strategy Shifts with AI Experience
By
–
As users gain experience, their oversight strategy shifts. New users approve each action individually. By 750 sessions, over 40% of sessions are fully auto-approved.
-

Claude Code Autonomy Growing: 99.9th Percentile Turns Double
By
–
Most Claude Code turns are short (median ~45 seconds). But the longest turns show where autonomy is heading. In three months, the 99.9th percentile turn duration nearly doubled, from under 25 minutes to over 45 minutes. This growth is smooth across model releases.
-
AI Productivity Gains Double US Economic Growth in 2025
By
–
For a long time, we saw "AI everywhere but in the productivity data". In 2025, my estimate (based on employment and GDP numbers) is that US productivity growth will be about 2.7% for 2025, roughly double the average for the prior 10 years. It's volatile, but in the right