Anthropic just built Claude specifically for investment banking. Wall Street Prep's 2026 benchmark ranked Claude #2 for finance tasks, with a score of 5.5 out of 10 – ahead of Copilot (4.4) and ChatGPT (2.5). Most finance prompts circulating on X are basic role assignments. No
GENERATIVE AI
-
Codex App: AI Transforms Software Development Into Task Delegation
By
–
holy sht.. AI just changed how software gets built. Codex App might be the closest thing to a GPT-3 moment for development. For years, AI coding tools lived inside terminals. Claude Code, Codex CLI, all incredibly powerful, but they still felt like tools built by developers, for developers. Flexible? absolutely. But also fragmented, full of setup, plugins, MCP servers, and custom workflows. Great for engineers. Not exactly a product for everyone else. What Codex changes isn’t just the model. It’s the interface of development. Instead of stitching together tools, environments and scripts, you simply talk to the system. Behind the scenes, agents read your codebase, modify files, install dependencies and execute tasks. Software creation starts to feel less like programming and more like delegating work. The moment it clicked for me was simple. During the OpenClaw wave I bought a Mac mini and set up a fresh environment. Normally the first installs would be npm or brew. This time it was Codex. I gave it full access and asked it to install everything needed to run the project. Dependencies, environment setup, configuration, runtime. All from a single prompt. Watching the system configure itself without touching the terminal once felt like looking at the next interface of computing. Not because AI wrote code. But because the computer started executing intentions instead of commands. Most people think AI will democratize coding by generating code faster. But that’s not the real shift. The real shift is that software development is slowly moving from writing code to assigning tasks to agents. Historically computing had three main interfaces. CLI for engineers, GUI for consumers, APIs for systems. AI introduces a new one. The agent interface. You don’t operate the software anymore. You tell systems what outcome you want and they orchestrate the process. If that interface becomes mainstream, the impact goes far beyond coding. It changes how startups are built, how products are shipped, and how technical the world needs to be to create software. Codex App might be one of the first glimpses of that future.
→ View original post on X — @arrakis_ai, 2026-03-06 12:32 UTC
-
ArcFlow: two-step high-fidelity AI image generation
By
–
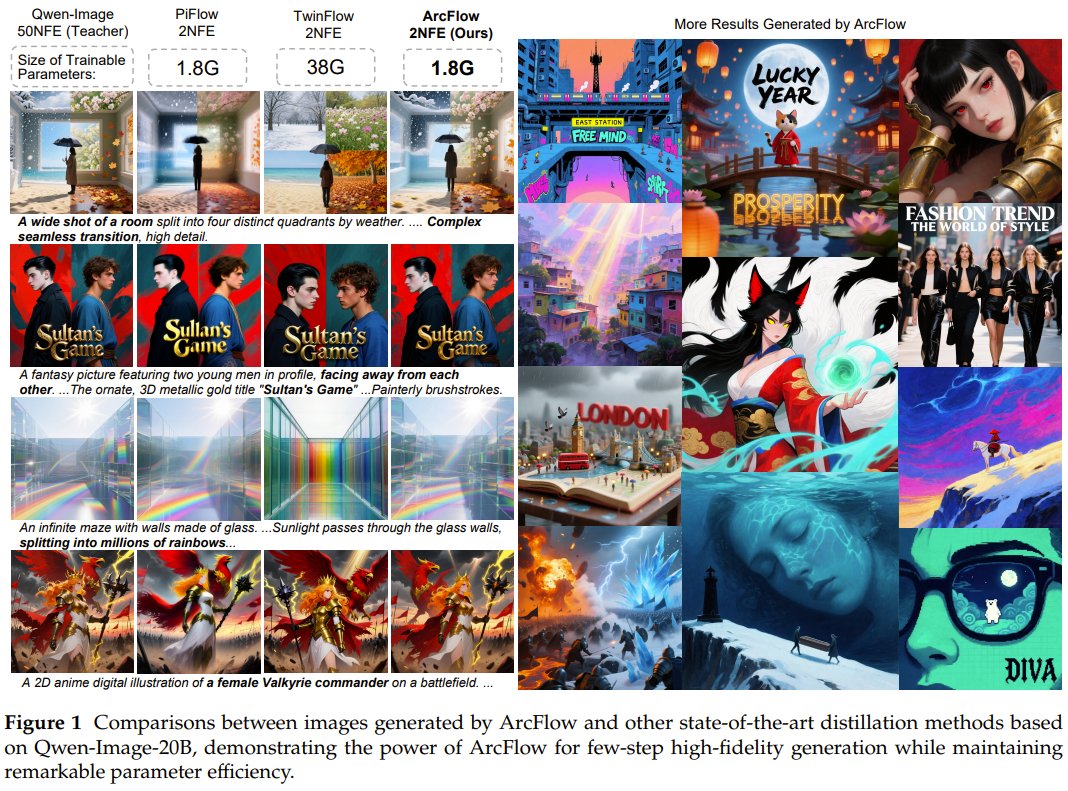
Cool, now it's possible to generate high-fidelity AI images in just two steps! Enter ArcFlow from Fudan University and Microsoft Research Asia. While most tools use straight-line shortcuts that sacrifice quality, ArcFlow uses a non-linear approach that follows the natural,
-
OpenAI GPT-5.4: Beyond Scale in AI Race
By
–
Everyone keeps saying the AI race is about bigger models. More parameters.
More data.
More compute. That has been the playbook for the last two years. But when I looked at OpenAI’s new release this week, one detail caught my attention. OpenAI introduced 𝐆𝐏𝐓-𝟓.𝟒, its -
53 Slides on Post-Training Algorithms and Data Quality
By
–
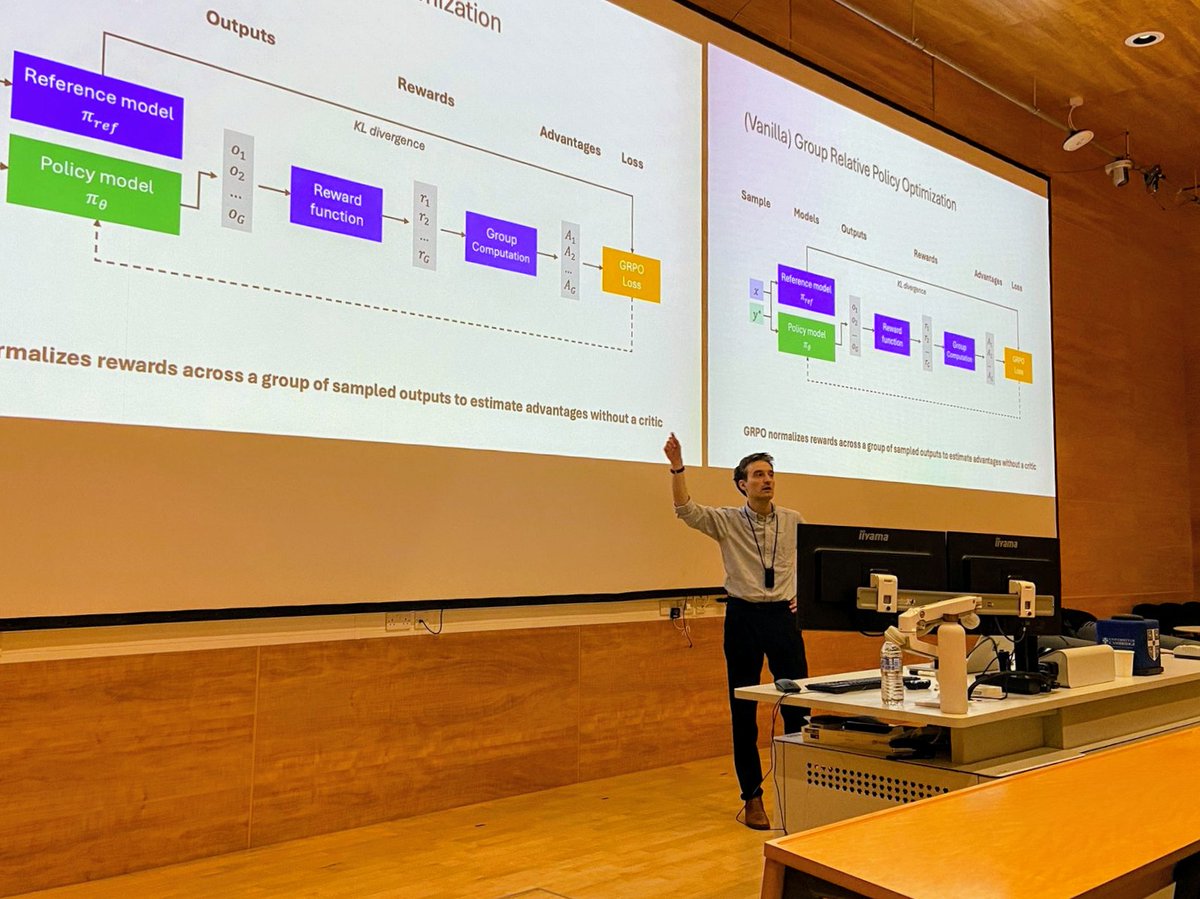
I'm releasing 53 slides on post-training, covering core algorithms like DPO and GRPO, as well as data quality, synthetic data pipelines, and on-policy training. I had the pleasure of presenting it yesterday as a guest lecturer in Cambridge, UK
→ View original post on X — @maximelabonne, 2026-03-06 10:45 UTC
-
Models Know Longer Isn’t Always Better
By
–
the deeper point here connects to something the field keeps rediscovering. we trained reasoning models to think longer. then we discovered longer doesn't mean better. now this paper shows the models themselves already know that. they're generating stop signals that our inference
-
DeepSeek and Qwen3 performance improvements
By
–
specific numbers worth sitting with: > DeepSeek-R1-7B on MATH-500: 93% accuracy (up from 91.6%), tokens cut from 3,871 to 2,141 > DeepSeek-R1-1.5B on AIME 2025: accuracy jumps 6.2 percentage points > Qwen3-8B: response length halved from 18,342 to 9,183 tokens with no accuracy
-
SAGE-RL: Simple RL Training Modification
By
–
then they fold it into training with SAGE-RL. dead simple modification: in standard reinforcement learning (GRPO), you sample 8 responses per question. SAGE-RL replaces 2 of those 8 with SAGE-generated samples. the other 6 stay normal. one-line code change. the model learns to
-
SAGE: Efficient Reasoning with Confidence Checks
By
–
their solution: SAGE (Self-Aware Guided Efficient Reasoning). instead of generating token by token, SAGE extends chains in whole reasoning steps. after each step, it checks: is the model confidently signaling it wants to stop? if yes, reasoning ends. no fine-tuning. no new
-
Researchers test AI self-awareness in reasoning
By
–
here's where it gets interesting. the researchers probed whether models internally "know" they're done. they introduced TSearch, which scores partial reasoning traces by cumulative log-probability across the entire chain, not just the next token. when you let the model explore