We’re moving from “ask AI anything” → to “AI understands everything around you.” That’s a fundamental interface shift. If you’re building products, this changes UX, data strategy, and distribution. I break this down in this latest video with Meta. Curious how you see this
DATA
-

Meta prepares ‘Hatch’ AI agent on social data
By
–
META : An upcoming always-on AI Agent called "Hatch" from Meta will be available on a waitlist and grounded in social data from Instagram and Facebook. > According to The Information, Meta is targeting internal testing of Hatch by the end of June, with mock environments built
-

Implementing Neural Networks for Image Detection
By
–
Quand on m’a invité à cette conf, j’ai directement proposé de faire une conf sur tout sauf de l’IA générative. Donc, pendant 1 h, bénévolement, je vais pouvoir vous expliquer et implémenter devant vous des réseaux de neurones pour faire de la détection sur des données d’imagerie
-
Four Benefits of Data Augmentation: Overfitting, Robustness, Small Data, Soft Boundaries
By
–
The four benefits in order of impact: 1. Prevents overfitting (the big one)
2. Adversarial robustness
3. Augments small datasets
4. Softer decision boundaries Used by experts. Skipped by most novices. Don't be a novice. -
Four Key Benefits of Data Augmentation: From Overfitting to Decision Boundaries
By
–
The four benefits in order of impact:
— Satya Mallick (@LearnOpenCV) 7 mai 2026
1. Prevents overfitting (the big one)
2. Adversarial robustness
3. Augments small datasets
4. Softer decision boundaries
Used by experts. Skipped by most novices. Don't be a novice. pic.twitter.com/eK6lhglg6oThe four benefits in order of impact: 1. Prevents overfitting (the big one)
2. Adversarial robustness
3. Augments small datasets
4. Softer decision boundaries Used by experts. Skipped by most novices. Don't be a novice. -
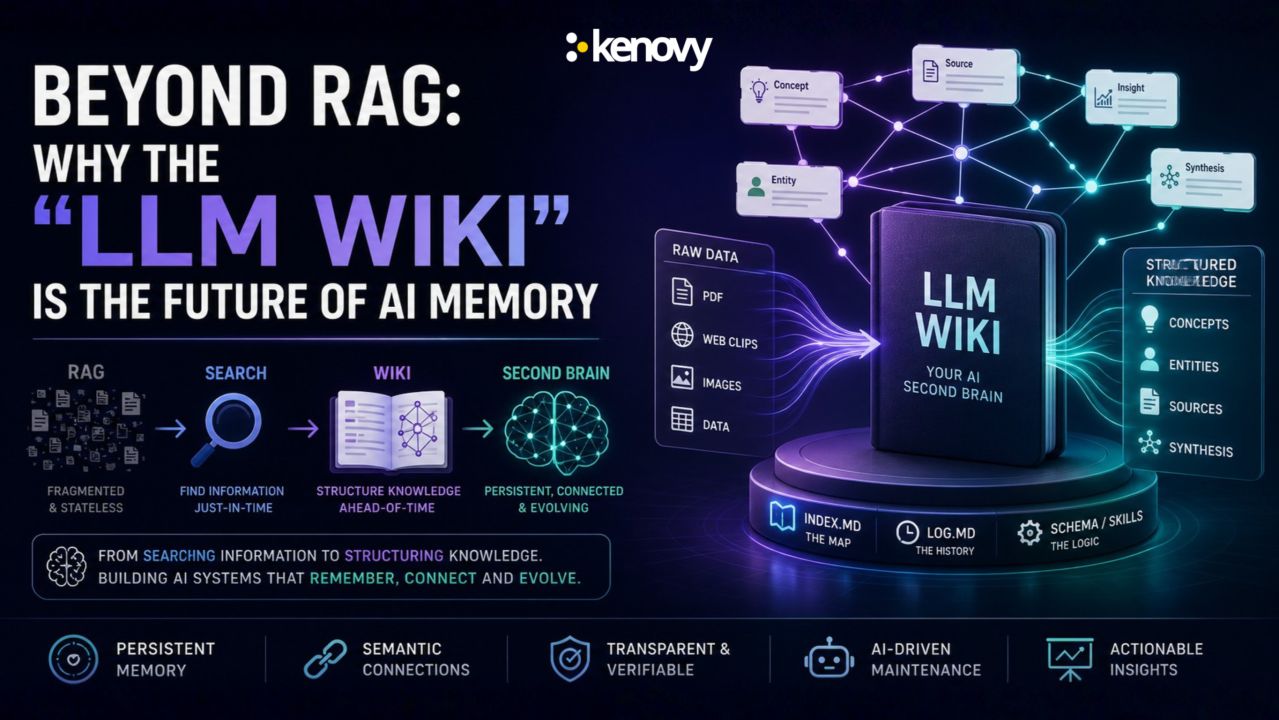
AI memory future: from retrieval to LLM Wiki compilation
By
–
RAG is already becoming the “old way” The future of AI memory is not retrieval.
It’s compilation. Here’s the shift in one sentence: From searching information To structuring knowledge The new model? LLM Wiki Instead of: Chunking documents Running similarity -
AI geniuses by 2028 require hired forward-deployed engineers
By
–
Labs; “we will have a nation of geniuses in a data center by 2028, capable of beating humans at every task, but you will need to hire our newly trained forward-deployed engineers for a six month engagement to deploy them to a single project”
-

Top AI stories: partnerships, trials and tools
By
–
Top stories in AI today: – Anthropic, SpaceX partner in new compute deal
– Mira Murati speaks out in Musk vs. OpenAI trial
– Use Claude Design’s slide decks feature like a pro
– DeepMind picks EVE Online game as next AI testbed
– 4 new AI tools, community workflows, and more -
Discussion on Foundation Model Approaches for Tabular Data
By
–
We are not working on foundation models for tabular data. We don't believe that is a very good approach.
-

Quebec Launches AI-First Sovereignty Initiative
By
–
http://
QUEBEC.AI launches Sovereign AI: AI‑First sovereignty = capability under control. Data, infrastructure, agents, proof, governance. Quebec enters AI‑First sovereignty: build, govern, secure, benefit. https://
quebecartificialintelligence.com/sovereign-ai #AIFirst #QuebecAI #QuebecIA