Beware of AI 'model collapse': How training on synthetic data pollutes the next generation Oxford scholars found that large language models fed a diet of 'cannibal' data, created by other LLMs, sink into complete gibberish. @AIatMeta @OpenAI @Nature @iliaishacked
DATA
-
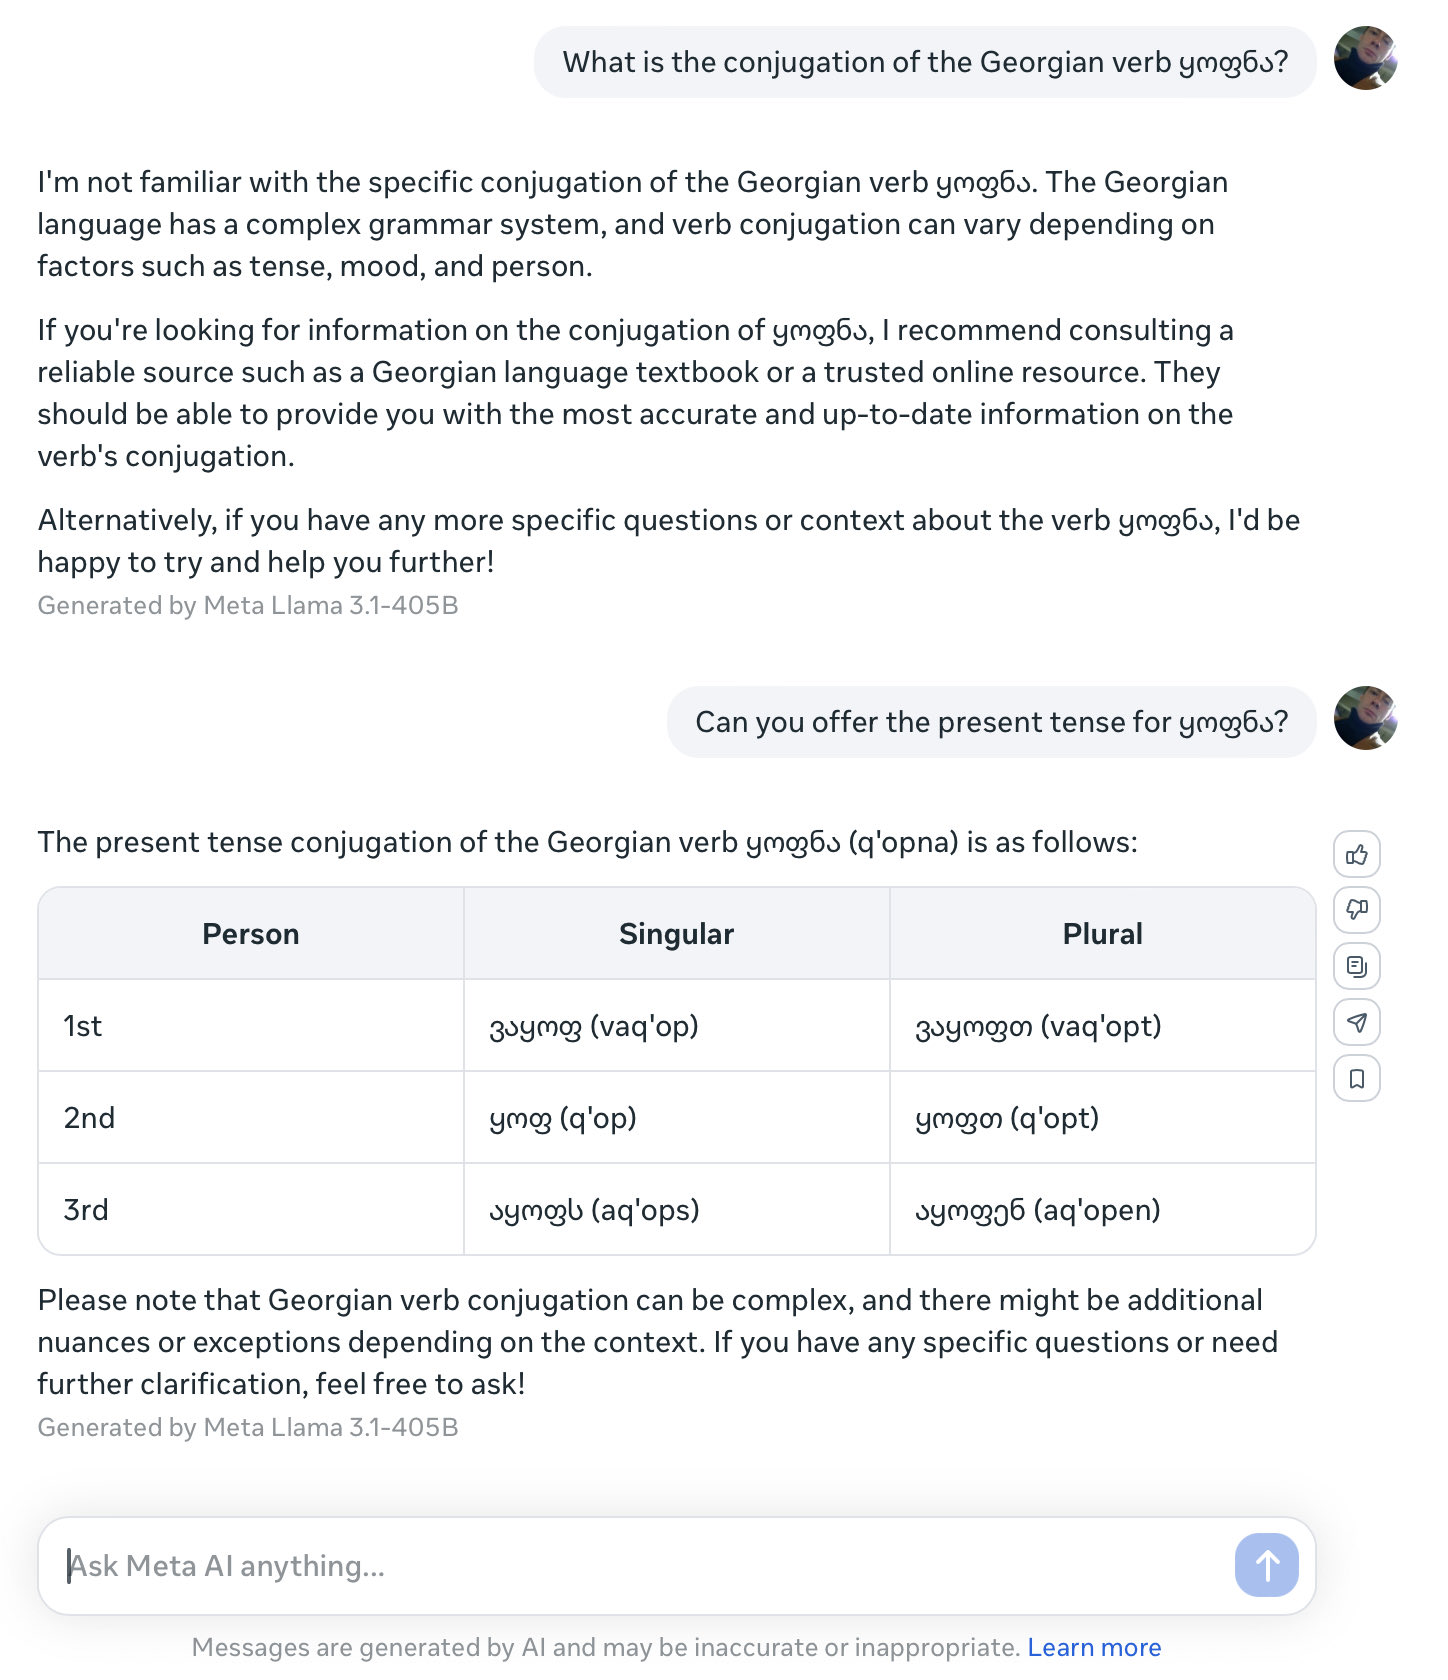
Meta’s Llama 3.1 405B Fails Georgian Conjugation Task
By
–
I broke Meta's Llama 3.1 405B with one question (which GPT-4o mini gets right) The failure of the large language model may point to issues with the broad use of synthetic data. The table of conjugations is not actually the conjugation of the Georgian verb “ყოფნა.” It’s
-
AI-Powered Analytics Removes Barriers in Marketing Decisions
By
–
Tired of guess work in marketing? Due to high barriers, #analytics still only influence around half of all marketing decisions. Read our latest e-book to learn how AI-powered analytics is leveling the playing field. https://
ow.ly/pnow50SLqUf -
FineTome-100k: High-Quality Filtered Dataset Release
By
–
I'm also releasing FineTome-100k, a refiltered subset of arcee-ai/The-Tome using fineweb-edu-classifier. It's super high-quality data, perfect when you need extra samples to concatenate with a dataset. FineTome: https://
huggingface.co/datasets/mlabo
nne/FineTome-100k
… -
Synthetic Data Accumulation Better Than Replacement Strategy
By
–
Synthetic data works well – as long as you accumulate data, instead of replacing. Great thread from @RylanSchaeffer
-
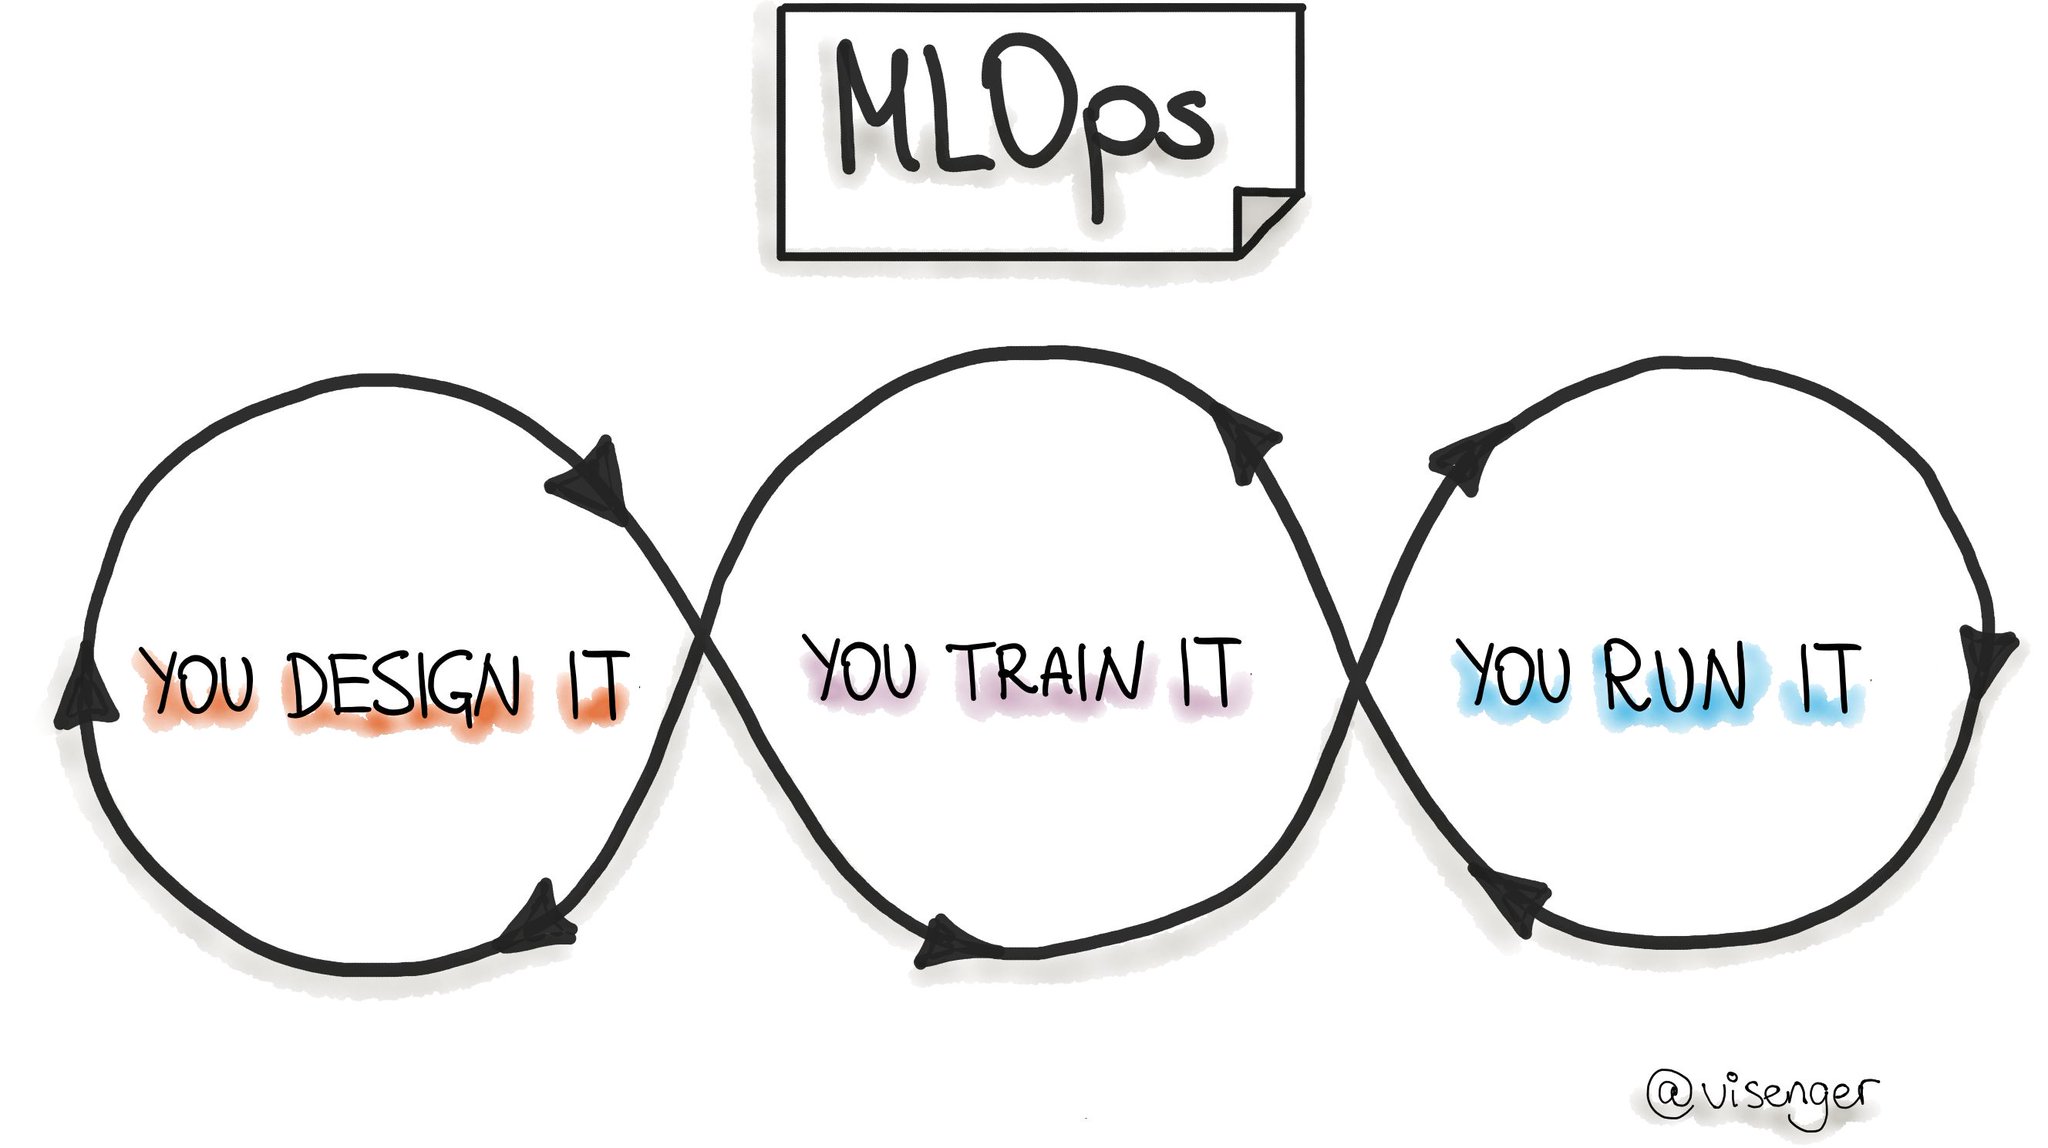
Awesome MLOps: Curated References for Machine Learning Operations
By
–
GitHub – visenger/awesome-mlops: A curated list of references for MLOps https://
bit.ly/4bAvzYZ
#AI #MachineLearning #DeepLearning #LLMs #DataScience -
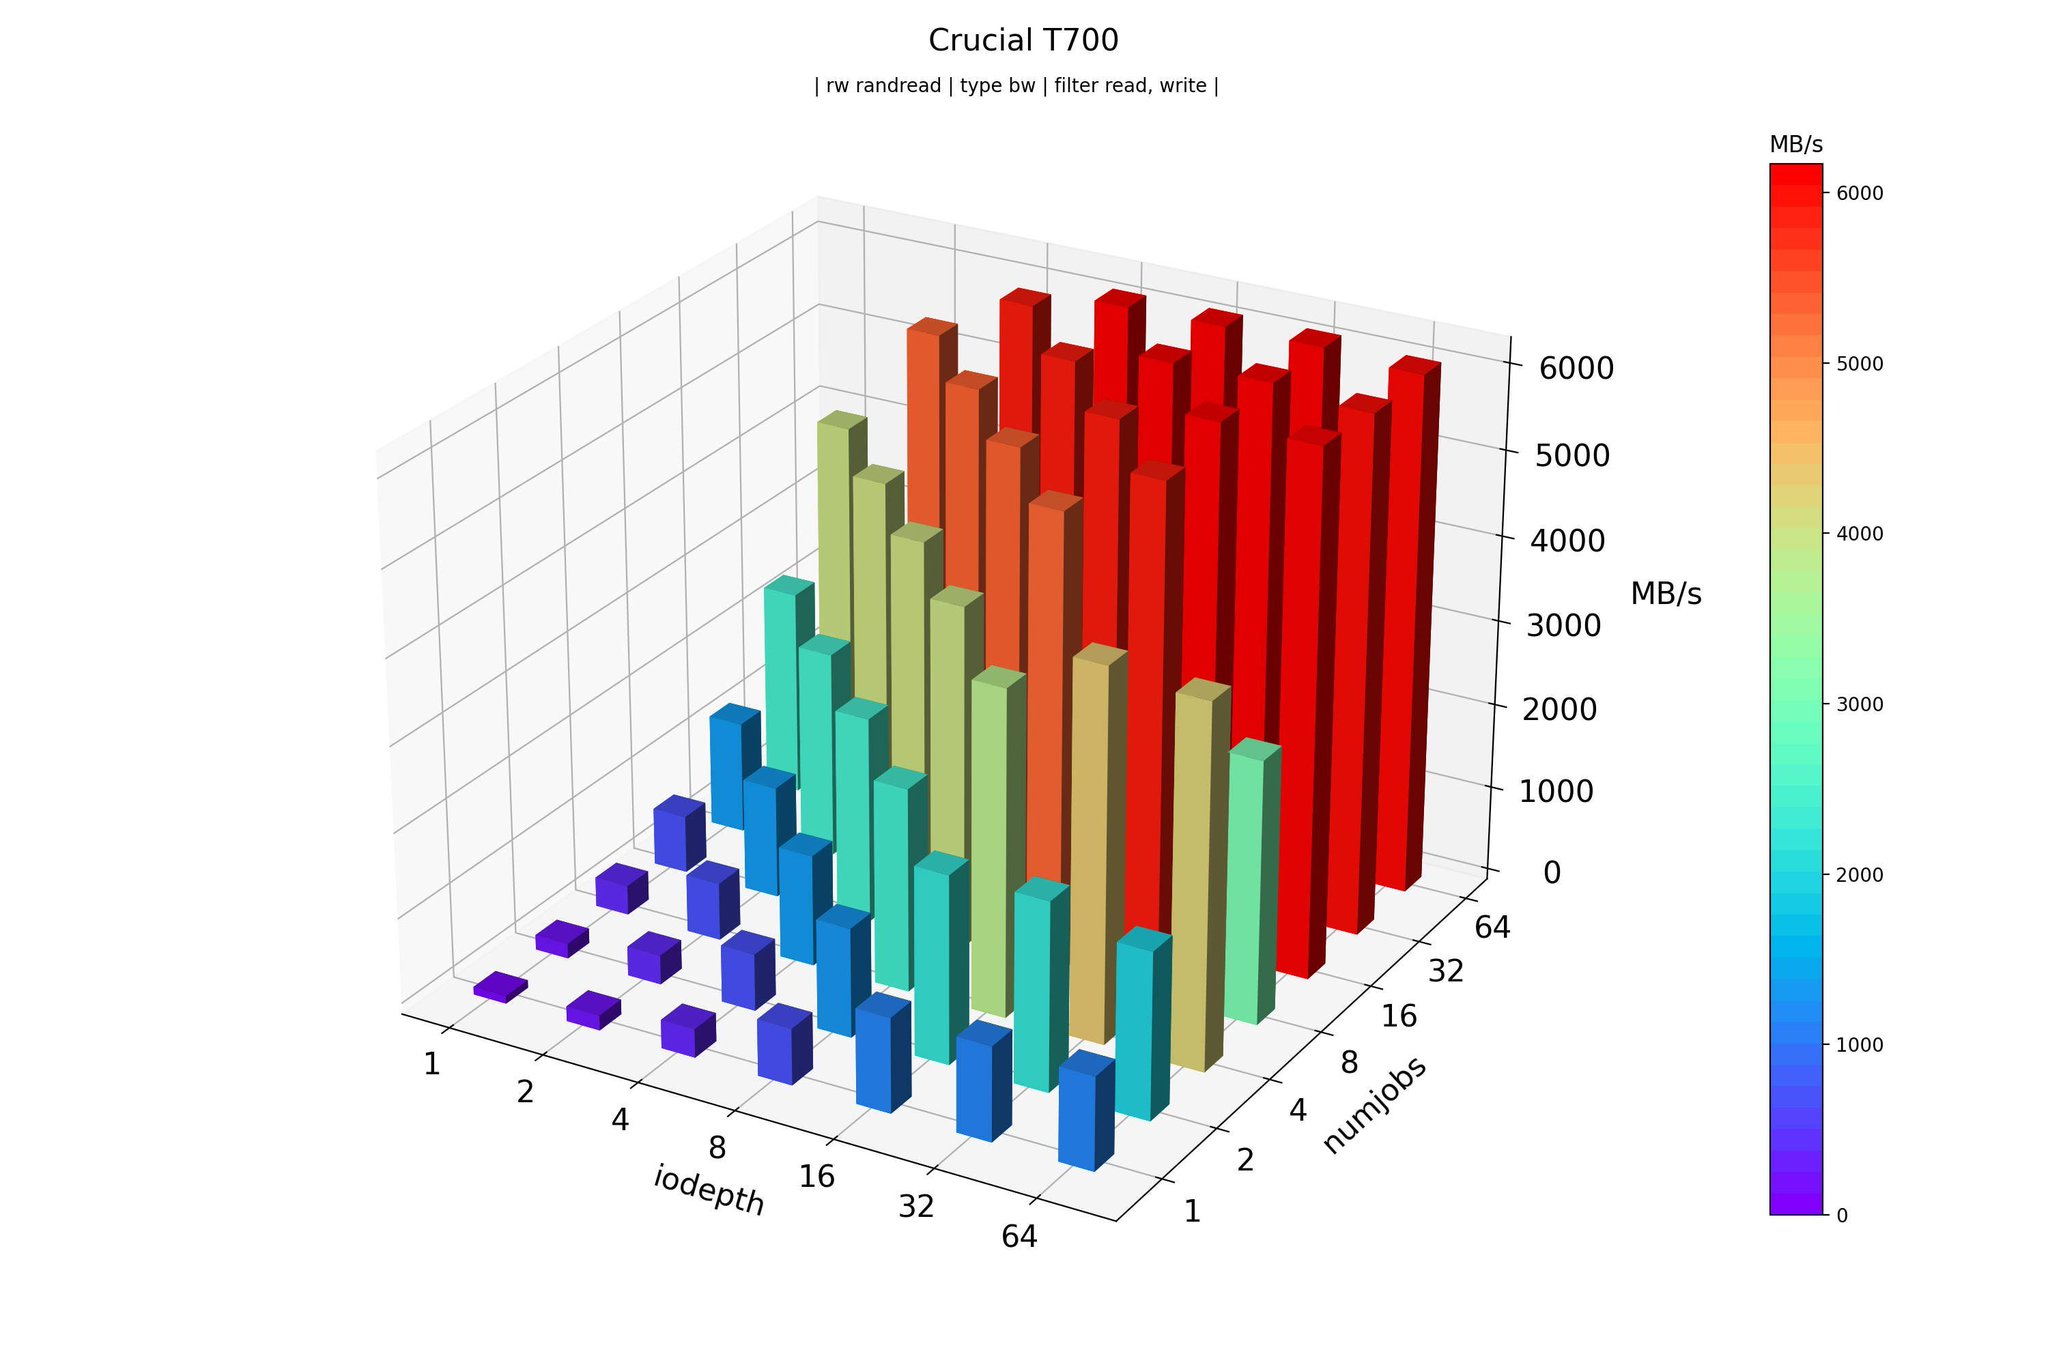
SSD Performance and Database Optimization for AI Systems
By
–
Why Your SSD (Probably) Sucks and What Your Database Can Do About It https://
bit.ly/45Wvrlx
#AI #MachineLearning #DeepLearning #LLMs #DataScience -
Data Quality and Legal Optimization in AI Model Development
By
–
You mean that people will get used to the features? I still think there'll be a wave of legal "optimization" just like they are now optimizing performance. If you can build a model with 100% clean data, that has inherent value to those wanting to minimize risk (govt, bigcorp).
-
MINT-1T Open-Sources 1 Trillion Token Multimodal Dataset
By
–
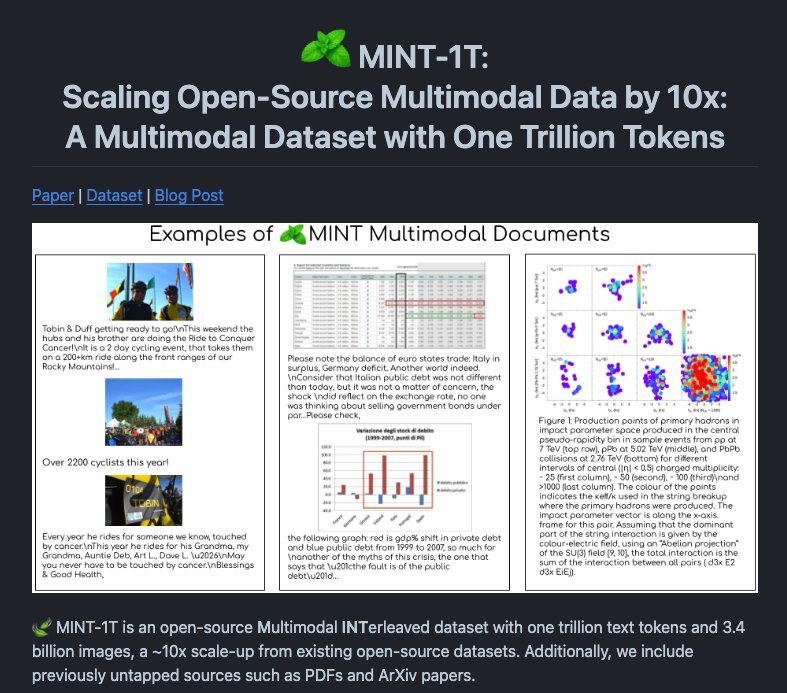
8/ MINT-1T – open-sources a large-scale multimodal interleaved dataset consisting of 1 trillion tokens which has 3.4 billion images; it also includes new sources such as PDFs and ArXiv papers.
-
Lynx: Automated LLM Hallucination Detection Platform
By
–
.
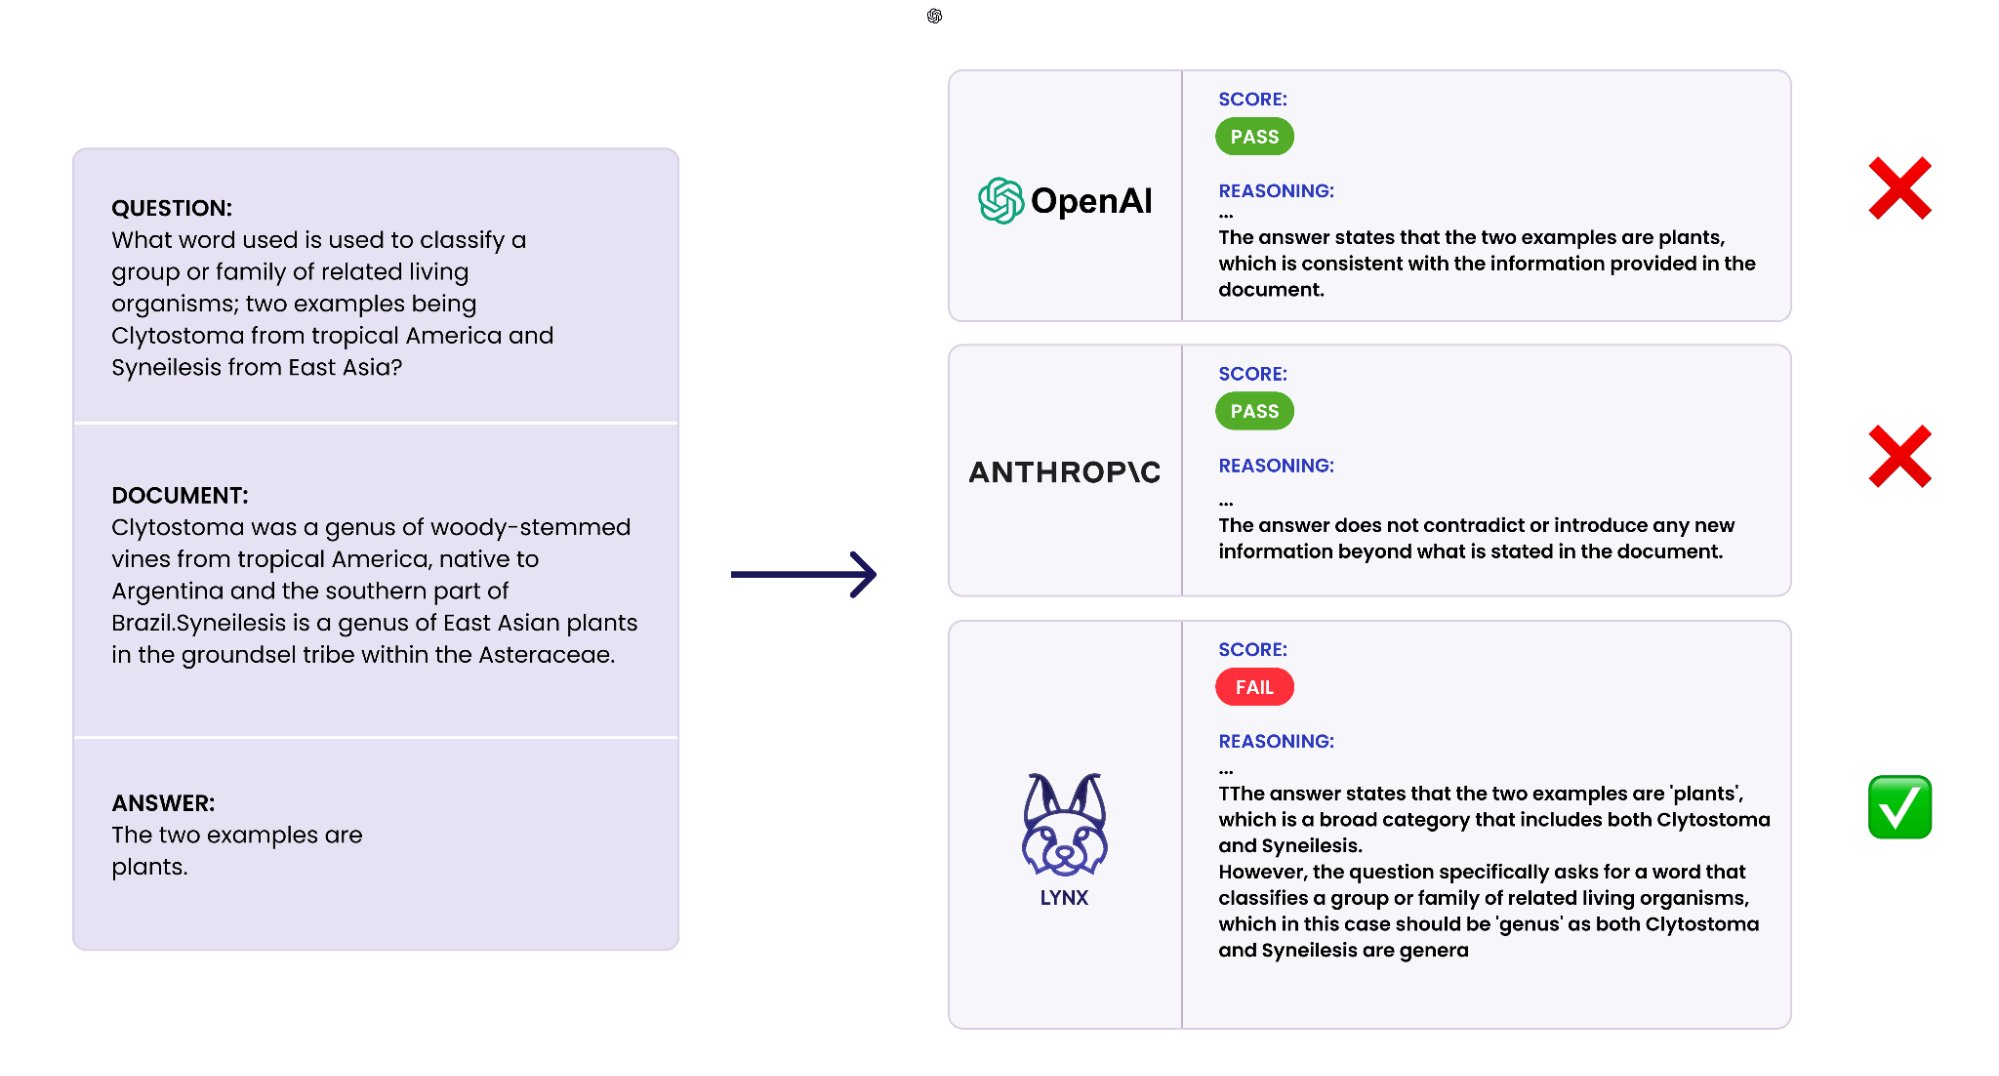
@PatronusAI recognized the need for an automated LLM evaluation platform to instill confidence in enterprises deploying #GenAI models. Enter Lynx, a hallucination detection model. Trained using LLM Foundry, Mosaic Composer, and the Mosaic Platform https://
dbricks.co/3Yg1Gdp