#ApacheSpark: The Definitive Guide. #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode https://
geni.us/ApacheSpark-
DATA
-

Apache Spark: The Definitive Guide for Big Data Analytics
By
–
-
Dataset Filtering for Large Language Model Training Runs
By
–
Possibly yes. More broadly, if we're going to be doing more large training runs at all, I'd guess we should start filtering the datasets soon (presumably using a previous-generation LLM finetuned for that?). It's hard to finetune out a cognition once it's learned by the base.
-

Data Lakes and Industrial IoT Key Takeaways Explained
By
–
Want to dive deep into the world of #datalakes and #IIoT? Check out this article summarizing the key takeaways from the recent All Things IIoT Day session. http://
ow.ly/TpzV50NsCmV #sponsored #hitachivantara_iiot #datascience #industrialIoT @BigDataMinded @YvesMulkers via @fogoros -

GitHub CLI Cheat Sheet for Data Science Productivity
By
–
GitHub CLI for Data Science Cheat Sheet: The GitHub CLI is a tool that allows for interaction with the GitHub platform with the command line interface. Mastering the most-used commands will allow you to become a productive of a data science, data… https://
kdnuggets.com/2023/03/github
-cli-data-science-cheat-sheet.html?utm_source=dlvr.it&utm_medium=twitter&utm_campaign=github-cli-for-data-science-cheat-sheet
… -
Segment Anything Model releases billion mask segmentation dataset
By
–
1/ Segment Anything Model – a set of resources for image segmentation; releases the largest segmentation dataset with over 1B masks on 11M licensed images; the model’s zero-shot performance is competitive with or superior to fully supervised results.https://t.co/sJvKhmeECe
— DAIR.AI (@dair_ai) 9 avril 20231/ Segment Anything Model – a set of resources for image segmentation; releases the largest segmentation dataset with over 1B masks on 11M licensed images; the model’s zero-shot performance is competitive with or superior to fully supervised results.
-
Copyright commercialization restrictions for AI training data
By
–
Surface level solutions (which work today) would involve being more strict about commercialisation rights, e.g. in Copyright. If you train on web-scraped data, that's OK for research, personal use and non-profit only — but you *cannot* commercialize.
-
Find Jupyter Notebook Repository and Star It
By
–
Find Jupyter Notebook Don't forget to star the repo!
-
Daily Content on ML, NLP, Computer Vision and LLMs
By
–
That's a wrap! If you interested in: – Python – Data Science – Machine Learning – Maths for ML – MLOps – NLP – Computer Vision – LLMs I'm sharing daily content over here, follow me → @akshay_pachaar if you haven't already!! Cheers!!
-

DBSCAN Clustering: Automatic Density-Based Cluster Detection
By
–
Applying DBSCAN doesn't get easier Notice that we don't need to worry about number of clusters in the data, it's determined based on density! Check this out
-
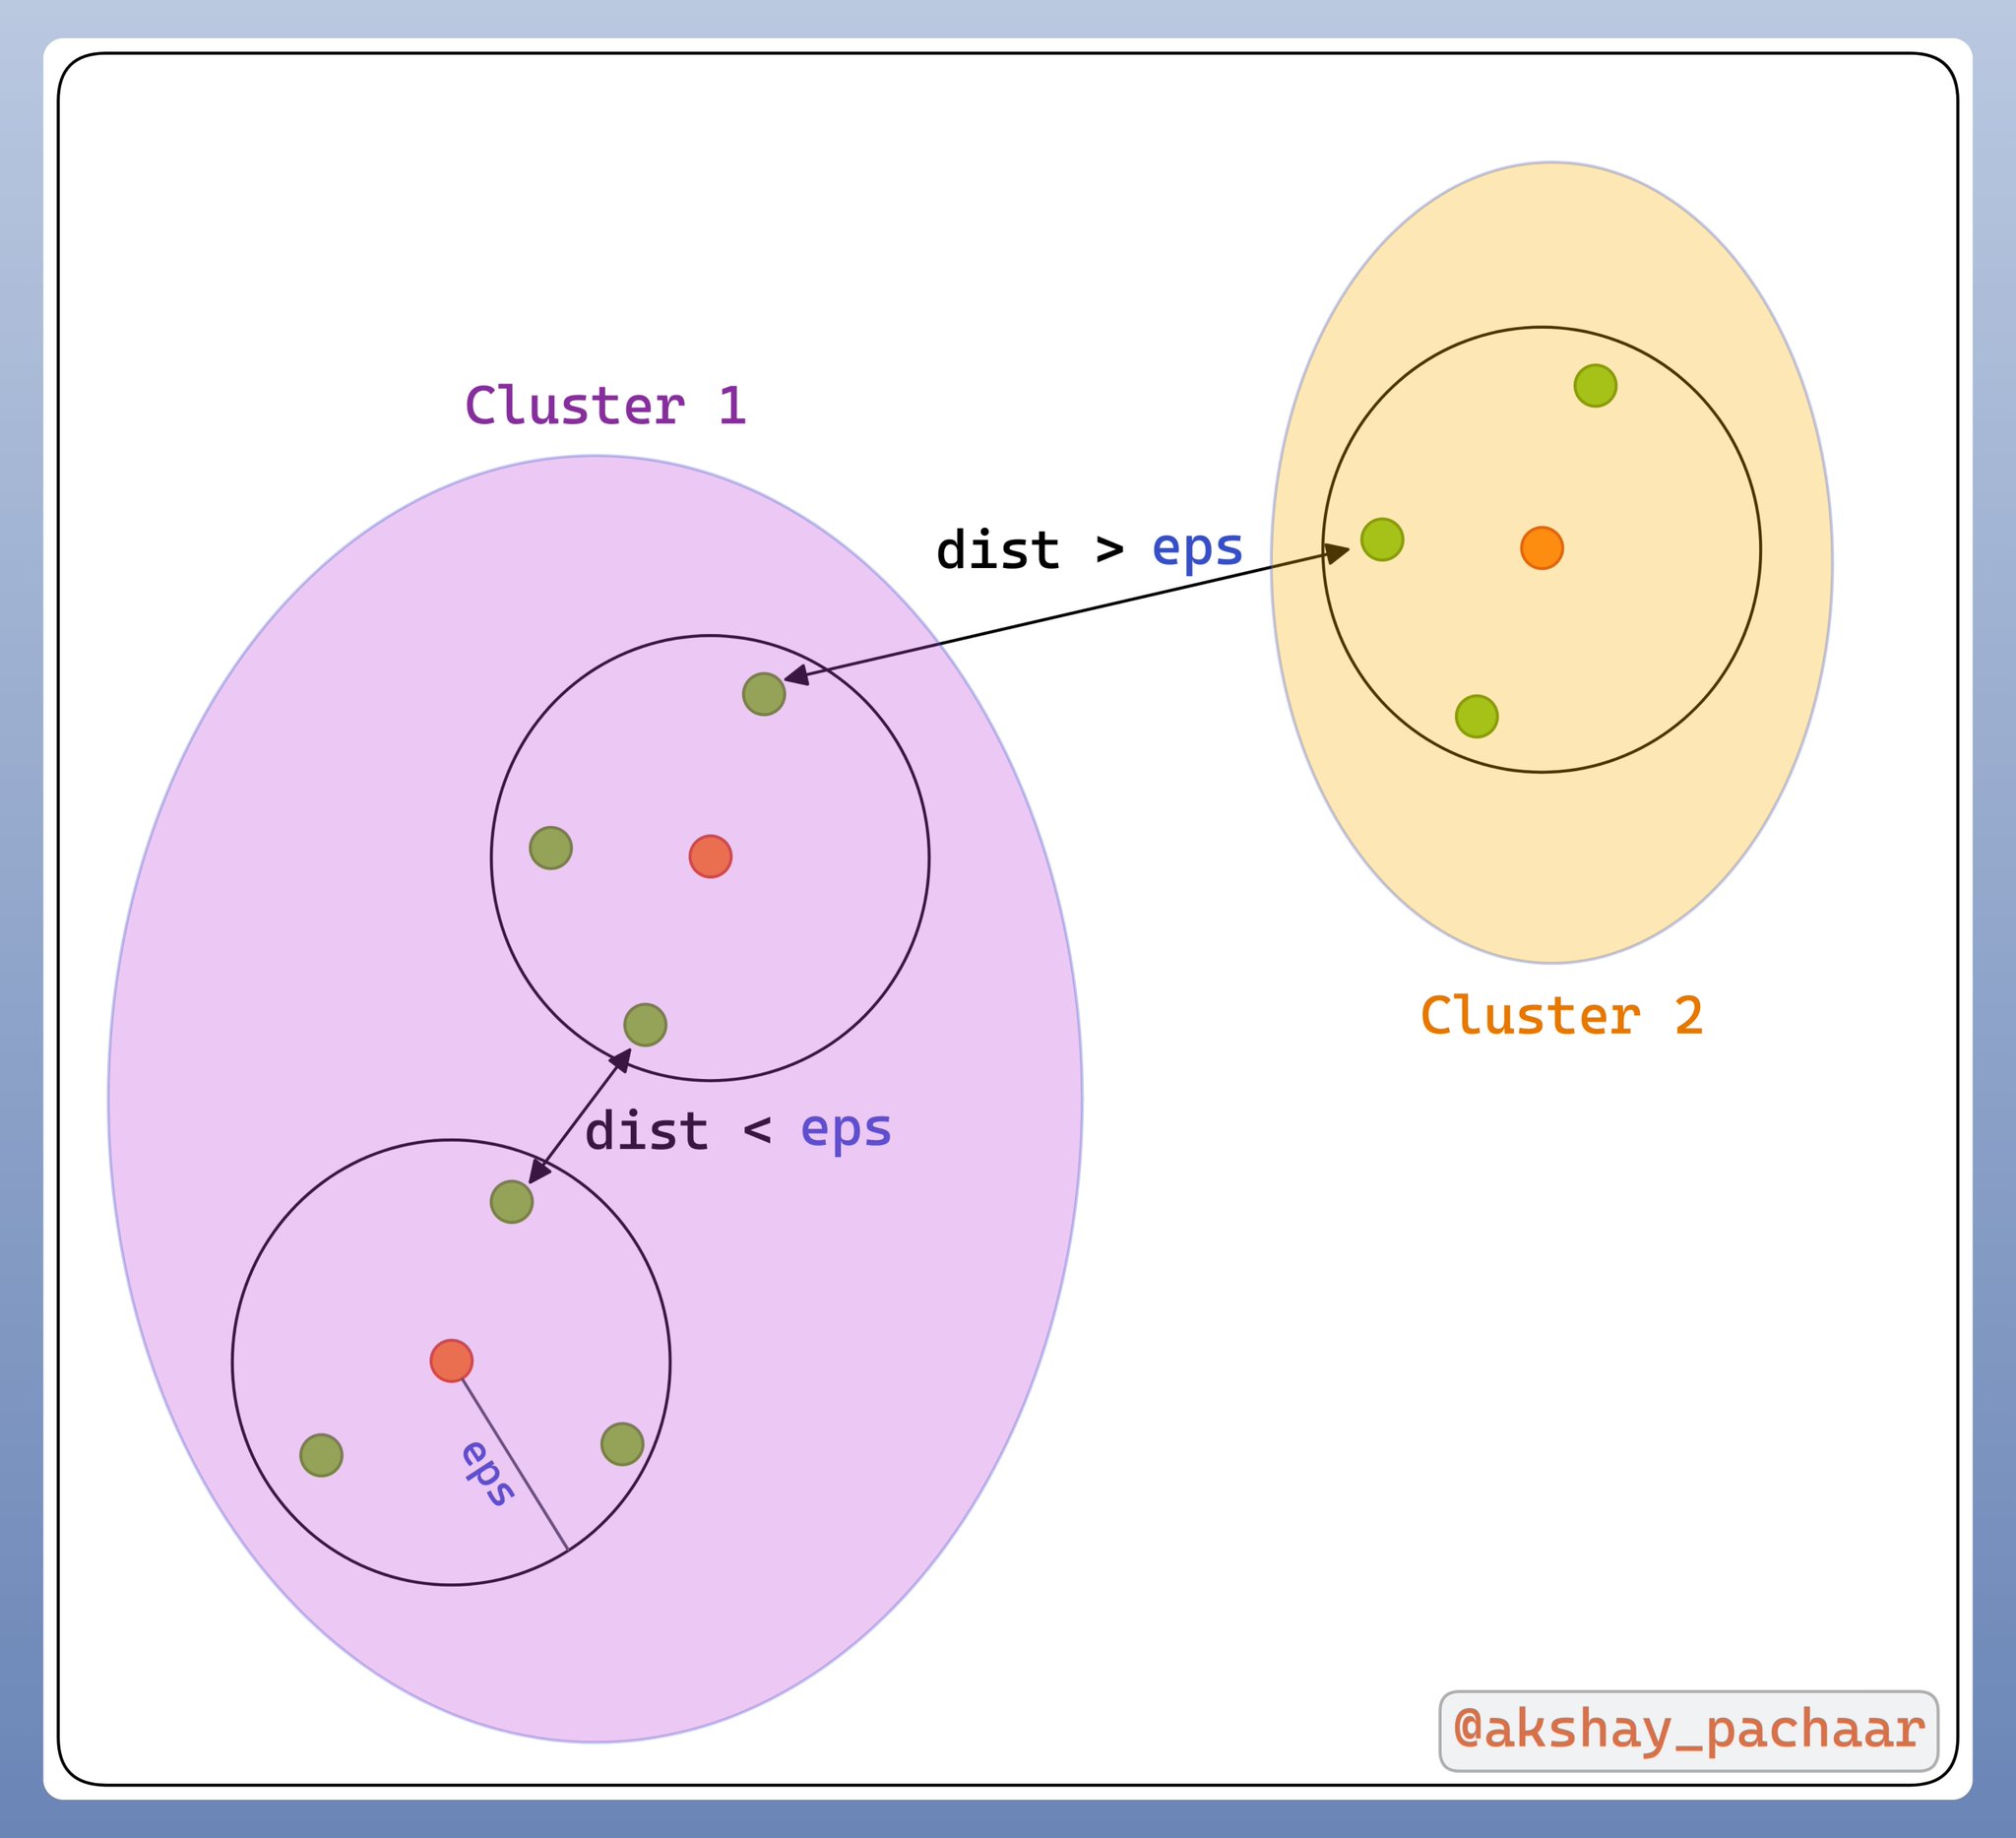
DBSCAN Clustering Algorithm Explained Simply
By
–
Now all the points which are not outliers & within in eps reachability of each, become part of the same cluster. That's it, that's all that DBSCAN is about! Check this image