
A neat feature of Keras is that its `keras.ops` API follows the NumPy API syntax exactly. And since it runs on JAX, PyTorch, TensorFlow, and NumPy itself, you can use Keras to write GPU-accelerated NumPy code that runs with any framework.
COMPUTING
-
Dealing with random MPI hangs in large model training
By
–
I thought I didn't have to deal with these, but already the 350M model (14 hours of 8 GPUs working) sometimes randomly hangs with a cryptic MPI error once in a while. So I have to put the whole optimization into a `while 1` loop and a script that watches the log file and sends
-
Single Node Training vs Large-Scale Multi-GPU Distributed Runs
By
–
But those were also much much bigger runs, so it's a lot more impressive. This was on a single node so you don't need to deal with any cross-node interconnect. It starts to get a lot more fun when you have to keep track of O(10,000) GPUs all at once. For a very specific
-

Snowflake CFO Explains Unique Database and Data Sharing Approach
By
–
Please enjoy my interview with Snowflake CFO Mike Scarpelli Snowflake CFO explains a few things you don’t understand about this business Many people don’t understand just how unique the Snowflake way of running a gigantic database is, or its approach to data sharing, says CFO
-
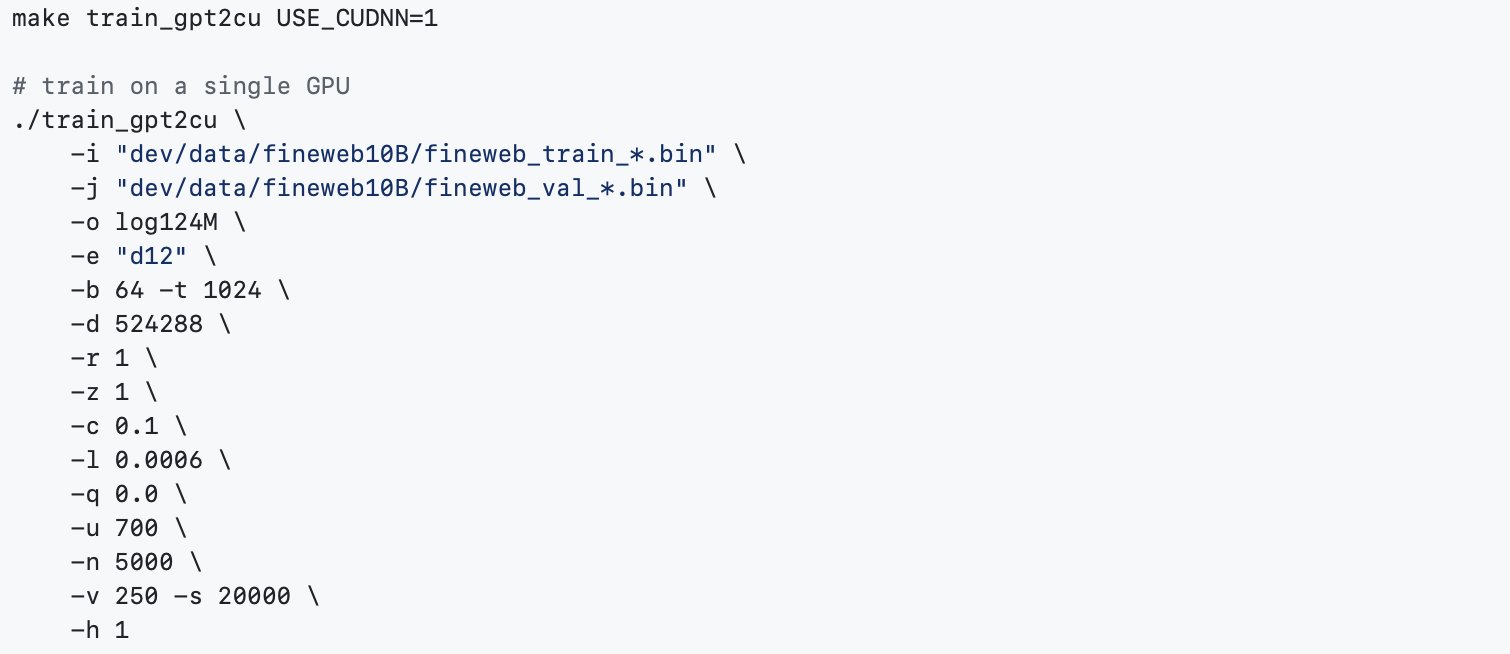
Reproduce GPT-2 124M in llm.c for $20 in 90 Minutes
By
–
# Reproduce GPT-2 (124M) in llm.c in 90 minutes for $20 The GPT-2 (124M) is the smallest model in the GPT-2 series released by OpenAI in 2019, and is actually quite accessible today, even for the GPU poor. For example, with llm.c you can now reproduce this model on one 8X
-
Running Multiple Open Source LLMs Locally with Ollama
By
–
Check out the code and complete hands on tutorial in the below blog https://
blog.futuresmart.ai/running-multip
le-open-source-llms-locally-with-ollama
…
#FuturesmartAI #AI #LLMs #Opensource -
Ollama: Running Open-Source LLMs Locally on Your PC
By
–
Ollama is a tool designed for this purpose, enabling you to run open-source LLMs like Mistral, Llama2, and Llama3 on your PC. Running LLMs can help to maintain privacy, reduced latency, and customisation as per your requirements.
-
Intel Launches 5th Gen Xeon Processors for Enterprise Computing
By
–
Do you know that 60°C (140°F) is the average temperature of an operating processor?
— Pascal Bornet (@pascal_bornet) 28 mai 2024
Recently, @intel marked one of the most important product launches in company history with the unveiling of the 5th Gen Xeon Processors. 🎉
In 3 words, 5th Gen Xeon Processors are… pic.twitter.com/u6tDkh5D8MDo you know that 60°C (140°F) is the average temperature of an operating processor? Recently, @intel marked one of the most important product launches in company history with the unveiling of the 5th Gen Xeon Processors. In 3 words, 5th Gen Xeon Processors are
-

Rare Earth Magnet Alternatives Transforming EV Drivetrain Sustainability
By
–
Exploring alternatives to rare earth magnets in EVs could significantly enhance sustainability. Learn about the impact on EV drivetrains: https://
spr.ly/6017eDrjt #EVs #Electrification #Sustainability -

Obayashi’s Space Elevator Project: Revolutionary Infrastructure Innovation
By
–
i love this
— Yohei (@yoheinakajima) 28 mai 2024
more: https://t.co/aU6yKGKVeX https://t.co/3MLx1rwdun pic.twitter.com/K3Bd2nPF5ti love this more: https://
obayashi.co.jp/chronicle/130t
h/en/story/space-elevator/
…