Discover how senior ASIC engineer Tarun Patil is engineering success and pioneering advancements in silicon performance analysis: https://
nvda.ws/4e5bSvc
#NVIDIAlife
COMPUTING
-

NVIDIA engineer pioneers silicon performance analysis advancements
By
–
-
The Race for LLM Cognitive Core: Always-On Personal Computing Kernel
By
–
The race for LLM "cognitive core" – a few billion param model that maximally sacrifices encyclopedic knowledge for capability. It lives always-on and by default on every computer as the kernel of LLM personal computing.
Its features are slowly crystalizing: – Natively multimodal -
US China AI Chip War: Strategic Vulnerabilities and Export Controls
By
–
The real AI war isn’t just about chips – it’s about Achilles heels. And both the U.S. and China have them.
— Nina Schick (@NinaDSchick) 27 juin 2025
If you’re watching this space closely, you’ll know something huge is unfolding beneath the headlines. On the surface, it’s about export controls, chip bans, and supply… pic.twitter.com/rnAlUNfsnVThe real AI war isn’t just about chips – it’s about Achilles heels. And both the U.S. and China have them. If you’re watching this space closely, you’ll know something huge is unfolding beneath the headlines. On the surface, it’s about export controls, chip bans, and supply
-
Cerebras Achieves Order of Magnitude Token Output Improvements
By
–
"Before Cerebras, everything sits sub 200 tokens per second output. And after us, on every model, you have vast improvements, order of magnitude improvements. And what this allows you to do is deliver something special and different to your customers —faster responses, richer… pic.twitter.com/Geo41OaASV
— Cerebras (@cerebras) 27 juin 2025"Before Cerebras, everything sits sub 200 tokens per second output. And after us, on every model, you have vast improvements, order of magnitude improvements. And what this allows you to do is deliver something special and different to your customers —faster responses, richer
-
Future Computers: Do We Still Need CPUs?
By
–
really dumb question. will future computers even need CPUs? seems they mostly exist to load data on and off the GPU. what’s the point of that
-
Free AI Infrastructure Revolution Democratizes Computing Access
By
–
You don’t realize what tremendous amount of free or 20$/month infrastructure the computer revolution poured into our lives? Almost everything I have to read and watch for my work is free. I pay mostly for convenience. I can even run decent AI models at home.
-

MLRun and NVIDIA NIM enable scalable observable AI deployment
By
–
Learn how Iguazio’s MLRun and NVIDIA NIM combine to enable scalable, observable AI by combining optimized inference with operational oversight. https://
nvda.ws/43YI3Yy > Iguazio’s MLRun automates and orchestrates the deployment and management of NVIDIA NIM microservices -

Gemma 3n: Powerful Open Source Multimodal Model for Edge
By
–
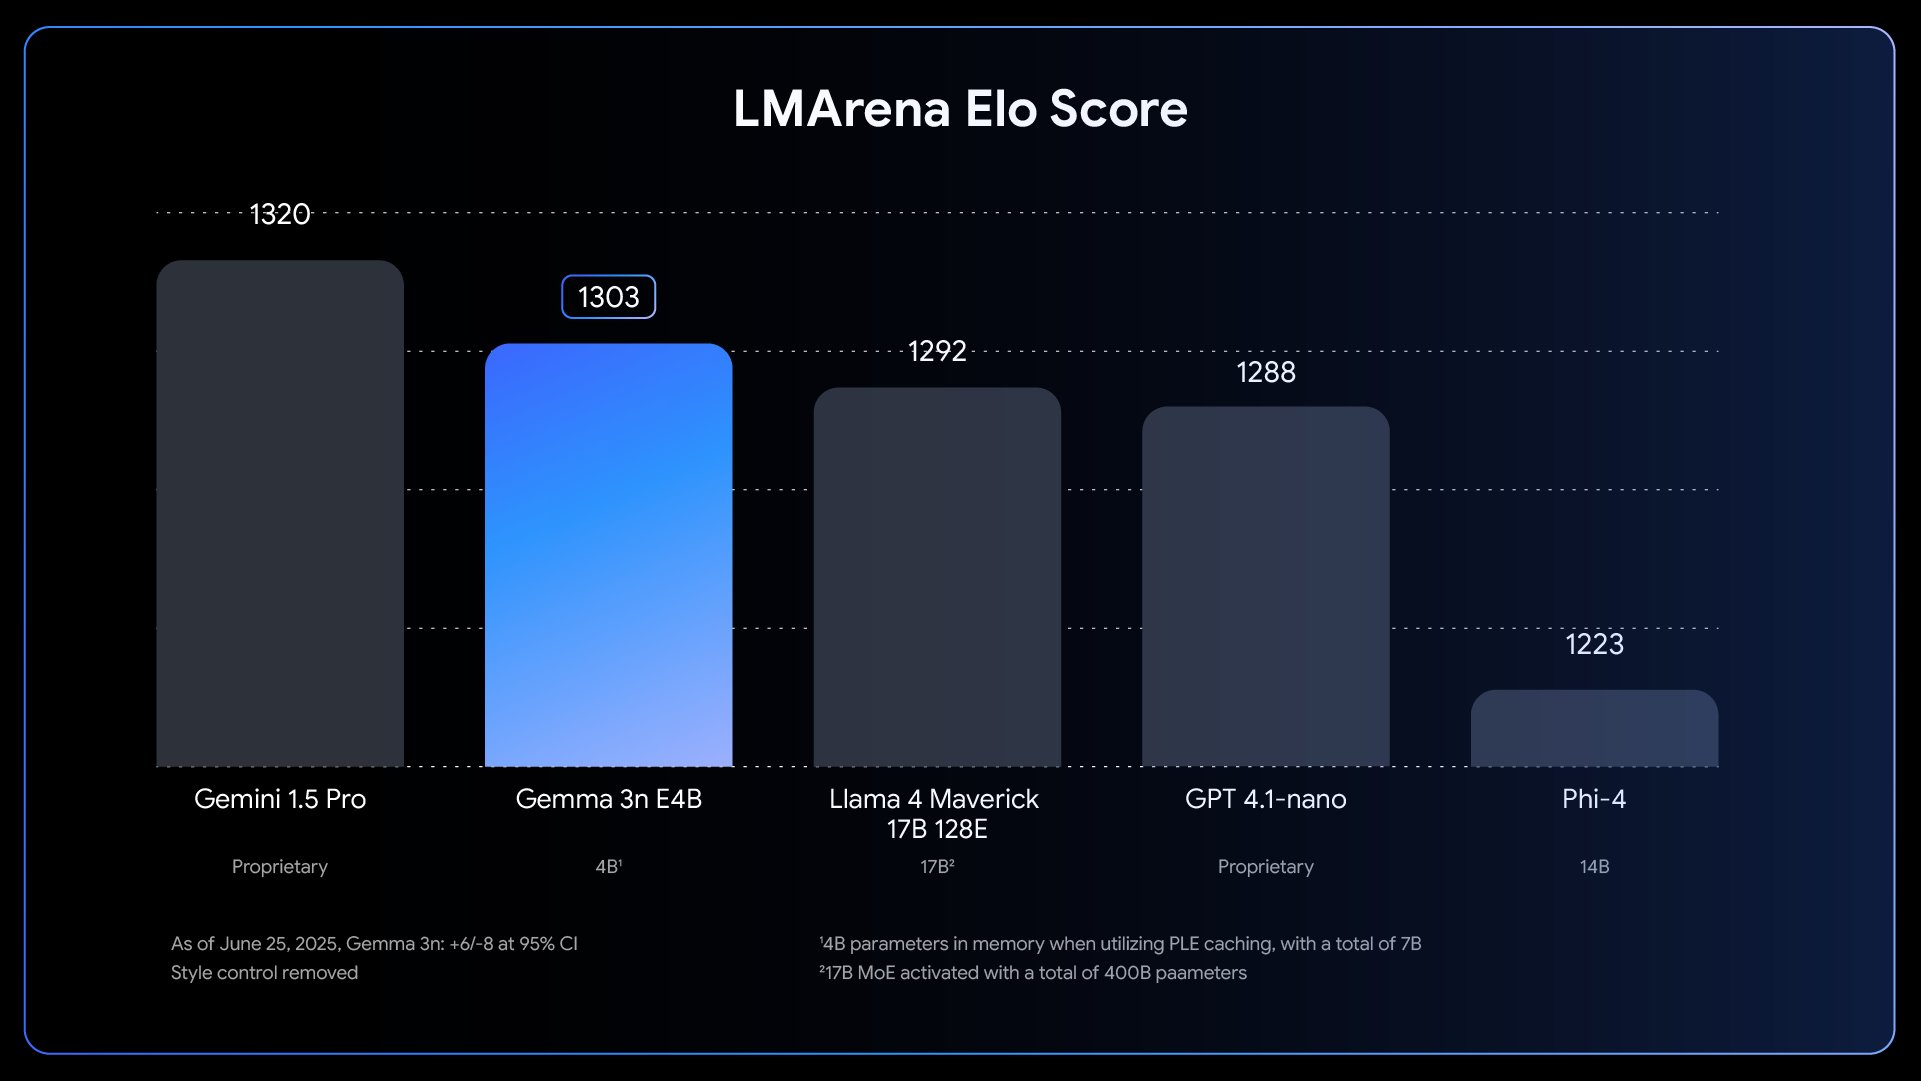
Our open source Gemma models are the most powerful single GPU/TPU models out there! Our latest model Gemma 3n has amazing performance, multimodal understanding, & can run with as little as 2GB of memory – perfect for edge devices – enjoy building at http://
ai.studio ! -
Preference for Scalable Turn-the-Crank Algorithms with Increased Compute
By
–
I sometimes try to explain it as a statement of preference for "turn the crank" algorithms. When you're eventually given more compute (faster crank), you shouldn't have to touch anything at all, you just crank faster to make better. You can (and probably locally should) knowingly