Check out our Gemma 4 12B model: it's a super capable open weights model that can run directly on your laptop.
COMPUTING
-

Step-by-step LLM engineering projects roadmap
By
–
Step-By-Step LLM Engineering Projects Roadmap – Build a tokenizer
– Learn embeddings
– Implement RoPE / ALiBi
– Hand-wire attention
– Build MHA
– Build a Transformer block
– Train a mini-former
– Compare objectives
– Build sampling
– Speculative decoding
– KV cache
– MQA / GQA / -
Colocating memory avoids costly transfers during inference
By
–
"If you can co-locate your memory, you're getting a lot more bang for your buck because you're avoiding this costly memory transfer."@sarahookr (author of The Hardware Lottery, founder of @adaptionlabs ) on why inference is forcing a new chip paradigm – one that wafer-scale was… pic.twitter.com/tTfu19zUWU
— Cerebras (@cerebras) 4 juin 2026“If you can colocate your memory, you get much more value for your money because you avoid that costly memory transfer.” @sarahookr (author of The Hardware Lottery, founder of @adaptionlabs) on why inference forces a new paradigm
-
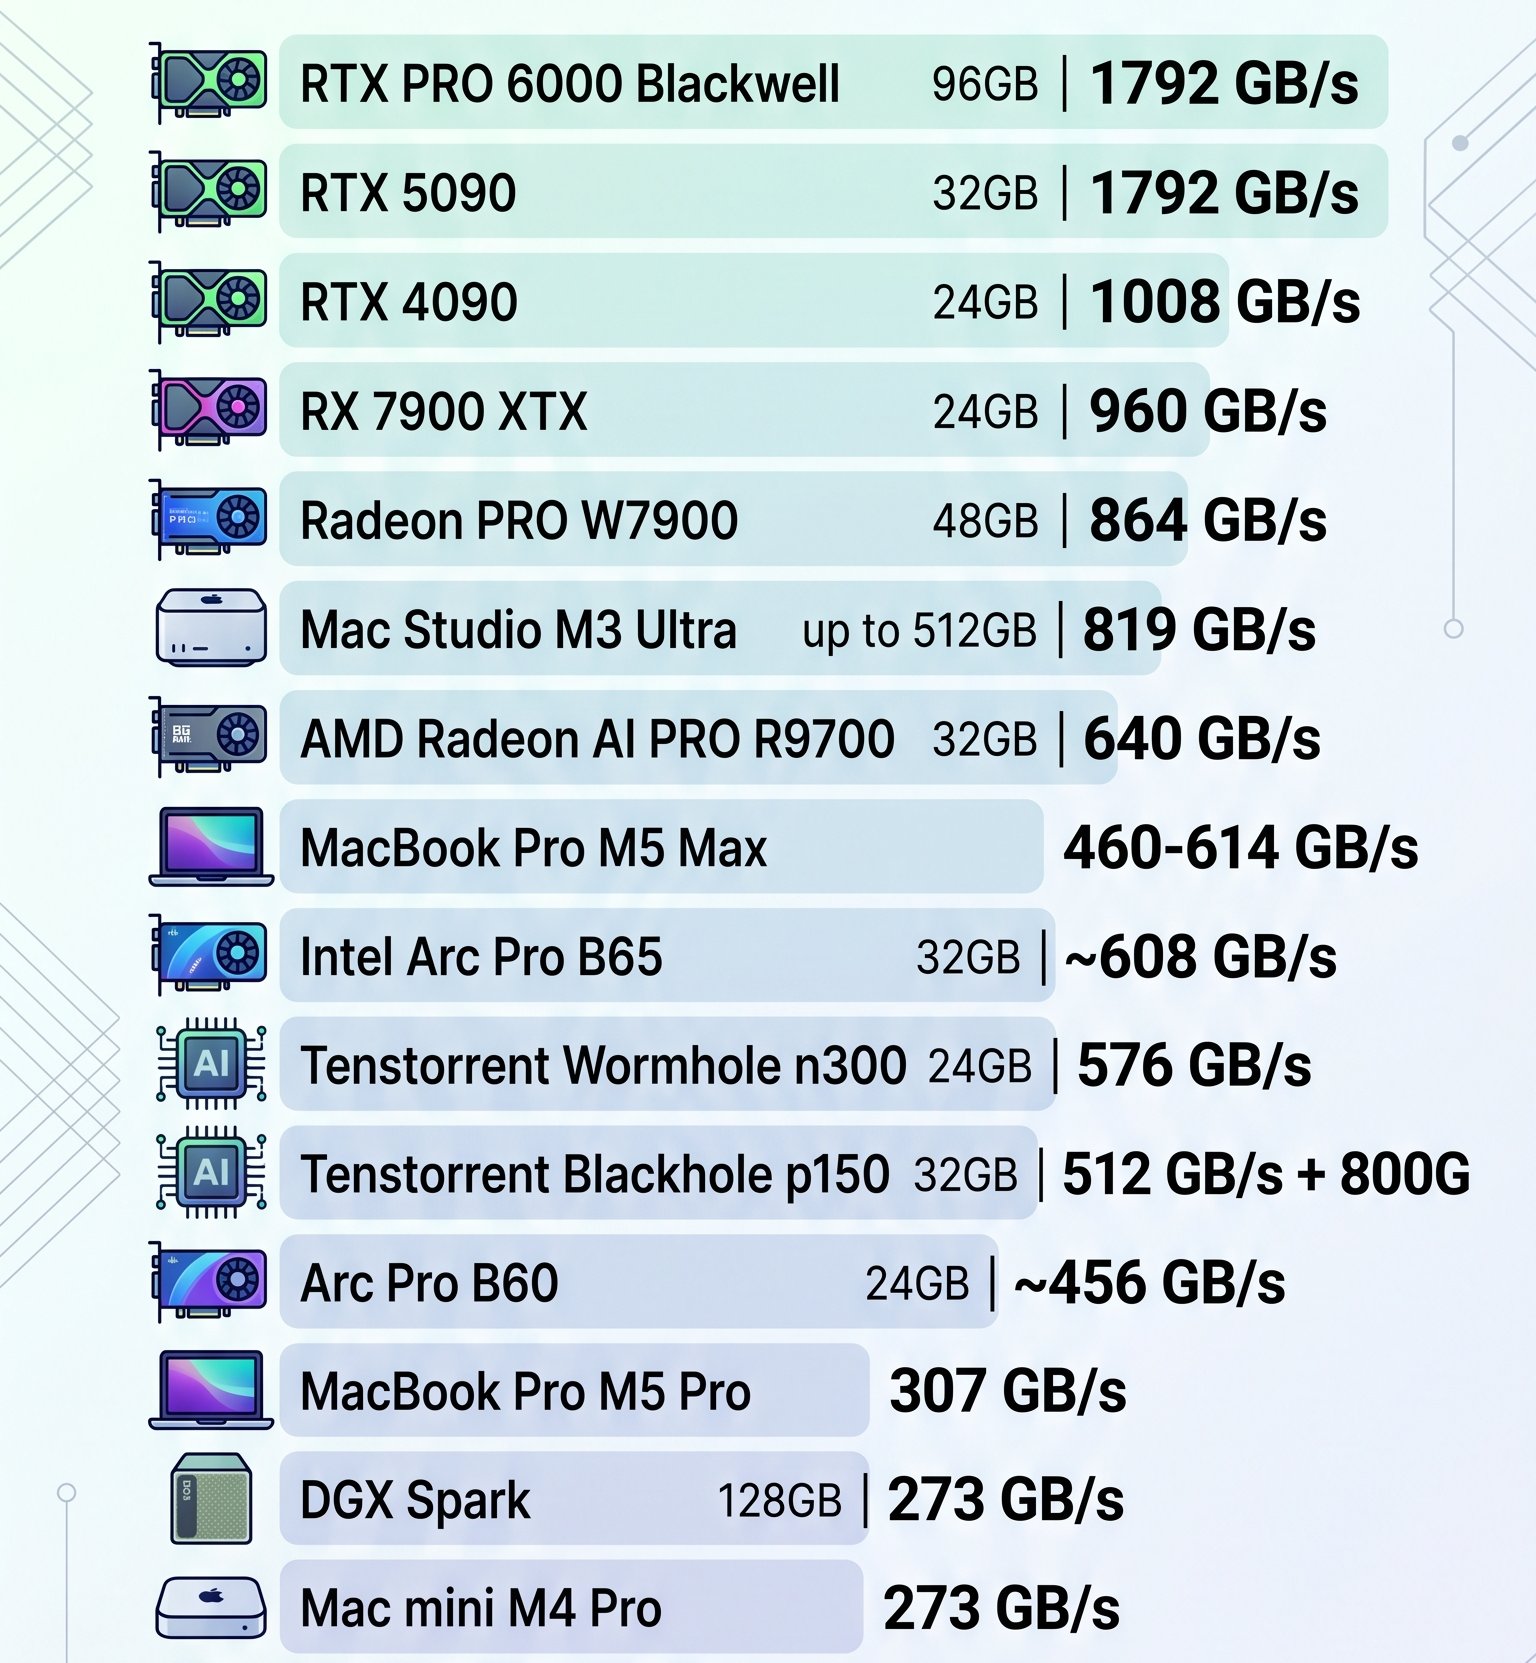
Local AI hardware: capacity, bandwidth, and software stack
By
–
Local AI hardware = capacity × bandwidth × software stack – Capacity tells you what fits
– Bandwidth tells you how hard the box can breathe
– The software stack tells you how much of the spec sheet you can actually cash out. Hardware by Memory Bandwidth
– Mac Studio M3 Ultra: -
Compute usage: 1B ChatGPT vs 5M Codex users
By
–
Who is using more compute – 1b of ChatGPT users or 5m of Codex users?
-
Try Grok models on Cloudflare’s AI Gateway
By
–
Try Grok models on @Cloudflare's AI Gateway! https://t.co/YY511gTthP
— xAI (@xai) 3 juin 2026Try Grok models on @Cloudflare
's AI Gateway! -

This alone convinces enterprises to host LLMs on-premise
By
–
I mean, look at this, this alone is enough to get every enterprise out there into hosting their LLMs on-premise
-
DGX Spark wins on energy, 4x 3090s on performance
By
–
Low energy/heat footprint: DGX Spark wins Performance: 4x 3090s win
-

LFM2/2.5 architecture: convolution is almost all you need
By
–
Oh fun! The LFM2/2.5 architecture is a joy to play with. Convolution is (almost) all you need.
-

World’s first heterogeneous disaggregated inference cloud shown live at ComputeX
By
–
The world's first heterogenous disaggregated inference cloud was just shown running live at ComputeX. VC2 — backed by a $3.5B compute commitment to SambaNova from @Vista_Equity & @cambiumcapital — brings three chips together in production for the first time:
– NVIDIA B200 GPUs