When laws and oversight depend on transcripts, 70–80% isn’t enough. http://
Rafiqspace.ai hit 97.7% Bahasa Indonesia accuracy (2.3% WER) with fine‑tuned Nemotron Parakeet ASR—outperforming global tools while cutting per‑hour costs by up to 90%.
COMPUTING
-

NVIDIA’s Rafiqspace AI achieves 97.7% Bahasa Indonesia ASR accuracy
By
–
-
Everything You Need to Know About Inference Engines and Local LLMs
By
–
Everything You Need To Know About
Inference Engines and Running LLMs Locally at Home Explains why Inference Engines exist in the first place
– Prefill is not Decode
– VRAM is not bandwidth
– Fit is not speed
– KV Cache is the real memory problem
– Quantization only matters if -

NVIDIA Nemotron 3 Ultra solves AI agent fatigue and cost issues
By
–
AI agents don't just get expensive.
They get tired.
As workflows become longer, agents suffer from goal drift, context overload, and rising token costs.
NVIDIA's Nemotron 3 Ultra aims to fix that: Hybrid Mamba + Transformer 1M-token context 5x throughput 30% lower -

Apollo and Blackstone partnerships and Broadcom demand indicate AI market shift
By
–
Partnering with the money guys such as Apollo and Blackstone is an ominous turn for a crazed AI infrastructure market. So is the “huge” demand for Broadcom’s services by Google and others well in advance of actual deployment of chips. Not the end of the road, but a potential
-
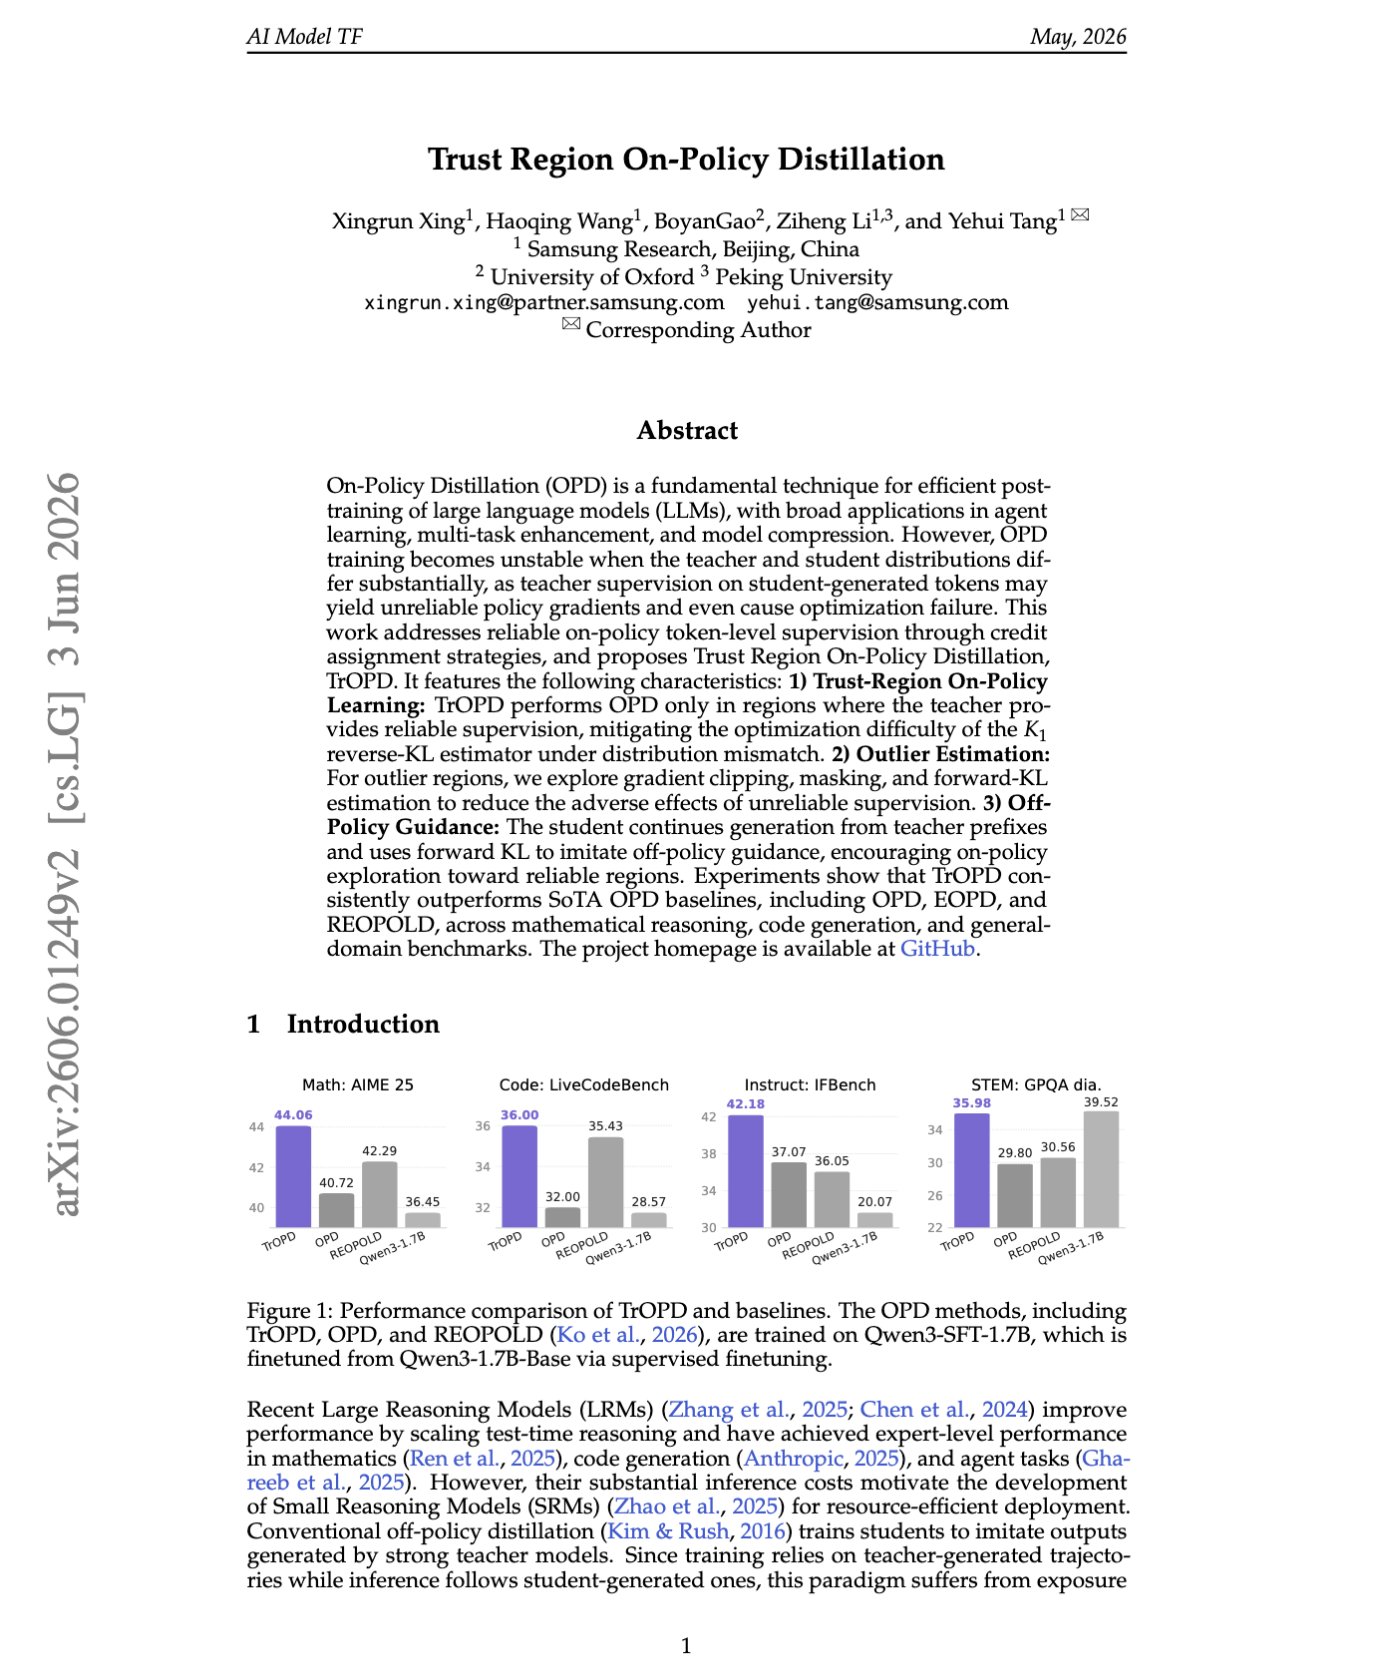
Trust Region On-Policy Distillation: Learning from reliable teacher signals
By
–
“Trust Region On-Policy Distillation” On-policy distillation is powerful, but one bad mismatch between student and teacher can negatively impact the gradients. So this paper's TrOPD only learns where the teacher is reliable, treats outliers separately, and nudges the student
-

SambaNova unveils disaggregated inference demo and SN50 RDU for AI agents
By
–
Premium inference is powering the next generation of AI agents. First live disaggregated inference demo for AI agents New SN50 RDU purpose-built for agentic inference Faster, more efficient AI with industry-leading throughput See what's next for AI inference:
-

NVIDIA DGX Spark updates boost agentic AI inference speeds 2.6x
By
–
Is your infrastructure ready for the shift to agentic AI? Discover how the latest NVIDIA DGX Spark updates simplify local agent workflows and boost inference speeds by up to 2.6x using NVIDIA NemoClaw. Read the blog: https://
nvda.ws/4uPi16d -
We are in the recursive era of AI according to Cerebras
By
–
We are in the recursive era of AI. Cerebras wrote an article about this from a hardware perspective in March: https://cerebras.ai/blog/why-the-ai-race-shifted-to-speed …
-
The Recursive Era of AI: Fast Inference and Accelerated Development per Cerebras
By
–
We are in the recursive era of AI.
Faster inference => faster AI development.
Our take on this from a hardware perspective:
https://cerebras.ai/blog/why-the-ai-race-shifted-to-speed
… -
New course on serving LLMs efficiently with Red Hat
By
–
New course on serving LLMs efficiently — how do you serve models to many concurrent users at low latency and reasonable cost? This short course is built with @RedHat and taught by @cedricclyburn.
— Andrew Ng (@AndrewYNg) 4 juin 2026
Efficient LLM serving requires efficient memory management. A 70B-parameter model… pic.twitter.com/KeKveT2IicNew course on serving LLMs efficiently — how do you serve models to many concurrent users at low latency and reasonable cost? This short course is built with @RedHat and taught by @cedricclyburn
. Efficient LLM serving requires efficient memory management. A 70B-parameter model